Now learning "llms.txt" as an LLM-legible docs format comes from @jeremyphoward who wrote a proposal here: https://
llmstxt.org
@goodside
-
Learning about llms.txt format from Jeremy Howard’s proposal
By
–
-
Convention for LLM-legible docs at fixed paths like robots.txt
By
–
Sure, but if you're starting a convention for LLM-legible docs (e.g. that docs should always be at some path à la robots.txt) the choice of markdown is incidental; it could be XML, JSON — whatever an LLM understands, which .txt signifies well.
-

Shane Legg talk on measuring AI intelligence and task distribution
By
–

For the measure of intelligence, recommend @ShaneLegg talk from 12 years ago. It set up the framework for me on how to measure the progress of AI. However it also left the lingering question of what task distribution E should be. https://
youtu.be/V6umr1OP8uo?si
=61sv3ALIm9mHnapr
… -
LLM IQ is a type error, not a human-like intelligence measure.
By
–
An LLM’s IQ is a type error. LLMs don’t preserve the positive manifold of correlated scores human IQ summarizes. An LLM’s IQ is 160 or 60 depending on the task and no human of any IQ is similar. The jagged frontier is not a chalk outline of the midwit mind.
-
Anthropomorphizing trap but wrong CoT outperforms non-CoT
By
–
I mostly agree — anthropomorphizing is a trap — but the choice of “Let’s think step by step” isn’t arbitrary either. Wrong CoT working better than non-CoT still says something
-
New research from Scale on detecting LLM output problems
By
–
New research from Scale — detecting problems in LLM outputs before it's too late. This work will be presented at NeurIPS 2024 main track — congrats @vaskar_n
, @dylanslack20
, @_jeffda
, @TommyMa9
, @hughbzhang
, Spencer Whitehead, and @SeanHendryx
! -
Efficient logprob encoding using control tokens for low values
By
–
A more efficient way to do this could be to have typical logprobs encoded normally and exceptionally low ones marked with a control token as exact magnitudes don’t matter much beyond them being low — this is the approach of SequenceMatch
-
Pregen from base model with frequency for greetings
By
–
Pregen + prompt with a sample sounds like a good workaround to me; just pregen a lot so you don’t mind the diversity. You could even pregen from a base model and count frequency so common greetings are common.
-
OpenAI o1 models top Scale’s SEAL Leaderboards, early impressions
By
–
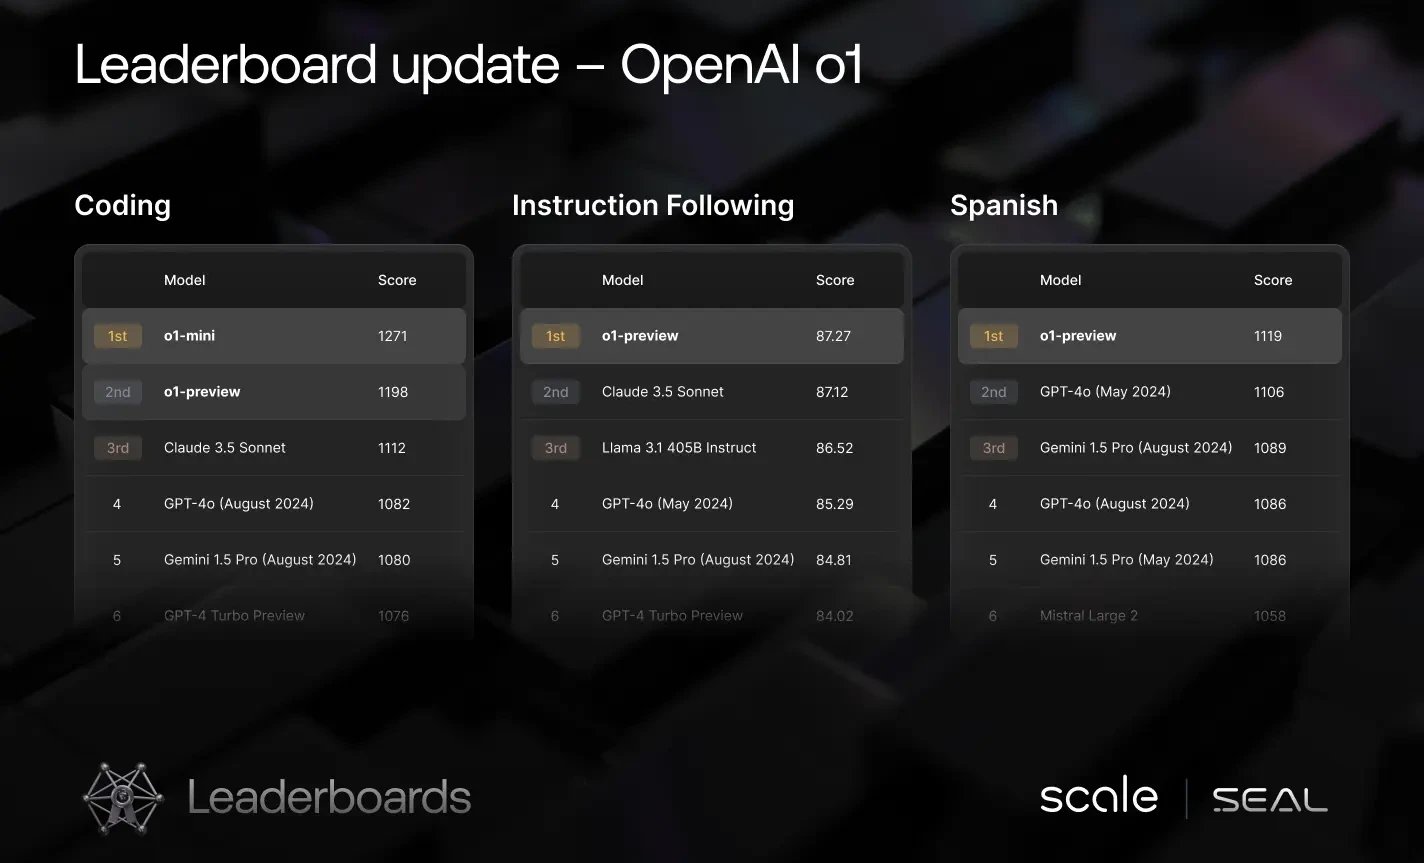
OpenAI’s o1-preview and o1-mini now top Scale’s SEAL Leaderboards! On the Scale blog, I recap benchmarks for the new o1 models and share some early impressions from my time using them. (Link in comment!)
-

Tokenization of ‘r’ same in both cases, questioning expectation
By
–
Why would you expect that to matter? “ r” is tokenized the same way in both cases. Either way, no: