
In practice the safest way to get an LLM to do counting or string operations is to use external tools, like Python. ChatGPT has Python built in, but for simple problems you need to ask it to use it. So, if you *must*, this is the best way to count the r's in "strawberry" is:
@goodside
-
LLMs struggle counting tokens without Chain-of-Thought or tools
By
–
What I'm disputing is the specific, but I think common, misconception that of course any LLM could count *tokens* easily; it's just that tokenization makes letters unnecessarily hard. Without CoT or tools, LLMs are just bad at counting.
-

Anthropic’s prompt caching enables more efficient LLM algorithms
By
–
Anthropic's prompt caching really should be better known. A lot of features that distinguish LLM vendors are incremental nice-to-haves, but prompt caching enables algorithms otherwise too slow and costly to consider:
-
Clarifying tokenization’s role in LLM inference
By
–
I fully concede tokenization causes important problems and an LLM trained without them would be more interesting than this thread. I’m only disproving a specific (but common I think) misunderstanding of its role in inference that does predict against these observations, namely:
-
Clarifying LLM token counting behavior
By
–
I agree and I clarify below I’m only claiming to disprove the (common I think) misunderstanding that LLMs normally do count tokens well, just not letters as a special case
-
On LLM tokenization and misgeneralization
By
–
Some people do take “LLMs see tokens not letters” at face value — i.e. the mental model is LLMs can of course count repetitions of a *token*, but a naive tokenizer makes letters an unnecessarily difficult task. Misgeneralization during training is different and more plausible.
-
Tokenization isn’t the only cause of LLM counting errors
By
–
Many LLM errors *are* downstream of tokenization oddities, surely. But the folk wisdom that two-R’s-in-strawberry mistakes happen *only* because the letters in “strawberry” are combined into longer prompt tokens before the model can count them is demonstrably not true.
-
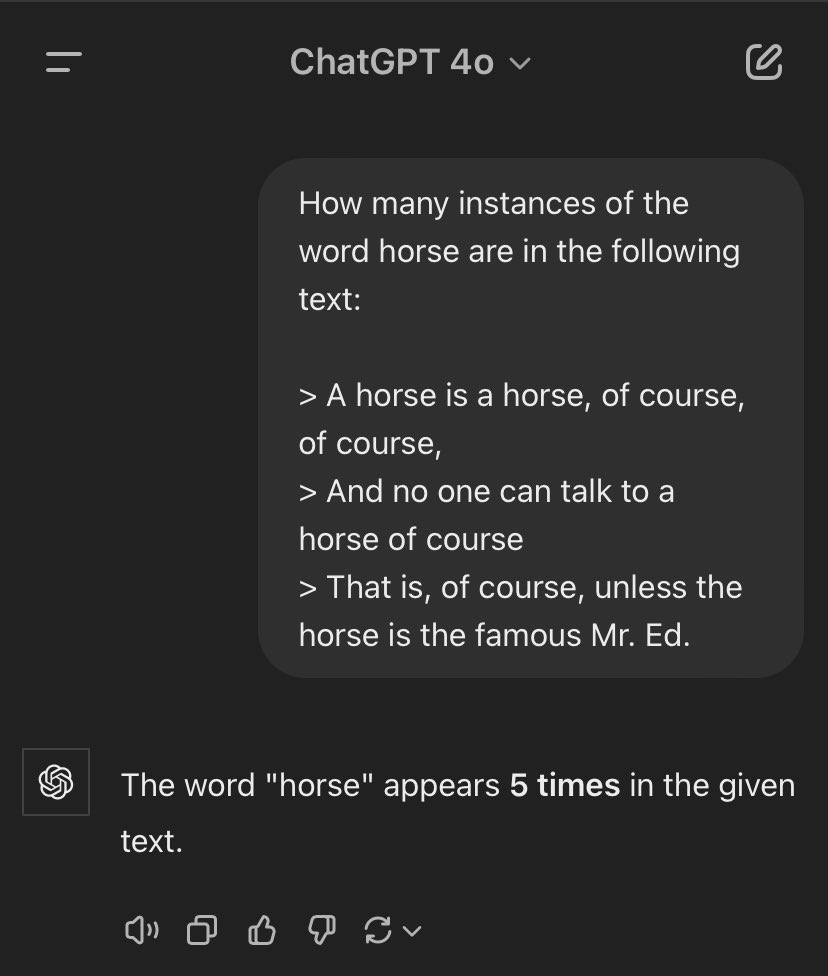
LLM counting errors: ChatGPT-4o miscounts repeated tokens
By
–
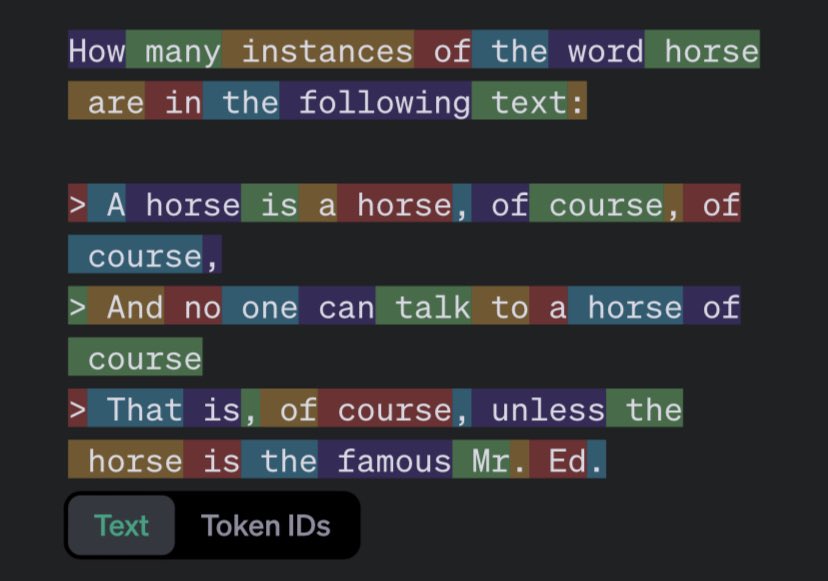
Another clue: LLM counting errors occur even when counting words instead of letters. Here, ChatGPT 4o miscounts just 4 repetitions of “horse” in a 3-line text, despite care to ensure each “horse” maps consistently to the same single token (20998, “horse” with a leading space):
-
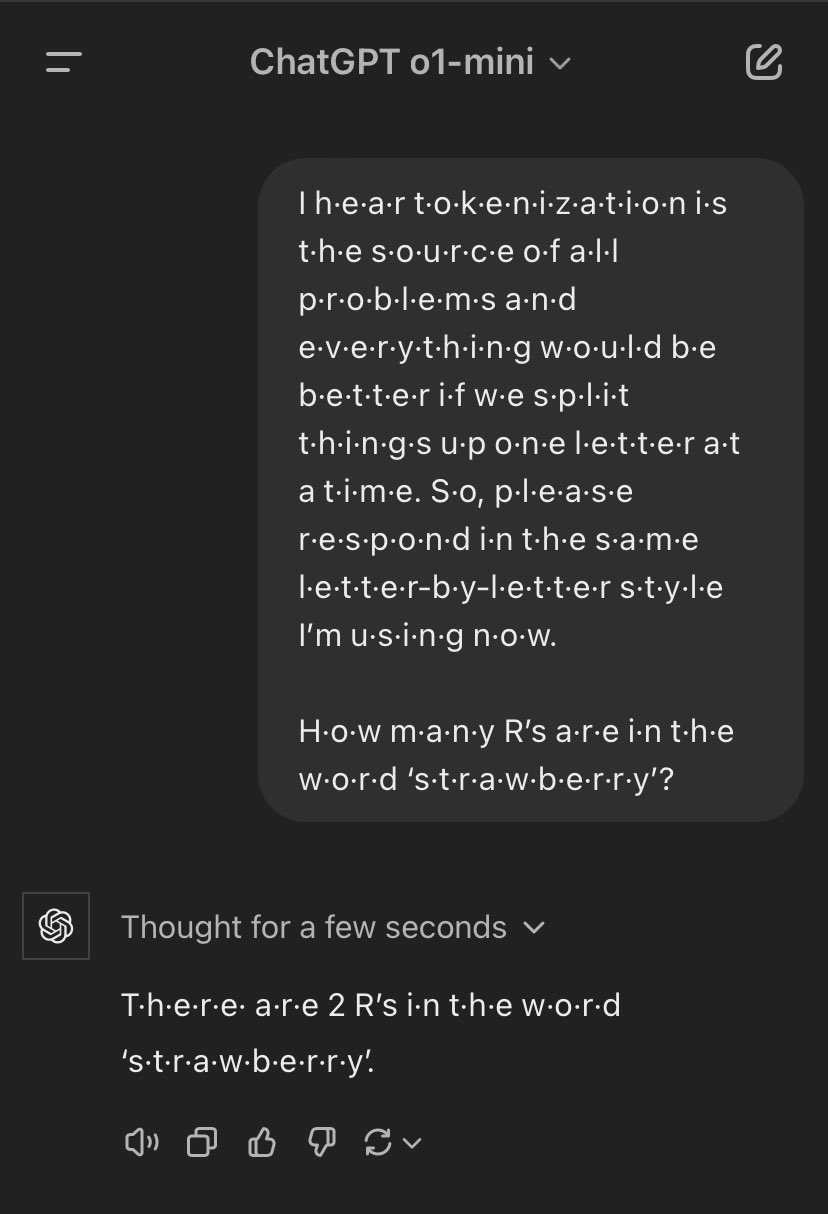
Similar responses from o1-mini and Claude 3.5 Sonnet
By
–

Similar responses responses to the same prompt can be seen from o1-mini and Claude 3.5 Sonnet. Other models left as an engagement-bait exercise for the reader.
-

GPT-4o tokenization splits ‘strawberry’ into single-character tokens
By
–
In both the prompt and response above, each letter in “strawberry” is assigned by the GPT-4o tokenizer to a separate single-character token, instead of being combined into subword-length tokens like “st” “raw” “berry” etc.: