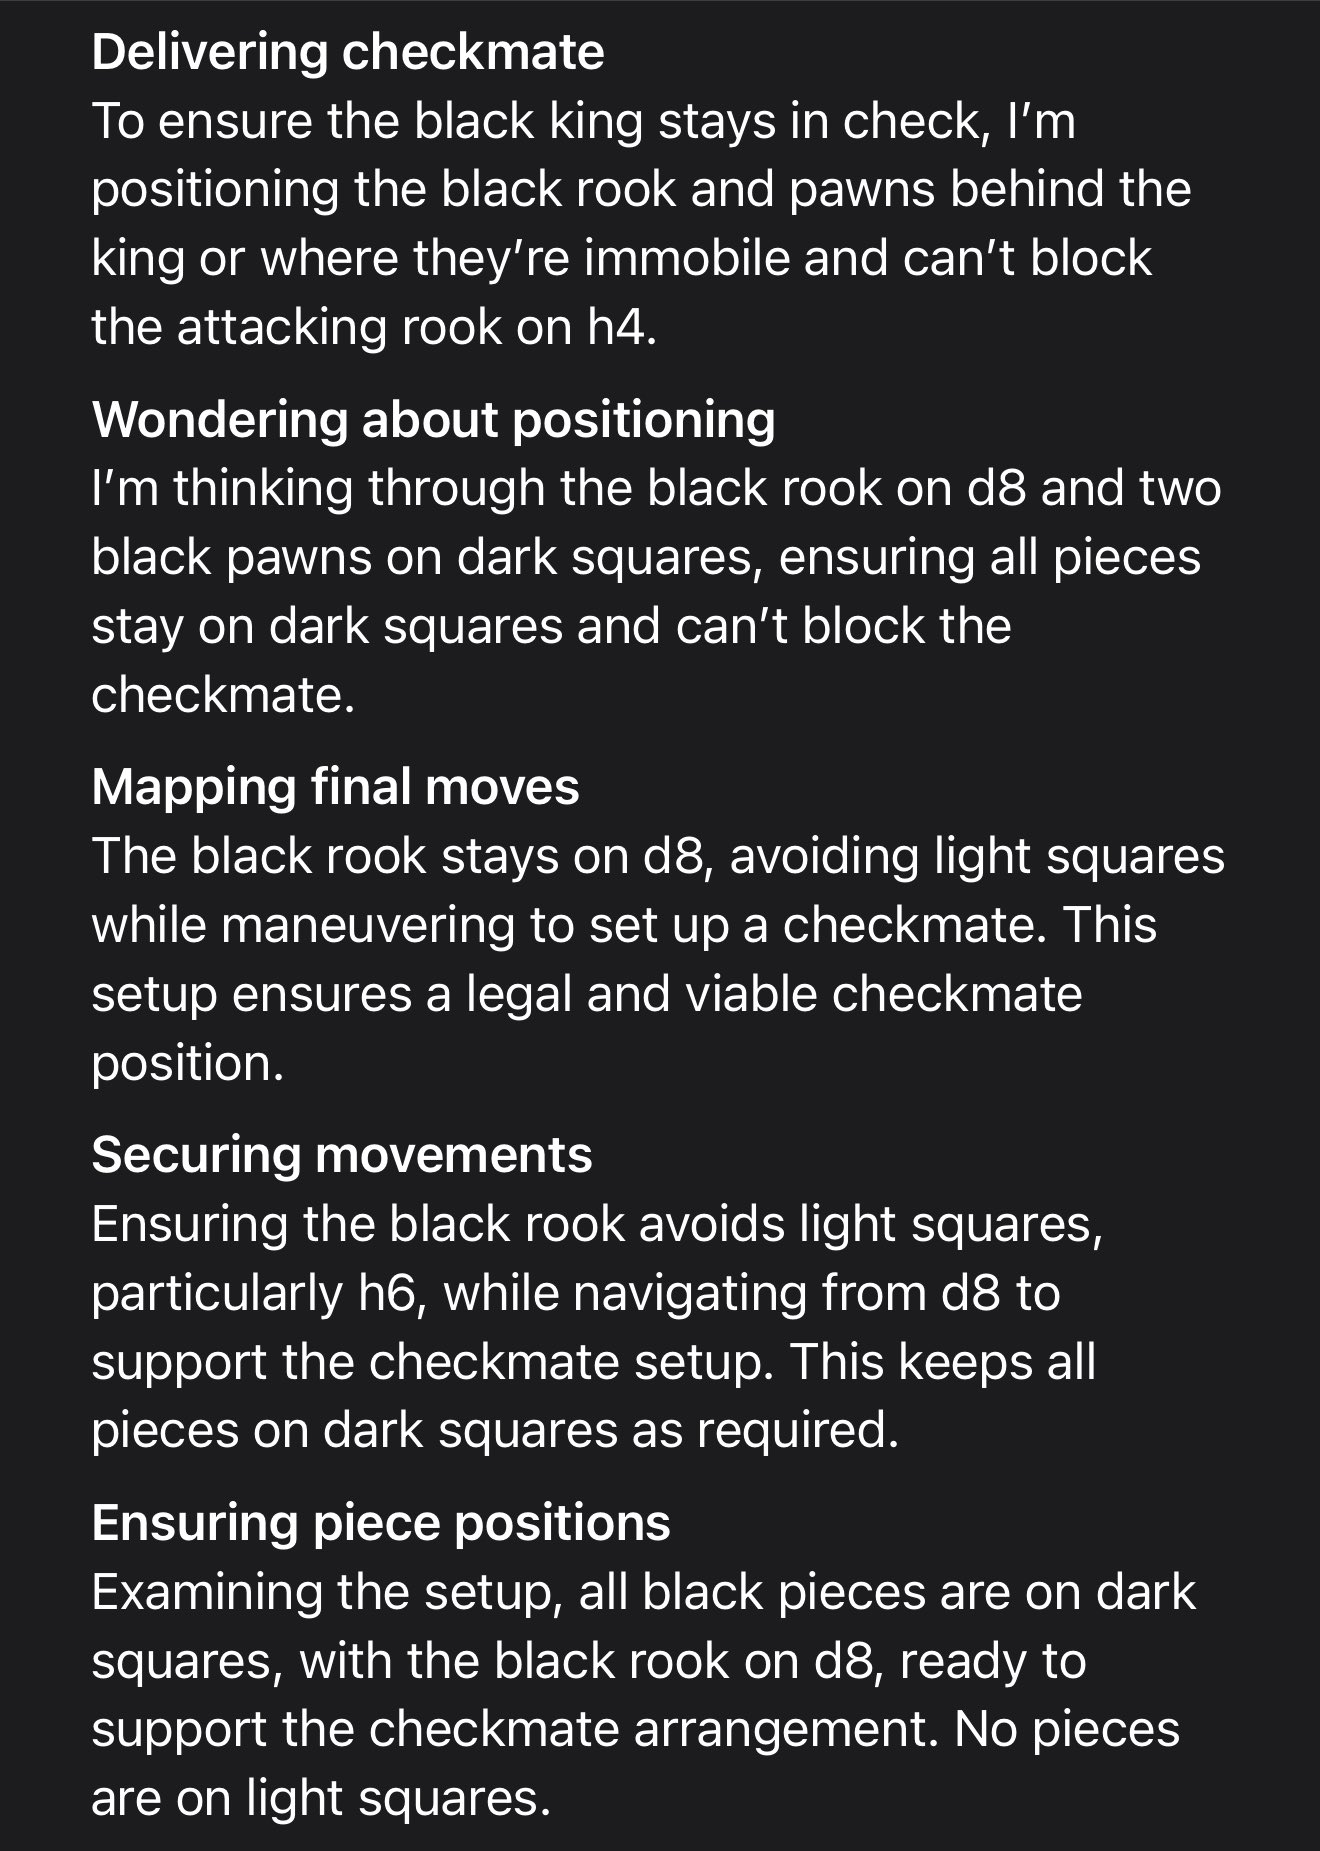
Also, the reason for the light square condition is to inject arbitrary novelty, adding credence the solution isn’t memorized from training I’m not worried it is; in that 5m45s o1 spews out a dozen pages of CoT summary broadly consistent with its answer — representative excerpt:
@goodside
-
AI model ‘o1 pro’ hits limits and produces illegal chess positions
By
–
This seems to be near the limit of what o1 pro can handle for this problem I first tried two pawns, two bishops, and a rook, but in four attempts o1 pro hit an error without returning and in the one that did, the position was not legal (both kings in check)
-
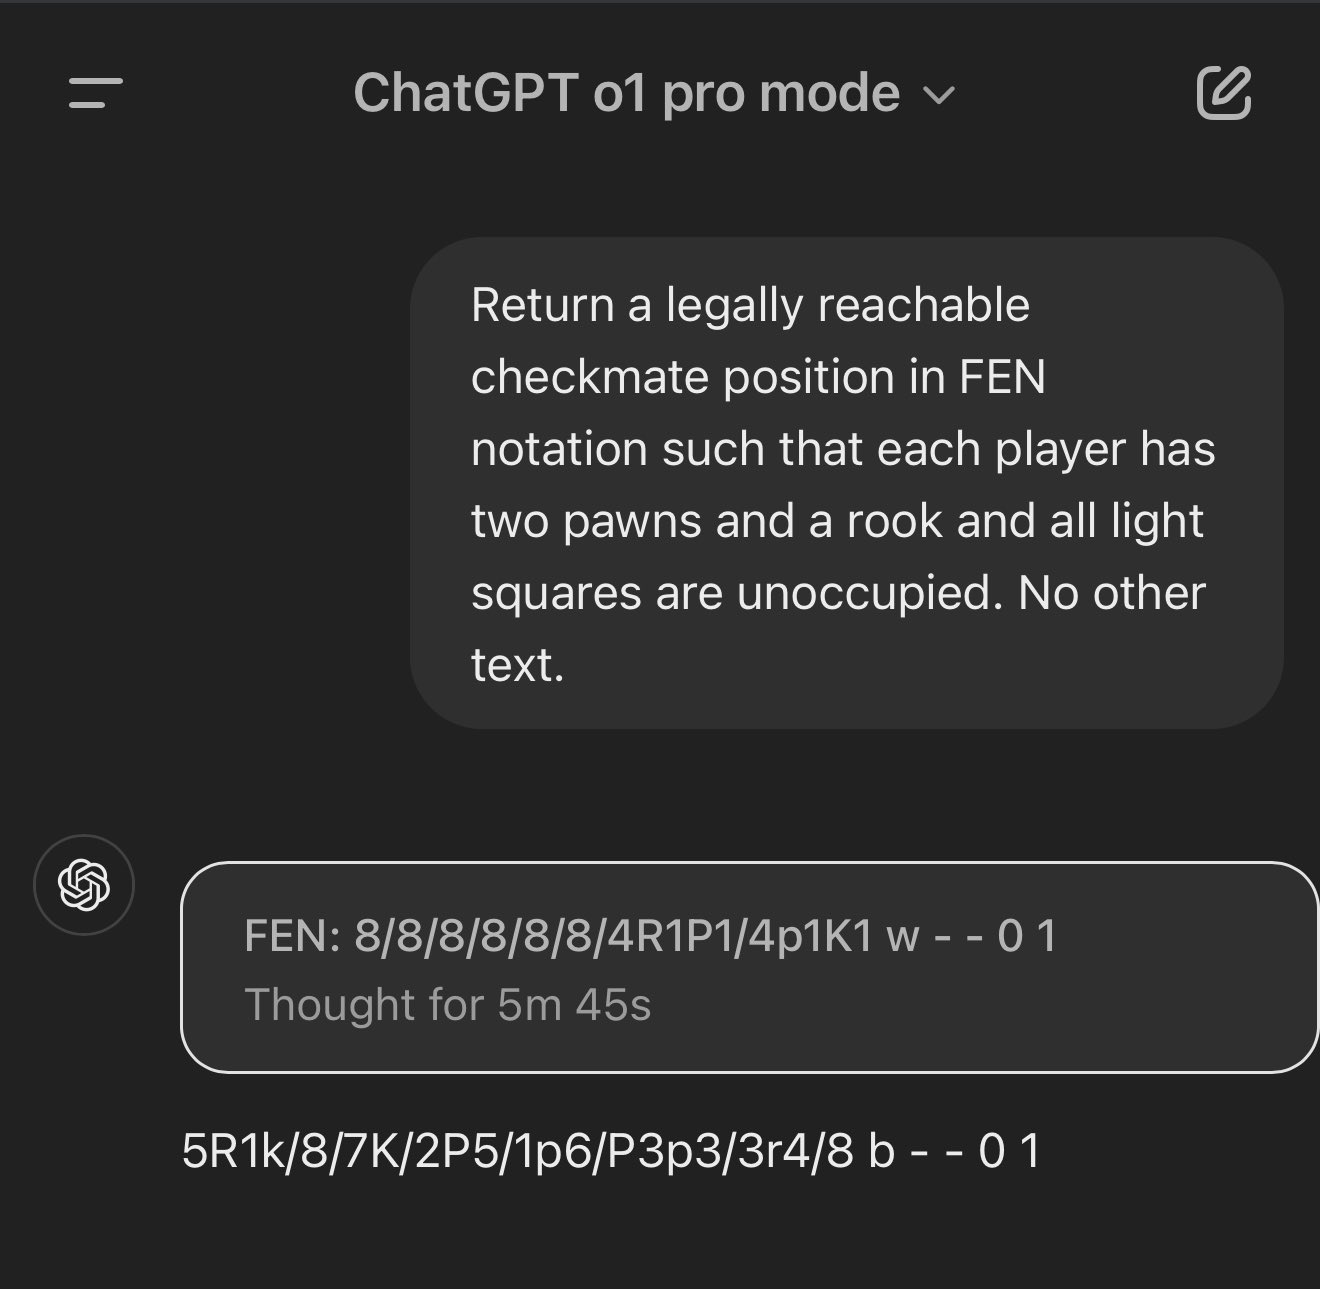
ChatGPT constructs a legal contrived checkmate
By
–
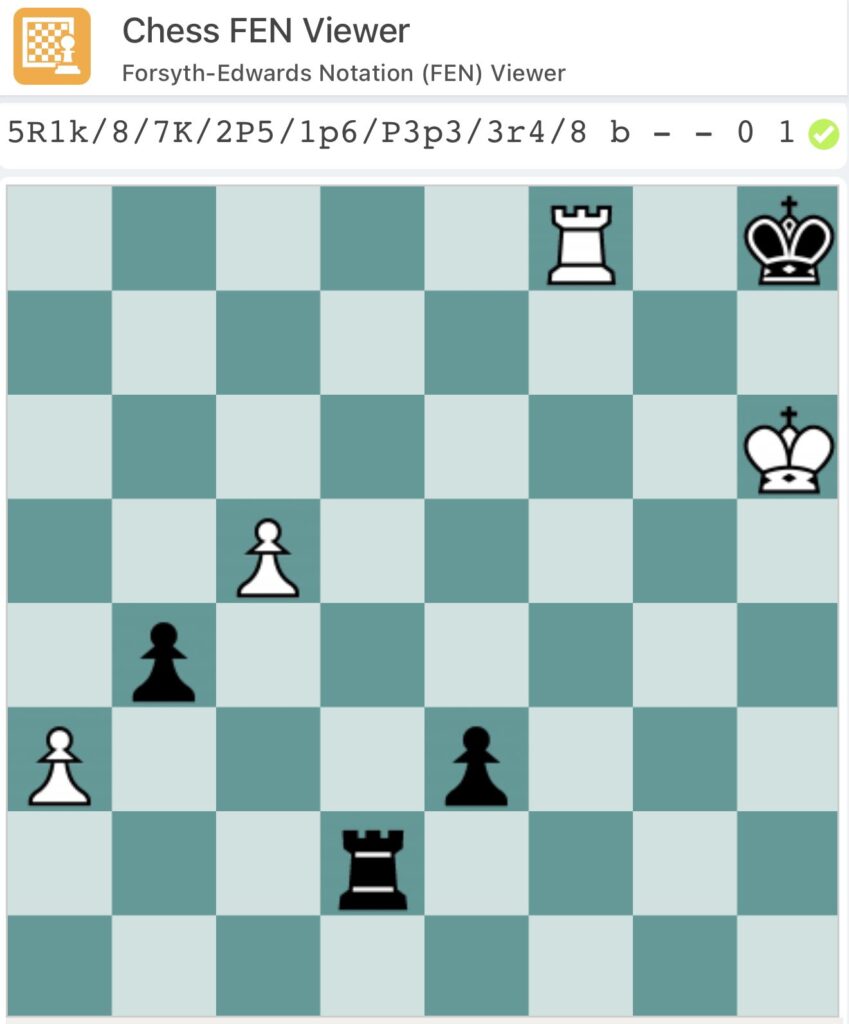
ChatGPT o1 pro constructs a legal (though contrived) checkmate position where each player has two pawns and a rook and all light squares are empty
-
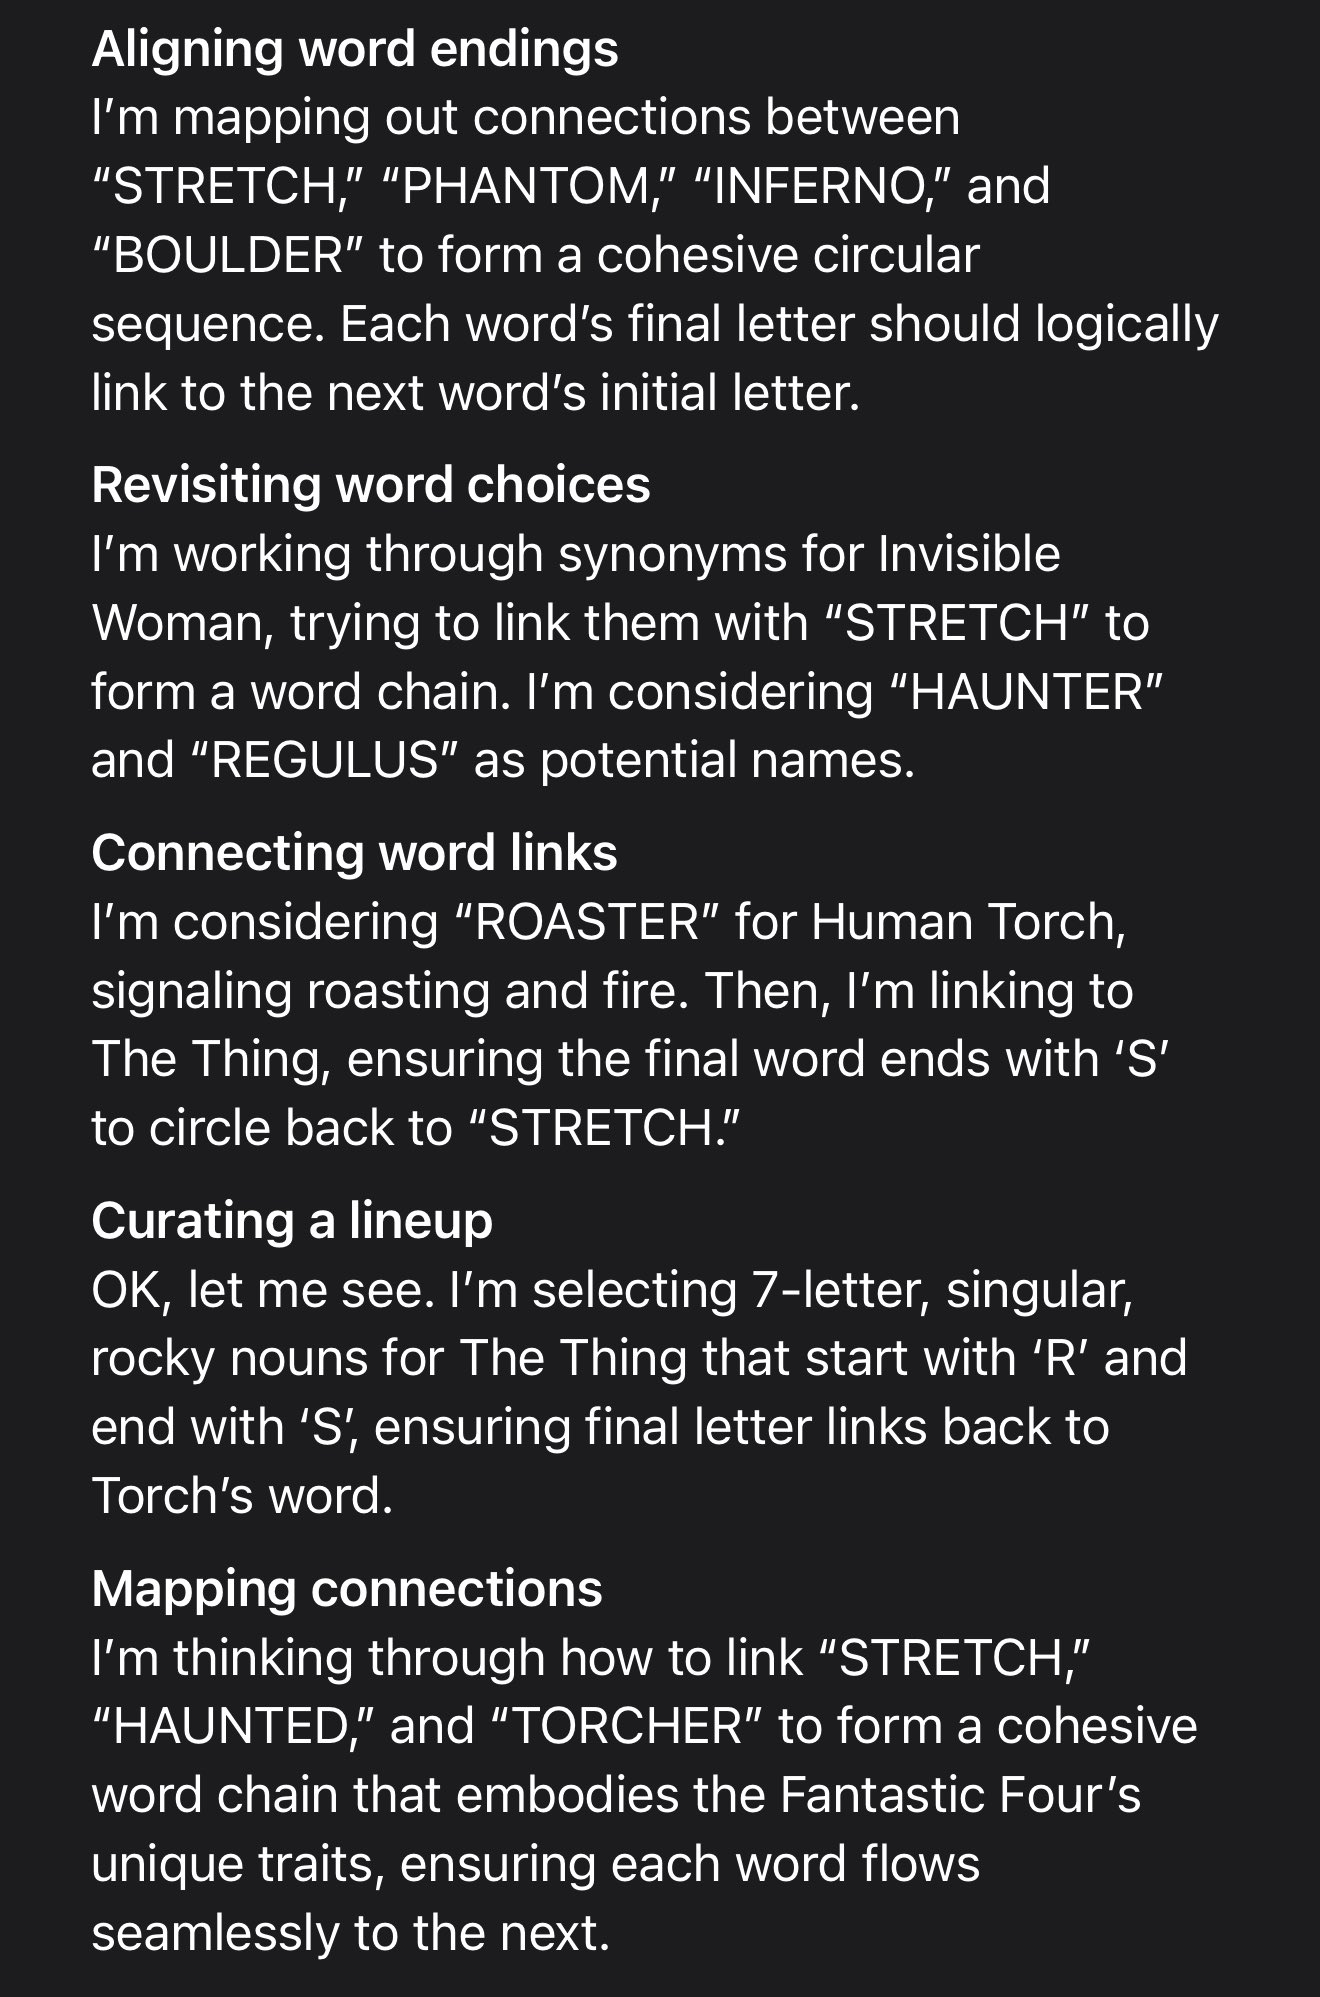
Chain-of-thought summary and AI categories
By
–
The CoT summary mostly what you’d expect — pages and pages of ideation about plausible nicknames and letter cycles, often nonsensically meandering. This is from the middle — imagine like 100 more pages of this stuff:
-
Speculation on token probabilities and tokenization artifacts
By
–
Just a guess but maybe “ouches” and “unction” are strings just below some threshold of probability of following a space to earn a token? E.g. “unction” would be from function names (where “f” is swallowed by an unseparated prefix) and “ouch” often follows an open-quote or dash.
-
Switching model variants to use code interpreter for SVG download
By
–
It doesn’t have a code interpreter. When I did my previous post creating an SVG, I had to make the SVG in o1 and then switch the chat to 4o make it a downloadable file, and once you do that it won’t let you switch back because o1 doesn’t support code.
-
Comparing o1 model capabilities versus REPL
By
–
It isn’t important; this task isn’t practical at all; it’s just a compact illustration of the broadened class of tasks o1 can do vs earlier models, e.g. tasks that seem to require a guess-and-check loop with dozens of iterations REPL is still best for many real-world tasks
-
User observation about OpenAI model tool access
By
–
Yeah that’s why I said “claims to be” — everything OpenAI releases is technically a black box but I have no reason to doubt them; it seems clear from using it that o1 doesn’t have tool access even when it could use it
-
LLM struggles with counting and arithmetic despite code workarounds
By
–
Yeah, it’s actually not a hard problem in code — you just iterate over x values from 0 until you find one that works. What makes it remarkable here is just that counting letters and arithmetic are traditionally hard for LLMs and o1 claims to not be using tools/code