Why this matters for open source: Dense models: Entire model needs retraining if you want to change anything
MoE models: Swap experts, add capabilities, fine-tune components independently Meta released Llama 405B (dense) – $50M+ training cost
DeepSeek released V3 (MoE) – $5.6M,
@godofprompt
-

MoE vs Dense Models: Cost Efficiency
By
–
-
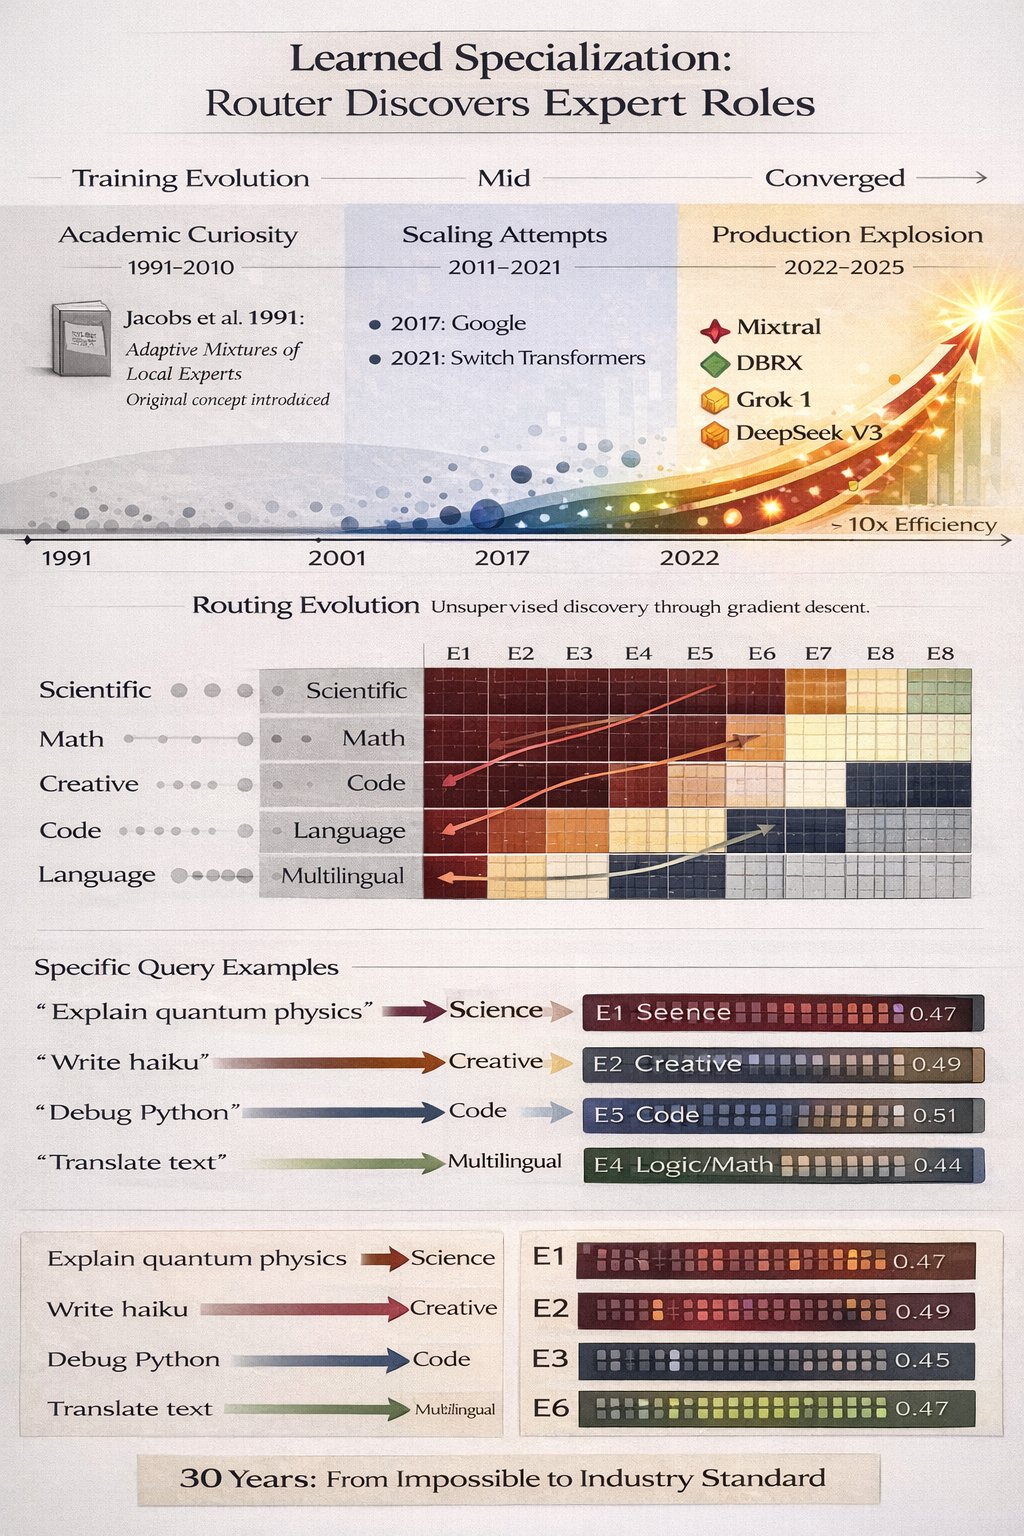
Router learns input-expert affinity patterns
By
–
The router is smarter than you think. It doesn't just pick experts randomly. It learns input-expert affinity during training. "Explain quantum physics" → activates Science + Technical experts
"Write a poem about love" → activates Creative + Emotional experts Specialized -
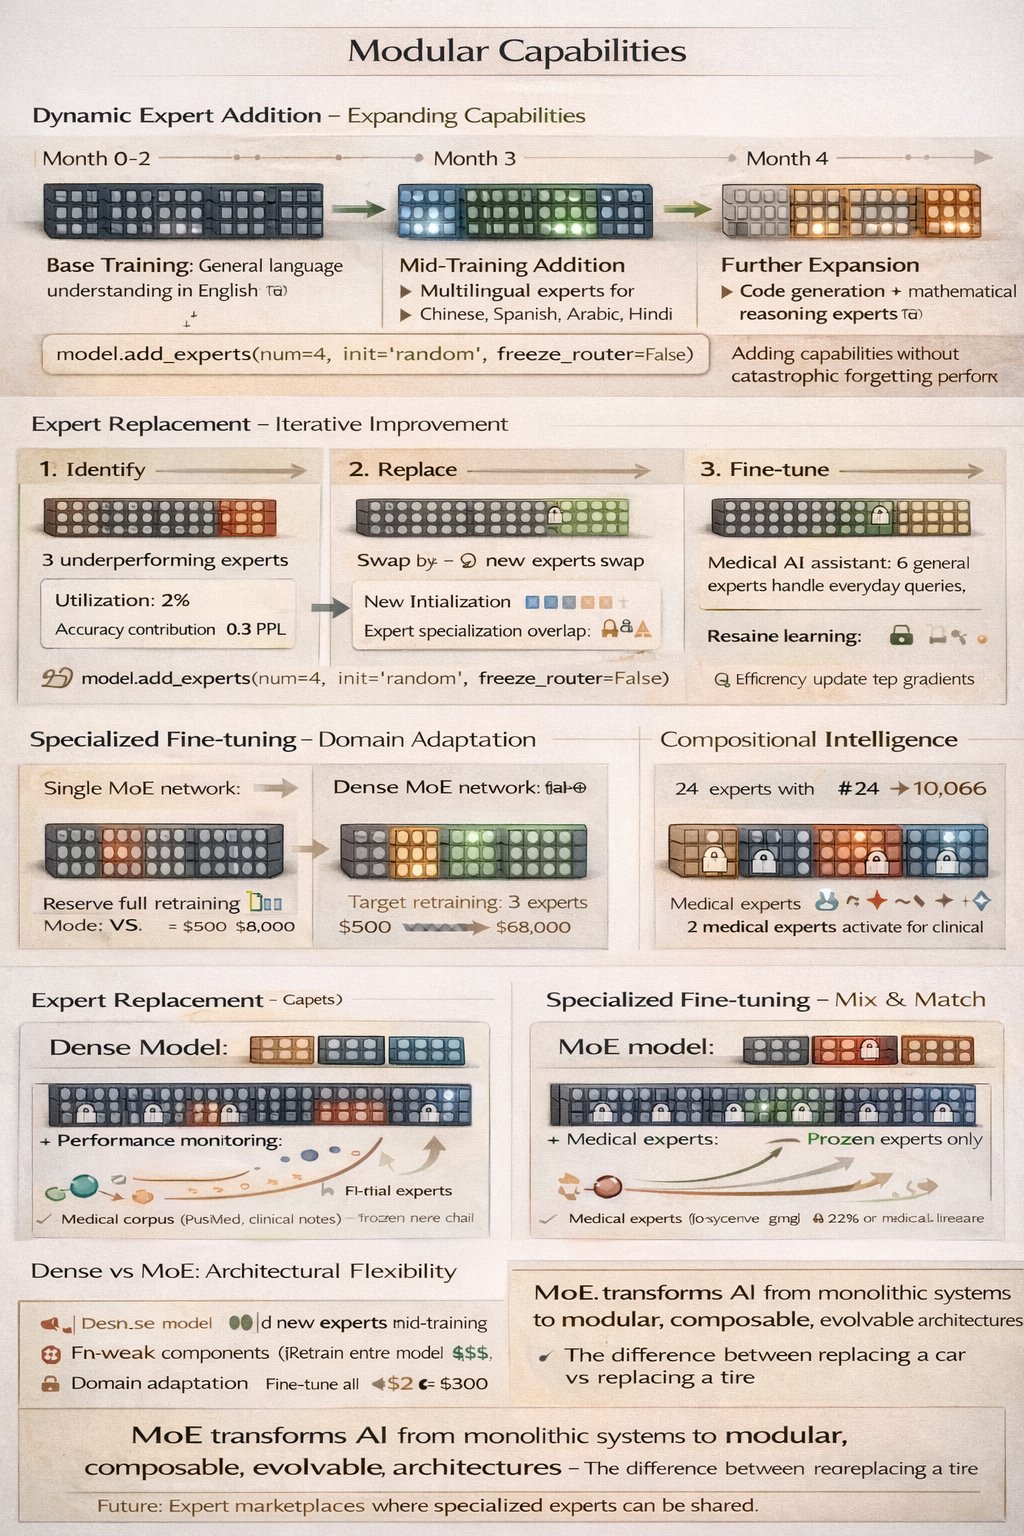
MoE’s Hidden Potential: New Training Strategies
By
–
Here's the part nobody talks about: MoE doesn't just save compute. It enables entirely new training strategies. You can: → Add experts mid-training for new capabilities
→ Replace underperforming experts without retraining everything
→ Fine-tune individual experts on -

MoE Architecture: 5-10x More Parameters
By
–
The modern MoE architecture is insane: > Mixtral 8x7B: 47B total params, only 13B active per token
> DeepSeek-V3: 671B params, 37B active – beats GPT-4 at 1/10th cost
> Grok-1: 314B params, trained faster than any dense model of similar quality Pattern: 5-10x more parameters. -
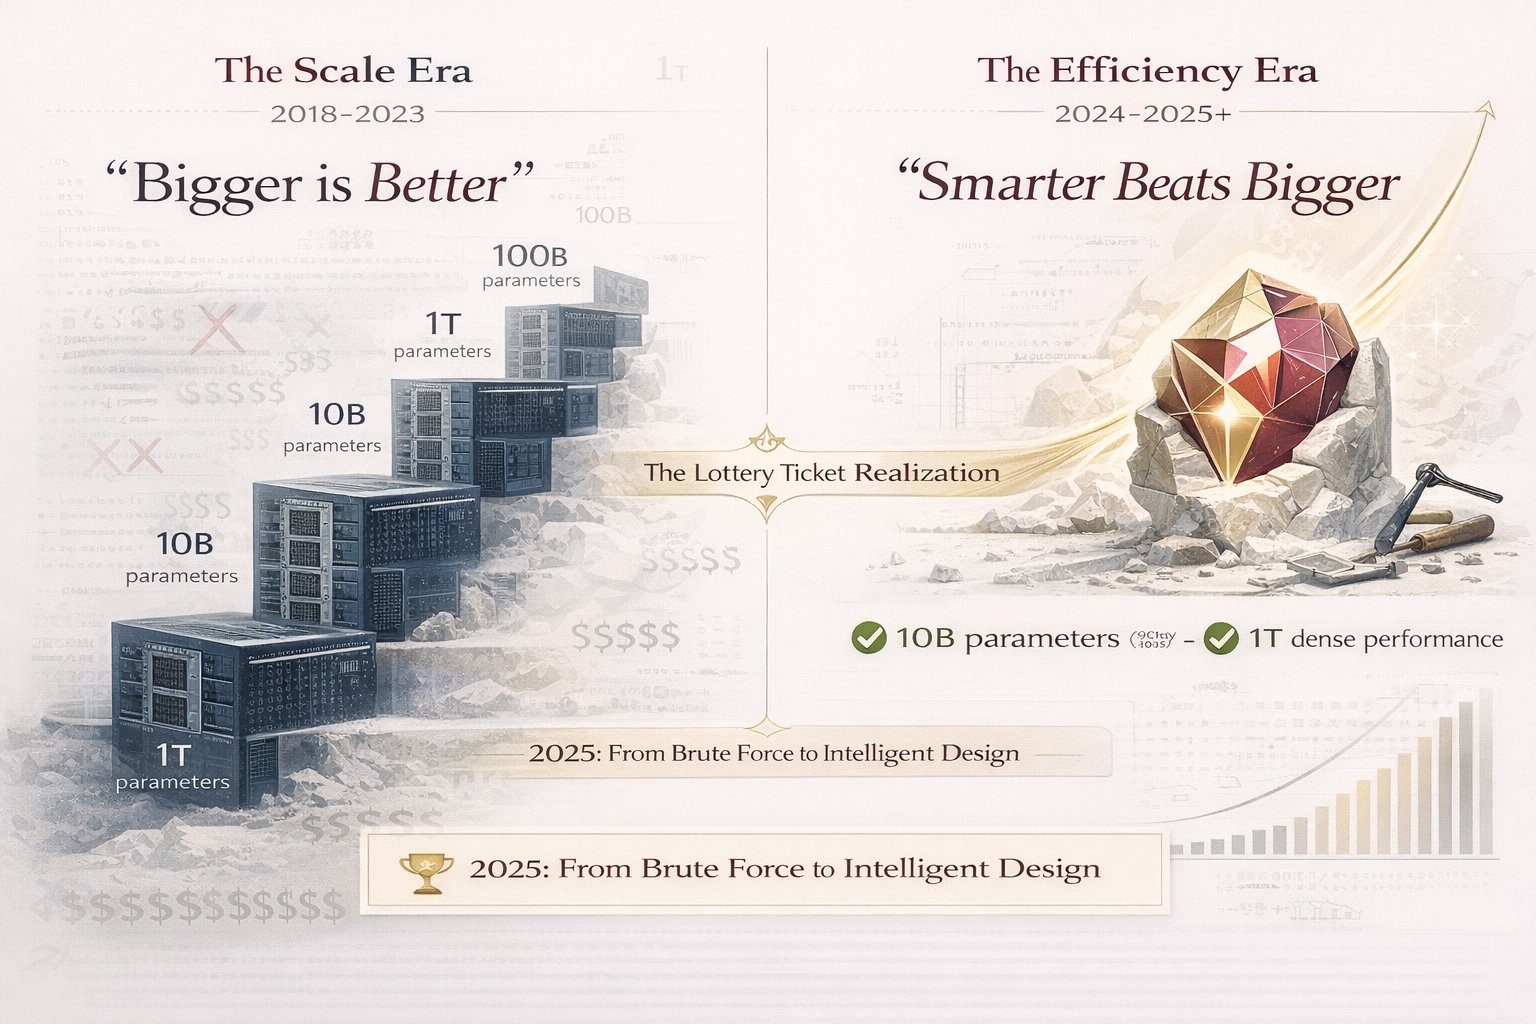
The Efficiency Era of AI Models
By
–
The lottery ticket hypothesis wasn't wrong. We just weren't ready for it. In 2025, sparse models are no longer academic curiosities. They're production infrastructure. The future isn't bigger models. It's smarter pruning. Welcome to the efficiency era. Read it here if you
-
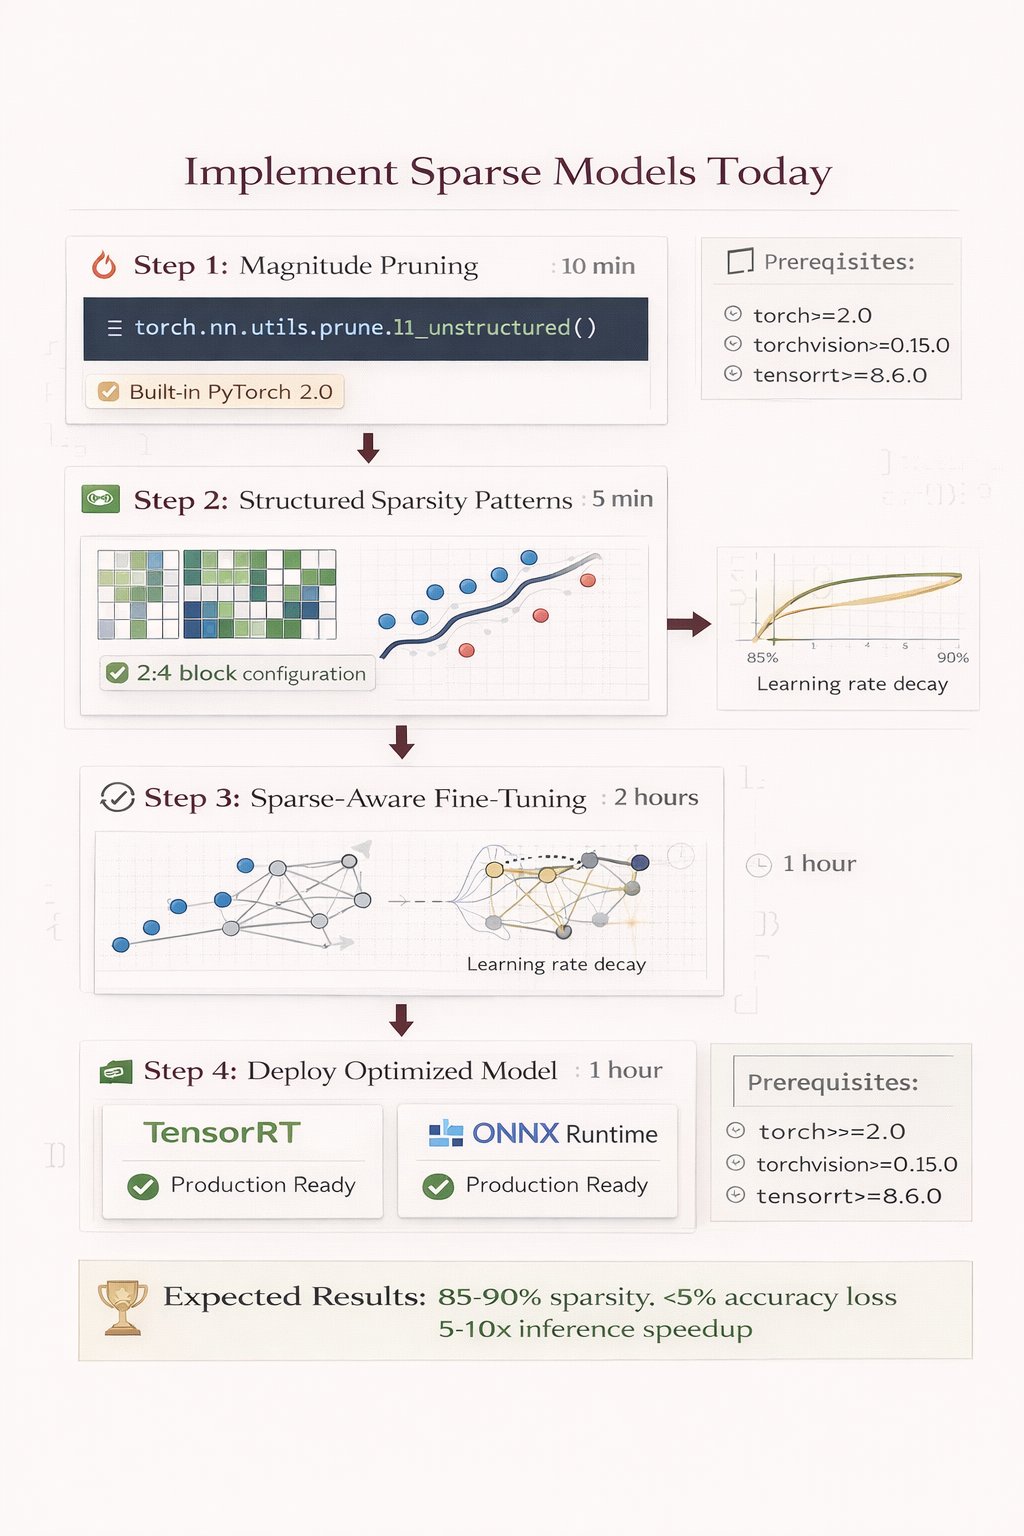
Implementing Sparse Model Training Today
By
–
How to implement this today: 1. Use PyTorch's torch.nn.utils.prune for magnitude pruning
2. Apply 2:4 structured patterns for GPU acceleration
3. Fine-tune with sparse-aware training
4. Deploy with TensorRT or ONNX Runtime The infrastructure exists. Most teams just don't know -

Sparse models generalize better than dense ones
By
–
The counterintuitive part: Sparse models often generalize BETTER than dense ones. Why? Dense networks memorize noise. Sparse networks are forced to learn robust features. It's not just cheaper. It's actually better science.
-

Sparse Models Deliver Real-World Gains
By
–
Real-world results from companies already deploying sparse models: OpenAI: 40% cost reduction on GPT-4 API
Meta: 3x throughput increase for Llama inference
Google: 60% memory savings for production transformers The early adopters are already winning. -
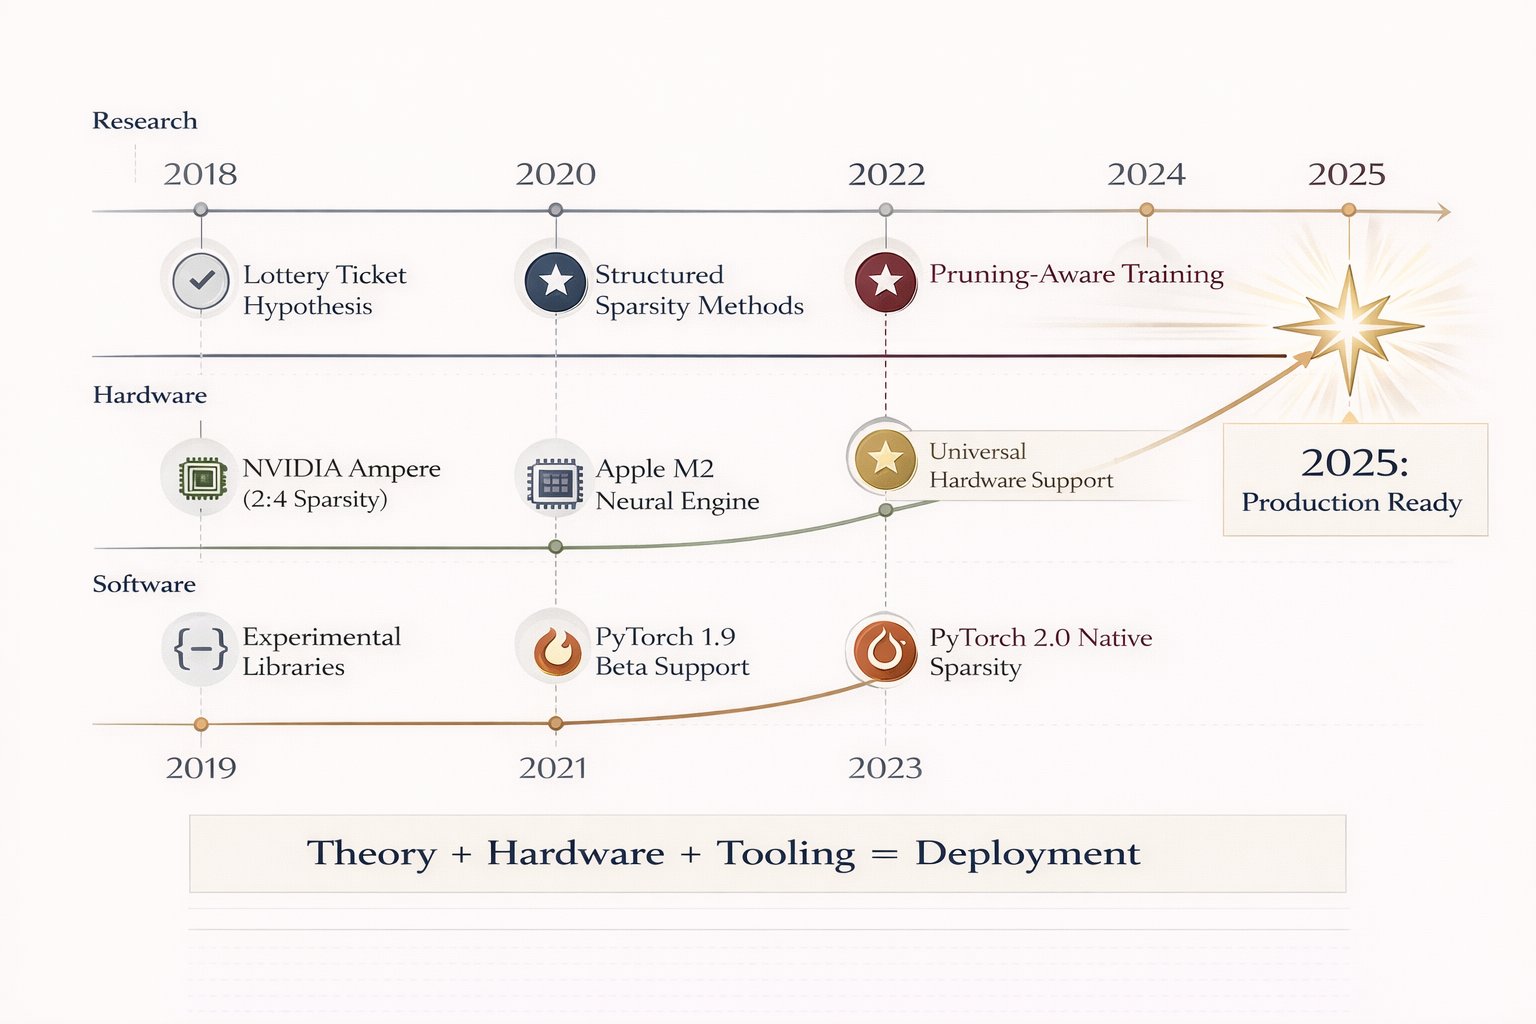
2026 Breakthroughs Made AI Production-Ready
By
–
Three breakthroughs made this production-ready in 2026: 1. Pruning-aware training (train sparse from the start)
2. Hardware support (NVIDIA Ampere+, Apple Neural Engine)
3. Framework integration (PyTorch 2.0 native sparsity) The tooling finally caught up to the theory. -
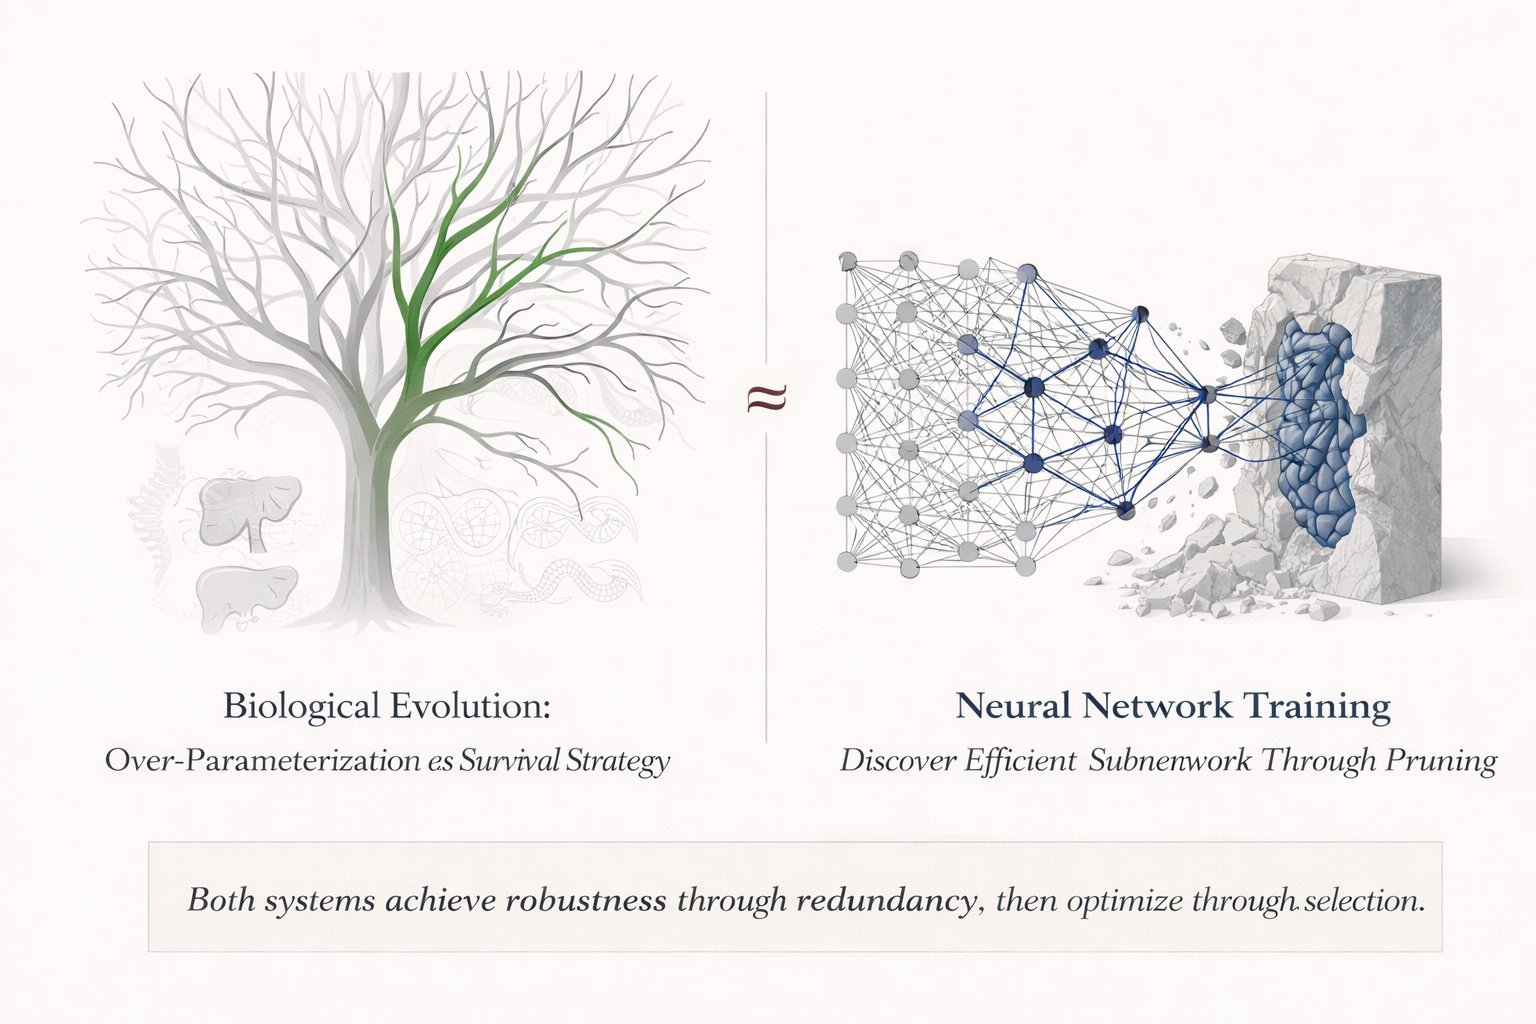
Neural networks are 90% redundant by design
By
–
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.