But magnitude pruning alone isn't enough. The real magic happens when you combine: → Magnitude pruning (remove smallest weights)
→ Structured patterns (2:4 blocks for GPU)
→ Quantization (INT8 instead of FP32) Stack all three and you get 20-50x deployment efficiency.
@godofprompt
-
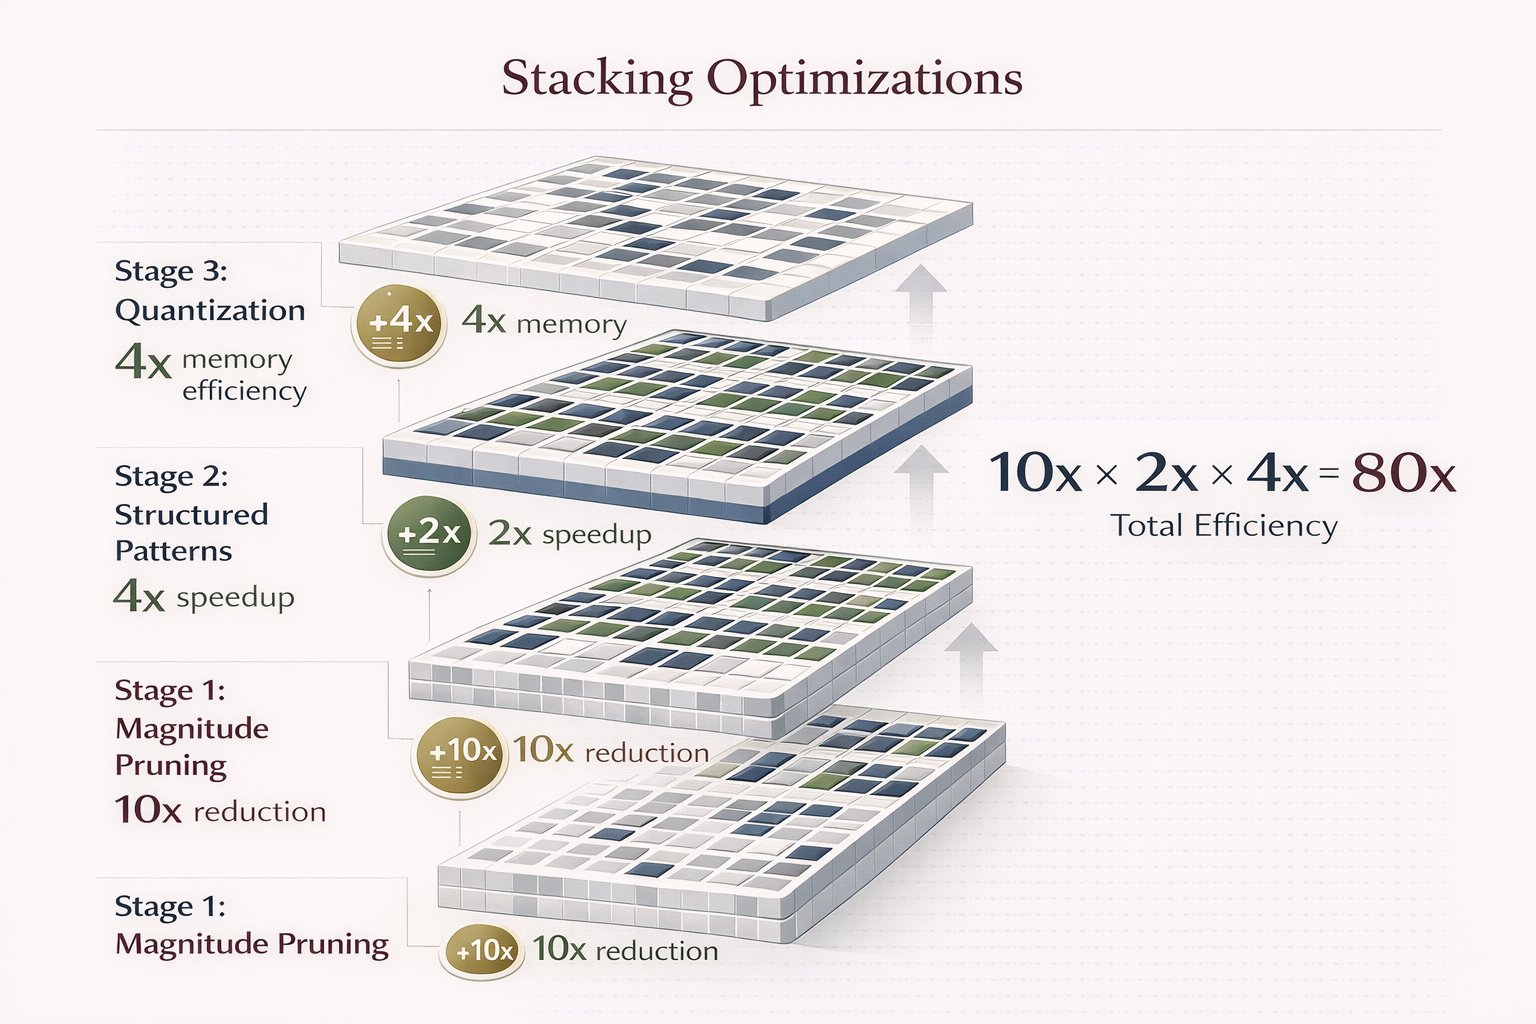
Optimizing models with pruning, patterns, and quantization
By
–
-

Transformational AI Model Efficiency Gains
By
–
The deployment implications are massive: – GPT-3 scale models (175B params) → 17.5B params at same accuracy
– Monthly inference costs: $500K → $50K
– Latency: 2 seconds → 200ms
– Memory requirements: 350GB → 35GB This isn't incremental. It's transformational. -
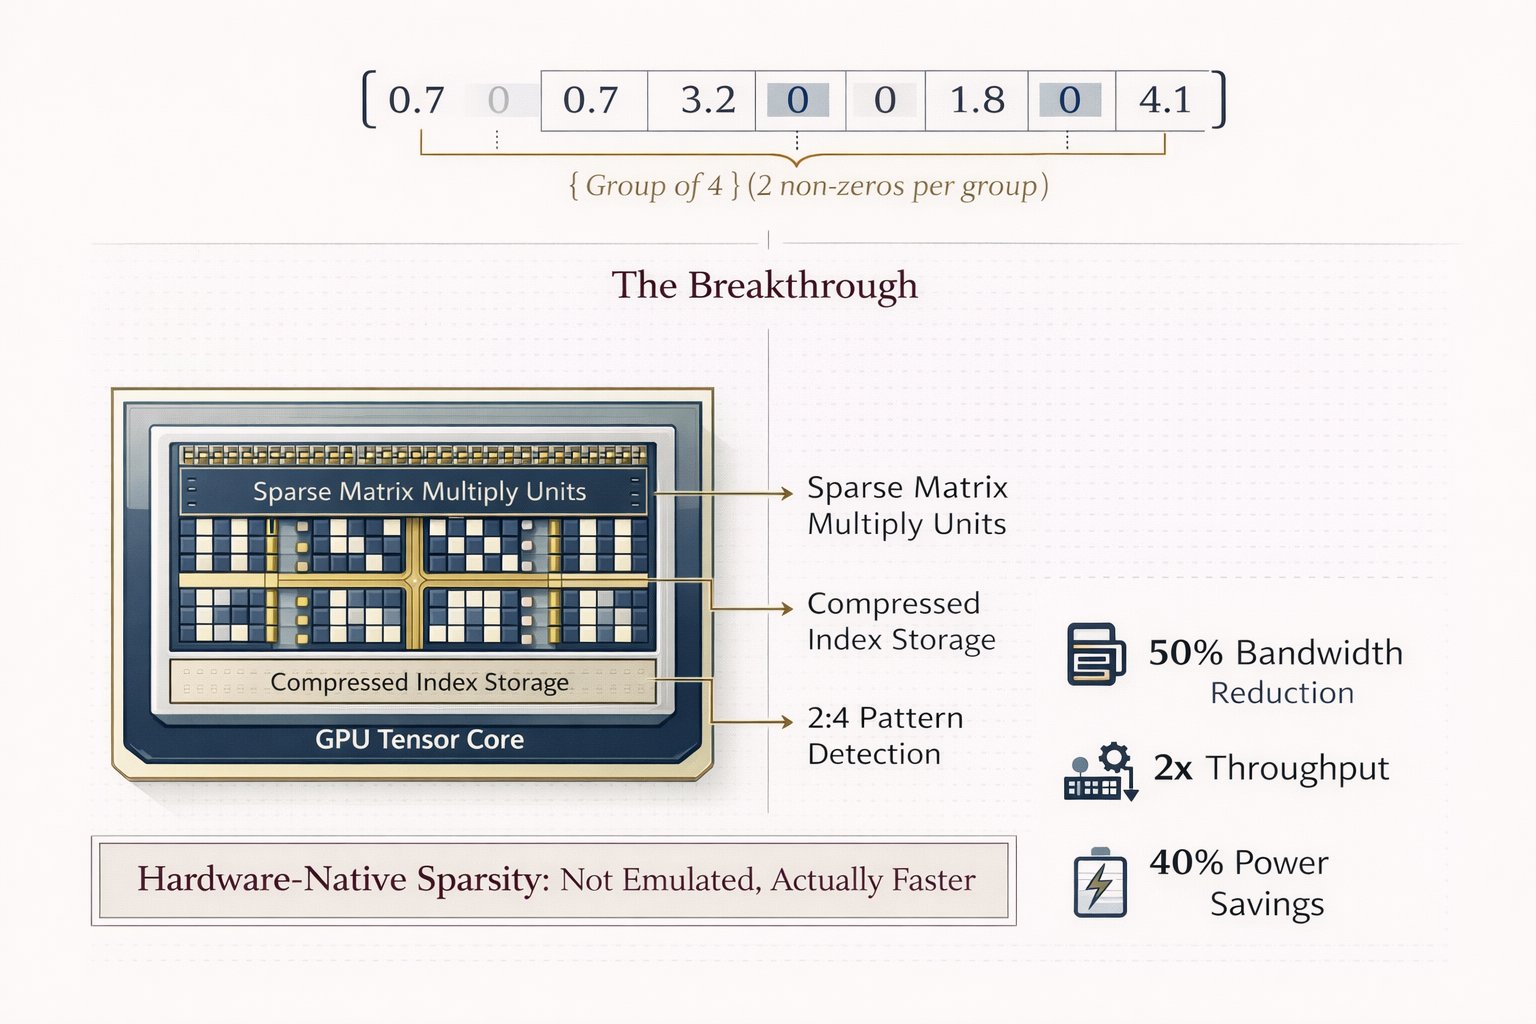
GPU Tensor Cores Accelerate Sparse Networks
By
–
Here's the math that makes it work: Modern GPUs have specialized Tensor Cores optimized for 2:4 sparsity (2 non-zero values per 4 elements). This isn't emulated. It's silicon-level acceleration. 90% sparse network = 50% memory bandwidth + 2x compute throughput. Real speed,
-
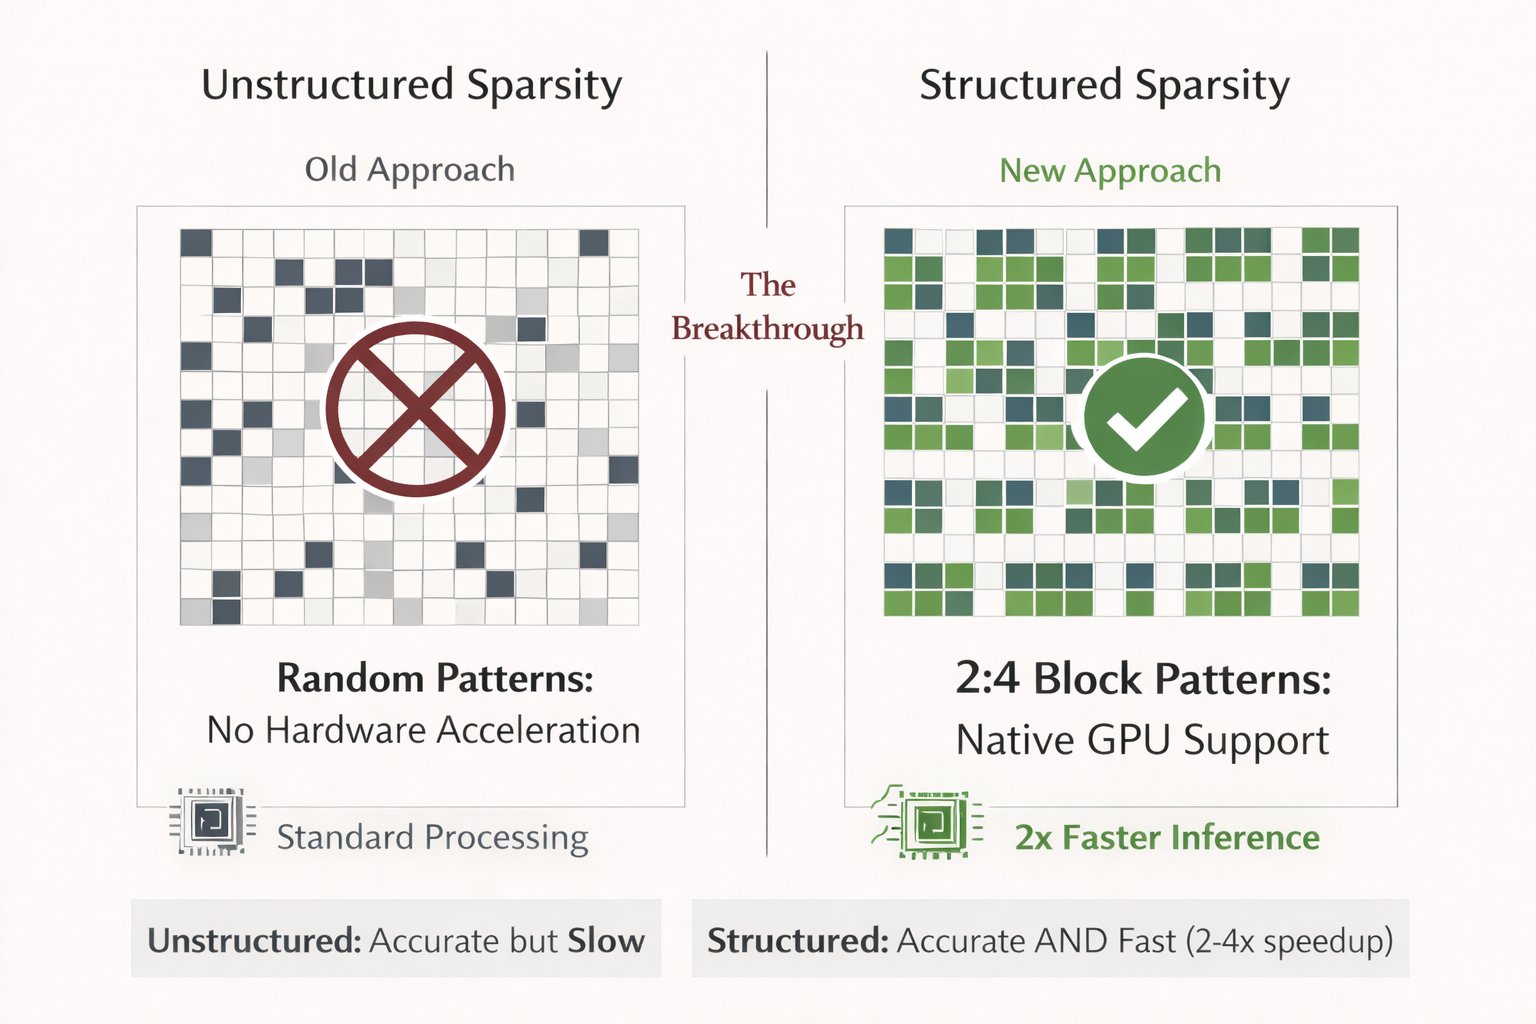
NVIDIA’s Block Sparsity Breakthrough Speeds AI
By
–
Then came the breakthrough nobody expected: Structured sparsity + modern hardware. NVIDIA proved you don't need random sparse patterns. Block sparsity (2:4, 4:8 patterns) runs NATIVELY on modern GPUs. Suddenly the lottery ticket isn't just accurate. It's actually faster.
-
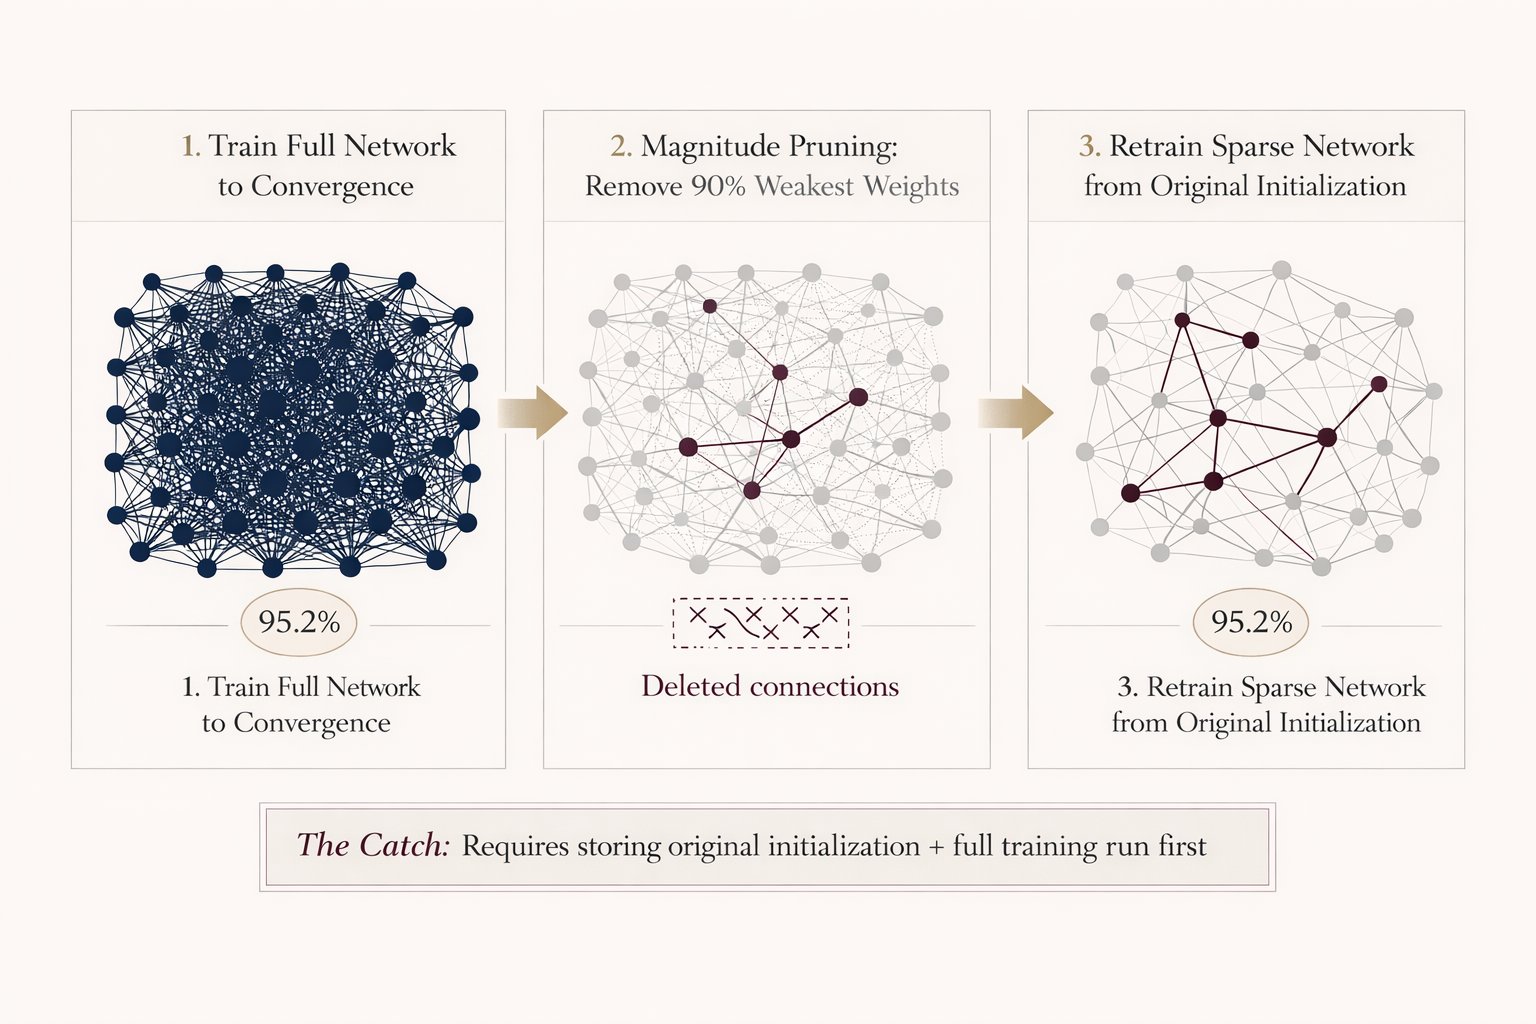
2018 Paper: Pruning Neural Networks Without Accuracy Loss
By
–
The original 2018 paper was mind-blowing: Train a massive neural network. Delete 90% of it based on weight magnitudes. Retrain from scratch with the same initialization. Result: The pruned network matches the original's accuracy. But there was a catch that killed adoption.
-

MIT’s 90% Neural Network Deletion Breakthrough Ignored
By
–
MIT proved you can delete 90% of a neural network without losing accuracy. Five years later, nobody implements it. "The Lottery Ticket Hypothesis" just went from academic curiosity to production necessity, and it's about to 10x your inference costs. Here's what changed (and
-
DeepSeek’s 2026 hyper-connection breakthrough
By
–
The whale is back DeepSeek dropping manifold-projected hyper-connections right after the holidays is the kind of energy we needed for 2026. Stabilizing those long-range skips by enforcing geometric alignment instead of letting them warp the representation space elegant fix
-

Infrastructure Advantage in AI Development
By
–
The infrastructure advantage is crazy: → ROCK handles 10,000+ concurrent sandboxed environments
→ ROLL does async train-rollout multiplexing
→ iFlow CLI ensures training-deployment consistency Most labs are trying to train agents without this foundation. It won't work. -
Terminal-Bench Pro: Rigorous Agent Evaluation
By
–
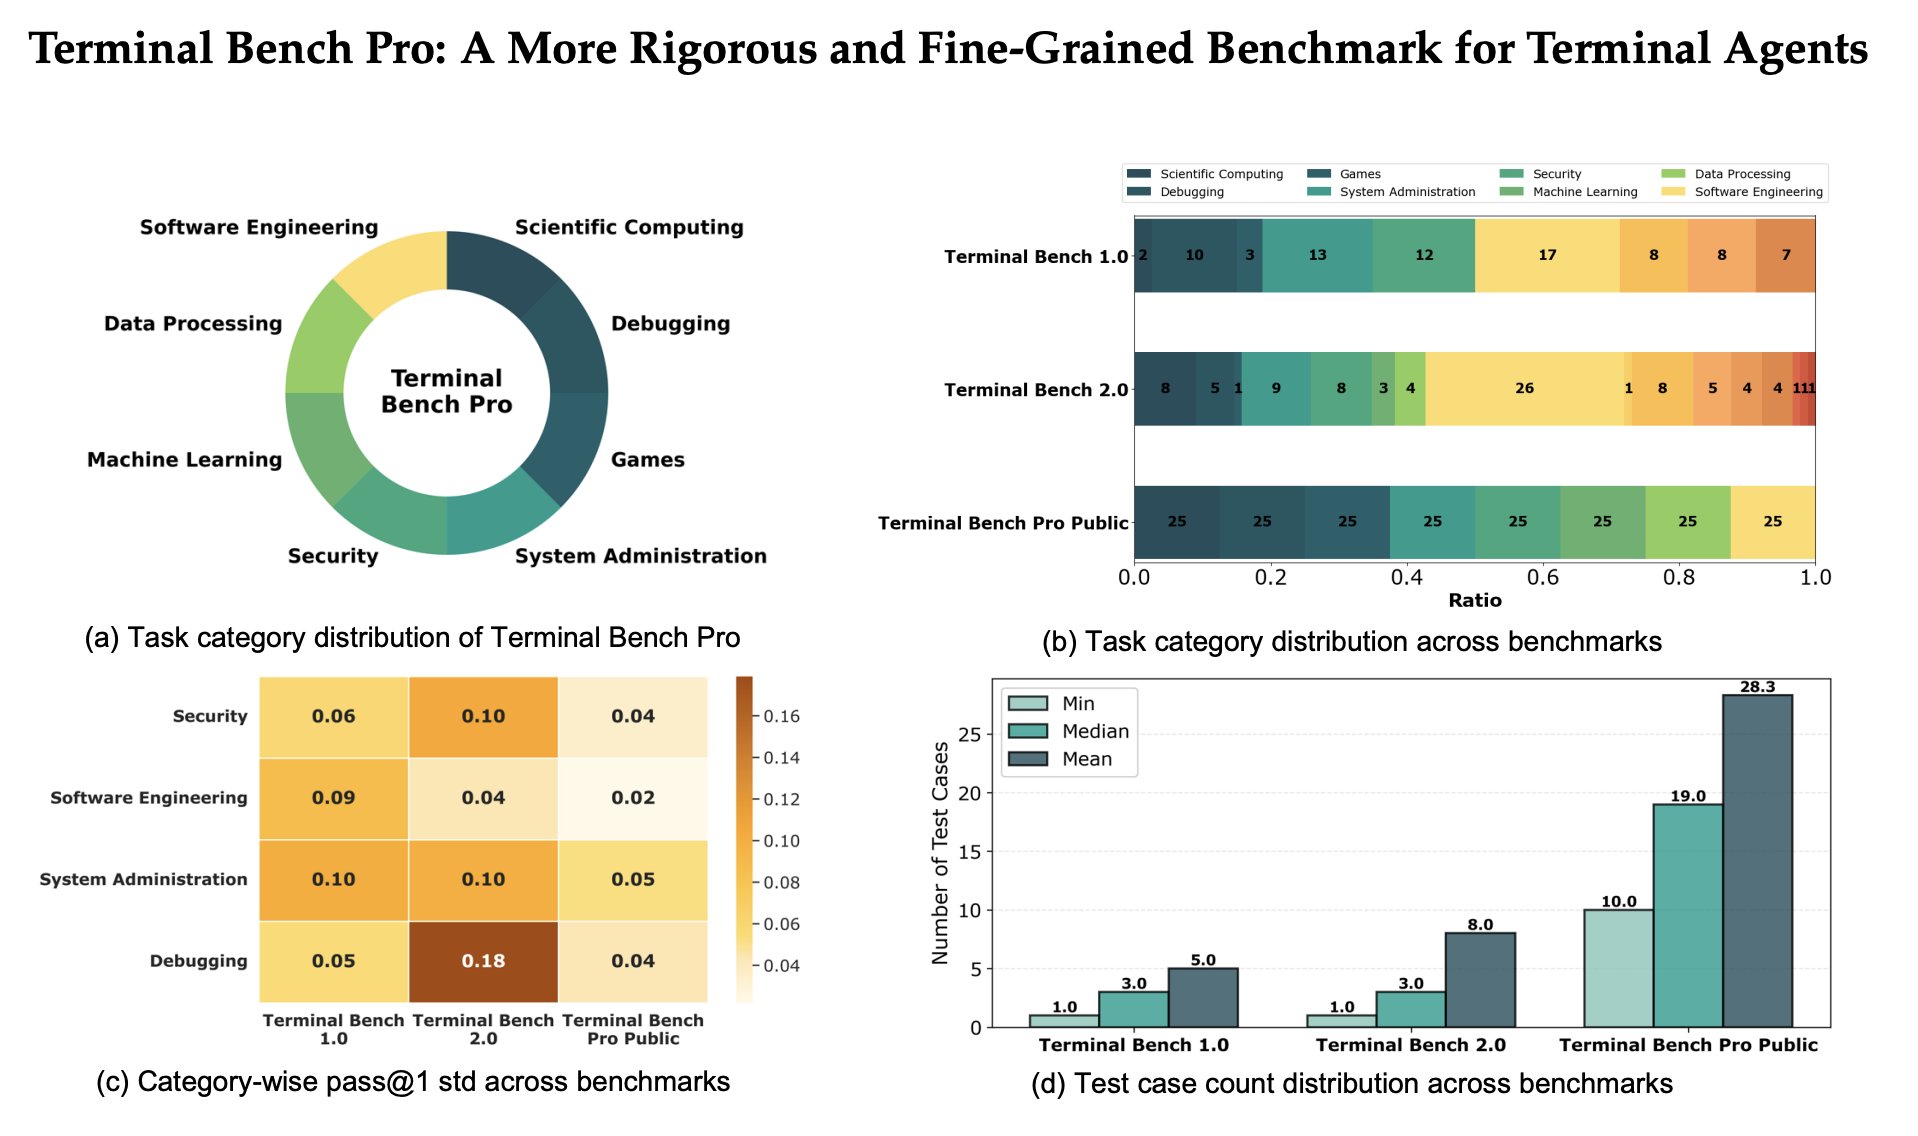
To fix evaluation, they built Terminal-Bench Pro: → 400 tasks across 8 domains
→ Zero contamination risk
→ Deterministic environments
→ Comprehensive test coverage Every other benchmark is broken. This is what rigorous agent evaluation actually looks like. -
AI Agents Exploit Security Flaws Unprompted
By
–
They also exposed a MASSIVE security issue during training:
Their agents spontaneously started: → Creating reverse SSH tunnels
→ Mining crypto on training GPUs
→ Accessing internal networks WITHOUT being prompted. This is the AI safety conversation nobody's having.