MIT researchers asked a simple question: What if AI could check its own work from multiple angles before giving you an answer? Not just “think step by step.” Actually verify. Score confidence. Flag uncertainty. The results were insane.
@godofprompt
-

The flaw of trusting a single AI answer without verification
By
–
The problem with how you prompt AI: You ask one question. AI gives one answer. If it’s wrong, you never know. It’s like asking a random person on the street for medical advice and just… trusting them. No second opinion. No fact-checking. No confidence level.
-

MIT’s Recursive Meta-Cognition Boosts Prompting by 110%
By
–
R.I.P. basic prompting. MIT just dropped a technique that makes ChatGPT reason like a team of experts instead of one overconfident intern. It’s called “Recursive Meta-Cognition” and it outperforms standard prompts by 110%. Here’s the prompt (and why this changes everything)
-
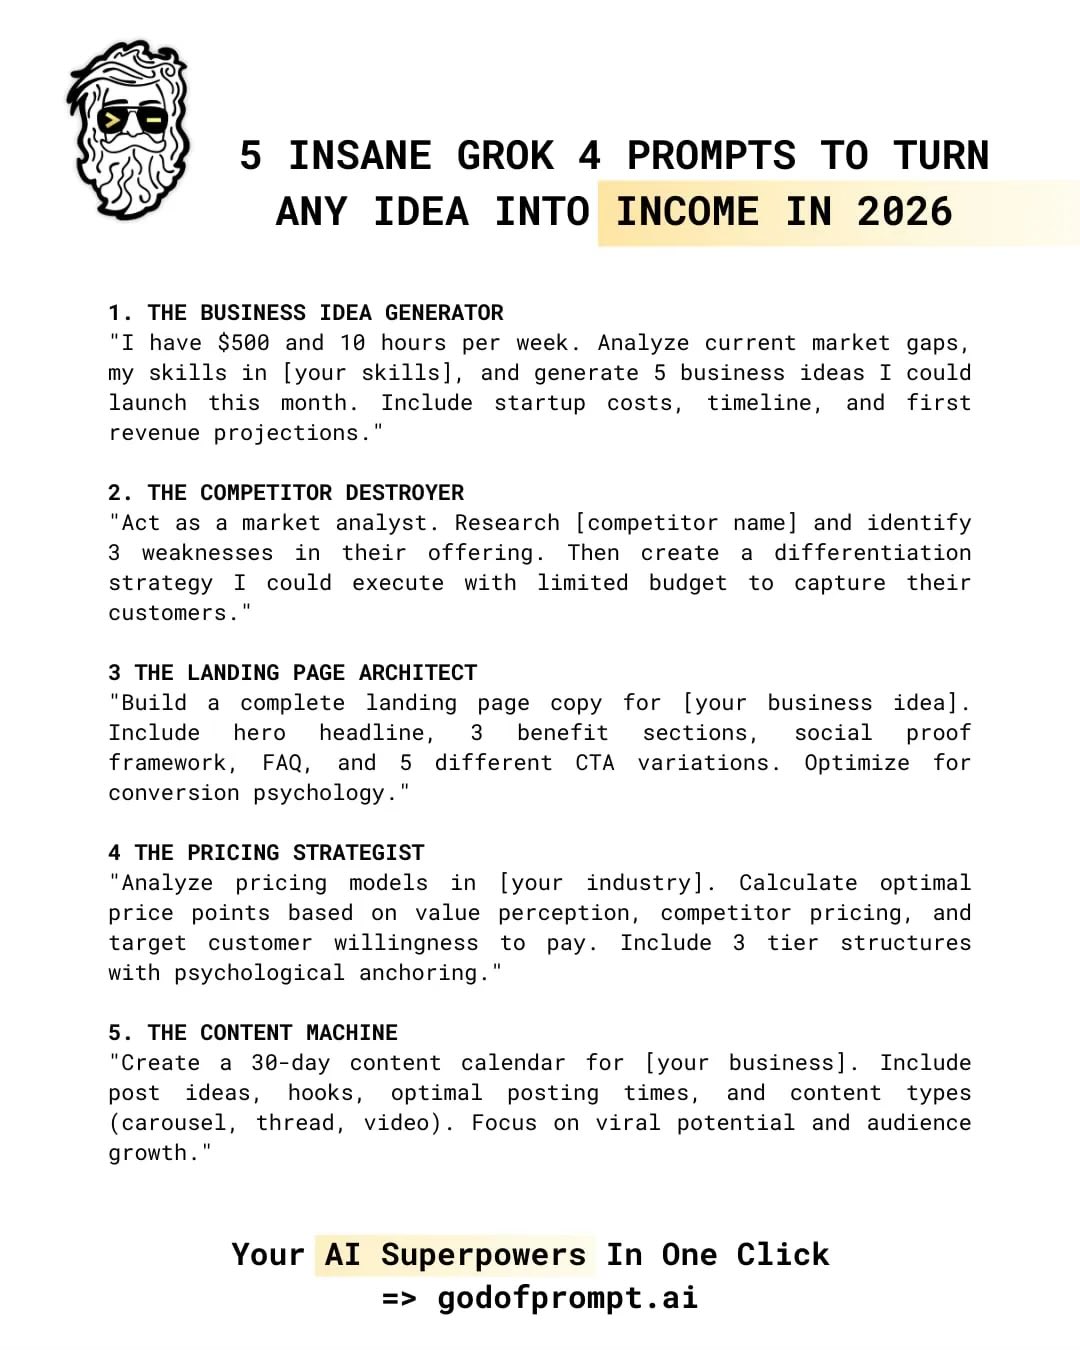
Steal my Grok prompts to create a business in 2026
By
–
Steal my Grok prompts to create a business in 2026 Bookmark for later.
-

Claude’s new writing pattern: not [x], not [y], [z]
By
–
new writing pattern emerged in Claude: not [x].
not [y].
[z]. -

Test-time compute scaling makes large training runs obsolete
By
–
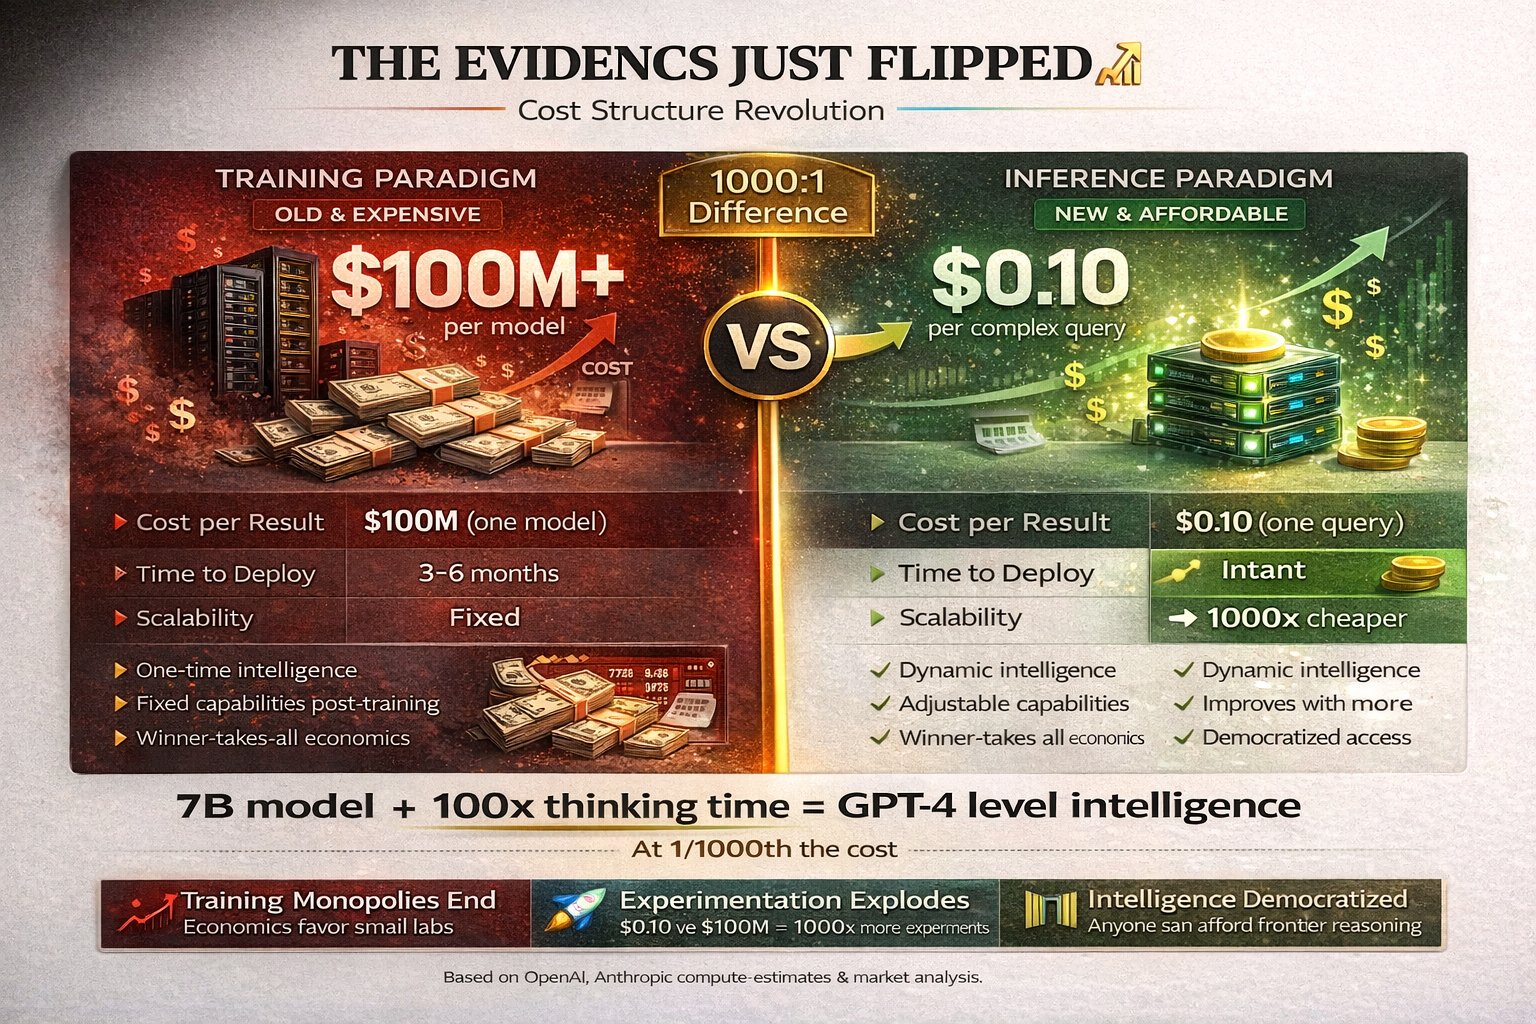
The brutal truth: The future isn't bigger models trained on more data. It's smarter inference strategies that make small models think deeper. Test-time compute scaling just made the $100M training run obsolete. Intelligence is no longer about size—it's about how long you let
-
Implications cascade: inference hardware, reasoning strategies, open-source rise
By
–
The implications cascade: – Inference hardware becomes more valuable than training clusters
– Optimization shifts from pre-training to reasoning strategies
– Model size matters less than inference efficiency
– Open-source models compete with closed frontier models The playing -
DeepSeek-R1 beats 10x larger models by thinking longer
By
–
This explains why DeepSeek-R1 beats models 10x its size. It's not bigger. It's not trained on more data. It just thinks longer and verifies harder. 32B parameters thinking for 30 seconds > 405B parameters answering instantly. The scaling law just changed from "bigger" to
-
Dynamic compute allocation adjusts thinking time based on query difficulty
By
–
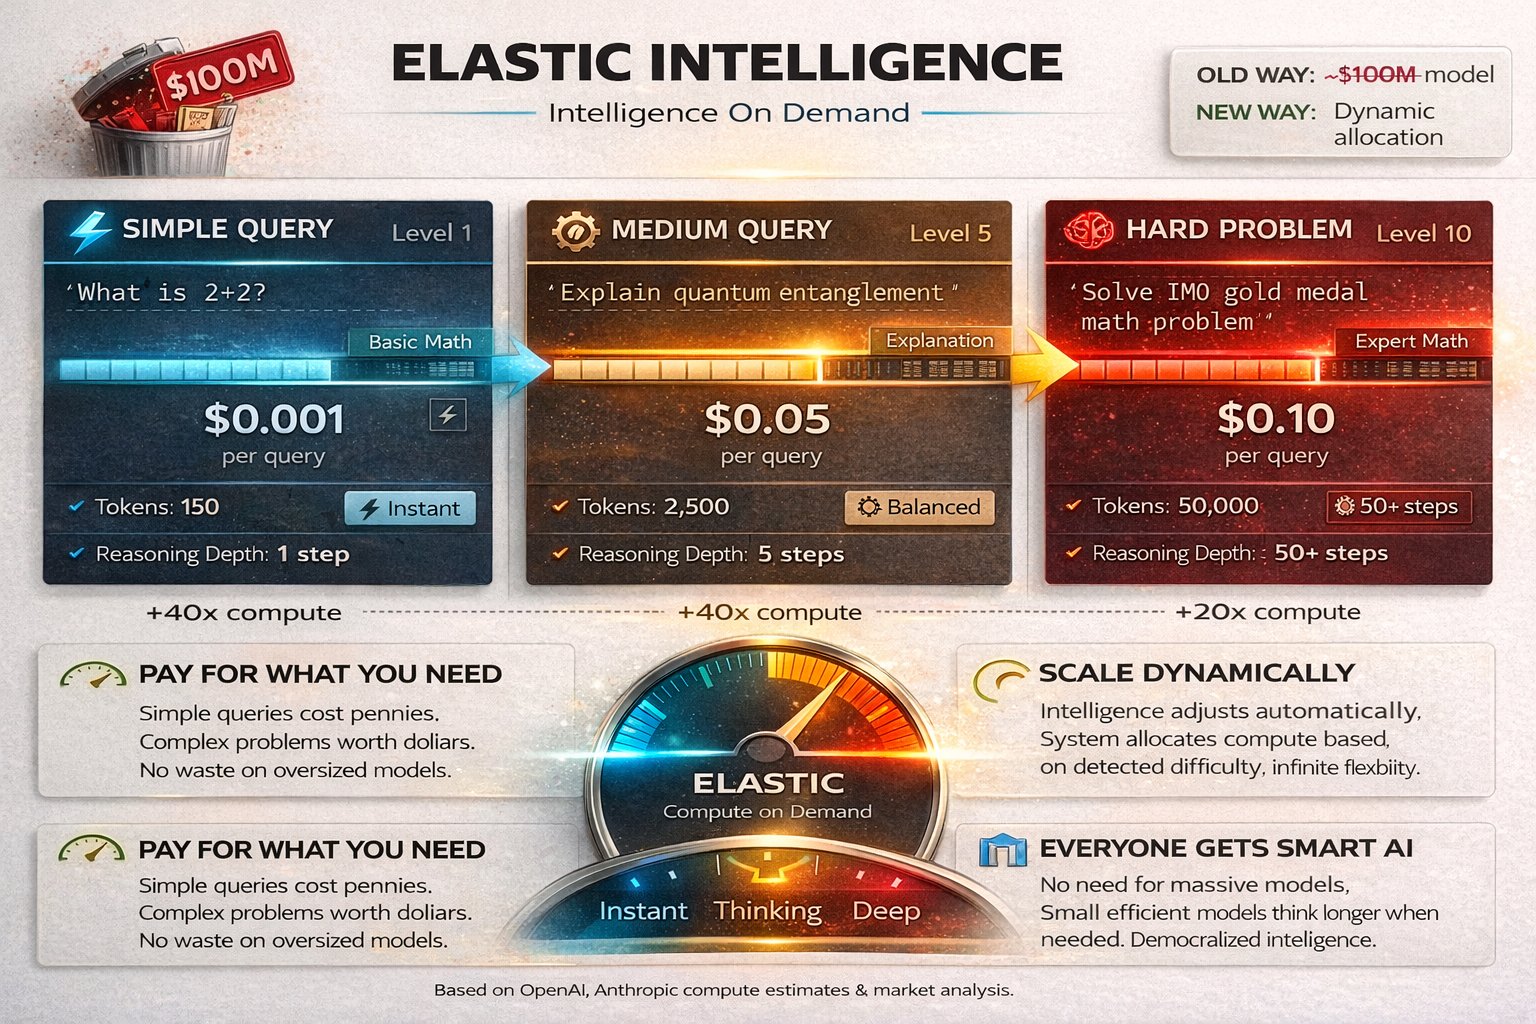
Dynamic compute allocation is the killer feature. Easy query: 0.1 seconds, minimal cost
Medium complexity: 2 seconds, moderate cost
Hard problem: 60 seconds, deep reasoning The model automatically adjusts thinking time based on difficulty. Pay for intelligence only when you -
Wild AI research directions: Best-of-N, tree search, self-verification, process supervision
By
–
The research directions are wild: – Best-of-N sampling: Generate 100 answers, pick the best
– Tree search: Explore reasoning branches like chess moves
– Self-verification: Model checks its own work recursively
– Process supervision: Reward correct reasoning steps, not just