The implications cascade: – Inference hardware becomes more valuable than training clusters
– Optimization shifts from pre-training to reasoning strategies
– Model size matters less than inference efficiency
– Open-source models compete with closed frontier models The playing
@godofprompt
-
Implications cascade: inference hardware, reasoning strategies, open-source rise
By
–
-
DeepSeek-R1 beats 10x larger models by thinking longer
By
–
This explains why DeepSeek-R1 beats models 10x its size. It's not bigger. It's not trained on more data. It just thinks longer and verifies harder. 32B parameters thinking for 30 seconds > 405B parameters answering instantly. The scaling law just changed from "bigger" to
-
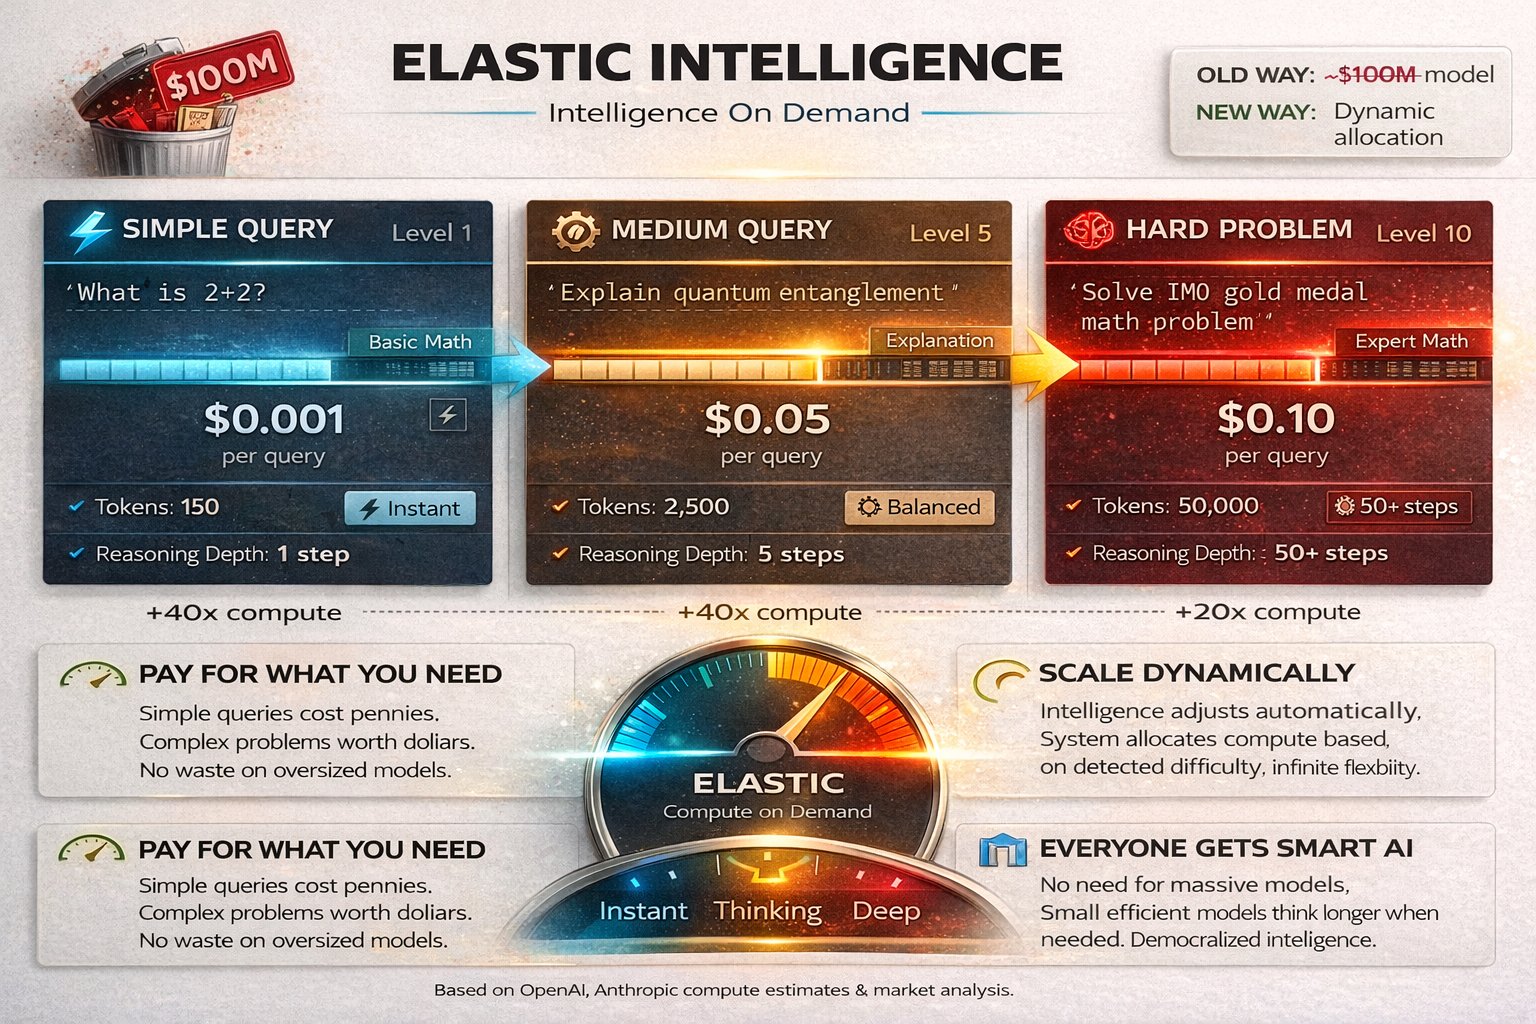
Dynamic compute allocation adjusts thinking time based on query difficulty
By
–
Dynamic compute allocation is the killer feature. Easy query: 0.1 seconds, minimal cost
Medium complexity: 2 seconds, moderate cost
Hard problem: 60 seconds, deep reasoning The model automatically adjusts thinking time based on difficulty. Pay for intelligence only when you -
Wild AI research directions: Best-of-N, tree search, self-verification, process supervision
By
–
The research directions are wild: – Best-of-N sampling: Generate 100 answers, pick the best
– Tree search: Explore reasoning branches like chess moves
– Self-verification: Model checks its own work recursively
– Process supervision: Reward correct reasoning steps, not just -

Elastic Intelligence: small model, dynamic per-query scaling
By
–
This makes $100M training runs obsolete. Why spend months training a massive model when you can deploy a smaller one and scale intelligence dynamically per query? Hard math problem? Give it 60 seconds to think.
Simple question? Answer instantly. Intelligence becomes elastic -

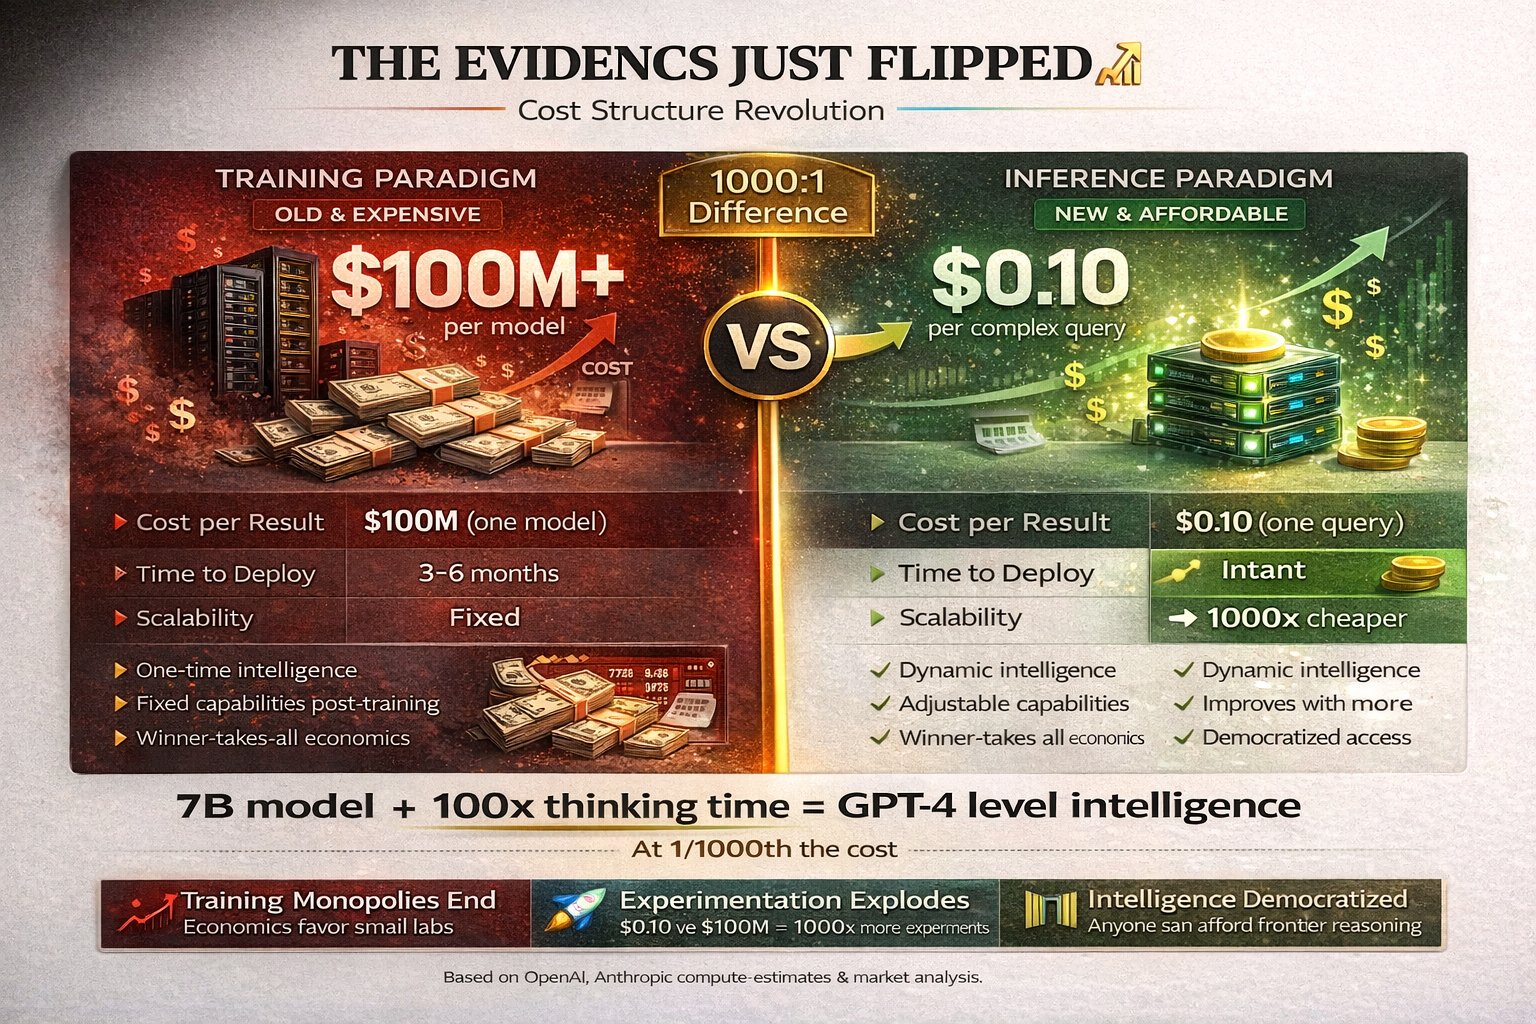
Economics flip: small models with more inference match GPT-4
By
–
The economics just flipped completely. Training GPT-4: $100M+ in compute
Inference scaling: $0.10 per complex query You can make a 7B model as smart as GPT-4 by letting it think 100x longer at inference. Smaller models + more thinking time = beats bigger models at fraction of -
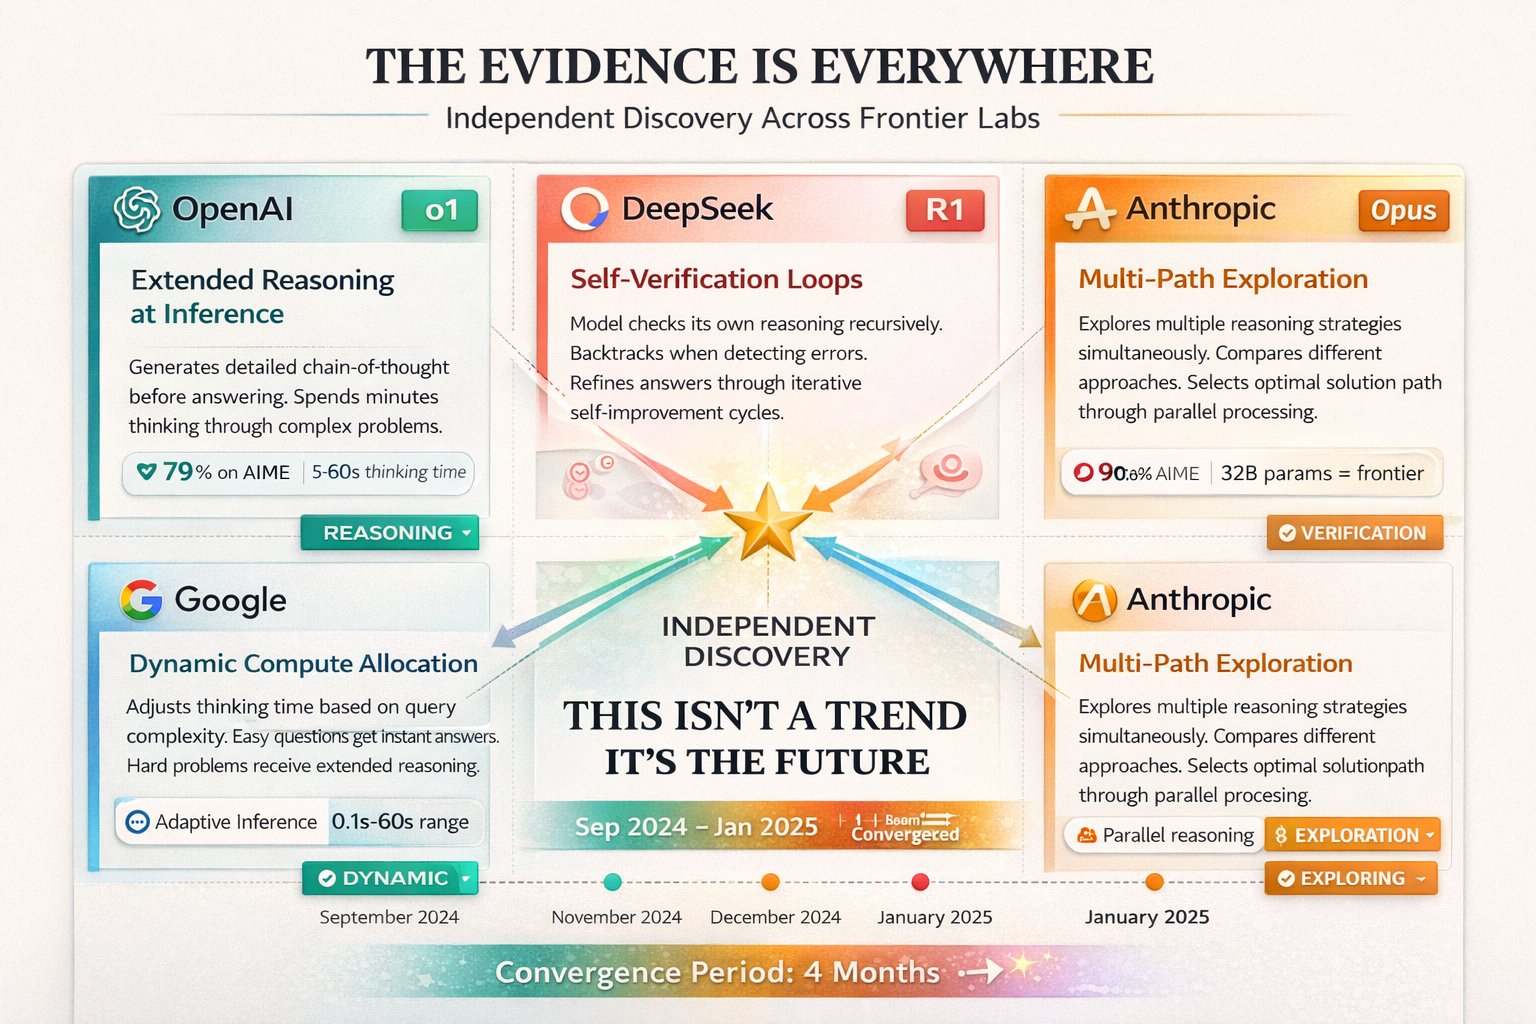
All frontier AI labs discover identical reasoning breakthrough
By
–
The evidence is everywhere: – OpenAI o1: Extended reasoning at inference
– DeepSeek-R1: Self-verification loops
– Gemini 2.0 Thinking: Dynamic compute allocation
– Claude Opus: Multi-path exploration Every frontier lab independently discovered the same breakthrough. This isn't -
Test-time compute scaling: models think harder during inference
By
–
Test-time compute scaling is simple but revolutionary: Instead of making models bigger, you make them think harder during inference. The model generates multiple reasoning paths, verifies answers, backtracks when wrong, and improves solutions in real-time. It's thinking, not
-
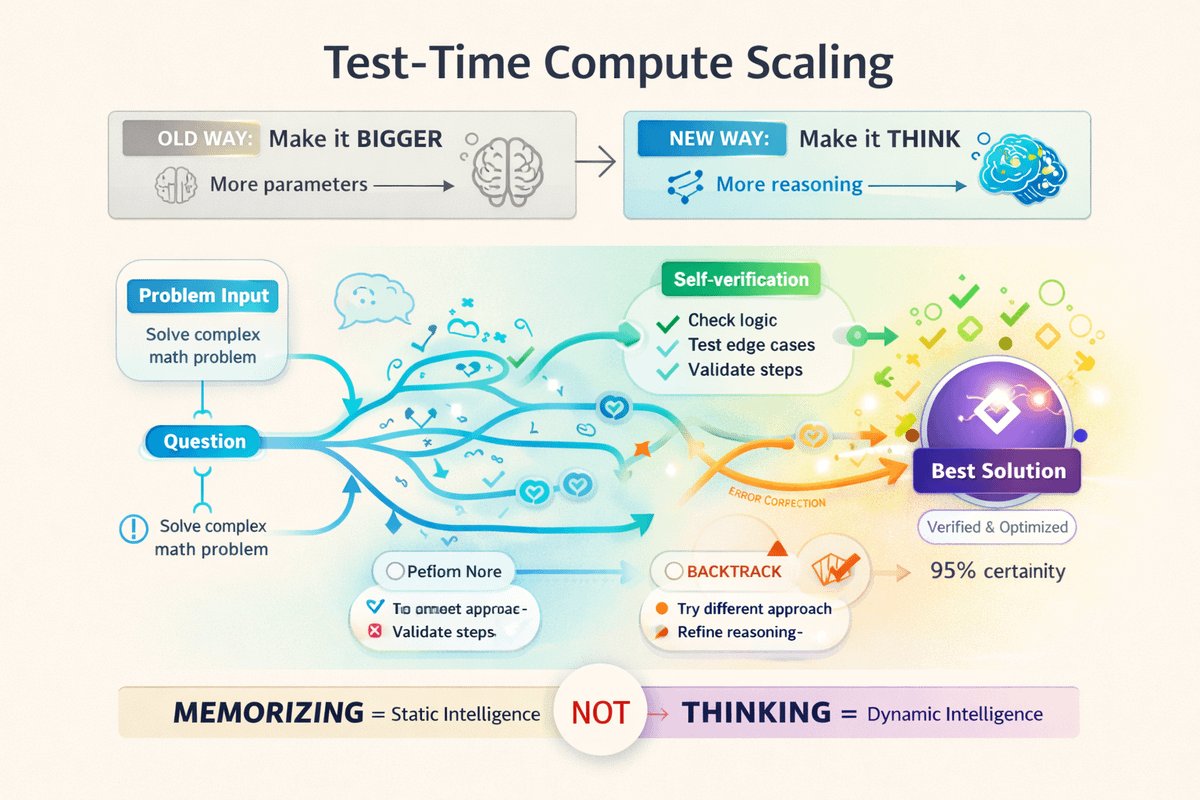
OpenAI’s o1 demonstrates smarter models via inference-time compute
By
–
OpenAI's o1 proves you can make models smarter by making them "think longer" at inference not training bigger models. DeepSeek, Google, Anthropic all pivoting to test-time compute. Training wars are over. The inference wars just started. Here's the paradigm shift happening
-
GPT-5 boosts gene-editing efficiency 79x
By
–
OpenAI’s lab experiment with GPT-5 via Red Queen Bio optimized an actual gene-editing protocol and achieved a 79× efficiency gain . This is AI actually doing wet-lab biology, not just simulations. First real AI-augmented experimentation mixing predictions with robotic