The exploration/exploitation pattern: When previous output was bad? Exploration helped (trying new approaches) When previous output was good? Exploitation helped (refining what worked) The best performers knew when to pivot and when to iterate. Prompting isn't just
@godofprompt
-
Crossover test reveals prompt adaptation is model-specific
By
–
The crossover test proved adaptation was model-specific. When DALL-E 3 prompts were played on DALL-E 2? Performance difference nearly vanished (p=0.56). Users had unknowingly learned to write prompts that exploited DALL-E 3's unique capabilities. The prompts were tuned to
-
AI-assisted prompting reduces DALL-E 3 performance by 58%
By
–
The third group had GPT-4 automatically rewrite their prompts "to help." Performance dropped 58% compared to baseline DALL-E 3. Read that again. AI-assisted prompting made results WORSE than no assistance at all.
-
DALL-E 3 users learned to exploit capabilities without instruction
By
–
The performance gap widened over time. As participants made more attempts, DALL-E 3 users pulled further ahead (β=0.0010, p=0.023). They were learning to exploit its specific capabilities. Without anyone telling them.
-
Users adapted to better model with longer, descriptive prompts
By
–
How did users adapt without knowing they had a better model? → 24% longer prompts (6.9 more words on average) → Same ratio of nouns/adjectives (48% vs 49%) → More semantically consistent across attempts Translation: they added more descriptive information, not filler.
-

Study: Human prompting contributed 49% of AI gains
By
–
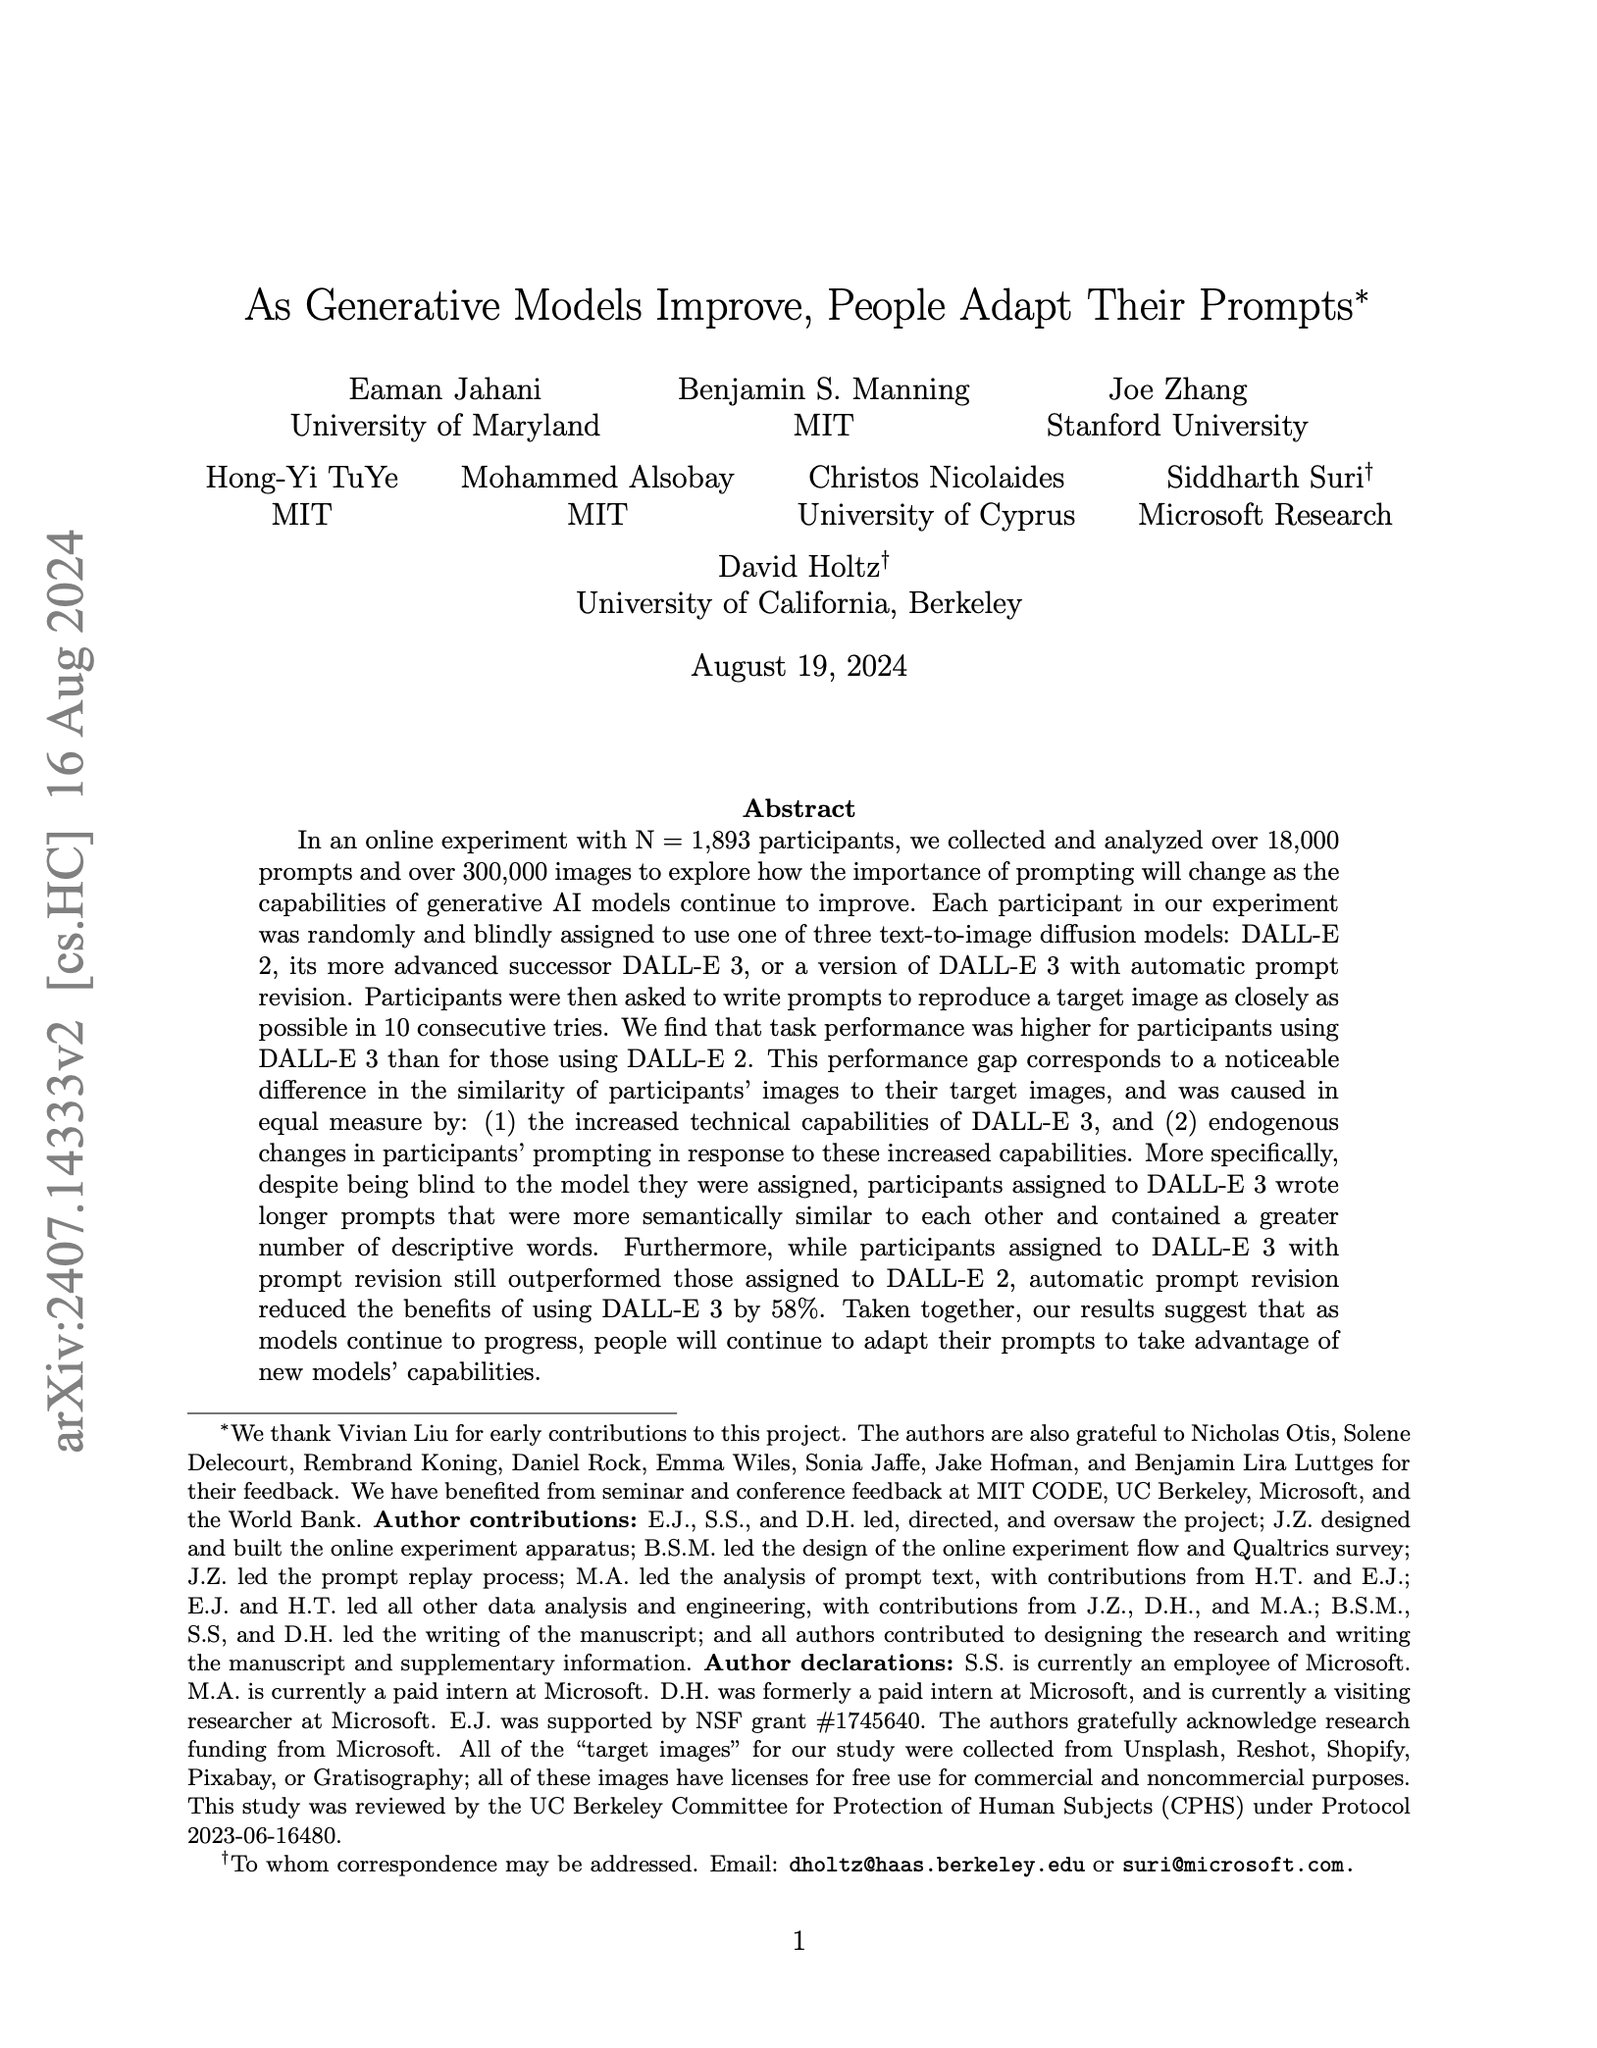
The first finding shocked the researchers. The researchers replayed every prompt on both models to isolate what caused the improvement. – Model effect: 51% of gains – Prompting effect: 49% of gains Nearly half was human behavior.
-

Blind study compares DALL-E versions on image recreation task
By
–
The experiment was elegant. Participants were randomly assigned to DALL-E 2, DALL-E 3, or DALL-E 3 with auto-rewriting. All blind to which model they got. Task: recreate a target image as closely as possible. Top 20% got bonus pay. Everyone was motivated. Nobody knew which AI
-
MIT Study Shows Prompting Equally Important as Model Upgrade
By
–
MIT just proved that upgrading your AI model only gets you HALF the results. The other half is how you prompt it. 1,900 participants. Controlled experiment. The findings completely destroy the "just use a better model" narrative. Here's what they discovered
-
10 psychological triggers to turn AI into a thinking partner
By
–
Most people think AI is a fancier Google. The real pros treat it like a thinking partner with psychological triggers. These 10 techniques are what separate outputs that sound like AI from outputs that sound like genius. Which one are you trying first?