Tom's Guide ran 7 head-to-head tests. Claude won all 7. OpenAI's own benchmark table shows GPT-5.5 leading on 14 categories. But that table includes tests where only OpenAI published a Claude score. Anthropic's own numbers tell a different story on several of those. The
@godofprompt
-
Token efficiency: GPT-5.5 vs Claude Opus 4.7 cost and speed
By
–
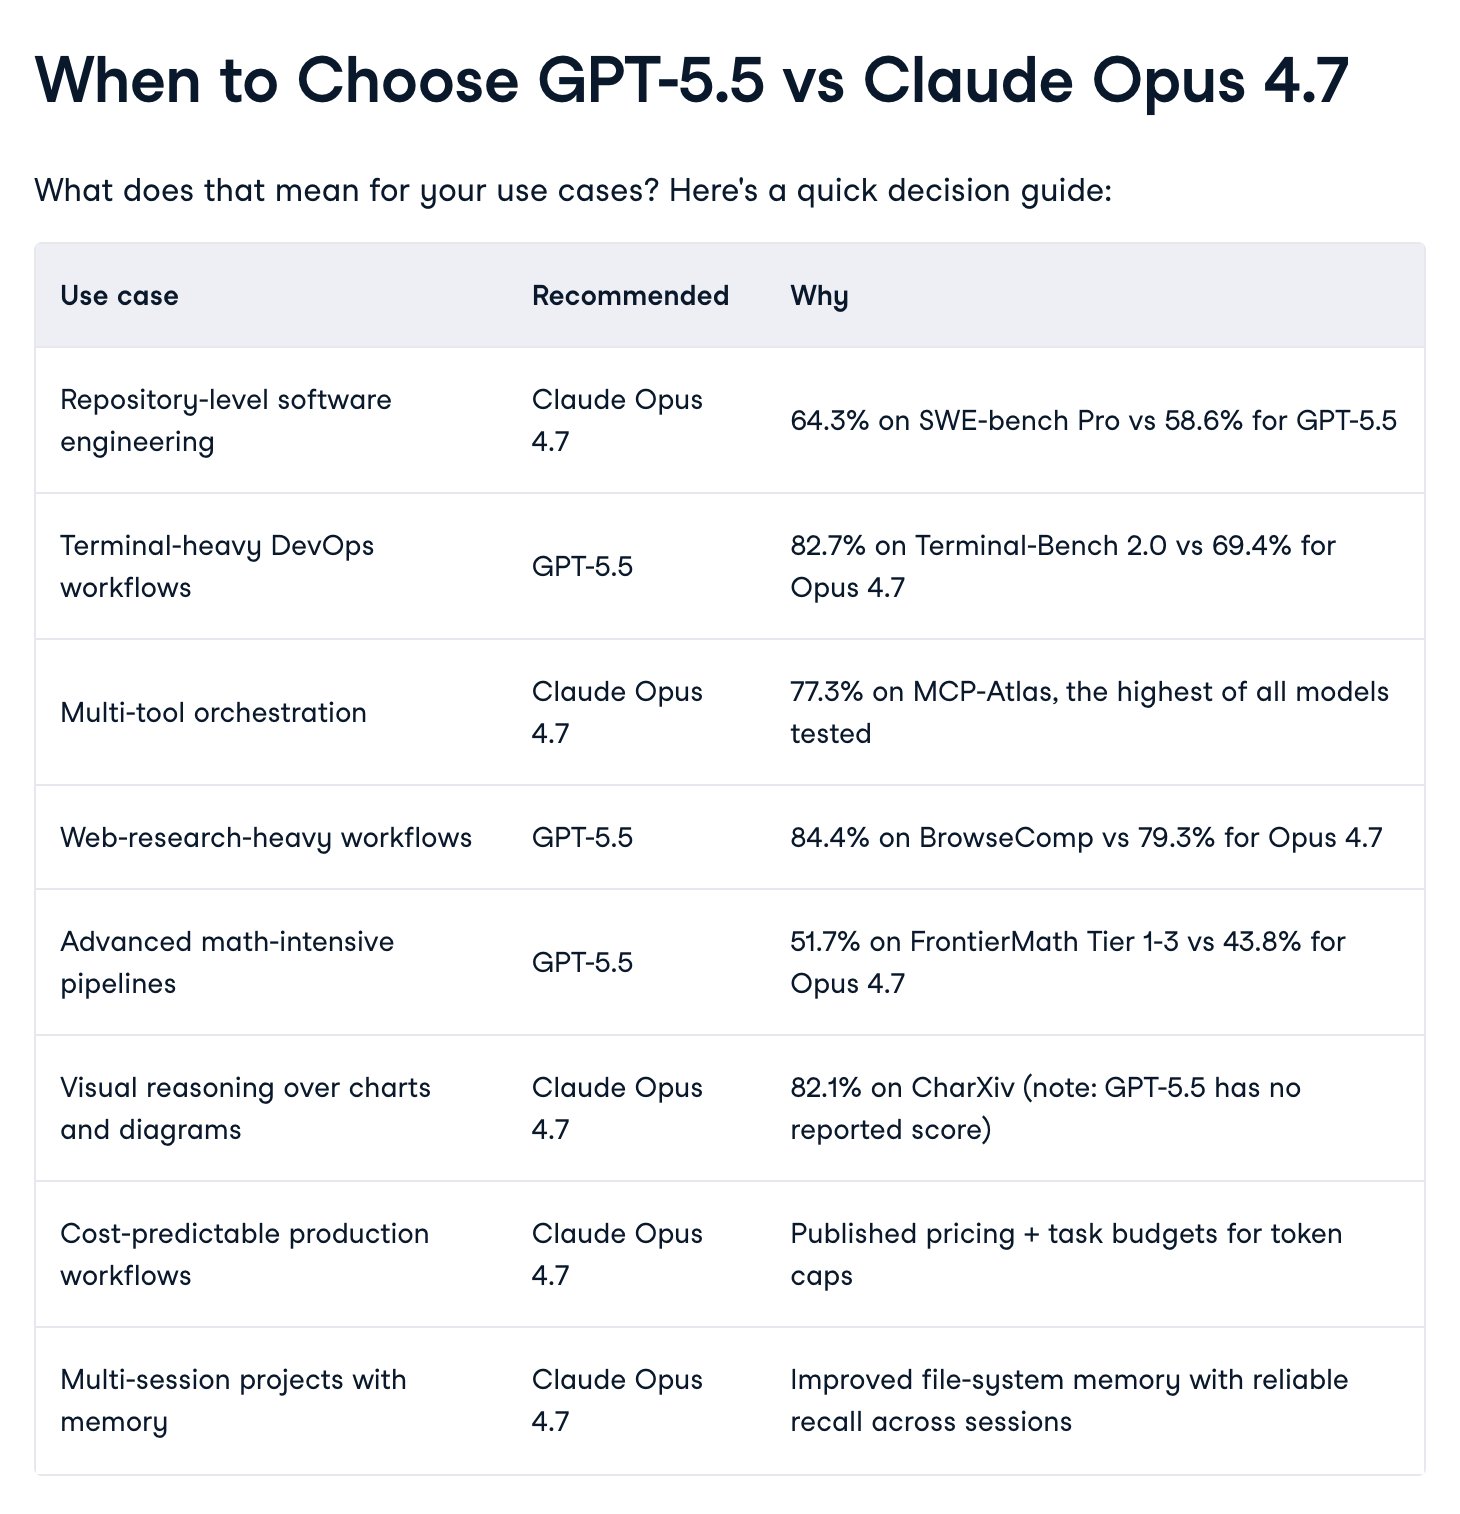
Token efficiency is where things get interesting. GPT-5.5 uses 72% fewer output tokens than Opus 4.7 on the same coding tasks. Fewer tokens means lower cost per task, even though GPT-5.5 costs $30/M output vs Claude's $25/M. But Claude's time-to-first-token is roughly 0.5s vs
-
GPT-5.5 outperforms Claude Opus 4.7 by 13 points on terminal benchmarks
By
–
Long-running agentic execution: GPT-5.5
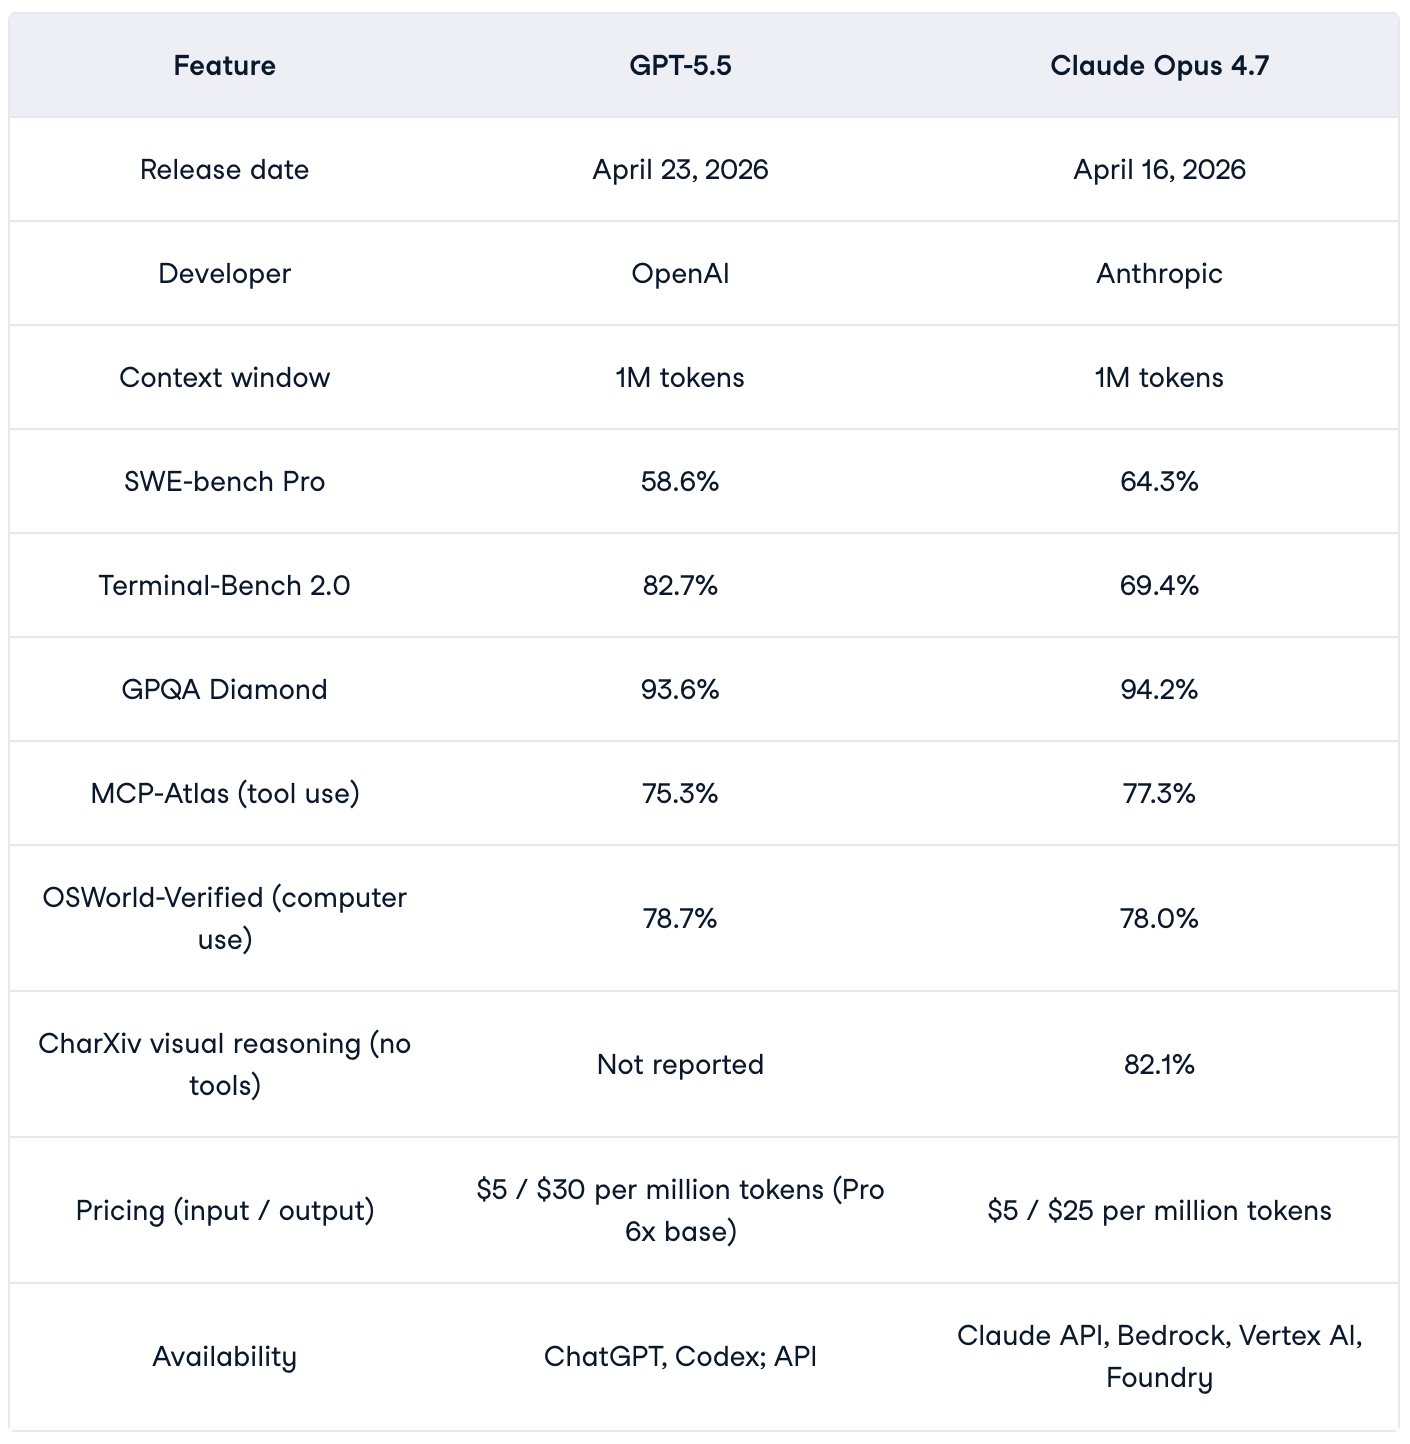
→ Terminal-Bench 2.0: 82.7% → Claude Opus 4.7: 69.4% That's a 13-point gap. Not noise.
→ OSWorld-Verified: 78.7% vs 78.0% → BrowseComp → CyberGym When the task requires driving a terminal, recovering from errors, and -
Claude Opus 4.7 dominates reasoning and code benchmarks
By
–
Deep reasoning and code precision: Claude Opus 4.7 → SWE-Bench Pro: 64.3% → GPT-5.5: 58.6% → MCP Atlas: 79.1% → GPT-5.5: 75.3% → GPQA Diamond, HLE (with and without tools), FinanceAgent v1.1: all Opus 4.7 When the task requires architectural thinking
-
Claude Opus 4.7 leads GPT-5.5 on 6 of 10 benchmarks by category
By
–
On the 10 benchmarks where both OpenAI and Anthropic report scores, here's the split: Claude Opus 4.7 leads on 6. GPT-5.5 leads on 4. But the leads aren't random. They cluster by category. And that changes what "winning" means entirely.
-
GPT-5.5 vs Claude Opus 4.7: The real benchmark story
By
–
GPT-5.5 shipped 7 days after Claude Opus 4.7. Everyone picked a winner based on headlines. I looked at every benchmark both labs published. The real story isn't what most people are reporting:
-
Reflection protocol before any serious AI task
By
–
LLMs don't think. You do. So before I ask AI to do anything serious, I run this prompt first. 3x more upvoted on r/ChatGPT than any other prompt type. Here's my version: ————————-
THINKING PROTOCOL
————————- You are a senior expert in [your -
Transform any AI model into a senior business strategist with this prompt
By
–
The prompt I use to turn any AI model into a senior business strategist: ———— Prompt: You are a senior management consultant with 20 years of experience across Fortune 500 companies and high-growth startups. I will describe a business challenge. Your job:
1.Ask me 5 -
Three Steps to Double AI Session Output Quality
By
–
How to start today: 1. Write a one-page IDENTITY file for your project (who, what, voice, constraints)
2. Keep a running DECISIONS log (what you chose, what you tried, why)
3. Load both at the start of every AI session Output quality doubles. The data is clear. -
Optimize thinking architecture before optimizing prompts
By
–
The shift most people haven't made yet: Stop optimizing the prompt. Optimize the thinking architecture before the prompt. A prompt is a tool. A thinking system is reusable infrastructure. This is what "LLMs don't think, you do" means in practice.