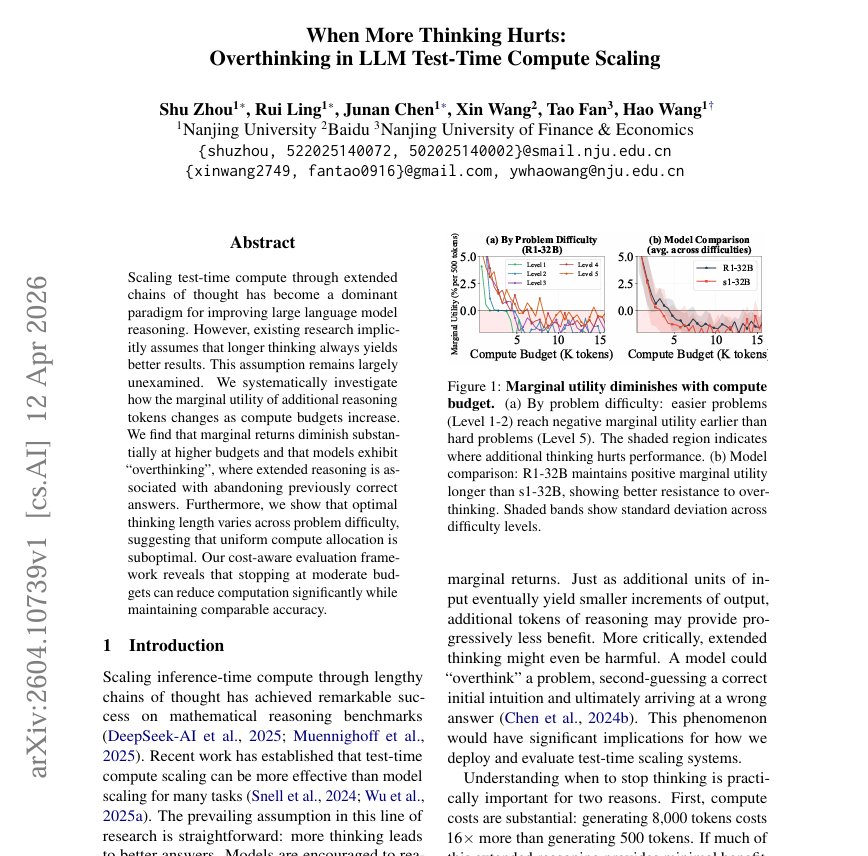
RIP "think step by step." Nanjing University and Baidu just published a paper that proves longer AI reasoning actively flips correct answers to wrong ones, and the implications are brutal for every prompt engineer using chain-of-thought.
@godofprompt
-
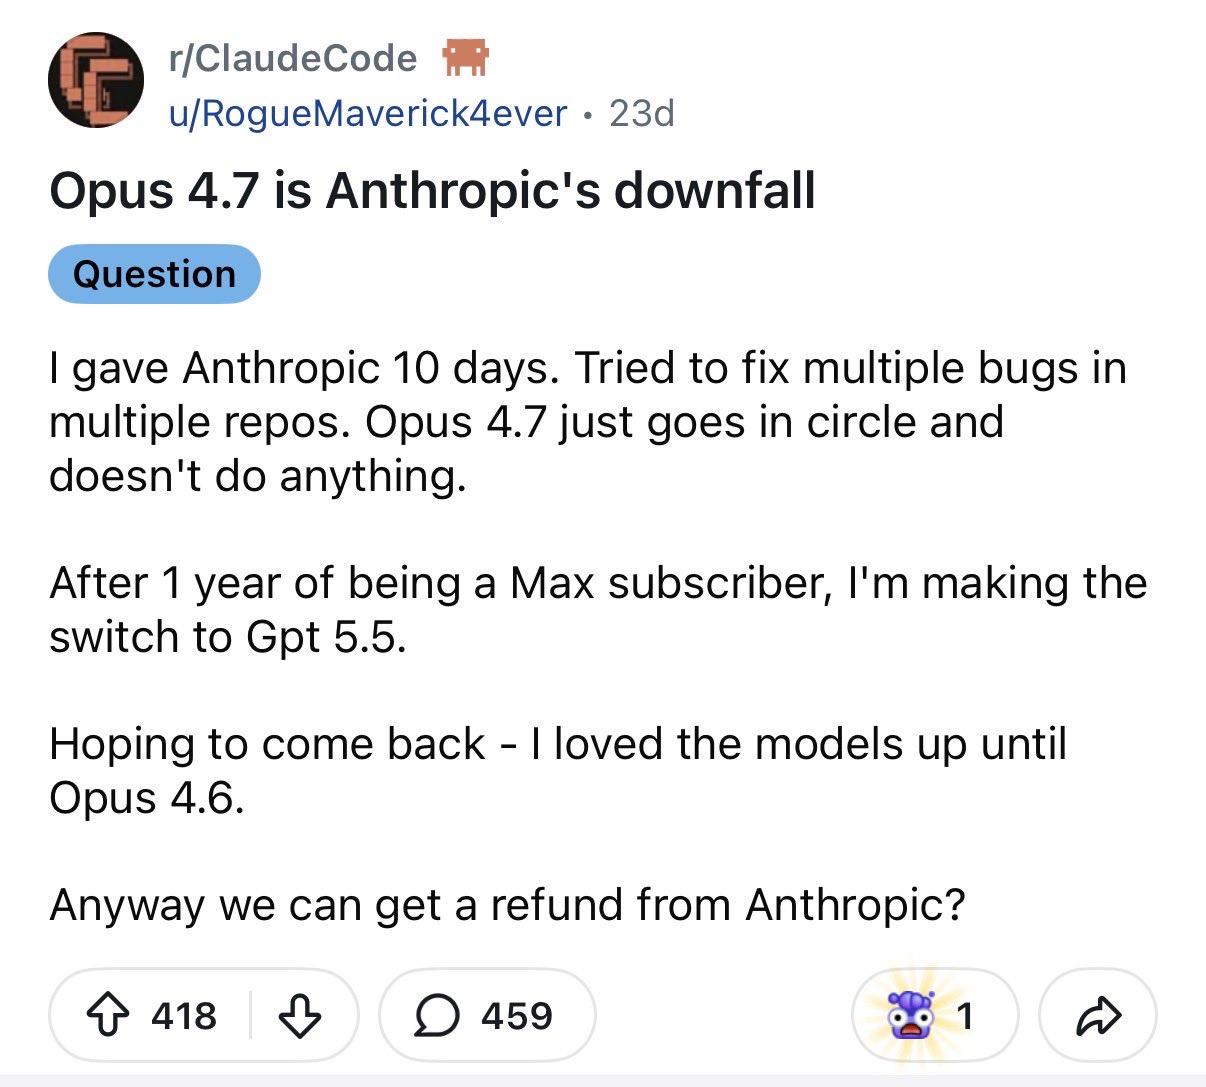
Regression reported in Anthropic’s Opus 4.7 model performance
By
–
Opus 4.7 is ignoring project instructions, skipping MCP servers, and burning through usage limits on tasks Opus 4.6 handles first try. Dozens of confirmed reports. Anthropic acknowledged the regression. The failures are specific:
→ Project instructions ignored entirely
→ MCP -
Optimizing LLM token usage by removing polite filler
By
–
The bigger point: you're paying for "Certainly!" and "I'd be happy to help with that" on every single response. Those tokens cost real money at scale. And they cost you time at every scale. Caveman mode isn't a hack. It's a correction. LLMs were trained on polite human text.
-
Performance Benchmarks of AI Plugin Token Reduction
By
–
The actual benchmarks from the original plugin: → Average 65% output token reduction across 10 real prompts
→ Range: 22-87% depending on task type
→ Coding explanations saw the highest compression
→ Code blocks themselves stayed identical One tester ran it for 6 days on a -
Optimizing LLM Performance Through Brevity and Prompt Engineering
By
–
Why does talking like a caveman actually work? Three things happening at once: → LLMs spend 40-60% of output tokens on filler. Greetings, restatements, encouragement, transitions. You scroll past all of it. Caveman strips it. → A March 2026 paper found that brevity
-
How to optimize Claude’s output using custom skills
By
–
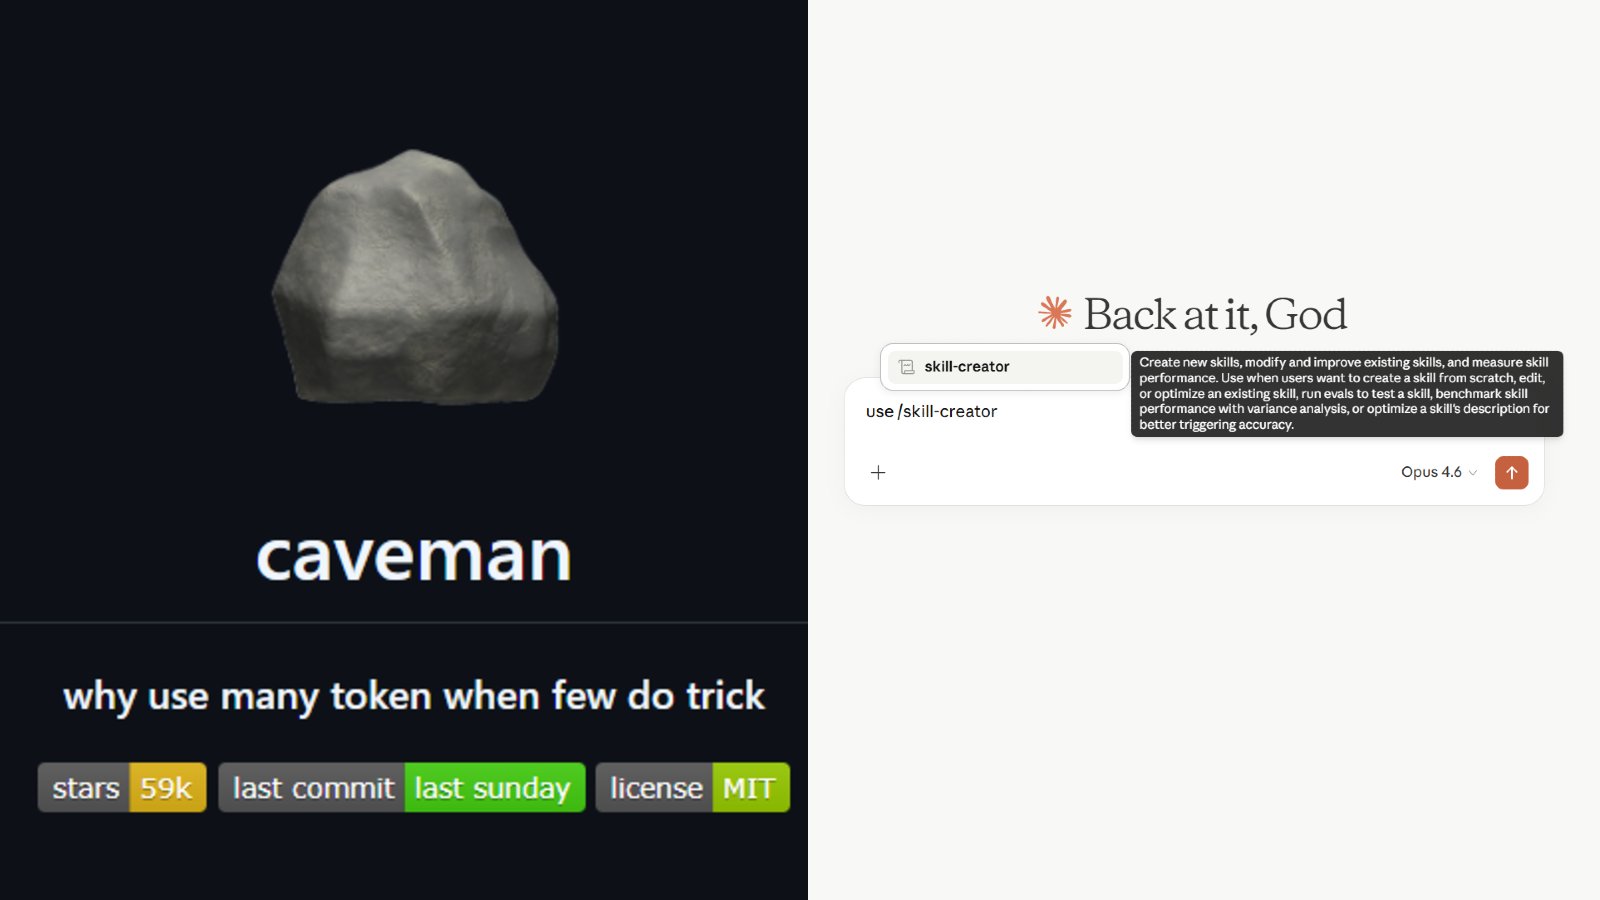
Julius Brussee's caveman plugin hit 51,000+ GitHub stars in two weeks. It cuts Claude's output tokens by 65%. I turned it into a Claude skill you can build in 30 seconds. Copy the prompt below. Ask Claude to build the skill. Save it in your Customize settings.
-
The Shift to Zero-Person AI Agent Businesses
By
–
The “one-person business” era lasted about 5 minutes.
— God of Prompt (@godofprompt) 18 mai 2026
Now we’re entering the zero-person business era:
AI agents running growth, content, sales, and ops while the founder checks in 4 hours a week.
Absolutely brutal for anyone still hiring for every task. https://t.co/2dK8GkqqNXThe “one-person business” era lasted about 5 minutes. Now we’re entering the zero-person business era: AI agents running growth, content, sales, and ops while the founder checks in 4 hours a week. Absolutely brutal for anyone still hiring for every task.
-
PolyAI launches enterprise voice agent platform for real-time customer dialog
By
–
Call centers are about to get absolutely cooked.
— God of Prompt (@godofprompt) 18 mai 2026
PolyAI just opened the same voice agent platform used by FedEx, Marriott, PG&E, Foot Locker, and more.
Not chatbot cosplay.
Real dialog agents for messy enterprise calls.
Built in 10 minutes or from your terminal.
Voice AI is… https://t.co/GWChJy35e8Call centers are about to get absolutely cooked. PolyAI just opened the same voice agent platform used by FedEx, Marriott, PG&E, Foot Locker, and more. Not chatbot cosplay.
Real dialog agents for messy enterprise calls. Built in 10 minutes or from your terminal. Voice AI is -
Standardizing Skills for Portable AI Coding Agent Workflows
By
–
If you're building AI workflows for yourself or clients, the practical takeaway is simple: Write your Skills in the SKILL .md format. You're not locked to one vendor. Your thinking systems become portable across every major coding agent. One Skill, 30+ compatible tools. That's
-
Comparative analysis of AI agent capabilities in Claude and Perplexity
By
–
Here's what "Skills" actually means on each platform: Claude: Full code execution in a sandbox. Works across Claude. ai, Claude Code, the API, and the Agent SDK. Ships scripts. Persists across sessions. The deepest implementation. Perplexity: Same SKILL. md format running