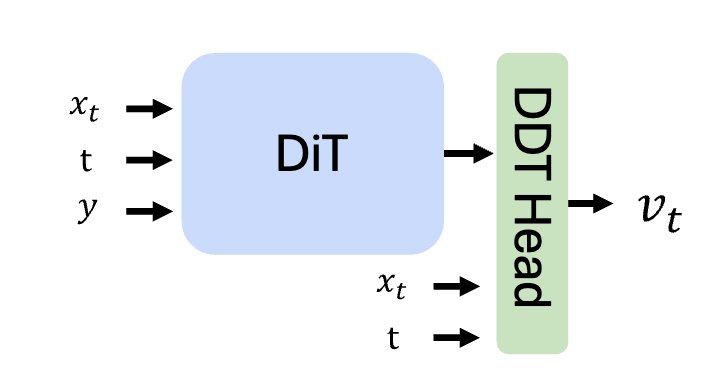
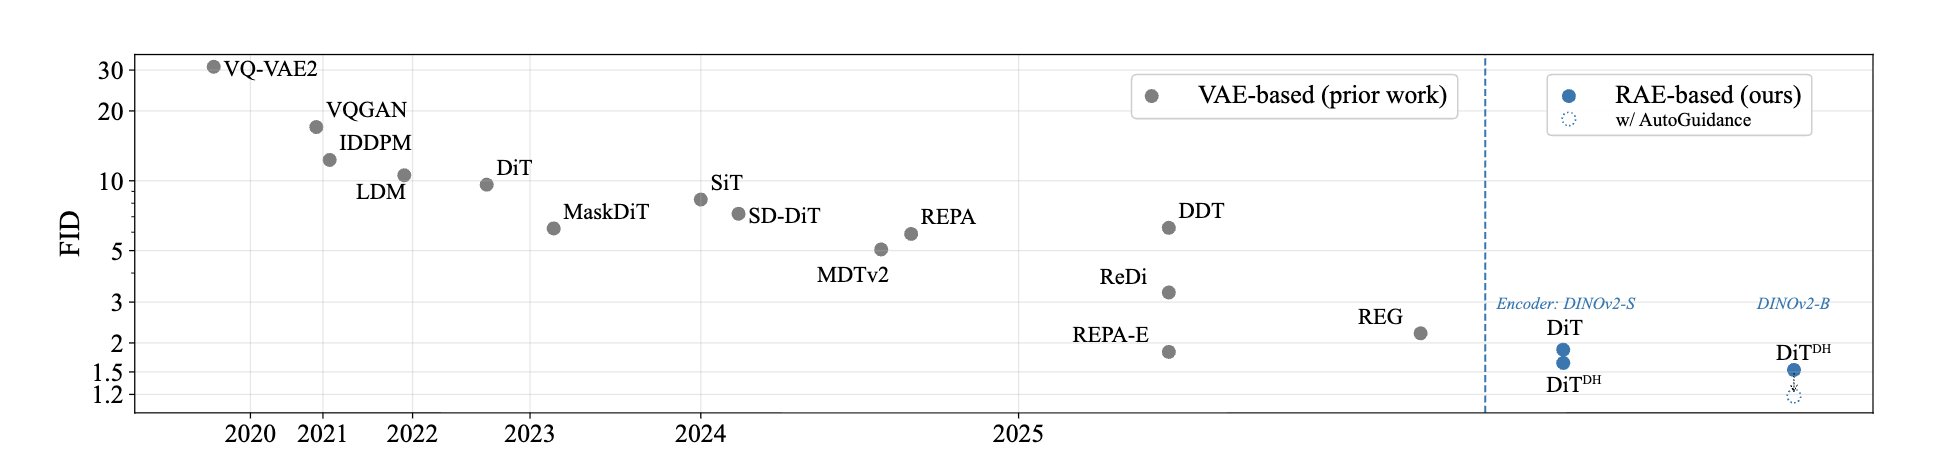
Finally, they added a wide diffusion head the DiTDH variant. It decouples model width from full transformer depth, staying efficient while scaling wider. Result: 2.16 FID on ImageNet-256. RAE-DiTDH outperforms every VAE-based diffusion model at every scale.
@godofprompt
-

Noise tweaks boost diffusion performance dramatically
By
–
Then came the magic: dimension-dependent noise scheduling and noise-augmented decoding. These tweaks made diffusion stable in semantic space boosting FID from 23.08 → 4.28. RAE models now converge 47× faster than SiT or REPA.
-
DiT Convergence: Width Over Depth Matters
By
–
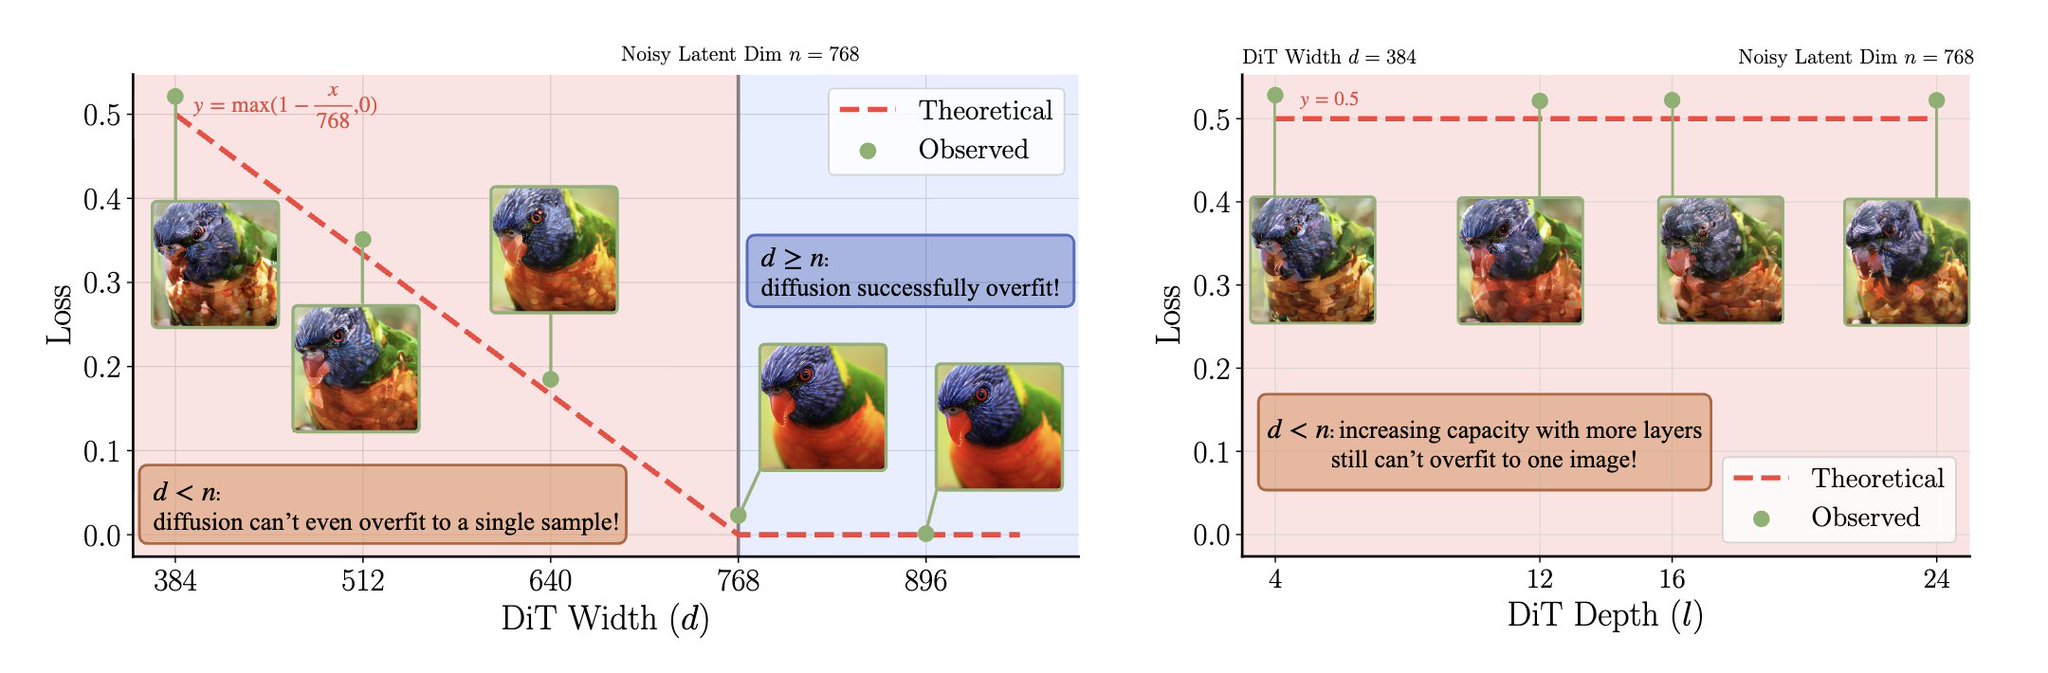
Diffusion Transformers struggled at first. Why? Their width was too small for RAE’s high-dimensional latents. The fix: scale width ≥ latent dimension. Once model width ≥ 768, DiT started converging instantly. Depth didn’t matter width unlocked training stability.
-

RAE + DINOv2-B beats VAEs with sharper images
By
–
Everyone assumed semantic encoders couldn’t reconstruct images.
Turns out, they can and better than VAEs. RAE + DINOv2-B achieves 0.49 rFID vs 0.62 for SD-VAE, with 6× less compute. That’s fewer FLOPs and sharper reconstructions. -
RAEs improve diffusion models over VAEs
By
–
Today, most diffusion models still use VAEs built on 2021 tech. They compress images into low-dimensional latents (like 4 channels). That’s why diffusion models lose global structure and texture fidelity. RAEs fix this by encoding rich semantic features directly from pretrained
-

New Paper Revolutionizes Diffusion Models
By
–
Holy shit…Diffusion just leveled up A new paper “Diffusion Transformers with Representation Autoencoders” basically kills the VAE era. Instead of the old VAE bottleneck, they use representation autoencoders (RAEs) built from pretrained encoders like DINO or SigLIP. The
-
Long Prompts and Folders Boost Workflow
By
–
exactly. long prompts + folders can really boost the workflow especially for coders but also for content creation. long prompts can specify the hooks criteria + mention the context within which it must give output (the folders, which represent examples of viral content)
-

Claude’s Skills Transform AI into Specialists
By
–
Skills turn Claude from a generalist into a specialist instantly. You’re not prompting an assistant anymore. You’re deploying experts. Full details on the Anthropic blog: https://
anthropic.com/news/skills -
Claude’s Dynamic and Composable Expertise
By
–
1. Dynamic Expertise
— God of Prompt (@godofprompt) 17 octobre 2025
Claude now scans your available skills and automatically loads only what’s relevant to the task.
No bloat. No latency. Just the right expertise, when needed.
2. Composable + Portable
Skills stack together like Lego pieces.
Build once → use across Claude… pic.twitter.com/EkFYL92IeN1. Dynamic Expertise Claude now scans your available skills and automatically loads only what’s relevant to the task. No bloat. No latency. Just the right expertise, when needed. 2. Composable + Portable Skills stack together like Lego pieces.
Build once → use across Claude -
Anthropic’s Claude gains custom skills
By
–
🚨 BREAKING: Anthropic just launched Agent Skills and it’s quietly the biggest Claude update yet.
— God of Prompt (@godofprompt) 17 octobre 2025
Claude can now load custom skills little folders packed with instructions, scripts, and resources that make it a specialist on demand.
Think:
→ a “Spreadsheet Expert” skill for… pic.twitter.com/SZHU5hNfzyBREAKING: Anthropic just launched Agent Skills and it’s quietly the biggest Claude update yet. Claude can now load custom skills little folders packed with instructions, scripts, and resources that make it a specialist on demand. Think: → a “Spreadsheet Expert” skill for