the solution? it’s not better video models. it’s world simulation models like google’s genie 3. genie doesn’t just predict pixels – it simulates physics rules. gravity, collision, momentum. it understands that when you climb a ladder, your hand grips, your foot lifts, your
@godofprompt
-

Using ChatGPT Prompts for Crypto Market Analysis
By
–
This ChatGPT Prompt separates the wheat from the chaff in crypto.
-

Leveraging Custom GPTs for Business Performance
By
–
Custom GPT Outputs power my business AI
Essential for tailored and efficient performance
• Fine-tune models
• Engineer prompts
• Embed data Click below to read more: https://
godofprompt.ai/blog/custom-gp
t-outputs-best-practices-for-businesses
… -
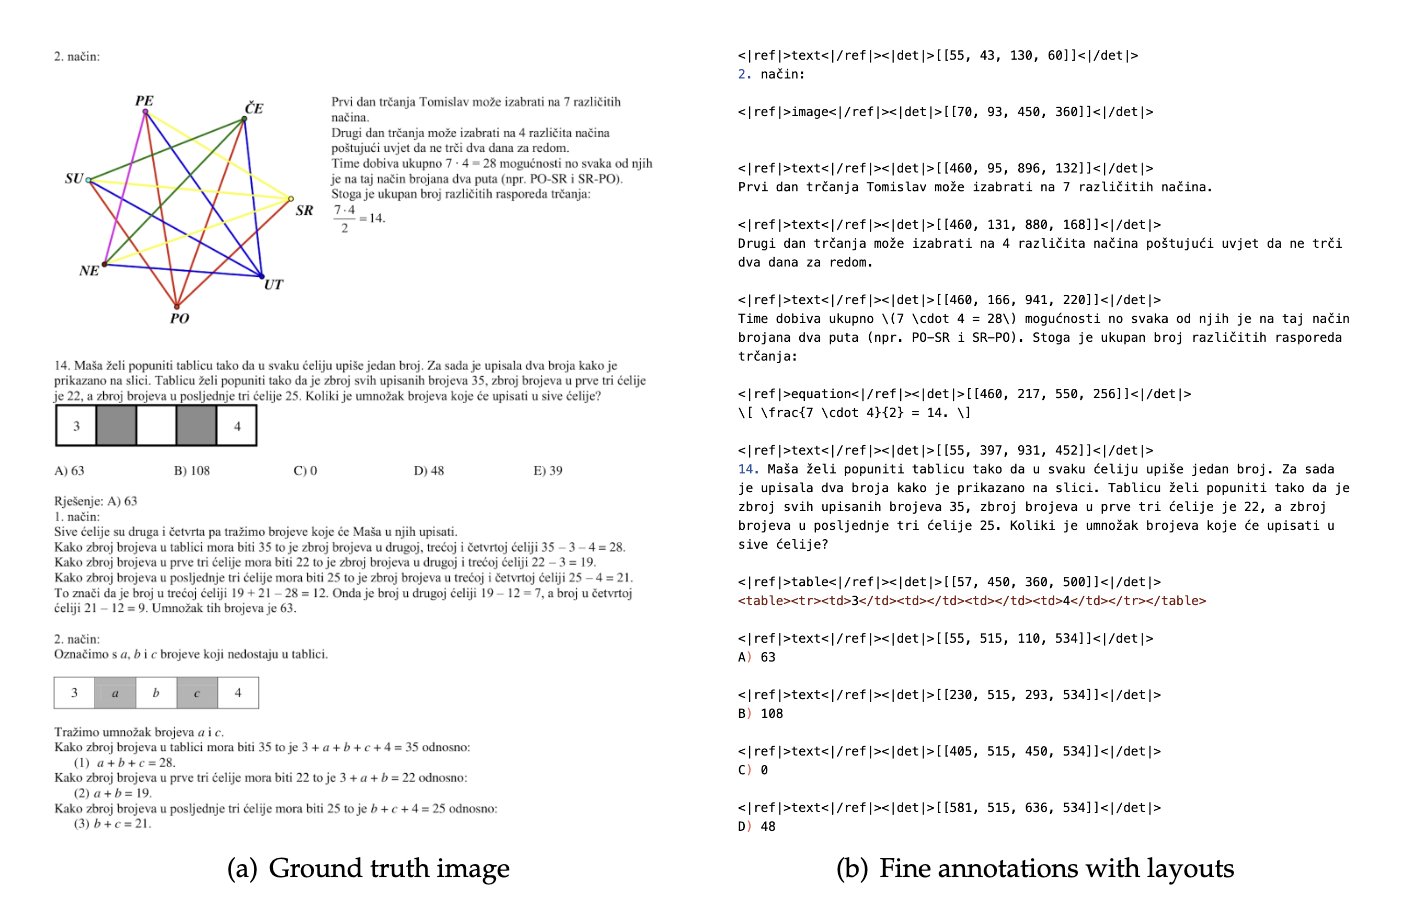
Using Visual Context Compression to Improve LLM Memory and Reasoning
By
–
5. This isn’t “just another OCR.” It’s a proof of concept for context compression. If text can be represented visually with 10× fewer tokens LLMs could use the same idea for long-term memory and efficient reasoning. Imagine GPT-5 processing a 1M-token document as a 100K-token
-

DeepSeek-OCR technical data training approach
By
–
4. Data Engine OCR 1.0 to 2.0 They didn’t just train on text scans. DeepSeek-OCR’s data includes: • 30M+ PDF pages across 100 languages
• 10M natural scene OCR samples
• 10M charts + 5M chemical formulas + 1M geometry problems It’s not just reading it’s parsing scientific -

Technical Overview of DeepSeek-OCR Multi-Resolution Gundam Mode
By
–
3. Multi-Resolution “Gundam” Mode Documents vary invoices ≠ blueprints ≠ newspapers. To handle this, DeepSeek-OCR supports multiple resolution modes: Tiny, Small, Base, Large, and Gundam. Gundam mode combines local tiles + a global view scaling from 512×512 to 1280×1280
-
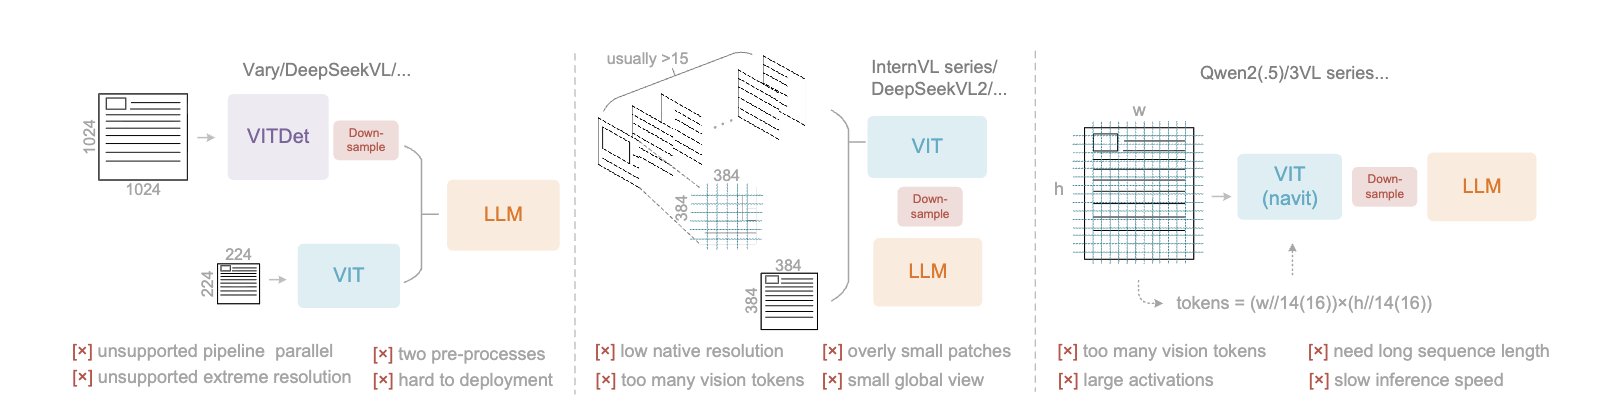
DeepEncoder: A Technical Overview of the Optical Compressor Architecture
By
–
2. DeepEncoder – The Optical Compressor Meet the star: DeepEncoder. It uses two backbones SAM (for perception) and CLIP (for global vision) bridged by a 16× convolutional compressor. This allows it to maintain high-res understanding without exploding activation memory. The
-
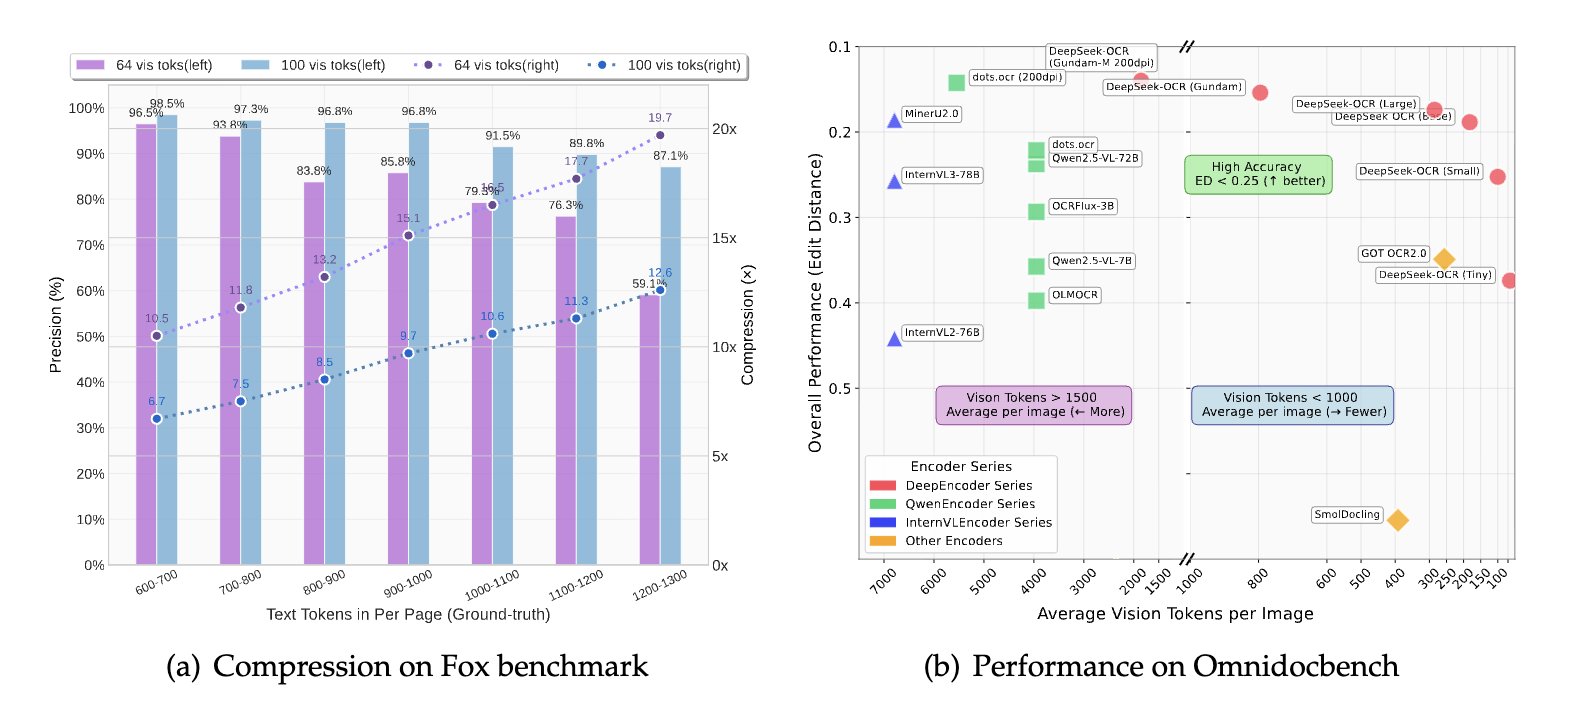
Technical Analysis of DeepSeek-OCR Vision-Text Compression
By
–
1. Vision-Text Compression: The Core Idea LLMs struggle with long documents because token usage scales quadratically with length. DeepSeek-OCR flips that: instead of reading text, it encodes full documents as vision tokens each token representing a compressed piece of visual
-
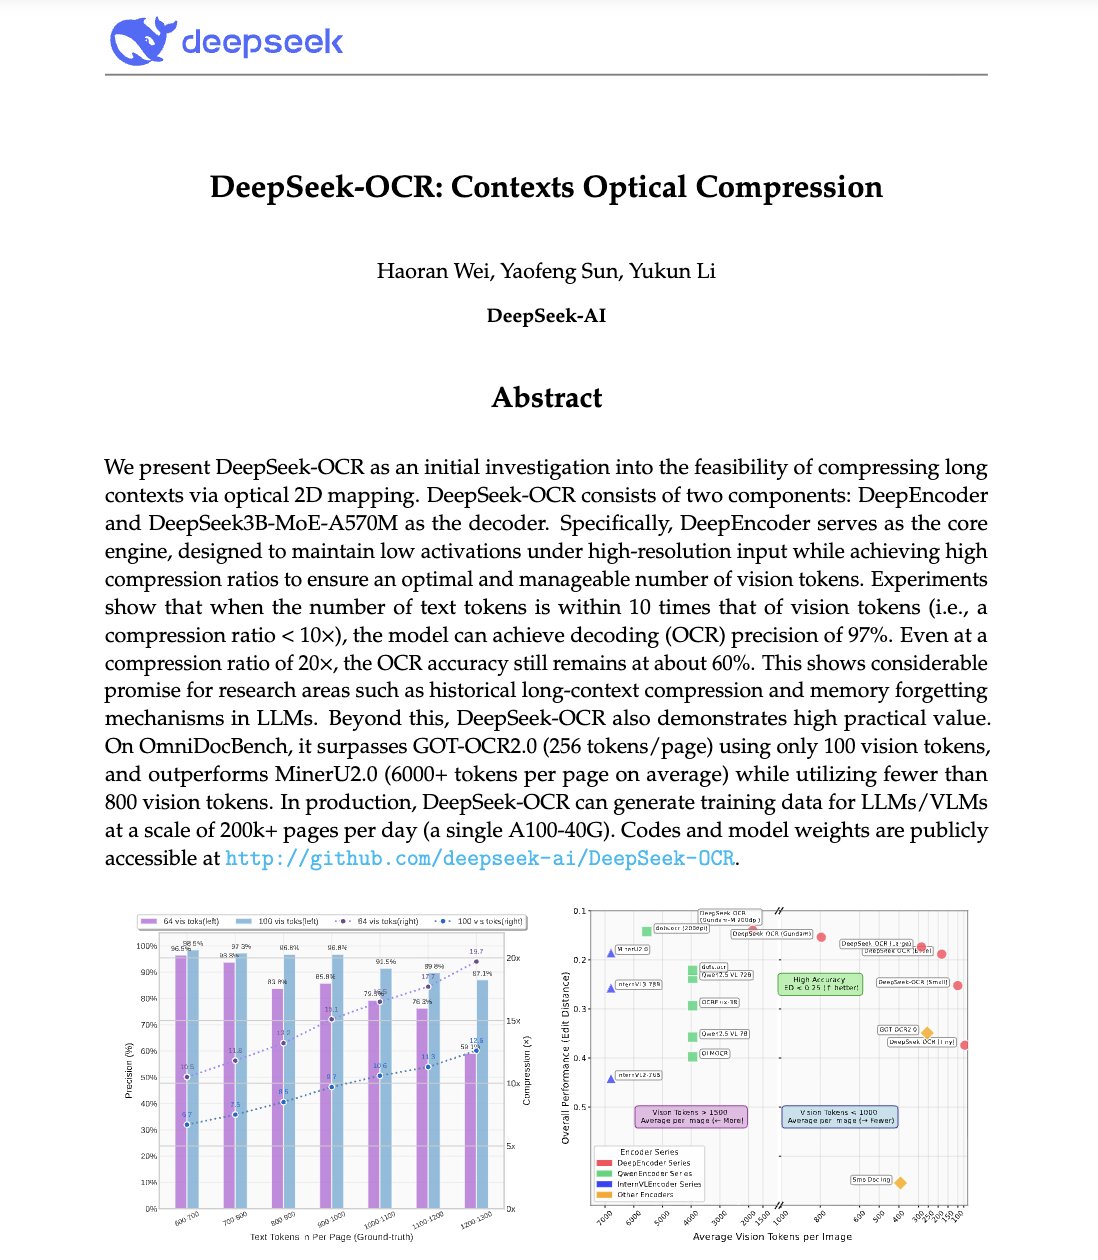
DeepSeek Introduces High-Efficiency OCR System Using Vision Tokens
By
–
DeepSeek just did something wild. They built an OCR system that compresses long text into vision tokens literally turning paragraphs into pixels. Their model, DeepSeek-OCR, achieves 97% decoding precision at 10× compression and still manages 60% accuracy even at 20×. That
-

Converting AI prototypes into functional apps via prompting
By
–
Turn your vibe coded slop into an actual app with this prompt. Bookmark for later.