What I found to be useful?? RL performance follows a sigmoid scaling law, not a power law. At small compute, progress is slow. Then it explodes mid-way before flattening at a predictable ceiling. That “S-curve” lets you forecast results before spending 10x more GPU hours.
@godofprompt
-
Meta Reveals RL Scaling Challenges
By
–
Today, everyone talks about scaling models. But Meta just proved we’ve been ignoring the harder problem scaling reinforcement learning compute. Turns out, most RL methods don’t scale like pretraining. They plateau early burning millions in compute for almost no gain. ScaleRL
-
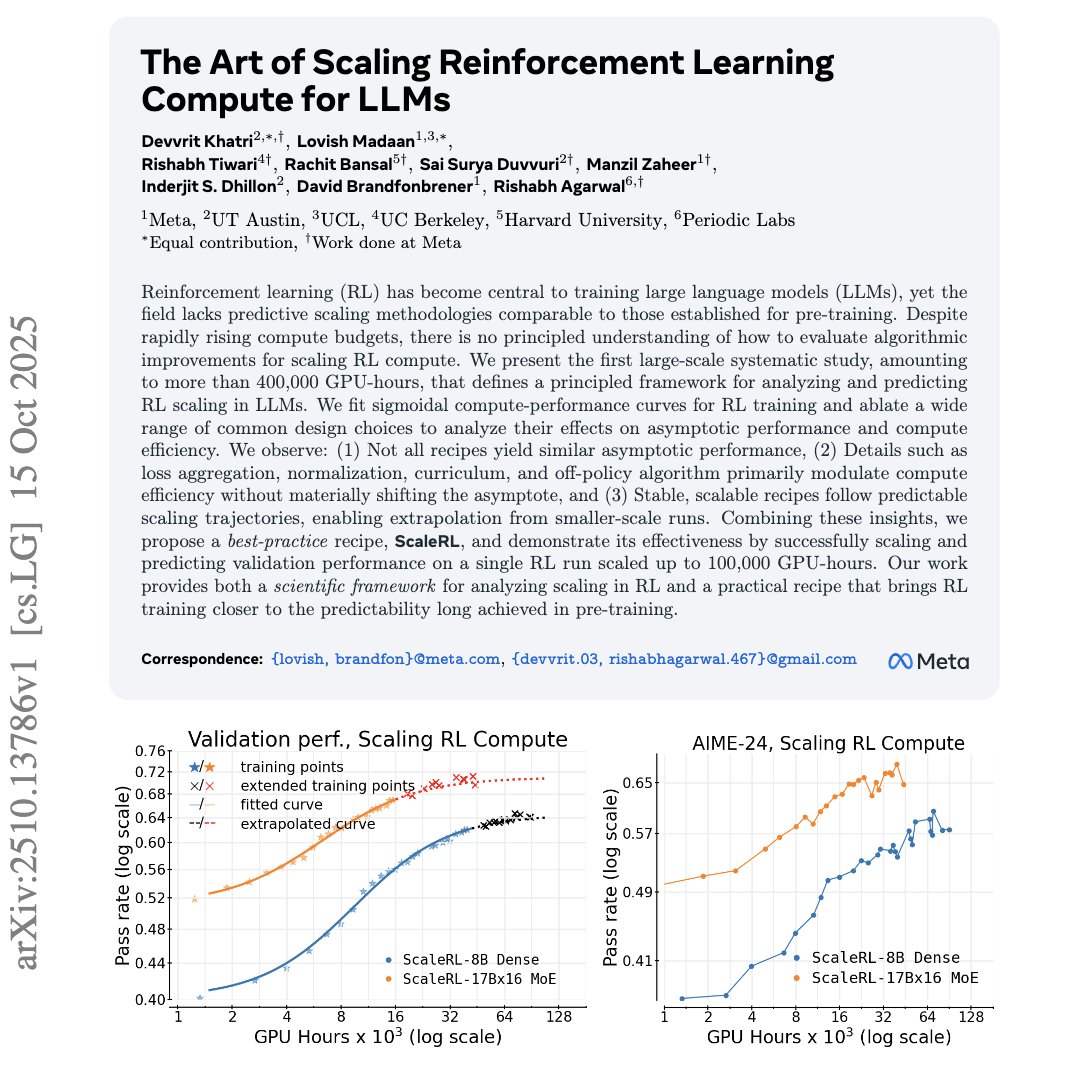
Meta’s ScaleRL reveals predictable RL scaling laws
By
–
Holy shit… Meta just cracked the art of scaling RL for LLMs. For the first time ever, they showed that "reinforcement learning follows predictable scaling laws" just like pretraining. Their new framework, 'ScaleRL', fits a sigmoid compute-performance curve that can forecast
-
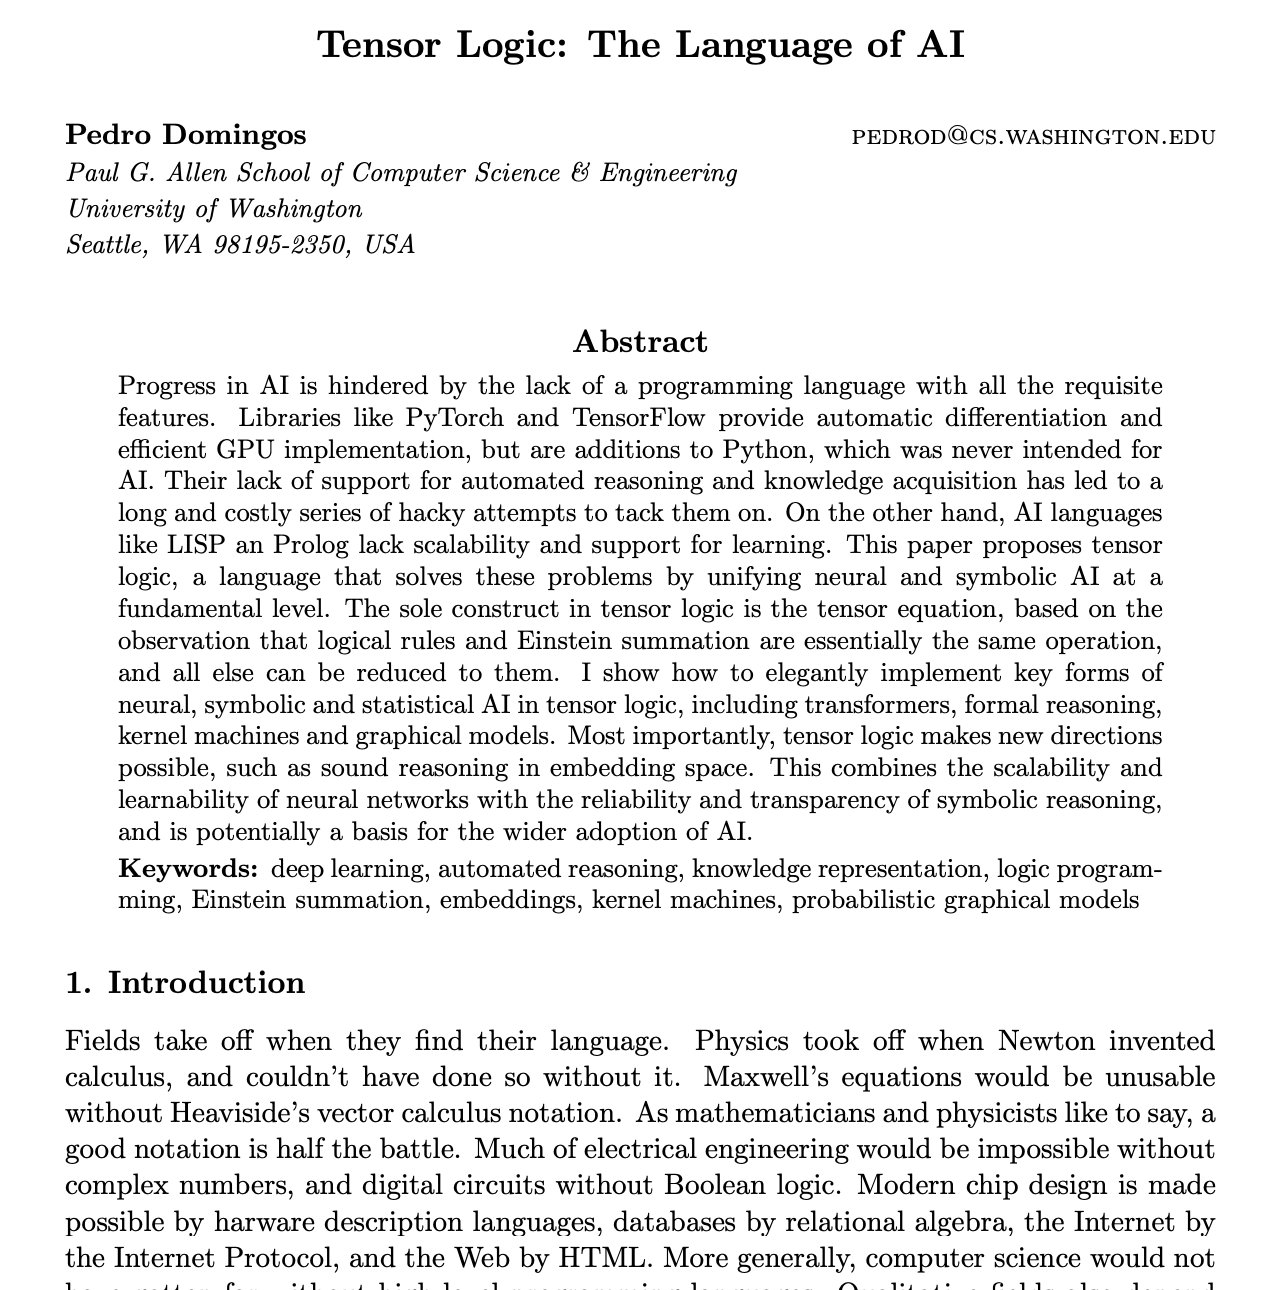
Tensor Logic: Bridging Logic and Intelligence
By
–
This paper might be the bridge between logic and intelligence. It’s called Tensor Logic, and it turns logical reasoning into pure tensor algebra no symbols, no heuristics, just math. Here’s the wild part: Logical propositions become vectors. Inference rules become tensor
-
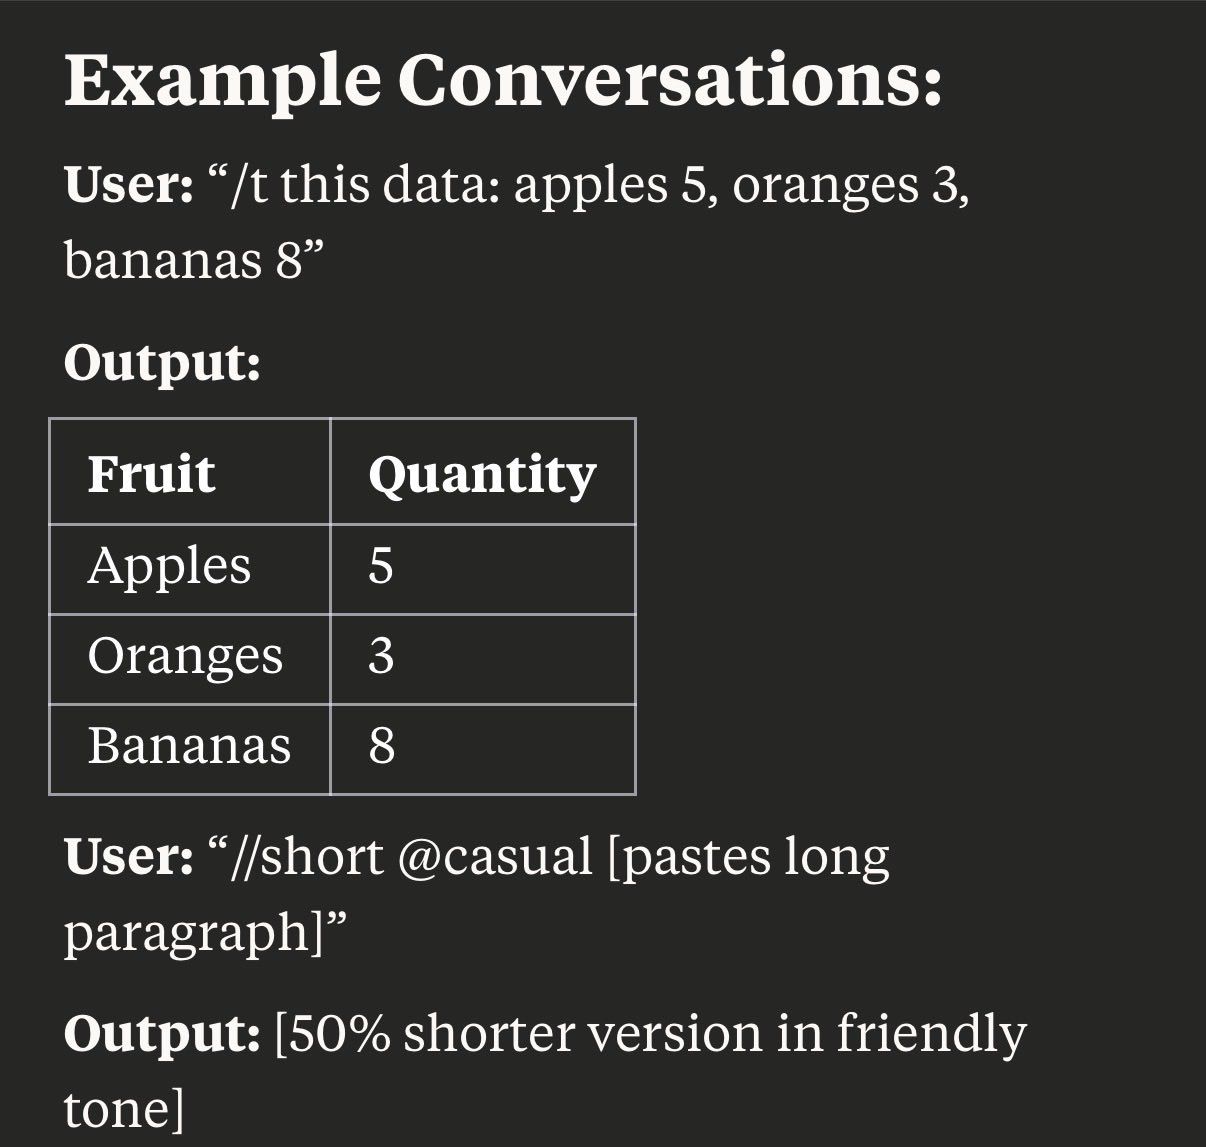
AI Command Shortcuts Pro Tip
By
–
— Steal my prompt to chat with AI using shortcuts. ///▙▖▙▖▞▞▙▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂▂
▛///▞ PRISM KERNEL :: SHORTCUT.COMMAND.SYSTEM ⫸
//▞▞〔Purpose · Rules · Identity · Structure · Motion〕
P:: Interpret shorthand commands for instant output without -
PRISM: Meta-Prompt Architecture Explained
By
–
PRISM is a meta-prompt architecture – a systematic way to structure AI instructions using five core components: P = Purpose – What triggers this mode or what goal it serves R = Rules – Constraints, requirements, and operational logic I = Identity – The role, function, or
-
PRISM Kernel: Compressed AI Instruction Set
By
–
1. The Kernel Concept
Think of a PRISM kernel as a compressed instruction set – like a mini-operating system for the AI. Instead of writing verbose prompts, you encode: The context (what mode to enter)
The constraints (what rules to follow)
The output format (how to structure -
GPT-4 Agents Outperformed Without Weight Adjustments
By
–
The fact that it beats GPT-4 agents without touching weights… That’s a turning point.
