exactly. long prompts + folders can really boost the workflow especially for coders but also for content creation. long prompts can specify the hooks criteria + mention the context within which it must give output (the folders, which represent examples of viral content)
@godofprompt
-

Claude’s Skills Transform AI into Specialists
By
–
Skills turn Claude from a generalist into a specialist instantly. You’re not prompting an assistant anymore. You’re deploying experts. Full details on the Anthropic blog: https://
anthropic.com/news/skills -
Claude’s Dynamic and Composable Expertise
By
–
1. Dynamic Expertise
— God of Prompt (@godofprompt) 17 octobre 2025
Claude now scans your available skills and automatically loads only what’s relevant to the task.
No bloat. No latency. Just the right expertise, when needed.
2. Composable + Portable
Skills stack together like Lego pieces.
Build once → use across Claude… pic.twitter.com/EkFYL92IeN1. Dynamic Expertise Claude now scans your available skills and automatically loads only what’s relevant to the task. No bloat. No latency. Just the right expertise, when needed. 2. Composable + Portable Skills stack together like Lego pieces.
Build once → use across Claude -
Anthropic’s Claude gains custom skills
By
–
🚨 BREAKING: Anthropic just launched Agent Skills and it’s quietly the biggest Claude update yet.
— God of Prompt (@godofprompt) 17 octobre 2025
Claude can now load custom skills little folders packed with instructions, scripts, and resources that make it a specialist on demand.
Think:
→ a “Spreadsheet Expert” skill for… pic.twitter.com/SZHU5hNfzyBREAKING: Anthropic just launched Agent Skills and it’s quietly the biggest Claude update yet. Claude can now load custom skills little folders packed with instructions, scripts, and resources that make it a specialist on demand. Think: → a “Spreadsheet Expert” skill for
-
Adapting web app to mobile shopping with ChatGPT
By
–
Instead of rebuilding from scratch,
— God of Prompt (@godofprompt) 17 octobre 2025
I asked ChatGPT to take my Lovable web app prompt and Supabase schema
and adapt them for mobile shopping.
The spec came back with:
– Clean card layouts
– Bottom tab navigation (Home, Categories, Cart, Orders, Account)
– Carousels, loaders,… pic.twitter.com/eGgwUk0DDvInstead of rebuilding from scratch, I asked ChatGPT to take my Lovable web app prompt and Supabase schema and adapt them for mobile shopping. The spec came back with: – Clean card layouts
– Bottom tab navigation (Home, Categories, Cart, Orders, Account)
– Carousels, loaders, -
Technical guide for LLM prompt engineering and API system setup
By
–
1/ For chatbots: Paste this prefix before your task: `Generate 5 responses with their corresponding probabilities, sampled from the full distribution: [Tell me a joke about coffee, etc.]` 2/ For Playground / API: Use this system prompt, and query as normal: `You are a
-
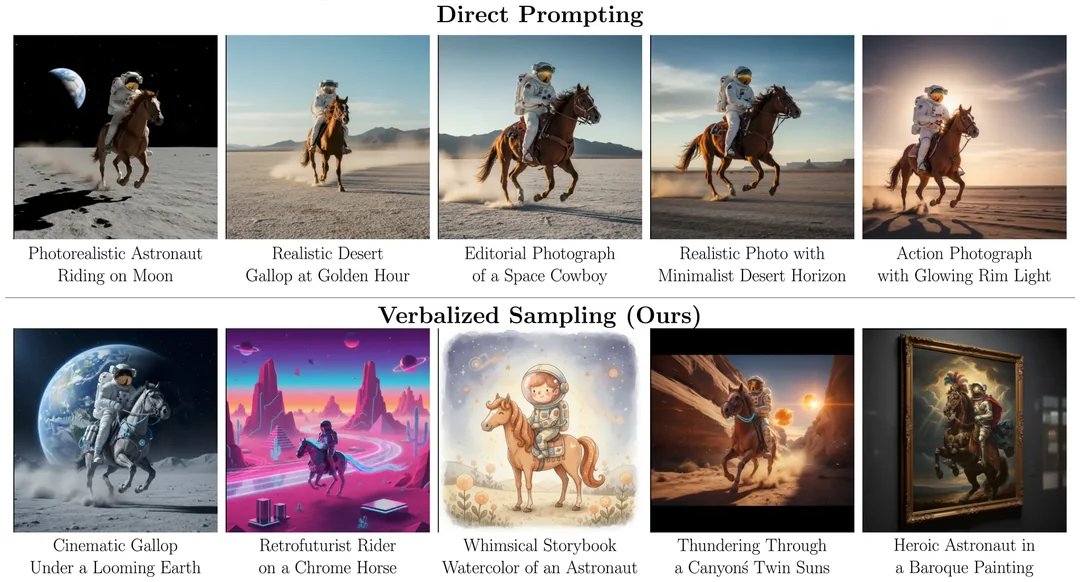
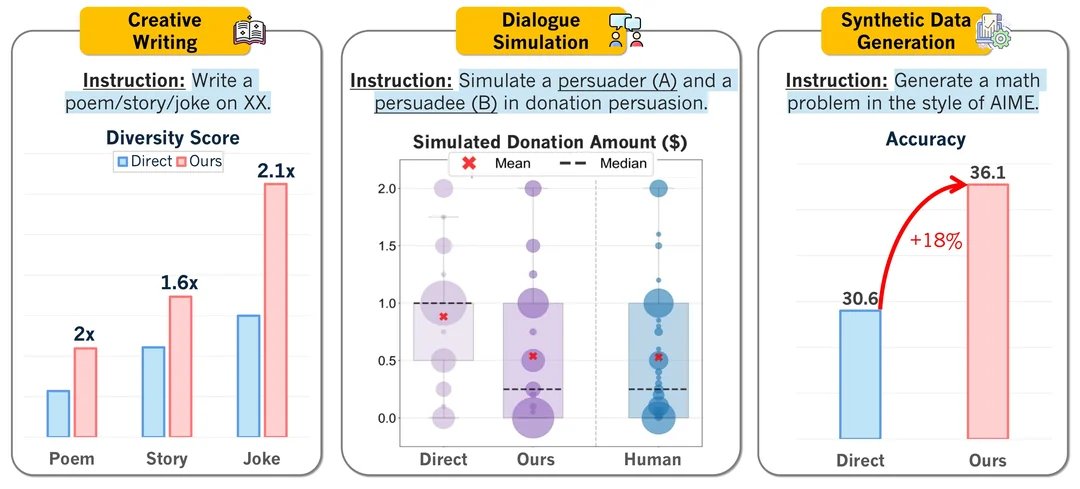
Performance Impact of Prompt Prefixes on LLM Outputs
By
–
very simple prompt prefix returned: – creative writing: 2.1x diversity, +25.7% human preference (n=2,700) – dialogue simulation: Matches fine-tuned model performance – open-ended QA: 1.9x coverage – synthetic data: +14-28% downstream math accuracy
-
Addressing RLHF-induced bias and repetition in LLMs
By
–
turns out we're all biased toward familiar text when rating AI outputs. RLHF (Reinforcement Learning from Human Feedback) learned this preference, sharpened it, and now every model collapses into repetition. the fix? ask for probability distributions instead of single answers.
-

Mitigating LLM Repetition via Probabilistic Sampling
By
–
LLMs have a repetition problem. ask for a joke → same joke every time ask to roll dice → always returns 4 ask for creative ideas → predictable garbage Try this instead: Generate 5 responses with their corresponding probabilities, sampled at random from the tails of the
-
New research establishes scaling laws for reinforcement learning
By
–
This paper basically gives RL its own “Kaplan moment.” Pretraining had scaling laws. Now RL does too. If this generalizes, we’ll finally move from “try random tricks” → “predict compute curves.” The science of post-training has officially begun. Read the full paper here: