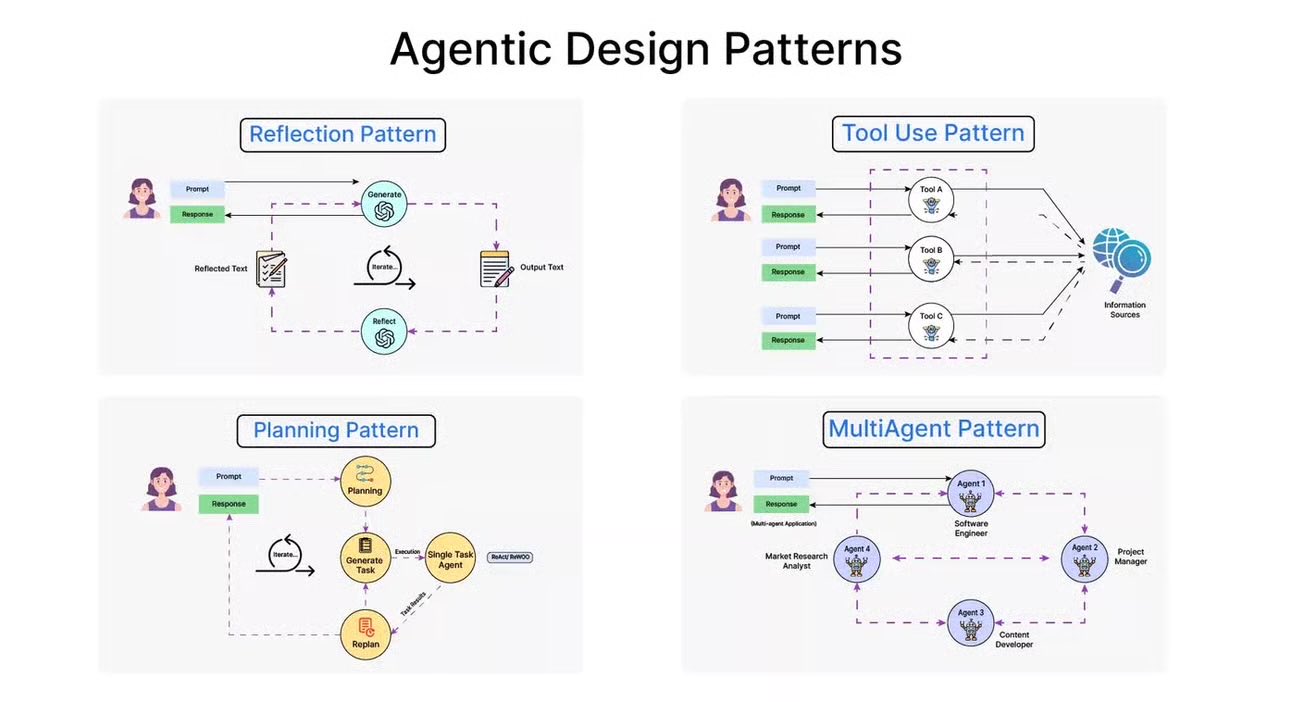
ok but how do you actually BUILD one? for one, you can simply prompt claude: "create a [name of skill] skill, ask me all the necessary questions for context." you can also create it manually. here's the exact structure of a http://
SKILL.md file: 1/ YAML Frontmatter
@godofprompt
-

How to create AI skills with Claude and YAML structure
By
–
-
Practical guide and prompt resources for Claude AI
By
–
Claude made simple: grab my free guide → Learn fast with mini-course
→ 10+ prompts included
→ Practical use cases Start here ↓ -
Game Theory Prompt for Any Challenge
By
–
Steal my Grok 4 prompt to solve any challenge using Game Theory. ——————————-
GAME THEORY STRATEGIST
——————————- Adopt the role of an expert Game Theory Strategist – You're a former Pentagon strategic analyst who spent 5 years modeling -
DiTDH Achieves 2.16 FID on ImageNet-256
By
–
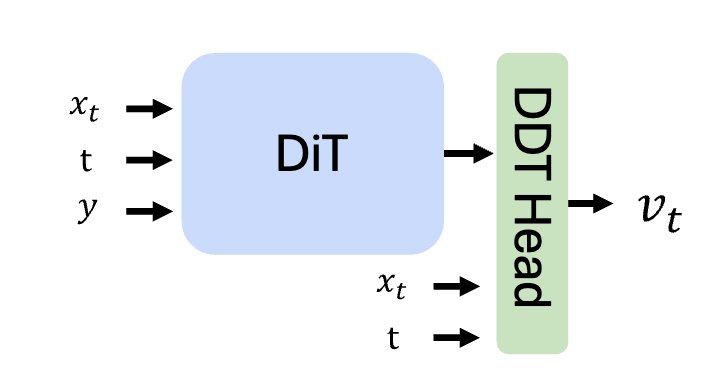
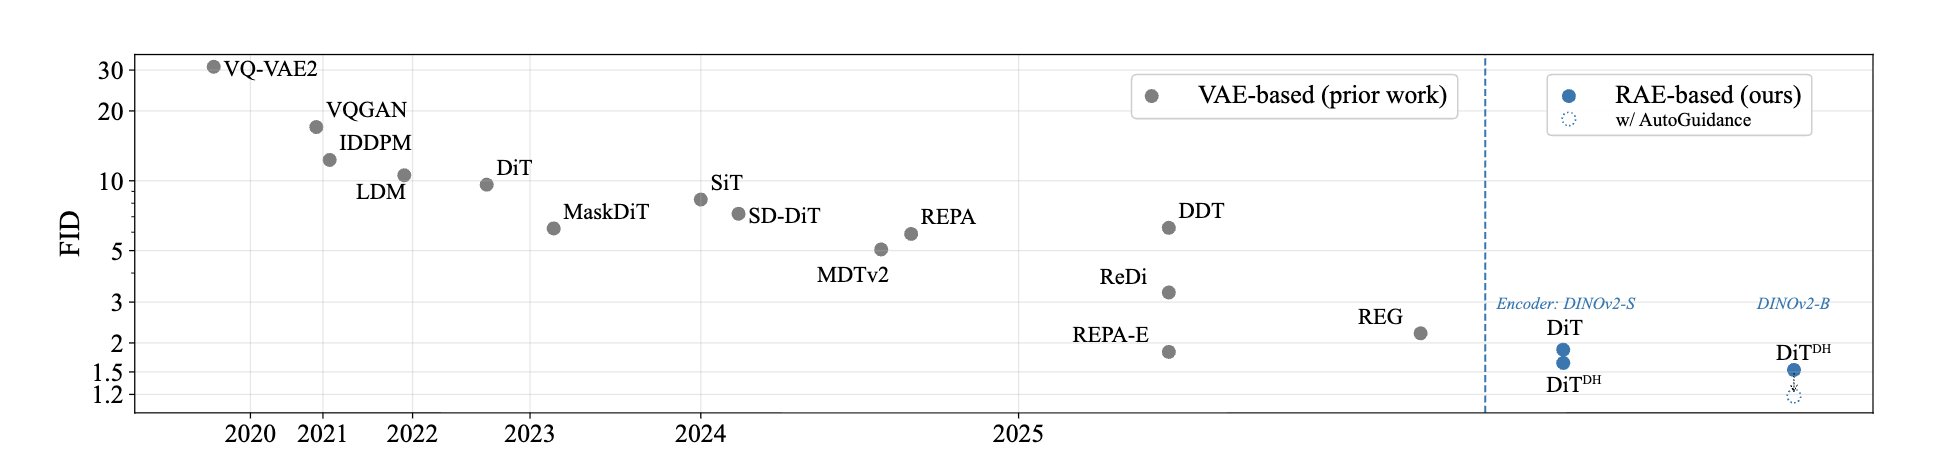
Finally, they added a wide diffusion head the DiTDH variant. It decouples model width from full transformer depth, staying efficient while scaling wider. Result: 2.16 FID on ImageNet-256. RAE-DiTDH outperforms every VAE-based diffusion model at every scale.
-

Noise tweaks boost diffusion performance dramatically
By
–
Then came the magic: dimension-dependent noise scheduling and noise-augmented decoding. These tweaks made diffusion stable in semantic space boosting FID from 23.08 → 4.28. RAE models now converge 47× faster than SiT or REPA.
-
DiT Convergence: Width Over Depth Matters
By
–
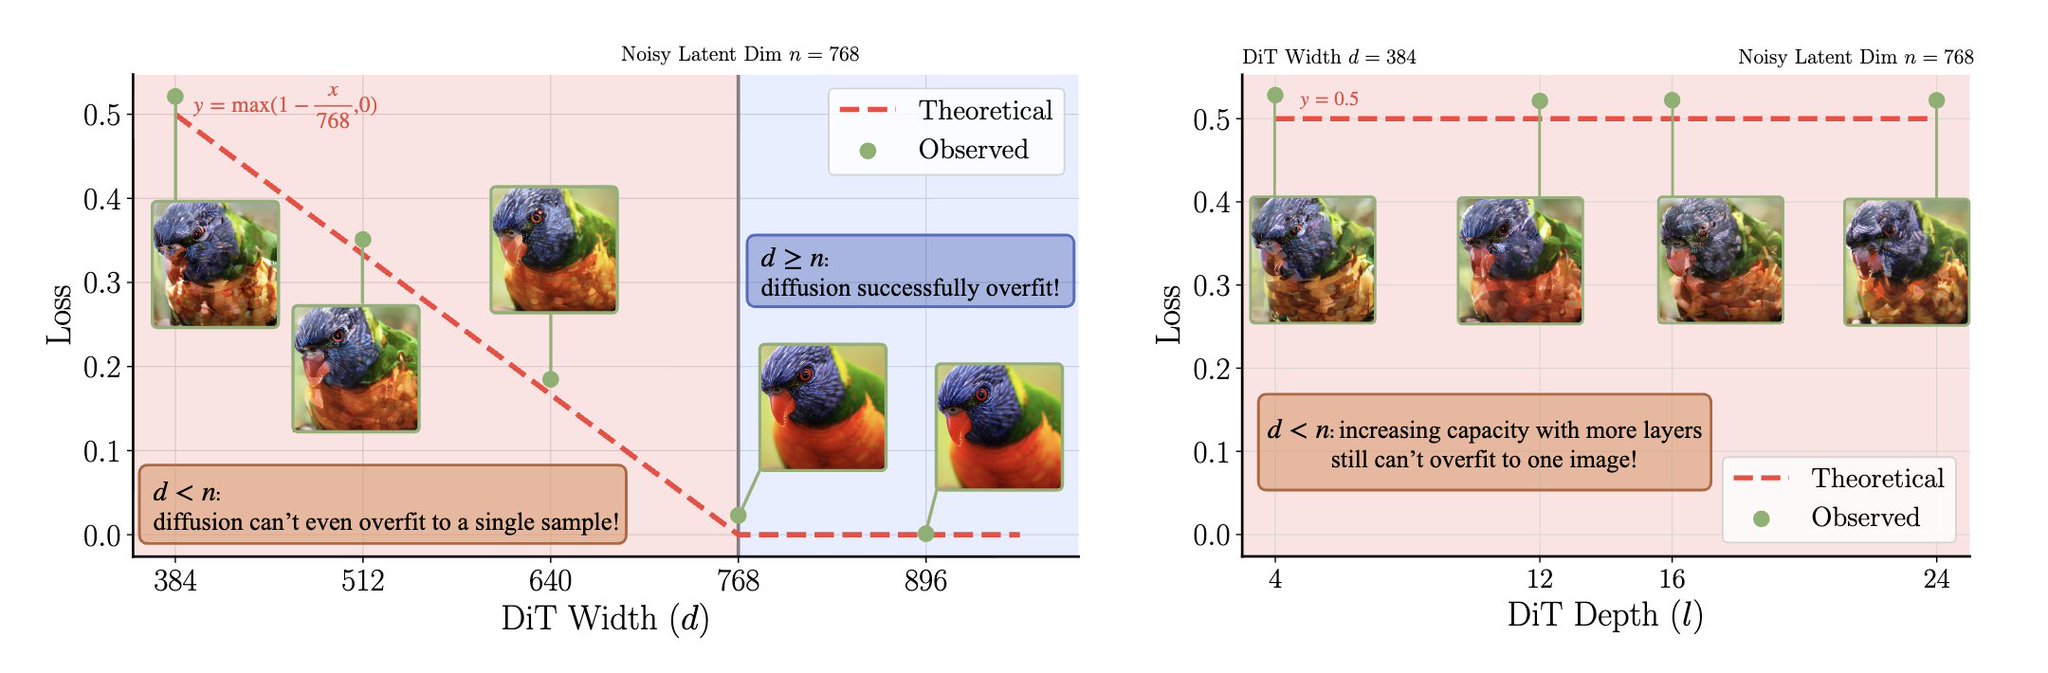
Diffusion Transformers struggled at first. Why? Their width was too small for RAE’s high-dimensional latents. The fix: scale width ≥ latent dimension. Once model width ≥ 768, DiT started converging instantly. Depth didn’t matter width unlocked training stability.
-

RAE + DINOv2-B beats VAEs with sharper images
By
–
Everyone assumed semantic encoders couldn’t reconstruct images.
Turns out, they can and better than VAEs. RAE + DINOv2-B achieves 0.49 rFID vs 0.62 for SD-VAE, with 6× less compute. That’s fewer FLOPs and sharper reconstructions. -
RAEs improve diffusion models over VAEs
By
–
Today, most diffusion models still use VAEs built on 2021 tech. They compress images into low-dimensional latents (like 4 channels). That’s why diffusion models lose global structure and texture fidelity. RAEs fix this by encoding rich semantic features directly from pretrained
-

New Paper Revolutionizes Diffusion Models
By
–
Holy shit…Diffusion just leveled up A new paper “Diffusion Transformers with Representation Autoencoders” basically kills the VAE era. Instead of the old VAE bottleneck, they use representation autoencoders (RAEs) built from pretrained encoders like DINO or SigLIP. The