Learn to use the new eve agentic framework from Vercel.
— DAIR.AI (@dair_ai) 23 juin 2026
Go try out the hands-on labs now. https://t.co/mC5nsSUNOe
Learn to use the new eve agentic framework from Vercel. Go try out the hands-on labs now.
By
–
Learn to use the new eve agentic framework from Vercel.
— DAIR.AI (@dair_ai) 23 juin 2026
Go try out the hands-on labs now. https://t.co/mC5nsSUNOe
Learn to use the new eve agentic framework from Vercel. Go try out the hands-on labs now.
By
–
The largest LLM-as-a-Judge reliability audit yet. Researchers ran 21 judges from nine providers over roughly 541,000 judgments on MT-Bench, JudgeBench, and RewardBench. Findings: Validating a judge with exact-match agreement overstates its skill, because exact match does not
By
–
The Top AI Papers of the Week (June 14 – June 21): – PreAct
– SpatialClaw
– Back on Track
– OpenClaw-Skill
– From Trainee to Trainer
– Compositional Skill Routing
– Can LLM Agents Infer World Models? Read on for more:
By
–
// Evolving Meta-Skill for Multi-Agent Systems // Can a multi-agent system get better at orchestration without touching a single weight? Automatic MAS generation has been stuck between two bad options. Inference-time methods use frozen frontier models but never learn from past
By
–
Great paper on long-term memory for LLM agents. (bookmark it) Coarse summaries drift and unconstrained updates corrupt, so AtomMem makes the unit of memory small. A Fact Executor pulls high-value atomic facts out of long interactions, organizes them into hierarchical event
By
–
If you build web agents, this one is worth your time. It's on how to make agent skills reusable. (bookmark it) LLM web agents usually run as tool callers. Each turn, the model reads a fresh page and emits one low-level action, so horizons and policy-facing LLM completions both

By
–
Who should design the training environment for an RL agent, the practitioner or the policy itself? RL pipelines for LLMs usually rely on manually redesigned environments between stages, with practitioners guessing which configuration will best improve the current policy. This

By
–
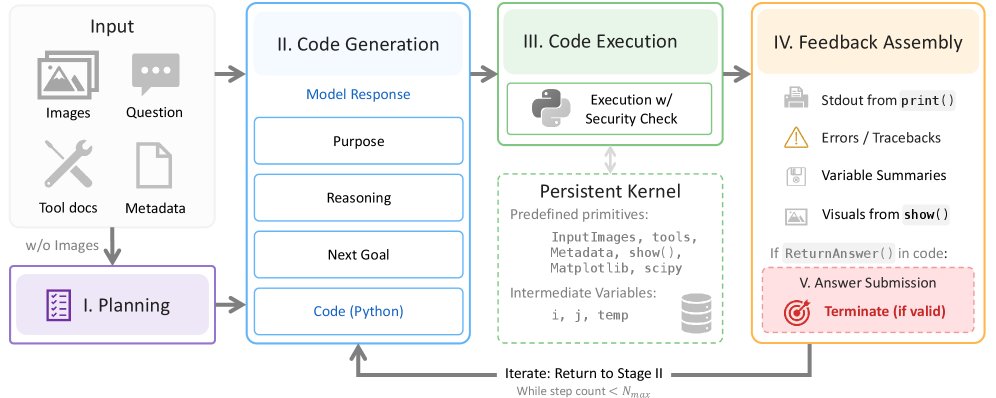
Outstanding paper on computer-using agents. (bookmark it) Computer-using agents drive real software through the screen, but they solve every task from scratch. Ask one to repeat a task, and it re-reads the screen and re-reasons every tap, paying the full cost again. PreAct

By
–
// HarnessX: Harnesses You Compile, Not Hand-Build // (bookmark it) Most agent harnesses are hand-crafted and frozen. Each new model or task means rewriting the prompts, tools, memory, and control flow from scratch, and the rich traces from every run get thrown away. HarnessX
By
–
The Top AI Papers of the Week (June 7 – June 14) – Agentopia
– Self-Harness
– Agents' Last Exam
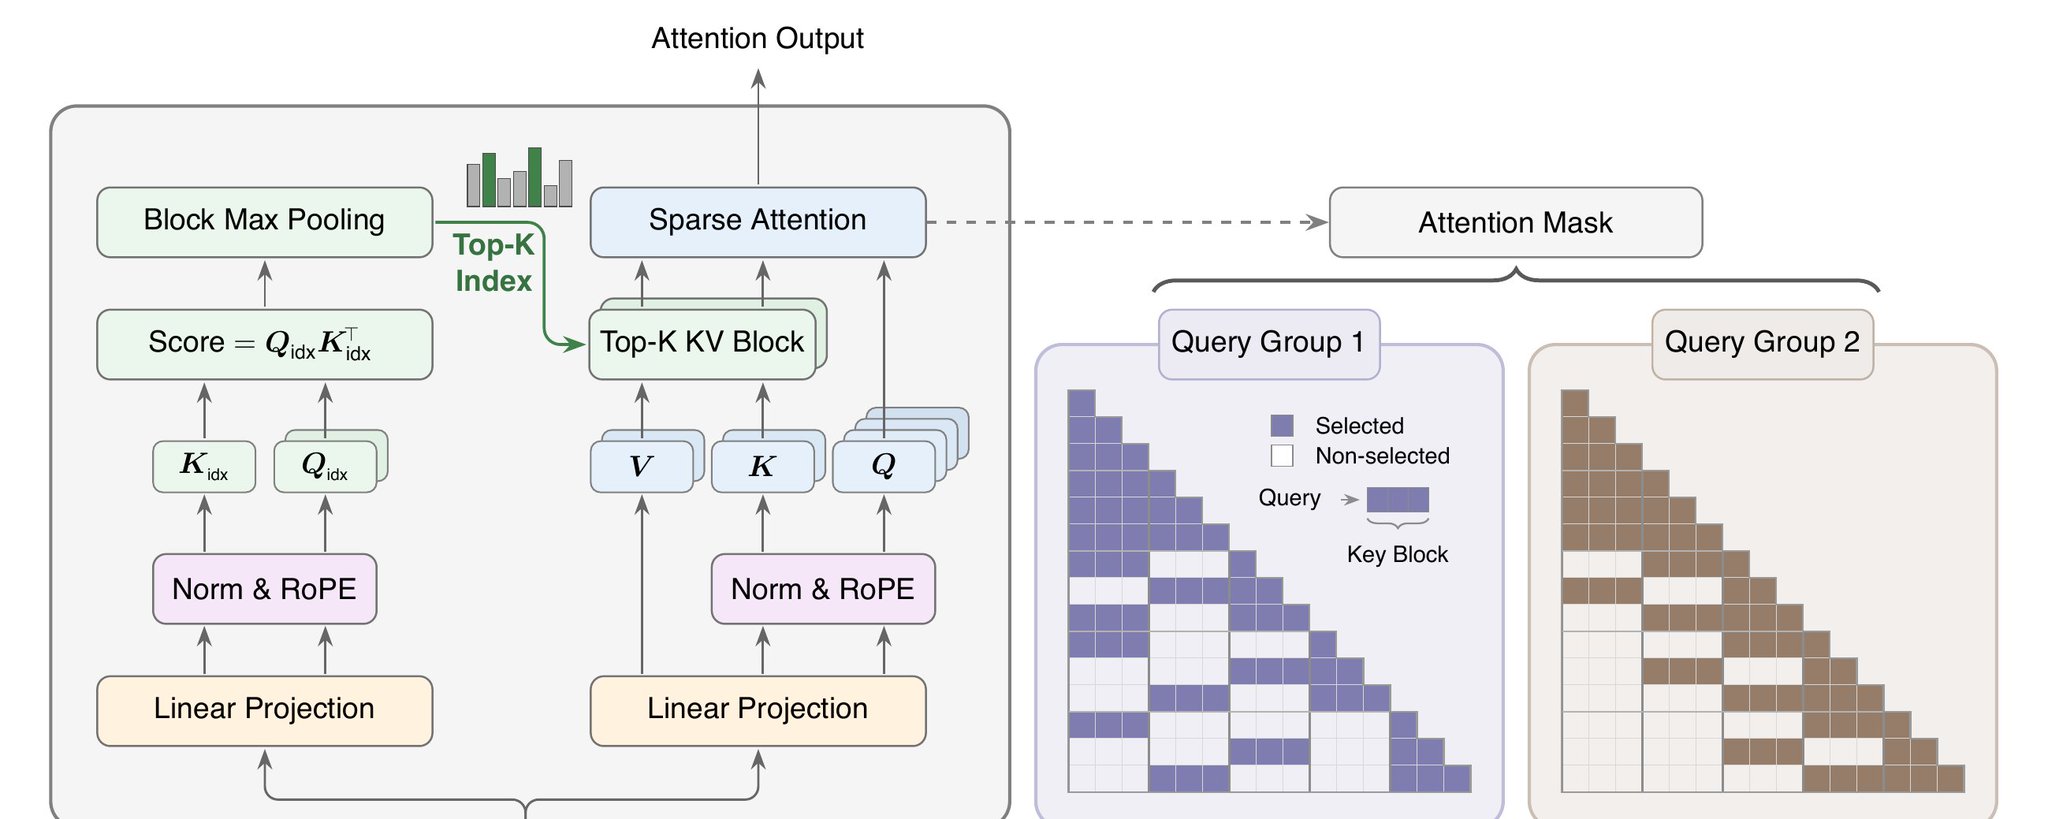
– MiniMax Sparse Attention
– Lookahead Sparse Attention
– How AI Agents Reshape Knowledge Work
– The Geometry of On-Policy Distillation Read on for more: