MemoryX uses commodity DDR5 memory in a 1U server format, making it super easy to procure & configure. We employed one rack for CS-3 & networking and another rack for a 55 TB MemoryX partition.
@cerebras
-
Cerebras MemoryX: 55TB External Memory for Trillion Parameters
By
–
Cerebras Wafer Scale Cluster uses unique, terabyte-scale external memory device called MemoryX to store model weights. For Sandia’s run, Cerebras configured a 55 terabyte MemoryX device – enough to comfortably store 1T parameters and optimizer states.
-
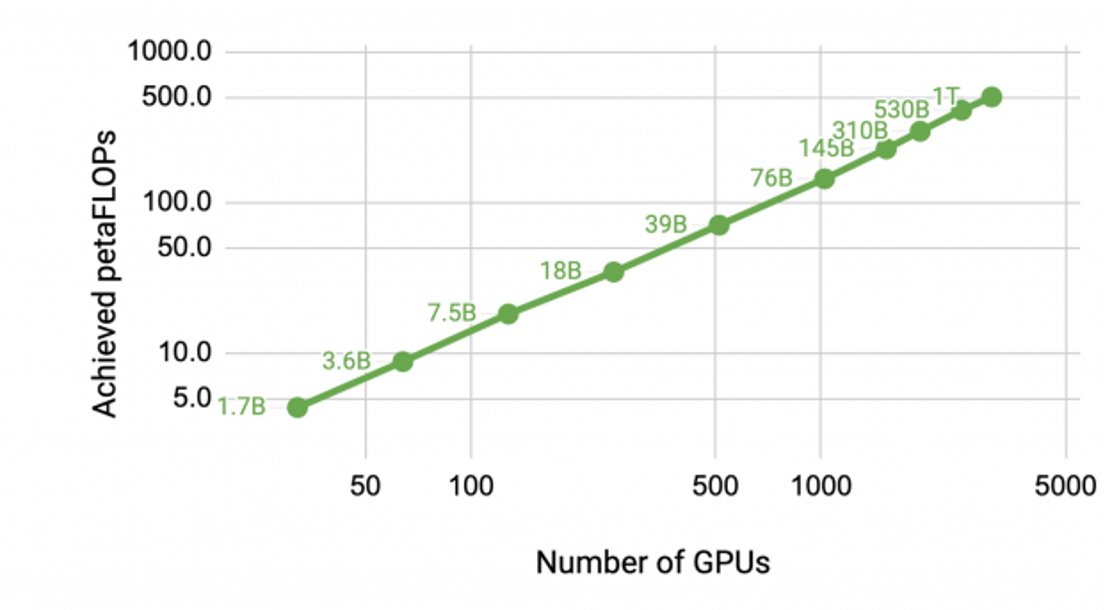
Trillion Parameter Models Demand Massive GPU Infrastructure Investment
By
–
Trillion parameter models require terabytes of memory. Thousands of GPUs must be procured and connected just to store the model weights. It takes months to bring up a working cluster of this scale. Nvidia's own chart below:
-

Cerebras CS-3 trains 1 trillion parameter model efficiently
By
–
Cerebras Systems + Sandia National Labs have demonstrated training of a 1 trillion parameter model on a single CS-3 system (!) This is ~1% the footprint & power of an equivalent GPU cluster.
-
Testing and Optimizing Language Models in Production Environments
By
–
What is it like to have a command Z button within your llama 🦙 production environment?
— Cerebras (@cerebras) 7 décembre 2024
In their LLamapalooza fireside chat with @erinmikail from @LaunchDarkly and @SarahChieng discuss how developers can test and optimize their llamas like never before!
Watch below: pic.twitter.com/TrYlpDpV4MWhat is it like to have a command Z button within your llama production environment? In their LLamapalooza fireside chat with
@erinmikail from @LaunchDarkly and @SarahChieng discuss how developers can test and optimize their llamas like never before! Watch below: -
Chip Advancements Shaping AI’s Next Competitive Wave
By
–
What should you expect from the next wave of competition? @andrewdfeldman will join a panel of industry leaders to discuss how the latest chip advancements are informing AI's capabilities, moderated by @sharongoldman Register for @FortuneMagazine Brainstorm AI here:
-
AIBI: AI-Powered Interview Platform Transforms Hiring Process
By
–
Meet AIBI: The Future of Interviews, powered by Cerebras Inference ⚡️
— Cerebras (@cerebras) 5 décembre 2024
Get instant insights, feedback and real-time follow up questions. Read how the hiring process is about to change: https://t.co/lKdvJ1HAIN pic.twitter.com/mQKYoAsTq6Meet AIBI: The Future of Interviews, powered by Cerebras Inference Get instant insights, feedback and real-time follow up questions. Read how the hiring process is about to change: https://
bit.ly/4il642w -
Cerebras Inference Crushes AWS Google on Llama Performance
By
–
Cerebras Inference is 75x faster than AWS, 32x faster than Google on Llama 3.1 405B. Nvidia's closest rival once again obliterates cloud giants in AI performance. Read more:
-
Cerebras Wafer-Scale Engine Powers Neocortex AI Supercomputer
By
–
How does the Cerebras Wafer-Scale Engine power the Neocortex AI supercomputer? Find out on December 6th. Register below!
-
Cerebras Demonstrates 70x Faster LLM Inference at NeurIPS 2024
By
–
It's that time of the year again! We're headed to Vancouver for NeurIPS 2024!
— Cerebras (@cerebras) 26 novembre 2024
Test drive Cerebras Inference, serving the biggest LLMs 70x faster than NVIDIA GPUs. Learn about the latest ML research that's powering the next wave of genAI.
See you there: https://t.co/9Cji9bKtx3 pic.twitter.com/JhGlaFPLWDIt's that time of the year again! We're headed to Vancouver for NeurIPS 2024! Test drive Cerebras Inference, serving the biggest LLMs 70x faster than NVIDIA GPUs. Learn about the latest ML research that's powering the next wave of genAI. See you there: https://
cerebras.ai/events/neurips
2024
…