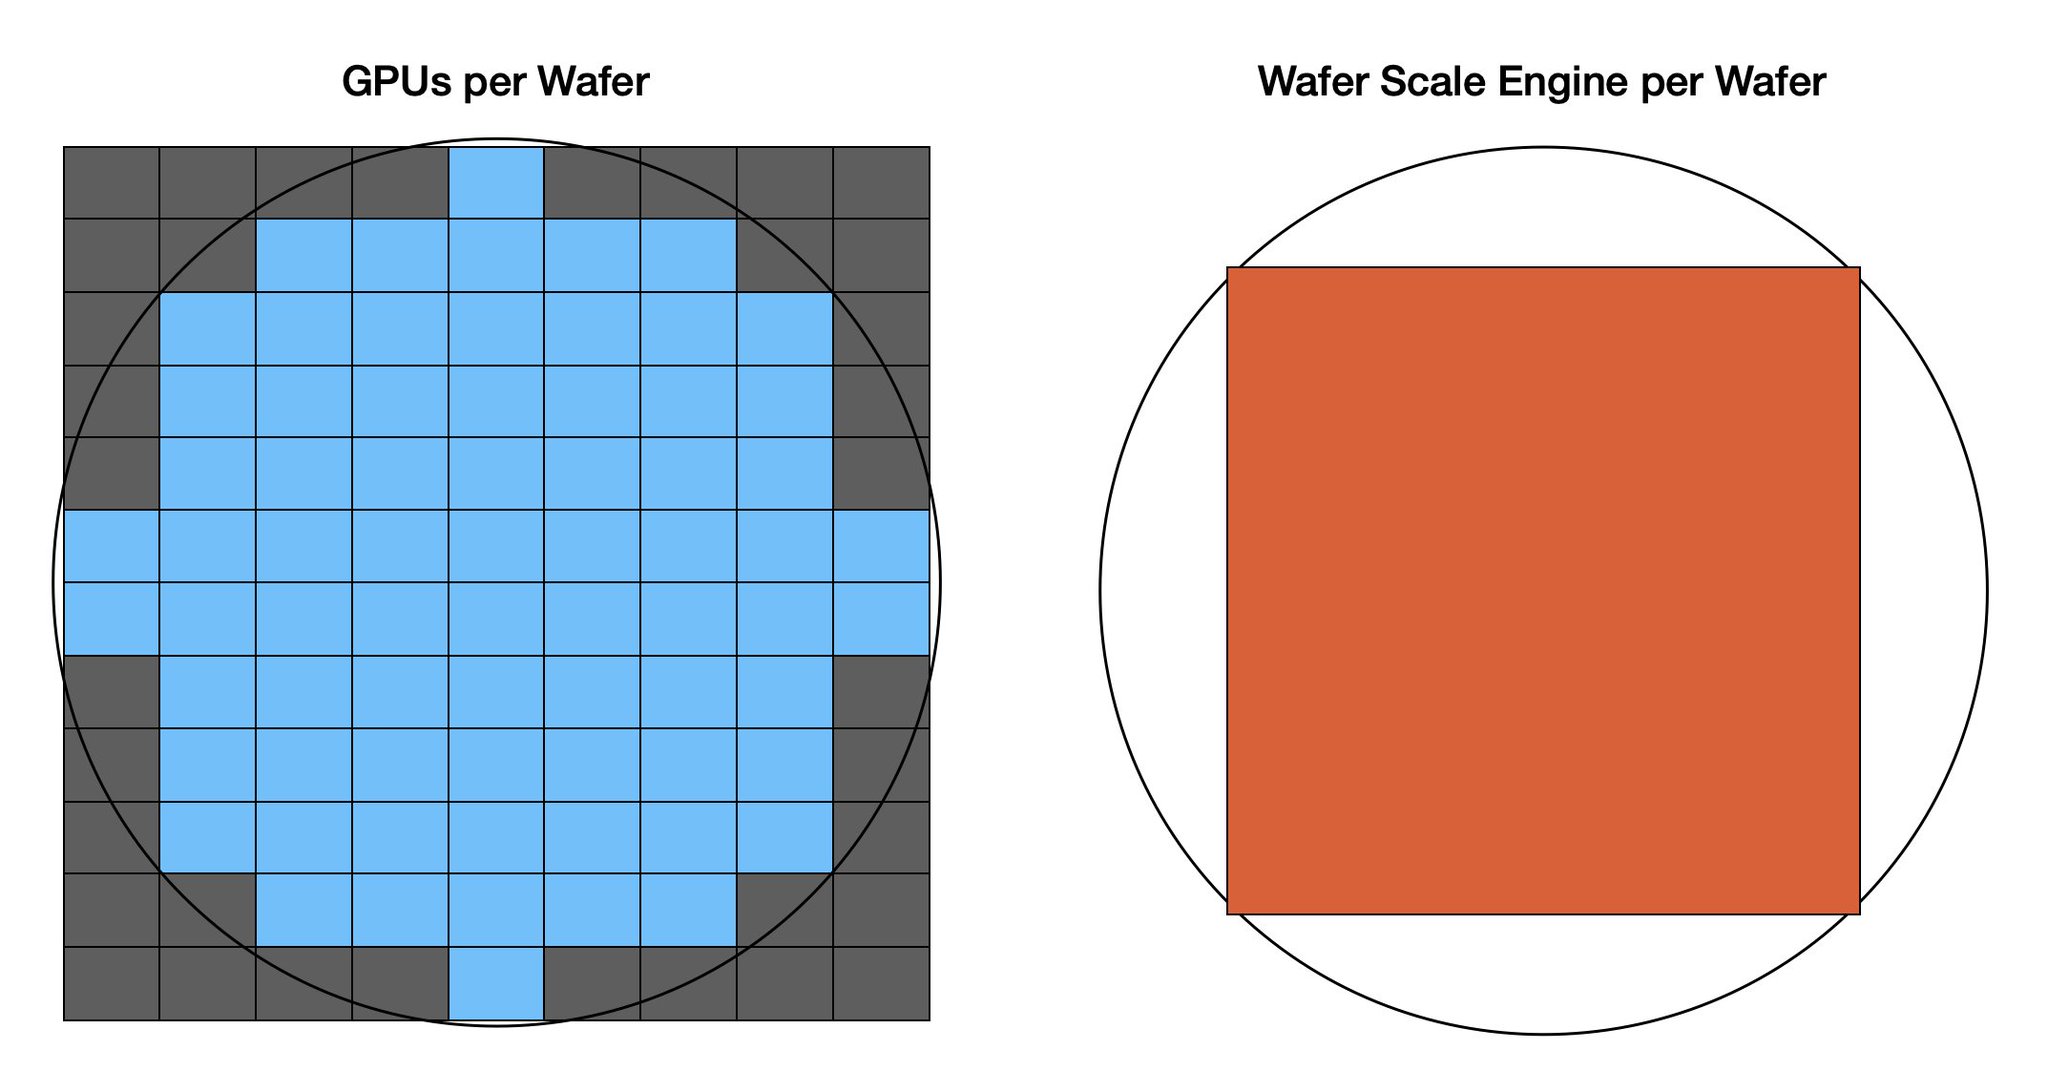
Let’s compare at the wafer level. At 5nm, here’s what an H100 sized chip and WSE look like side by side. A 300mm wafer yields ~72 GPUs or one Wafer Scale Engine.
@cerebras
-
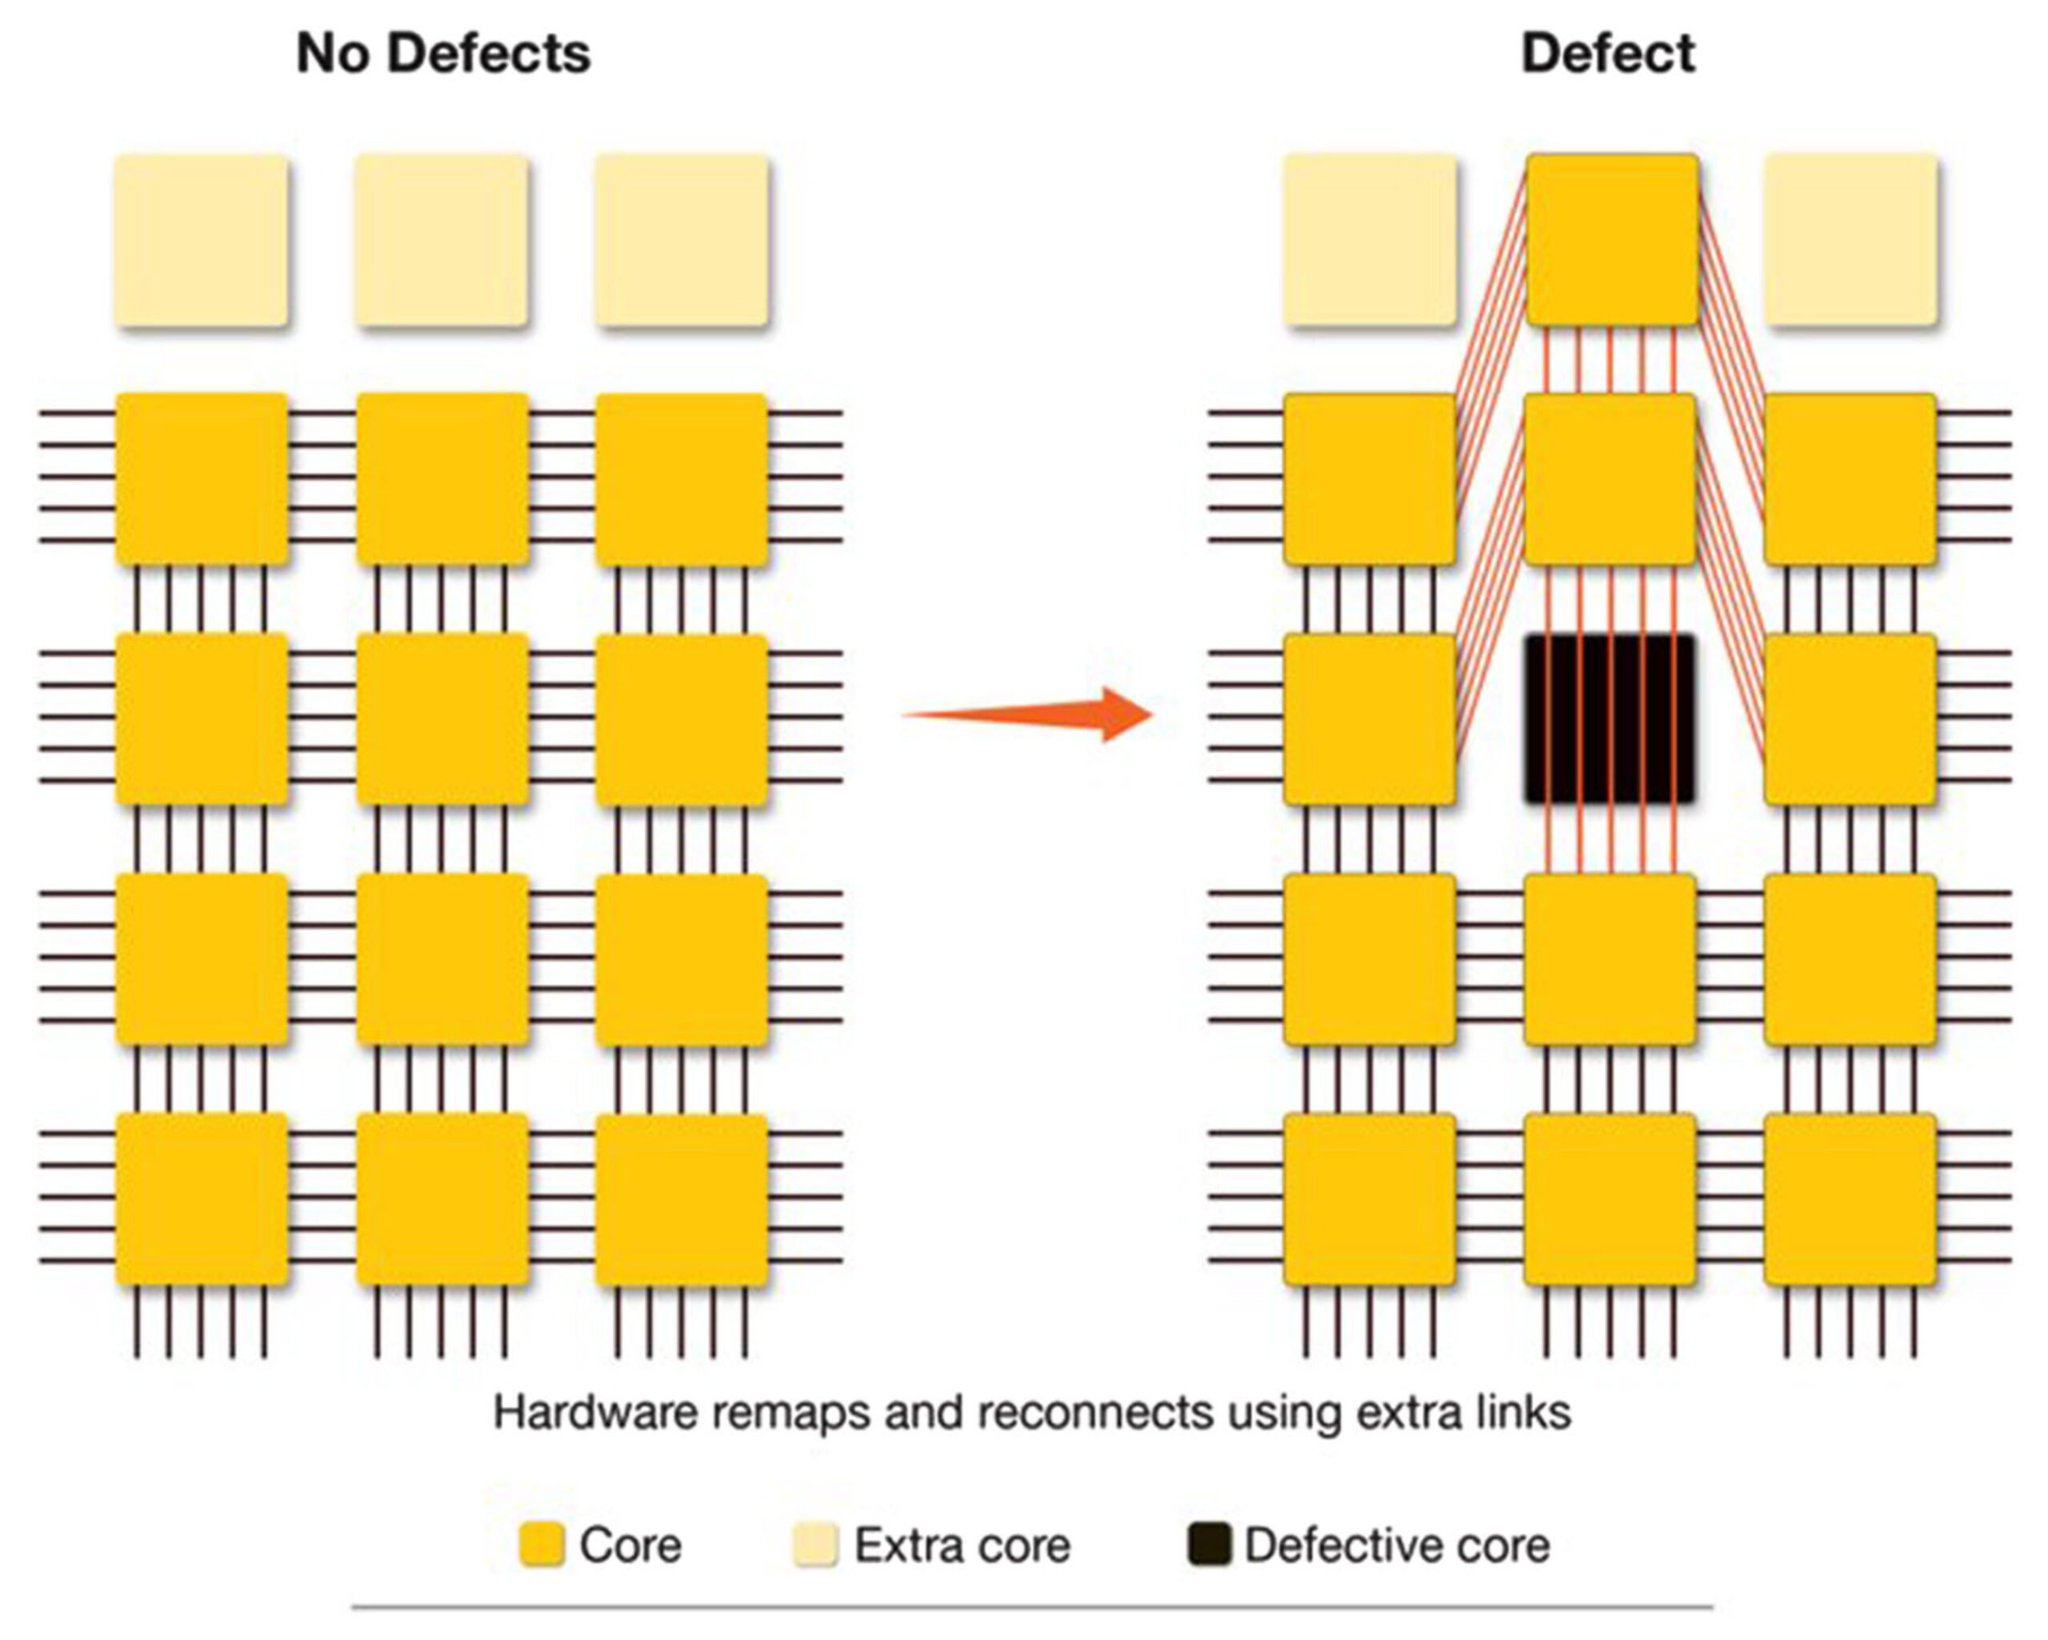
Fault-Tolerant Network Fabric with Redundant Communication Pathways
By
–
Our network fabric is also fault tolerant. When a defect is detected, the chip automatically routes around it using redundant communication pathways. The software layer presents the chip as a 2D grid even when there are defects.
-

WSE Cores: Tiny Chips Enable Efficient Large-Scale Hardware
By
–
Before we set out to build a large chip, we first designed a tiny core. Each WSE core is just 0.05mm^2 or ~1% the size of an H100 core. When a defect occurs, we lose a tiny amount of silicon relative to GPUs.
-

GPU Manufacturing Defects Impact Chip Performance Yields
By
–
Modern computer chips are far too large to yield perfect chips economically. When you buy a flagship H100 GPU, a dozen cores are either defective or disabled to manage yield. Since GPU cores are fairly large, too many defects can hurt performance.
-

Cerebras Solves Wafer-Scale Chip Yield Problem With Defect Tolerance
By
–
How does Cerebras yield a wafer-scale chip? Our latest blog provides the answers. https://
cerebras.ai/blog/100x-defe
ct-tolerance-how-cerebras-solved-the-yield-problem
… -
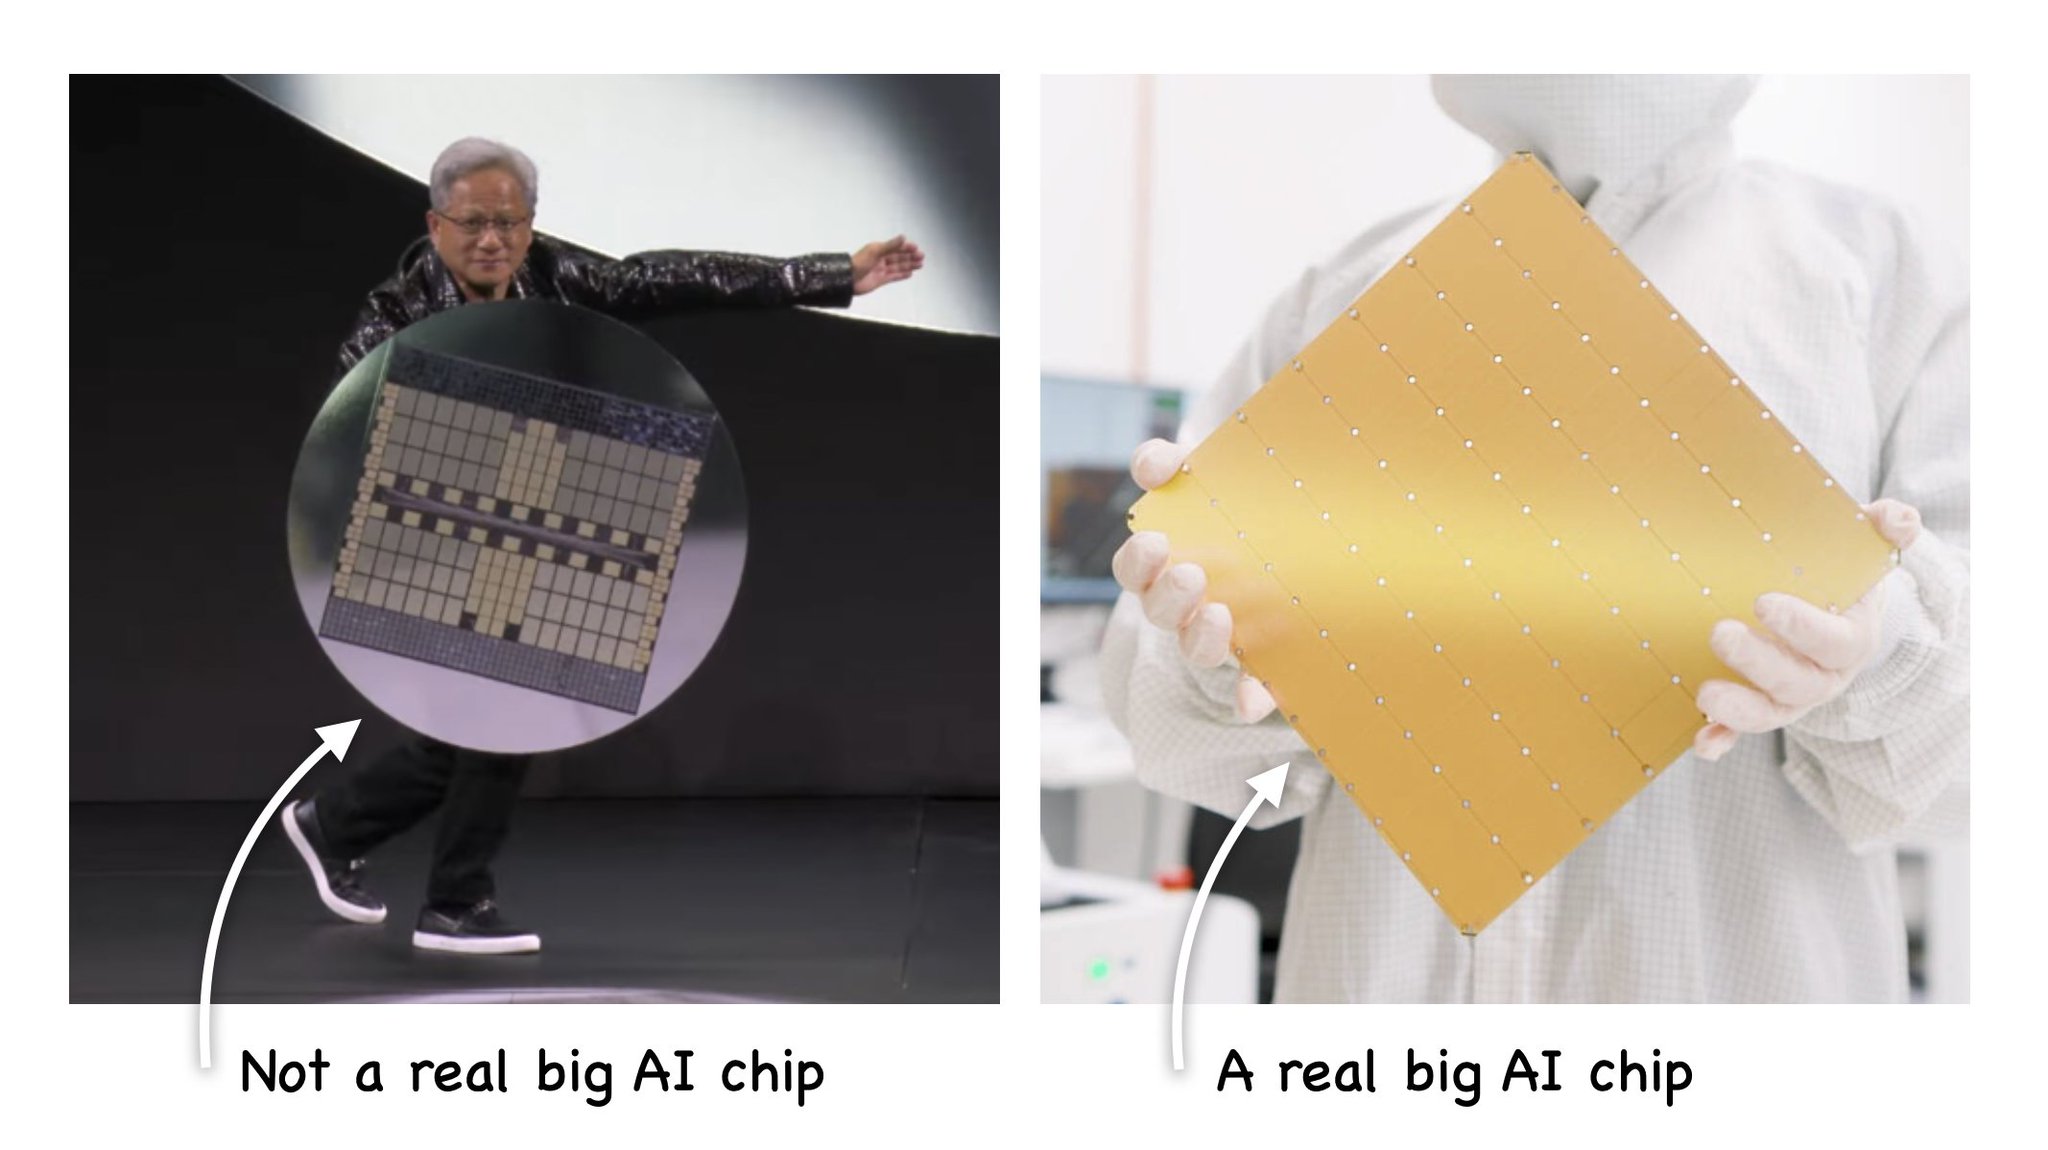
Nvidia’s CES Announcement: Industry Commentary and Analysis
By
–
We were asked to comment on Nvidia's CES
-
Tavus Digital Clone Powers Real-Time Conversations with Cerebras
By
–
Tavus is building the first, real-time digital clone, now powered by Cerebras Inference, to deliver an instant and natural conversation flow.
— Cerebras (@cerebras) 7 janvier 2025
Switching to Cerebras
⏱️ cut Time to First Token (TTFT) by 66%
⬆️ increased their Token Output Speed (TPS) by 3X.
Experience the… pic.twitter.com/xMwRsq8oayTavus is building the first, real-time digital clone, now powered by Cerebras Inference, to deliver an instant and natural conversation flow. Switching to Cerebras cut Time to First Token (TTFT) by 66% increased their Token Output Speed (TPS) by 3X. Experience the
-
Deploying LLMs with low latency and real-time responsiveness
By
–
Deploying LLMs with low latency and real-time responsiveness is no small task. But with @datarobot and Cerebras Inference, you’ll be ready to customize and deploy LLMs that deliver speed, precision, and real-time responsiveness. Dive in: https://
hubs.li/Q031lCn10 -
Cerebras Inference: 2200 tokens/sec on Llama 3.3 70B
By
–
What will you build in 2025 with the world's fastest Inference?
— Cerebras (@cerebras) 19 décembre 2024
Cerebras Inference by the numbers:
🔥 Blazing fast 2200 tk/s on Llama 3.3 70B.
🏎️ Record-breaking 969 tk/s on Llama 3.1 405B.
👋 70x faster than GPUs.
Try it today: https://t.co/rHJozqZvAx pic.twitter.com/xjuvA5Ooh7What will you build in 2025 with the world's fastest Inference? Cerebras Inference by the numbers: Blazing fast 2200 tk/s on Llama 3.3 70B. Record-breaking 969 tk/s on Llama 3.1 405B. 70x faster than GPUs. Try it today: http://
chat.cerebras.ai -

Speed in AI: The New Broadband Era for Applications
By
–
Speed matters, we are no longer in the dial-up era of AI. "Once we got broadband, all of a sudden, you had new applications, you had streaming, you had all these things that were fun, and the engagement was high, and I think that’s what’s happening right now with AI, is