At Cerebras, our mission is to accelerate AI by making it faster, easier to use, and more energy efficient, which is why we have created a unique research grant for university faculty and researchers. We want you to leverage Cerebras Inference to drive forward new techniques
@cerebras
-
NeurIPS24 Booth Success: ML Frontier Partnerships
By
–
From our booth, to happy hour with @e14fund
, to Cafe Compute with @GreylockVC and @sfcompute
, it's been an incredible week at NeurIPS24. Thanks to everyone who stopped by our booth to discuss how we can work together to move the frontier of ML forward! -
Memo-ry: AI Tool Assists Memory Loss Patients Daily
By
–
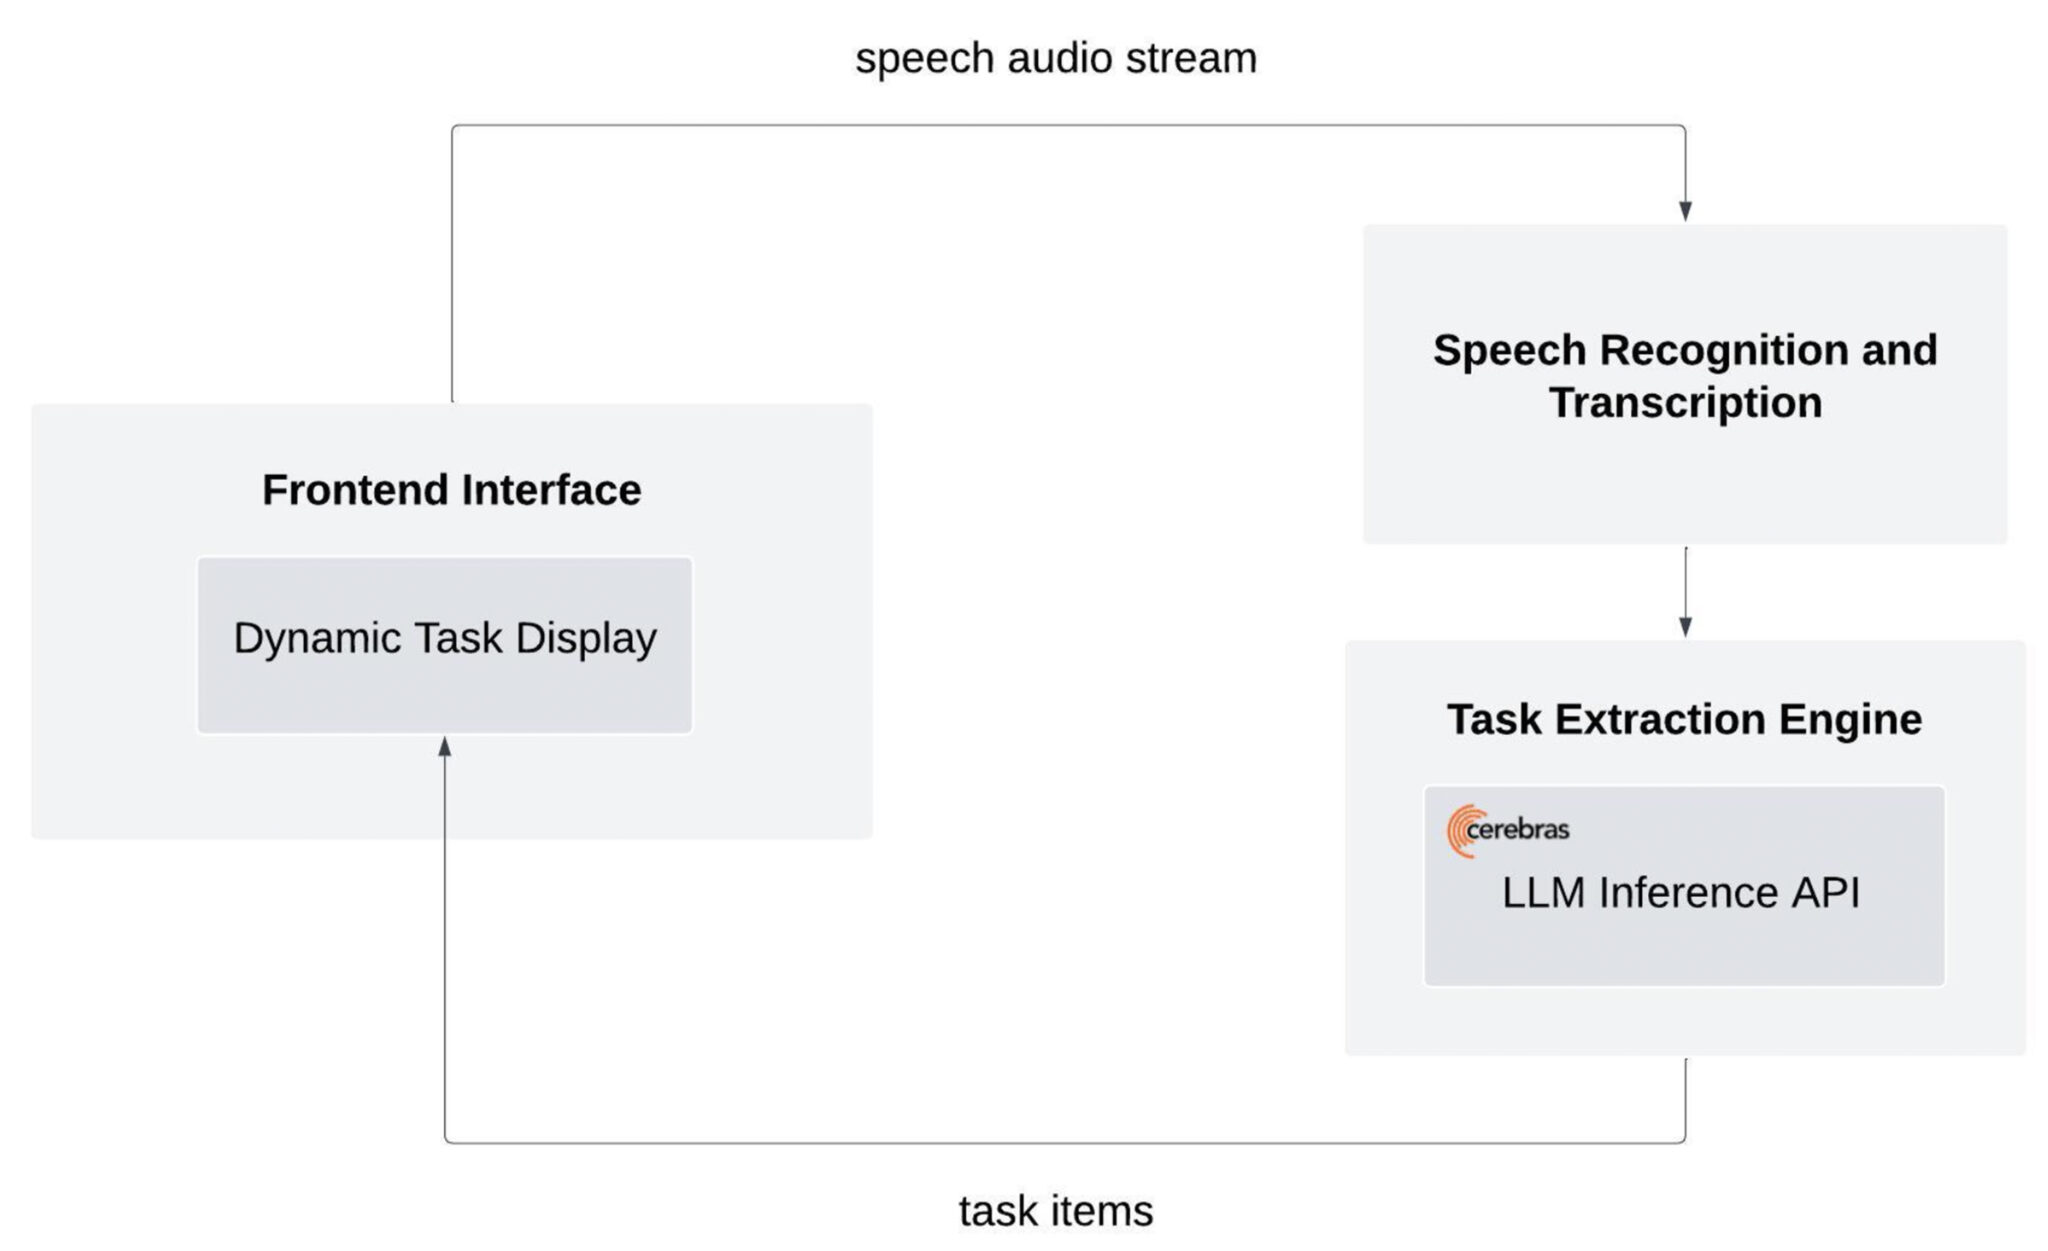
Meet Memo-ry, an instrumental tool to help make everyday activities more attainable for those with memory loss. Created by Fellow Jensen Coonradt, Cerebras Inference powerful speed processes conversations in near real-time to extract actionable tasks. Read more:
-

Cerebras Achieves 1 Trillion Parameter AI Model Training
By
–
To reach training of a 1 trillion parameter AI model is a one-of-a-kind achievement for frontier model development. Using Cerebras’ Wafer Scale Cluster technology, researchers at @SandiaLabs were able to initiate training on a single AI accelerator. We’re proud to help our
-
Llama 3.3 70B Results Missing from Analysis
By
–
they didn't submit results for llama 3.3 70B https://
artificialanalysis.ai/models/llama-3
-3-instruct-70b/providers#pricing
… -
Llama 3.3 70B on Cerebras Inference: Santa chatbot demo
By
–
What will Santa bring you? Ask him yourself with a little help from the friendly elves at @tavus and the speed of Cerebras Inference at 2200+ t/s. All we want for Christmas is to see what you will do Llama 3.3 70B running on Cerebras Inference. Talk to Santa:
-
Cerebras Trains Trillion-Parameter Models on Single CS-3
By
–
Learn more here: https://
cerebras.ai/press-release/
cerebras-demonstrates-trillion-parameter-model-training-on-a-single-cs-3-system
… https://
cerebras.ai/blog/introduci
ng-gigagpt-gpt-3-sized-models-in-565-lines-of-code
… -

Cerebras-GPT vs Megatron: Simplifying GPU Training Architecture
By
–
Nvidia is very proud of Megatron – it lets you train across thousands of GPUs! But it's 20K lines of code to manage the cluster. Cerebras-GPT is 500 lines of code. One block of memory. One logical accelerator. No distributed computing. Everyone who's used it calls it magic.
-

Linear Scaling AI Model Training Across Multiple Systems
By
–
After the single box ran, we scaled it to 2 and 16 systems with linear scaling. There were no model & code changes required.
Megatron
DeepSpeed
Sharding The model lives on a single block of memory. No need to break it up. The whole thing trains like one giant GPU. -
CS-3 Model Training Shows Stable Loss and Learning Curves
By
–
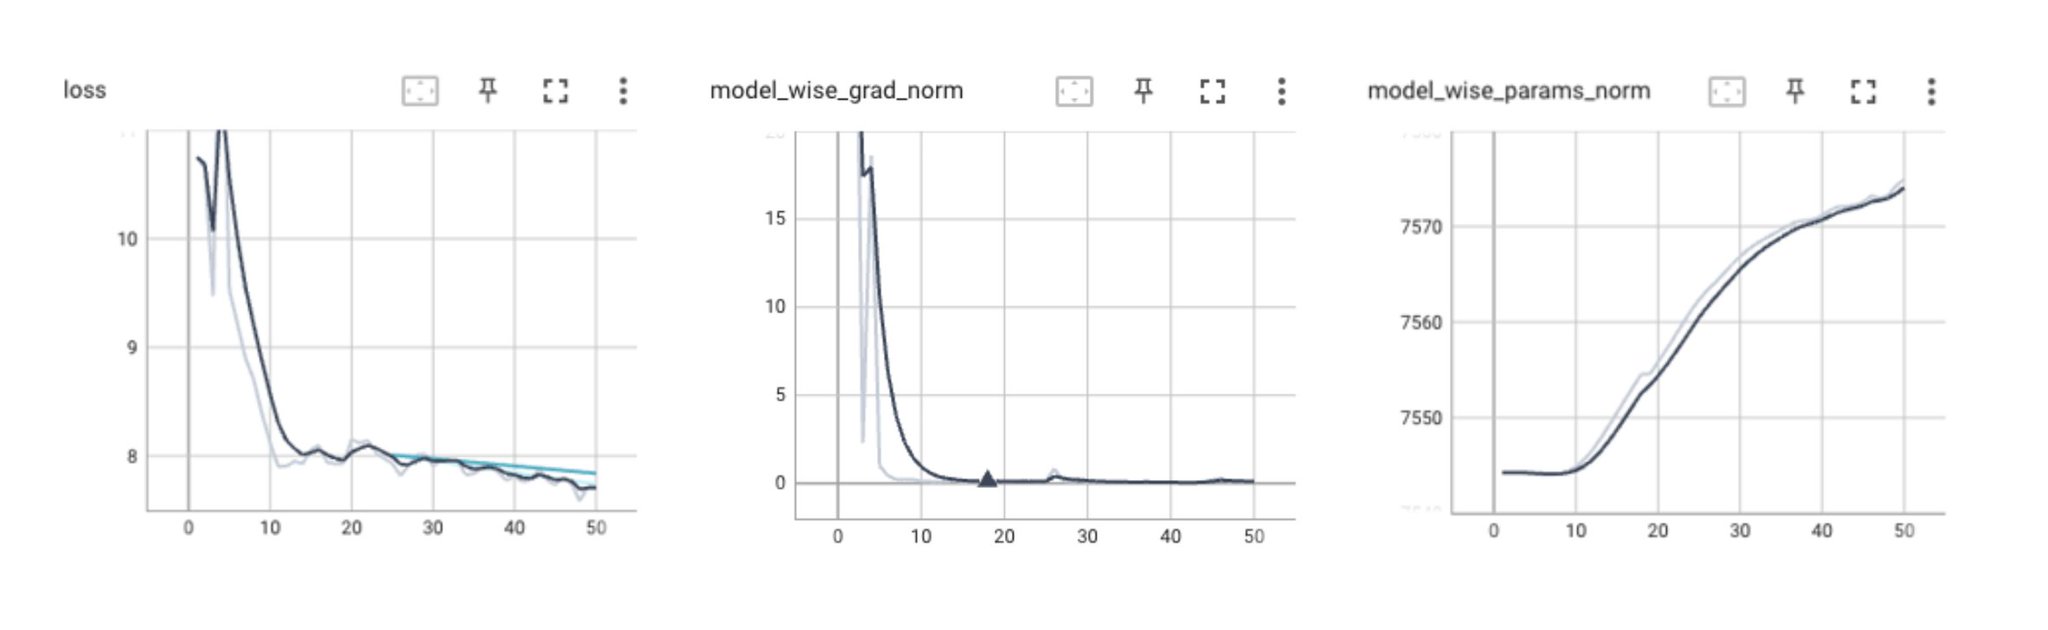
We ran about 50 steps on the CS-3. Saw nice loss and stable training curves