The results: – 1.59× higher Mean Accepted Length (MAL) than layer-pruned draft models
– 43.87% fewer MACs (Multiply-Accumulate operations) than dense draft models
– Only 8.36% reduction in MAL vs. dense models — a strong tradeoff for efficiency
@cerebras
-
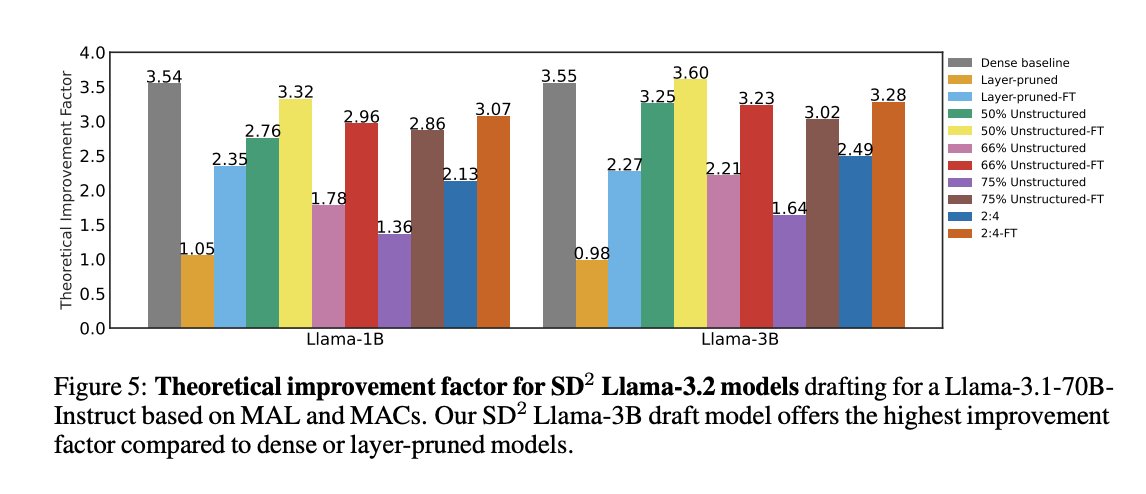
Draft Model Pruning Achieves 43% Fewer MACs with Strong Performance
By
–
-
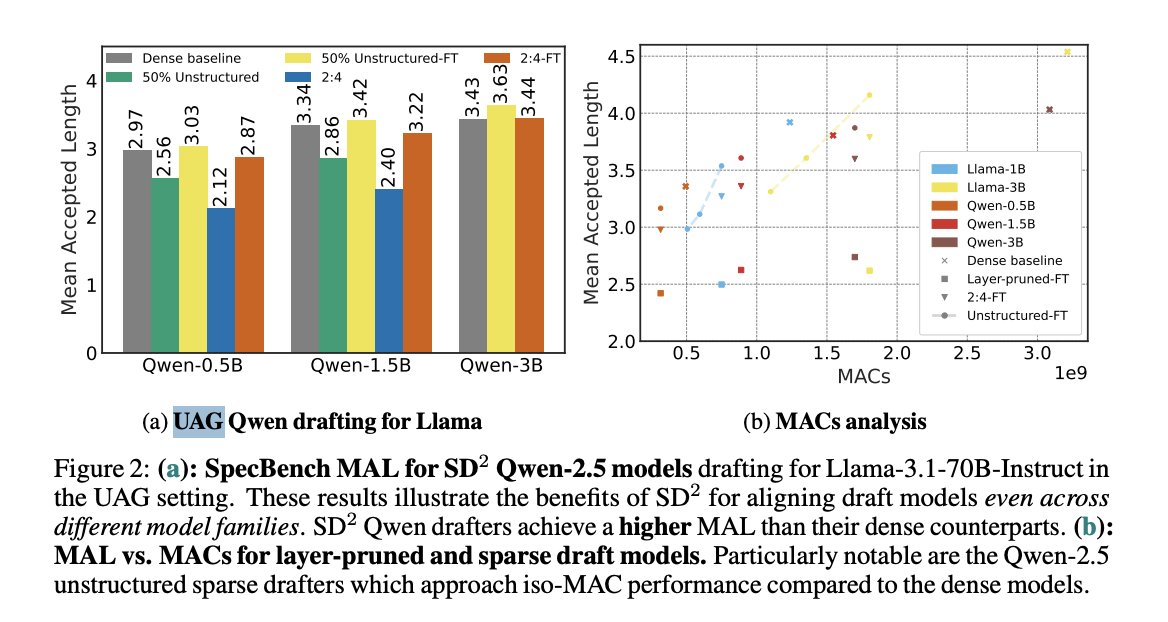
SD² Enhances Draft Token Acceptance Reducing MACs
By
–
SD² systematically enhances draft token acceptance rates while significantly reducing Multiply-Accumulate operations (MACs), even in the Universal Assisted Generation (UAG) setting, where draft and target models originate from different model families.
-
Self-Distilled Sparse Drafters: Efficient AI Model Methodology
By
–
The team's approach: Introducing Self-Distilled Sparse Drafters (SD²), a novel methodology that leverages self-data distillation and fine-grained weight sparsity to produce highly efficient and well-aligned draft models.
-
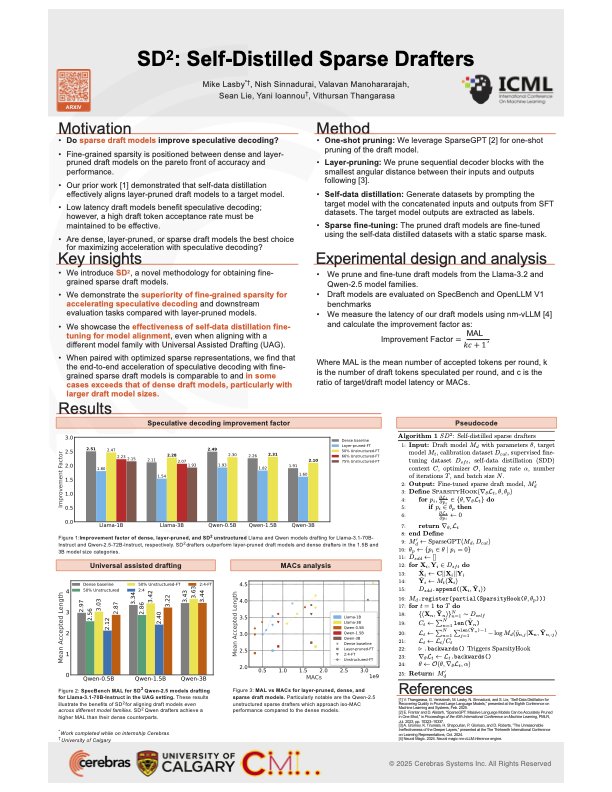
SD² Self-Distilled Sparse Drafters Speeds Up LLM Inference
By
–
Featured Paper at @icmlconf – The Internationall Conference on Machine Learning: SD² – Self-Distilled Sparse Drafters Speculative decoding is a powerful technique for reducing the latency of Large Language Models (LLMs), offering a fault-tolerant framework that enables the
-
Free API Key Launch: Speed Up Your Development Today
By
–
Do you feel the need for speed? Get your free API key and start flying!
-
Cerebras Achieves Order of Magnitude Token Output Improvements
By
–
"Before Cerebras, everything sits sub 200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers —faster responses, richer… pic.twitter.com/Geo41OaASV
— Cerebras (@cerebras) 27 juin 2025"Before Cerebras, everything sits sub 200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers —faster responses, richer
-
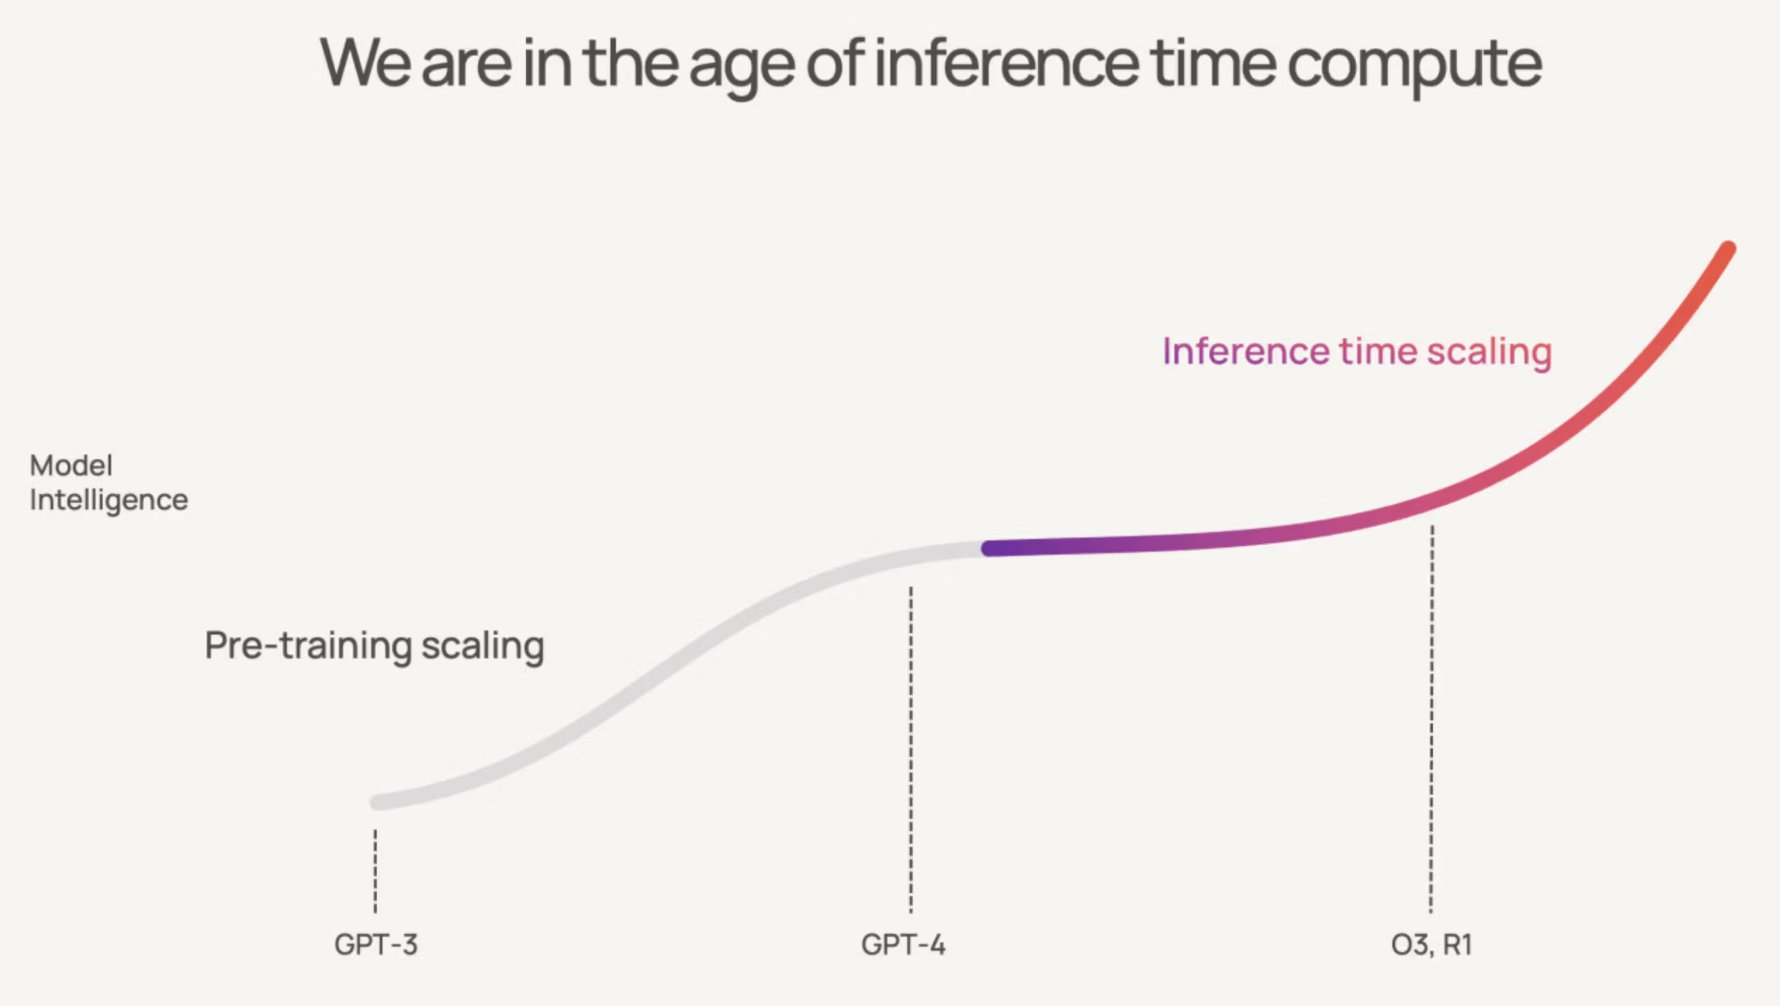
Cerebras Scaling Laws: Faster Inference for Smarter AI
By
–
AI Scaling Laws from the Cerebras Perspective
A new blog post by our CTO, Sean Lie https://
cerebras.net/blog/the-cereb
ras-scaling-law-faster-inference-is-smarter-ai
… -
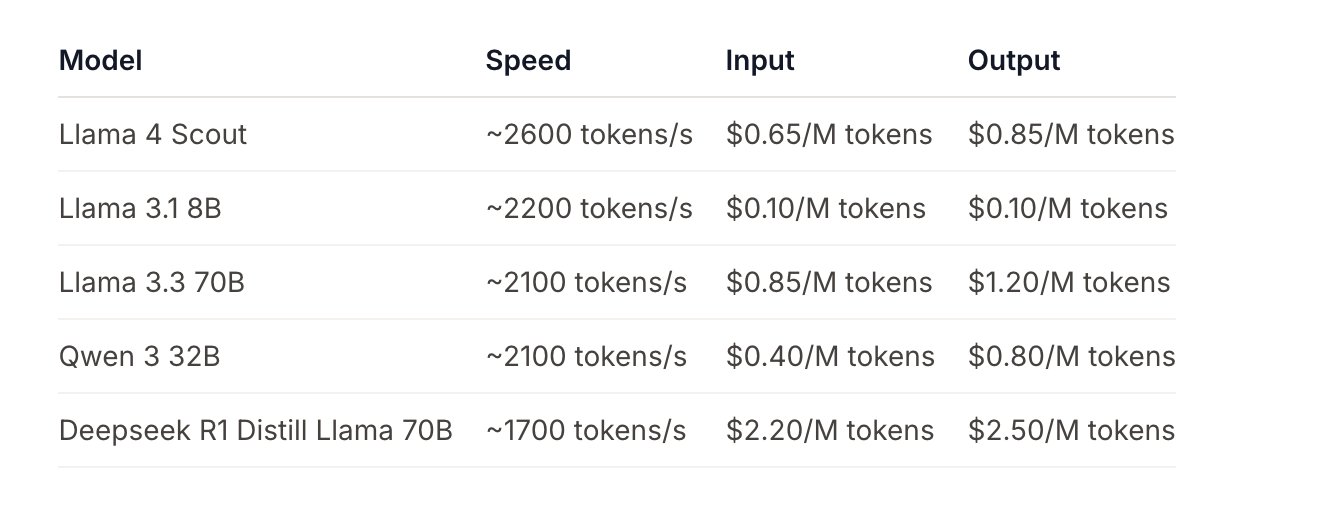
Cerebras Inference API Pricing Updates and Details
By
–
https://
inference-docs.cerebras.ai/support/pricing -

Try Qwen3 on Cerebras: AI Model Inference Platform
By
–
Think. But don't over think.
Try saying 'hello' to Qwen3 on Cerebras: https://
inference.cerebras.ai/?utm_source=tw
itter
…