Join the Cerebras Supernova Startups Program — transforming startups to build what they can’t on GPUs
@cerebras
-
Supernova: Real-time Reasoning with Qwen Open-weight Model
By
–
Supernova showed what’s possible when inference isn’t the bottleneck.
— Cerebras (@cerebras) 22 mai 2025
⚡️ Real-time AI
🛠️ Agentic workflows
🧠 Qwen: the fastest open-weight reasoning model, now running in real time
Big thanks to the devs, startups, customers, and partners who made it electric. pic.twitter.com/oL0Gk0gVDkSupernova showed what’s possible when inference isn’t the bottleneck. Real-time AI Agentic workflows Qwen: the fastest open-weight reasoning model, now running in real time
Big thanks to the devs, startups, customers, and partners who made it electric. -
Llama 4 Hackathon NYC May 31 June 1
By
–
We’re super excited to be supporting @cerebral_valley
’s Llama 4 hackathon with @MetaforDevs on May 31st-June 1st in NYC! This is going to be one of the best AI events of the year, and we’re excited to see what you build! We will also be providing API credits for all developers -
Qwen3-32B Reasoning: 1.7s TTFA on 10K Input
By
–
Default is 1k input. On 10k input, time to first answer is just 1.7s. https://
artificialanalysis.ai/models/qwen3-3
2b-instruct-reasoning/providers/prompt-options/single/long
… -
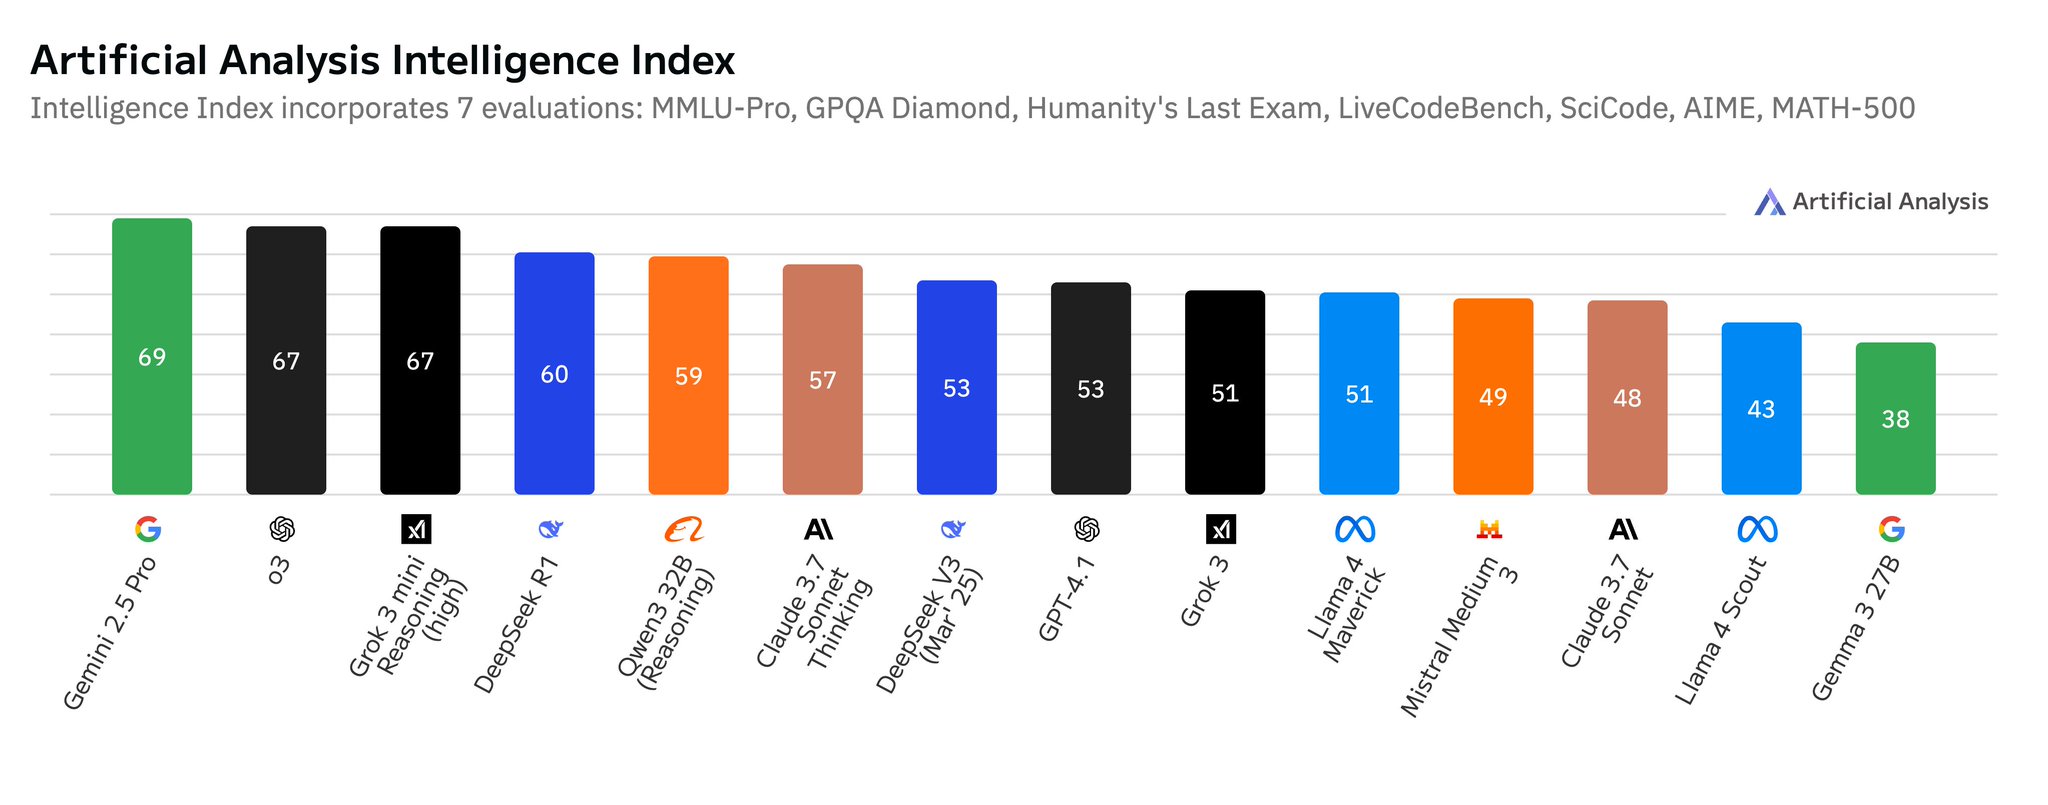
Qwen3-32B Performance Benchmark Against Leading AI Models
By
–
Qwen3-32B vs. leading models eval https://
artificialanalysis.ai/?models=gpt-4-
1o3llama-4-scoutllama-4-maverickgemma-3-27bgemini-2-5-proclaude-3-7-sonnet-thinkingclaude-3-7-sonnetmistral-medium-3deepseek-r1deepseek-v3-0324grok-3grok-3-mini-reasoningqwen3-32b-instruct-reasoning
… -
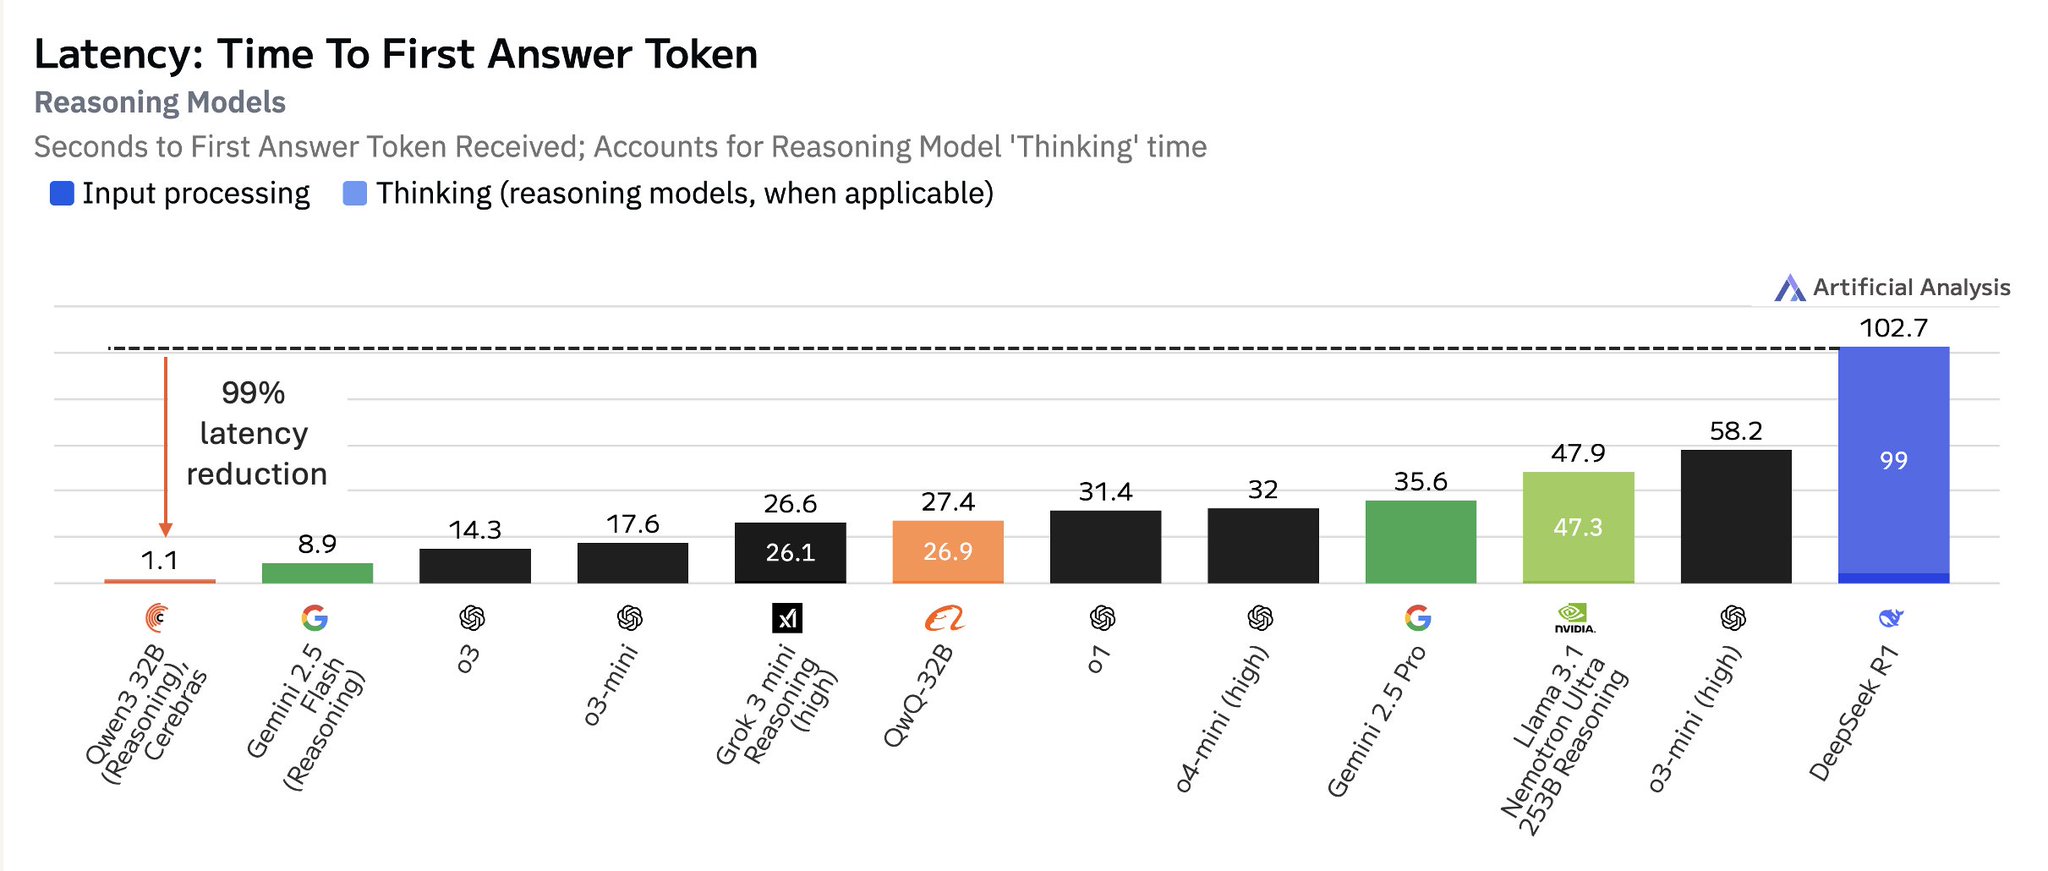
Cerebras Qwen3 achieves 99% latency reduction versus o3
By
–
Artificial Analysis measured the time to first token of every reasoning model from o3 to R1. DeepSeek R1 = 103 sec
Qwen3-32B on Cerebras = 1.1 sec We give you R1 level intelligence with 99% latency reduction. Try it: https://
inference.cerebras.ai -
Compare Qwen, Llama, DeepSeek Models on Cerebras Platform
By
–
Choose a model (
@Alibaba_Qwen 3 32B, @AIatMeta Llama 3.3 70B, Llama 4 Scout, @deepseek_ai R1 Distill Llama 70B) – https://
poe.com/search?q=cereb
ras
… Add a prompt template Connect your data Chain it with other tools -
Cerebras Delivers Fastest AI Inference on Poe Platform
By
–
Live on @poe_platform – Cerebras, delivering the fastest inference in the world.
— Cerebras (@cerebras) 20 mai 2025
Build a bot, drop the link below, and we’ll share our favorites. pic.twitter.com/Npkmc294ThLive on @poe_platform – Cerebras, delivering the fastest inference in the world.
Build a bot, drop the link below, and we’ll share our favorites. -
Cerebras Cloud Platform Enables AI Building Today
By
–
Don't wait for the future. Build it: http://
cloud.cerebras.ai -
50 Trillion Tokens: LLM Growth and Development Speed Call
By
–
0 to 50,000,000,000,000 tokens in just 3 years. 50T Tokens. That kind of scale isn’t just extraordinary, 𝗶𝘁’𝘀 𝗮 𝗰𝗮𝗹𝗹 𝘁𝗼 𝗯𝘂𝗶𝗹𝗱.
— Cerebras (@cerebras) 20 mai 2025
LLM growth is exploding, and speed is the catalyst. pic.twitter.com/XEDog6HOfu0 to 50,000,000,000,000 tokens in just 3 years. 50T Tokens. That kind of scale isn’t just extraordinary, 𝗶𝘁’𝘀 𝗮 𝗰𝗮𝗹𝗹 𝘁𝗼 𝗯𝘂𝗶𝗹𝗱. LLM growth is exploding, and speed is the catalyst.