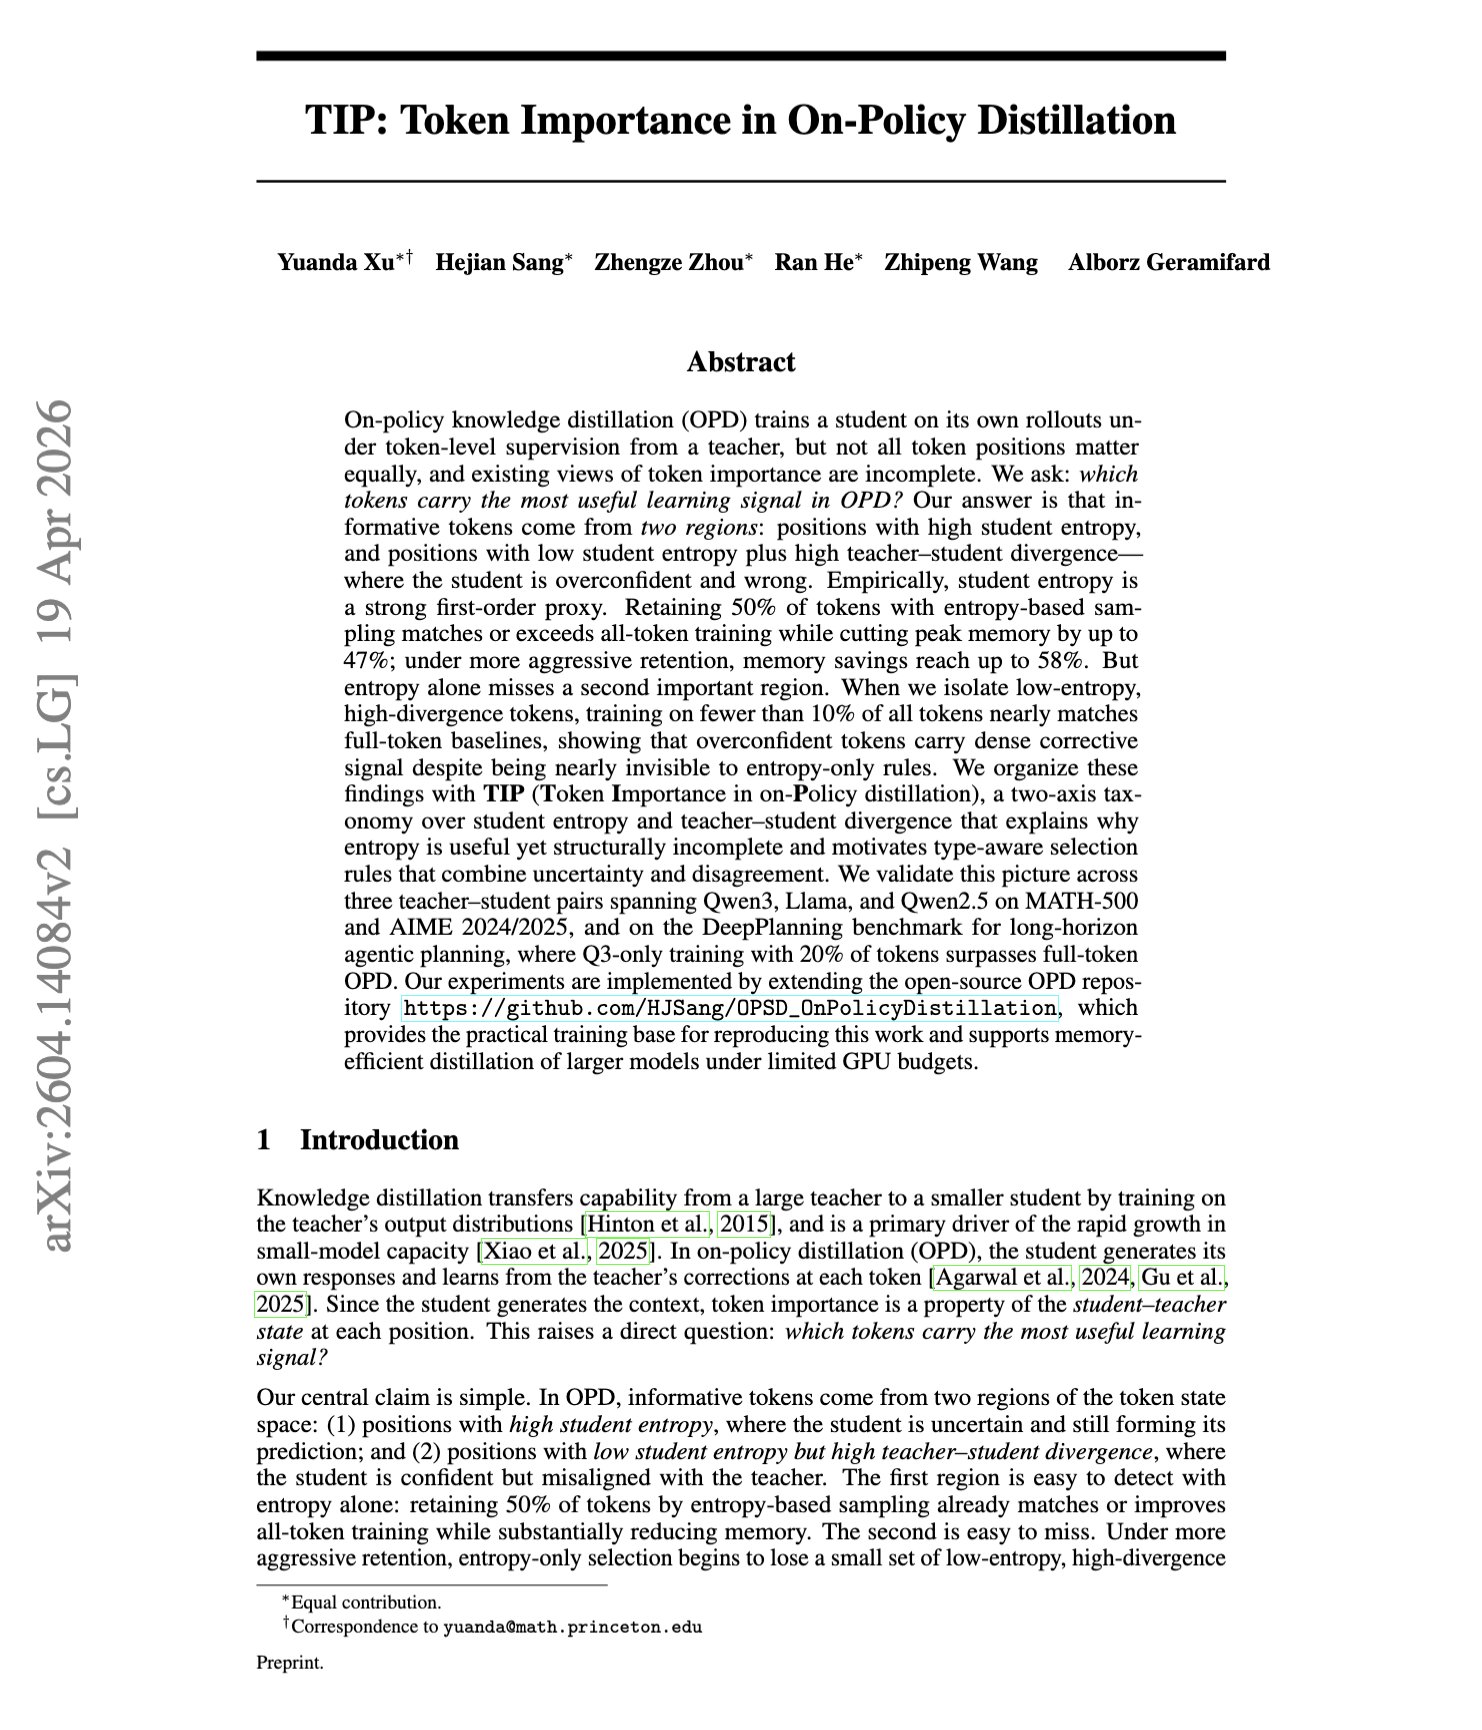
"TIP: Token Importance in On-Policy Distillation" This paper introduces selective token training for on-policy distillation, relying on student entropy to find high-signal tokens. A key point is that entropy misses confident mistakes, so they add teacher-student divergence to
@askalphaxiv
-
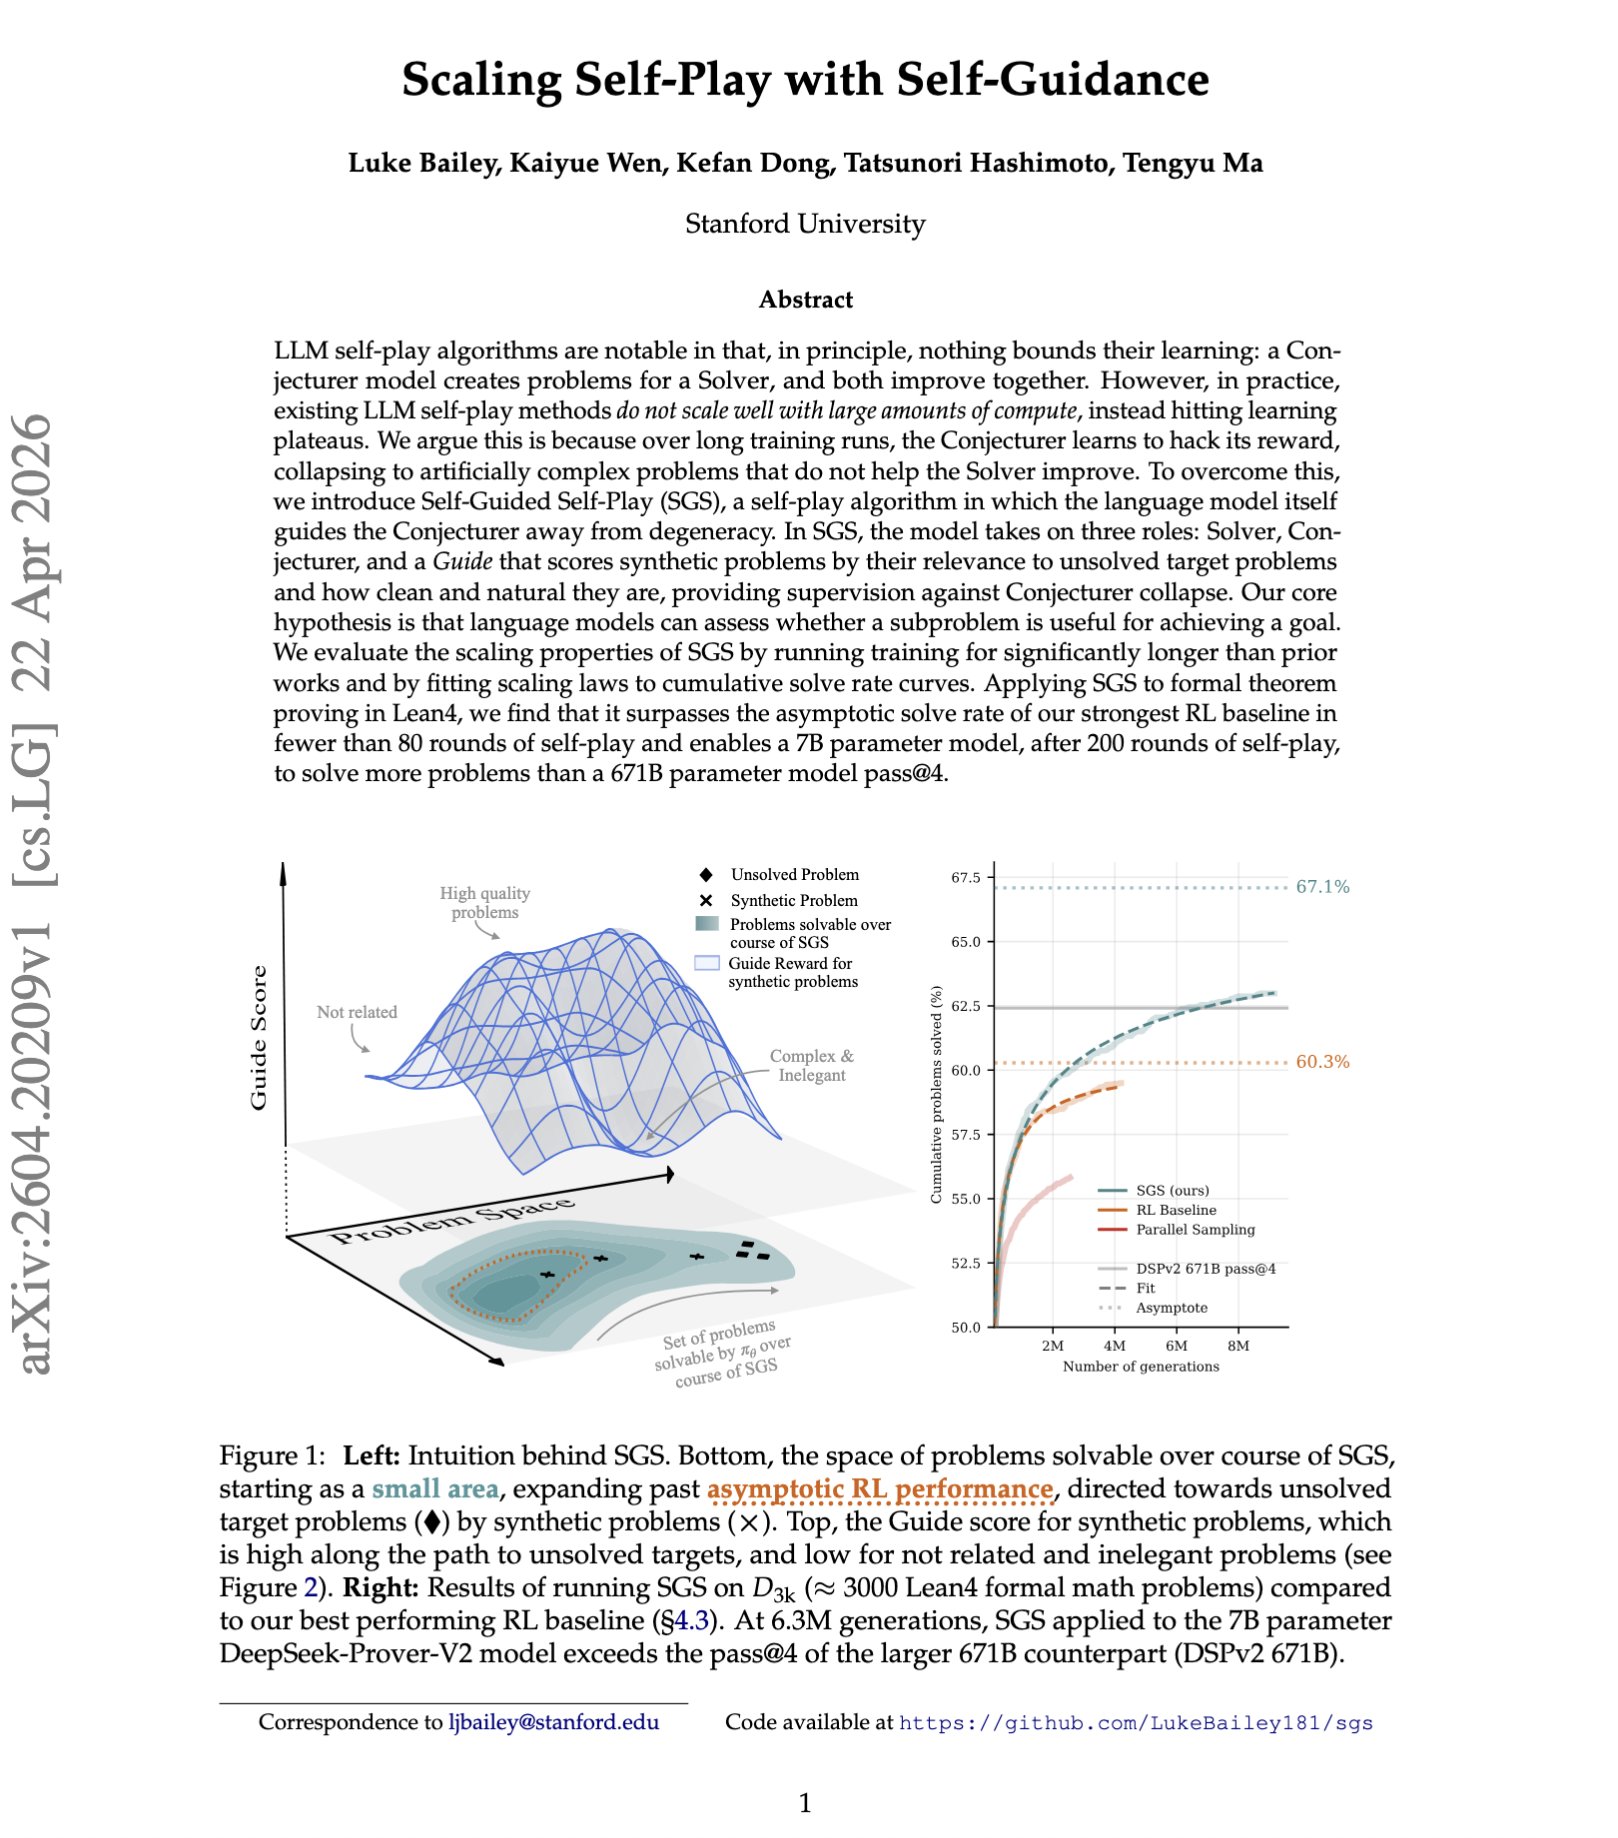
Scaling Self-Play with Self-Guidance for Theorem Proving
By
–
"Scaling Self-Play with Self-Guidance" The main problem with self-play for theorem proving is that generator usually learns to reward hack, which produces messy hard problems that do not help the solver. This paper suggests by adding a Guide model that scores generated
-
DeepSeek V4 Paper Release Announcement
By
–
Check out the full paper here! https://
alphaxiv.org/abs/deepseek-v4 -
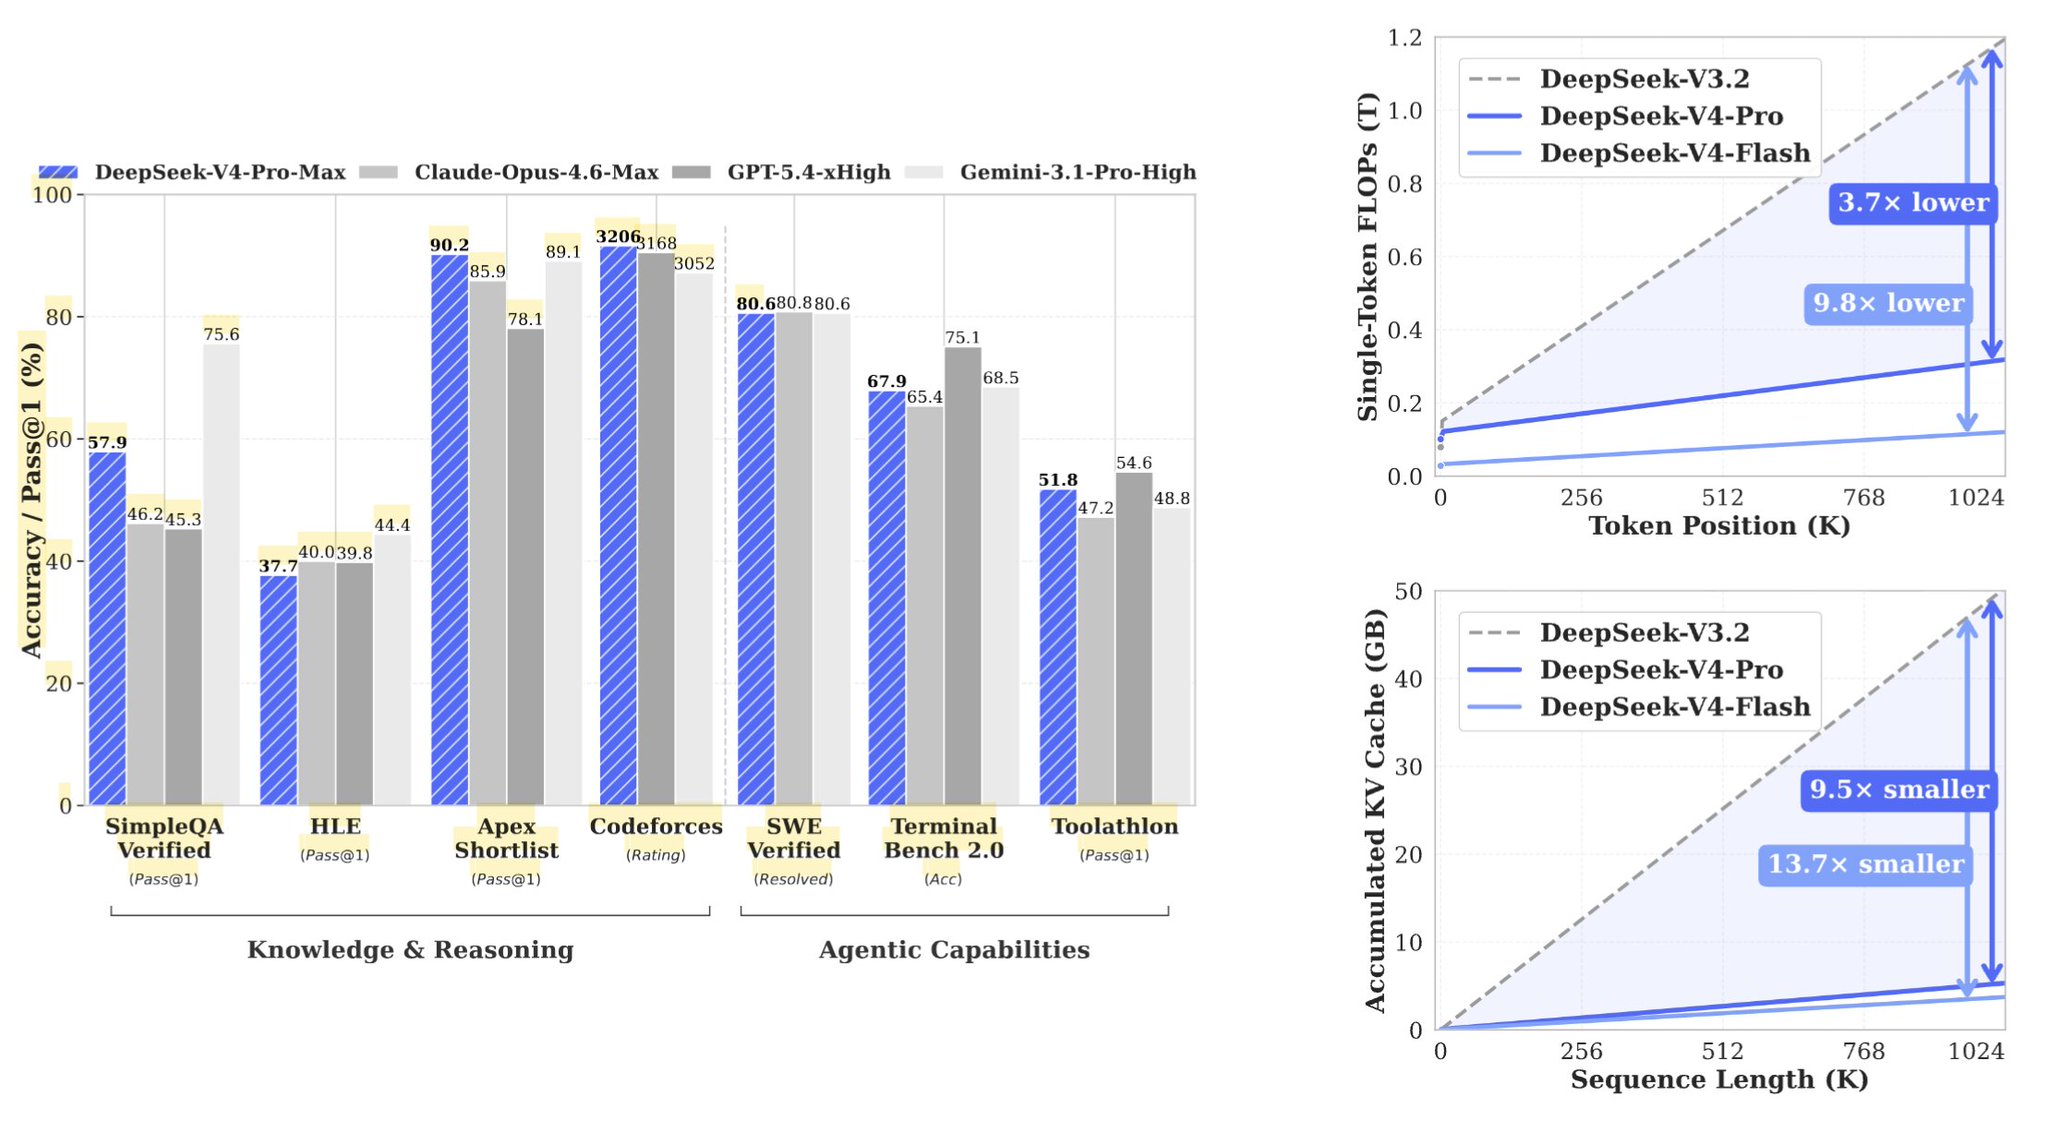
DeepSeek-V4 Introduces Advanced Attention Techniques for Million Token Context
By
–
"DeepSeek-V4 Technical Report" A 58 page paper with brand new attention techniques: Heavily Compressed Attention (HCA) & Compressed Sparse Attention (CSA). This hybrid attention setup enables V4 to hit 1 million context. DeepSeek-V4-Pro is now the largest OS model ever, with
-
alphaXiv LaTeX Assistant: Native Generation and Copying
By
–
Tired of typing LaTeX manually?
— alphaXiv (@askalphaxiv) 23 avril 2026
alphaXiv’s assistant now supports native LaTeX generation, rendering, and copying.
No need to edit entire chatbot responses, as every equation is easily copyable.
Simply ask it to generate equations, then copy and paste them wherever you’re… pic.twitter.com/WWl25TM7MwTired of typing LaTeX manually? alphaXiv’s assistant now supports native LaTeX generation, rendering, and copying. No need to edit entire chatbot responses, as every equation is easily copyable. Simply ask it to generate equations, then copy and paste them wherever you’re
-
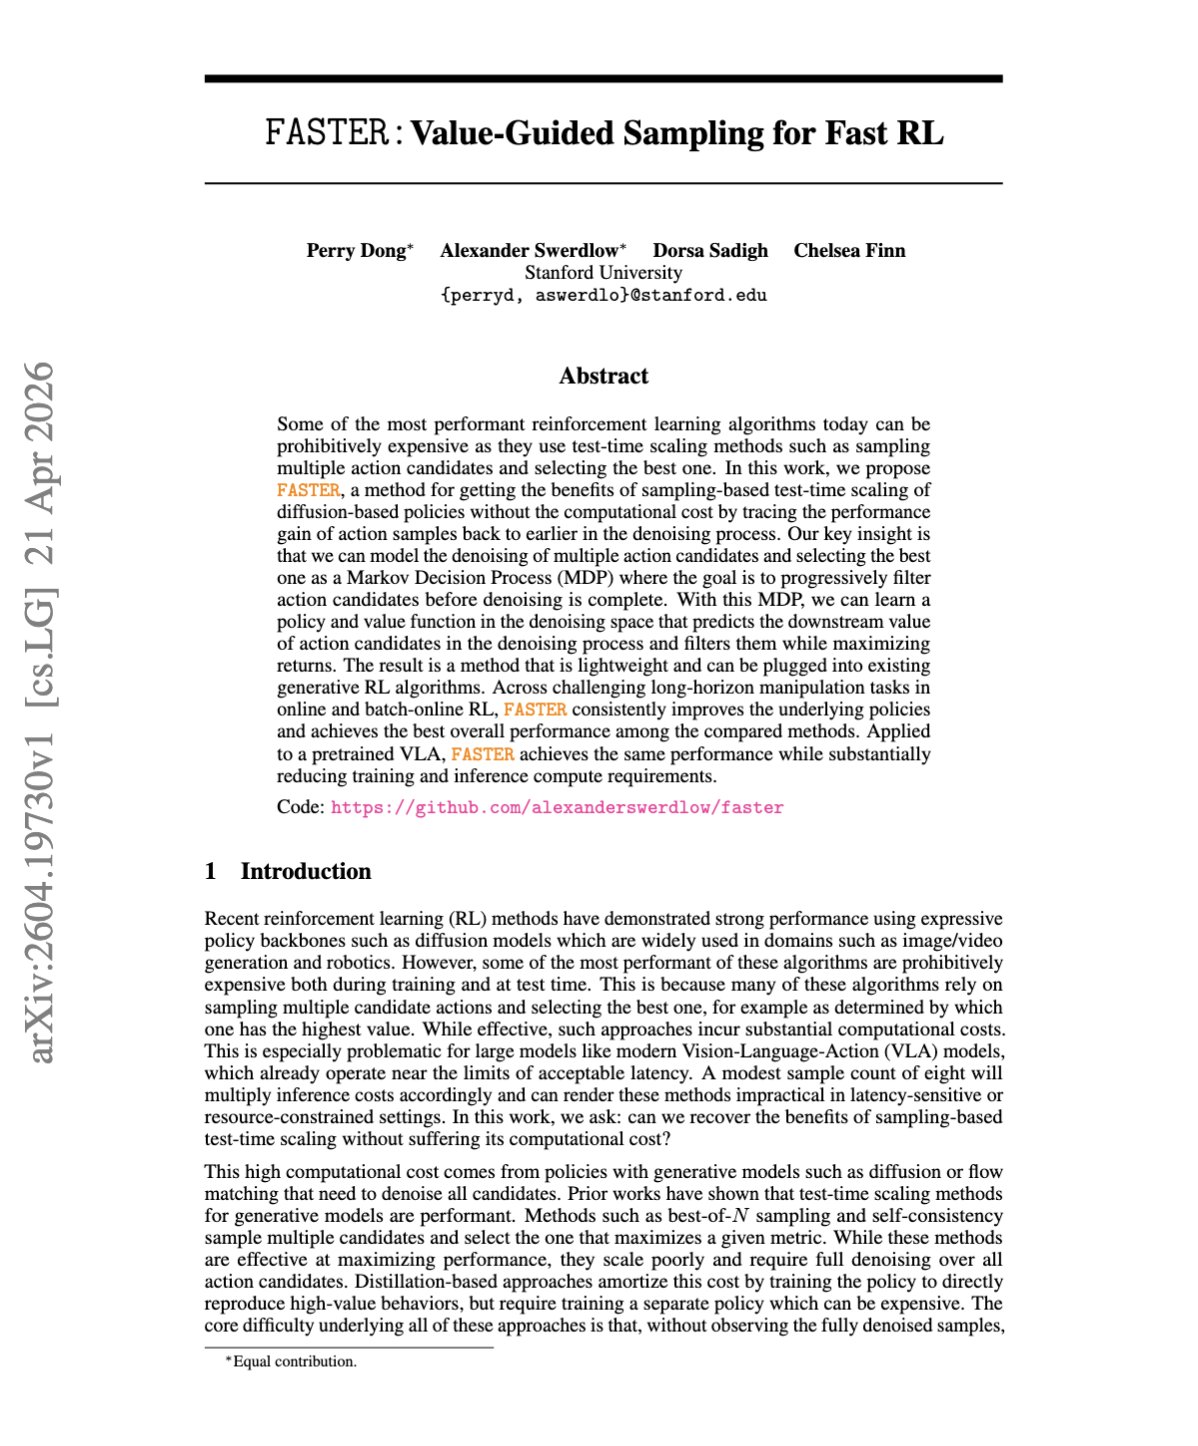
FASTER: Value-Guided Sampling Improves Reinforcement Learning Efficiency
By
–
"FASTER: Value-Guided Sampling for Fast RL" Instead of fully denoising many action candidates and picking the best one at the end, it learns a critic over the noise seed and selects the promising sample upfront. They showed that the advantage of best-of-N is already visible
-
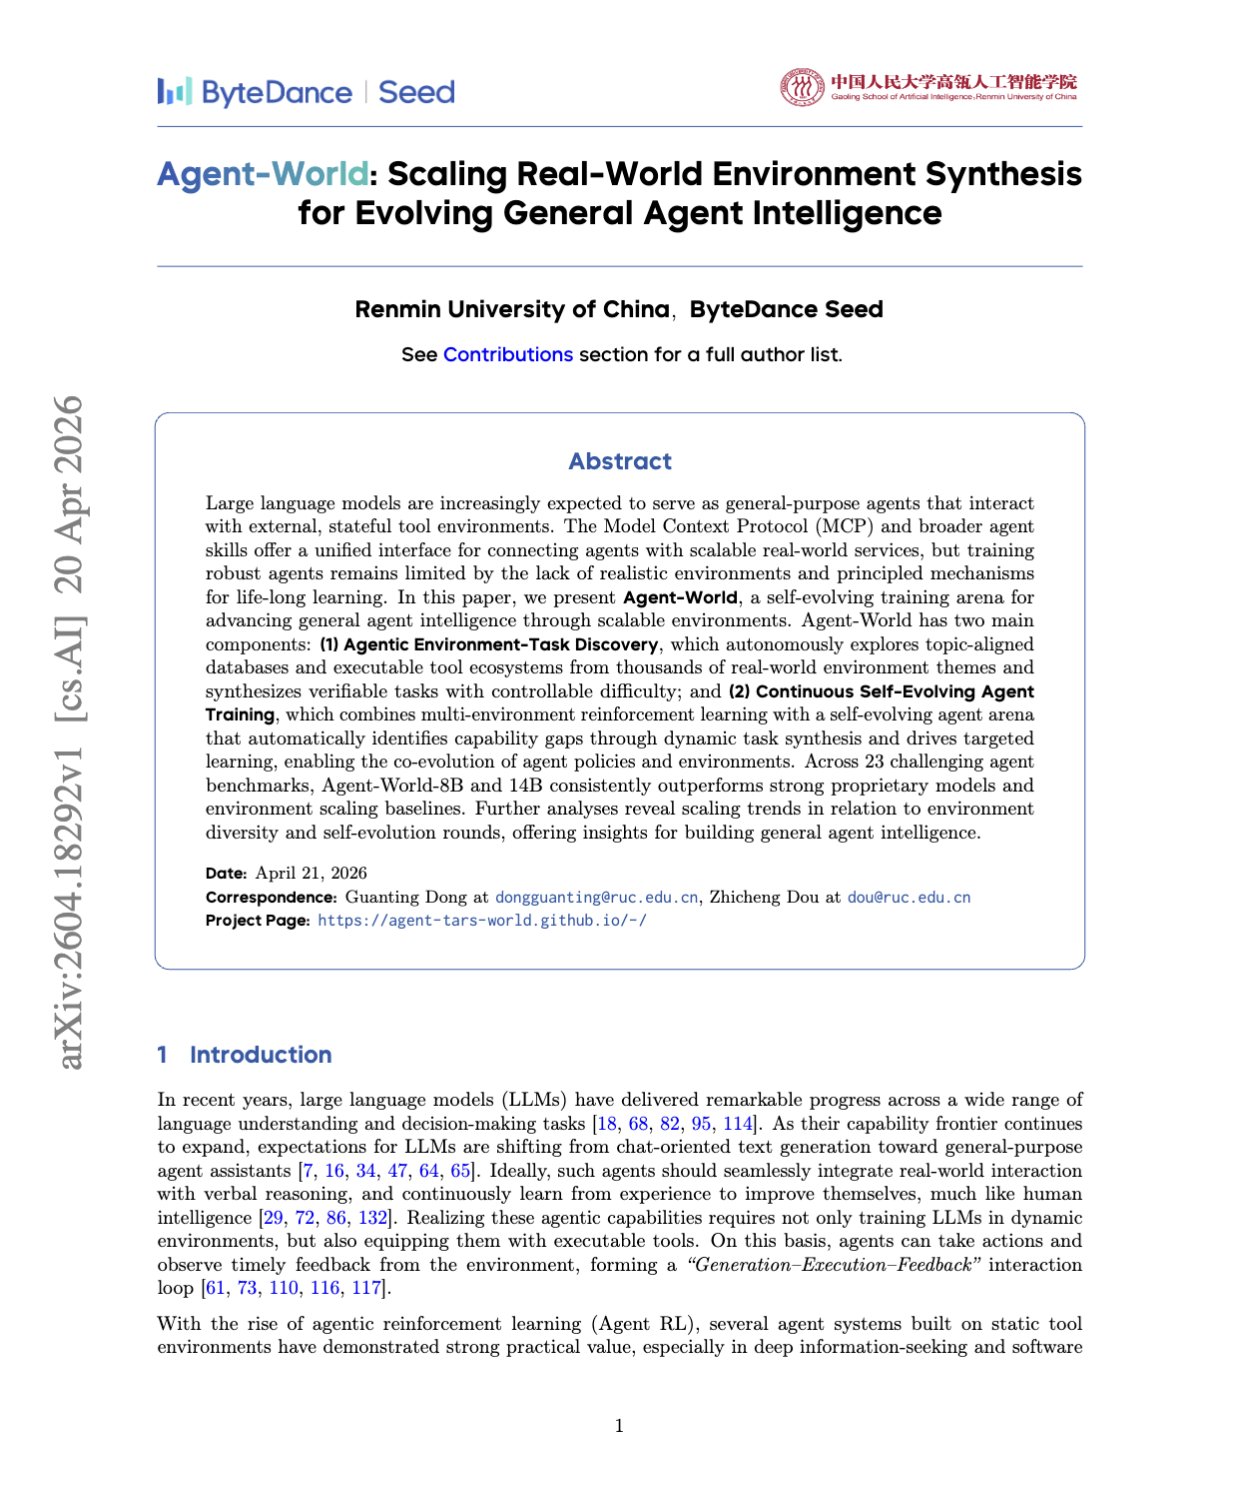
Scaling Agent RL with Real-World Environment Synthesis
By
–
"Agent-World: Scaling Real-World Environment Synthesis for Evolving General Agent Intelligence" This paper scales agent RL with actual stateful tool environments instead of toy simulators. A key component is that the environment set is not frozen but continuously expanded
-
First Notebook Competition with marimo to Implement AI Papers
By
–
Looking for a weekend project that is both challenging and rewarding? Enter our first notebook competition with @marimo_io to implement AI papers. You also got 5 days left if you want to win a Mac Mini + over $1K in prizes! Full details found below