“Preconditioned DeltaNet: Curvature-aware Sequence Modeling for Linear Recurrences” This paper views linear recurrences through a least-squares/test-time regression lens, and adds the missing curvature information via preconditioning. Main idea: precondition the delta-rule
@askalphaxiv
-
SWE-chat: Real-World Coding Agent Interactions Dataset
By
–
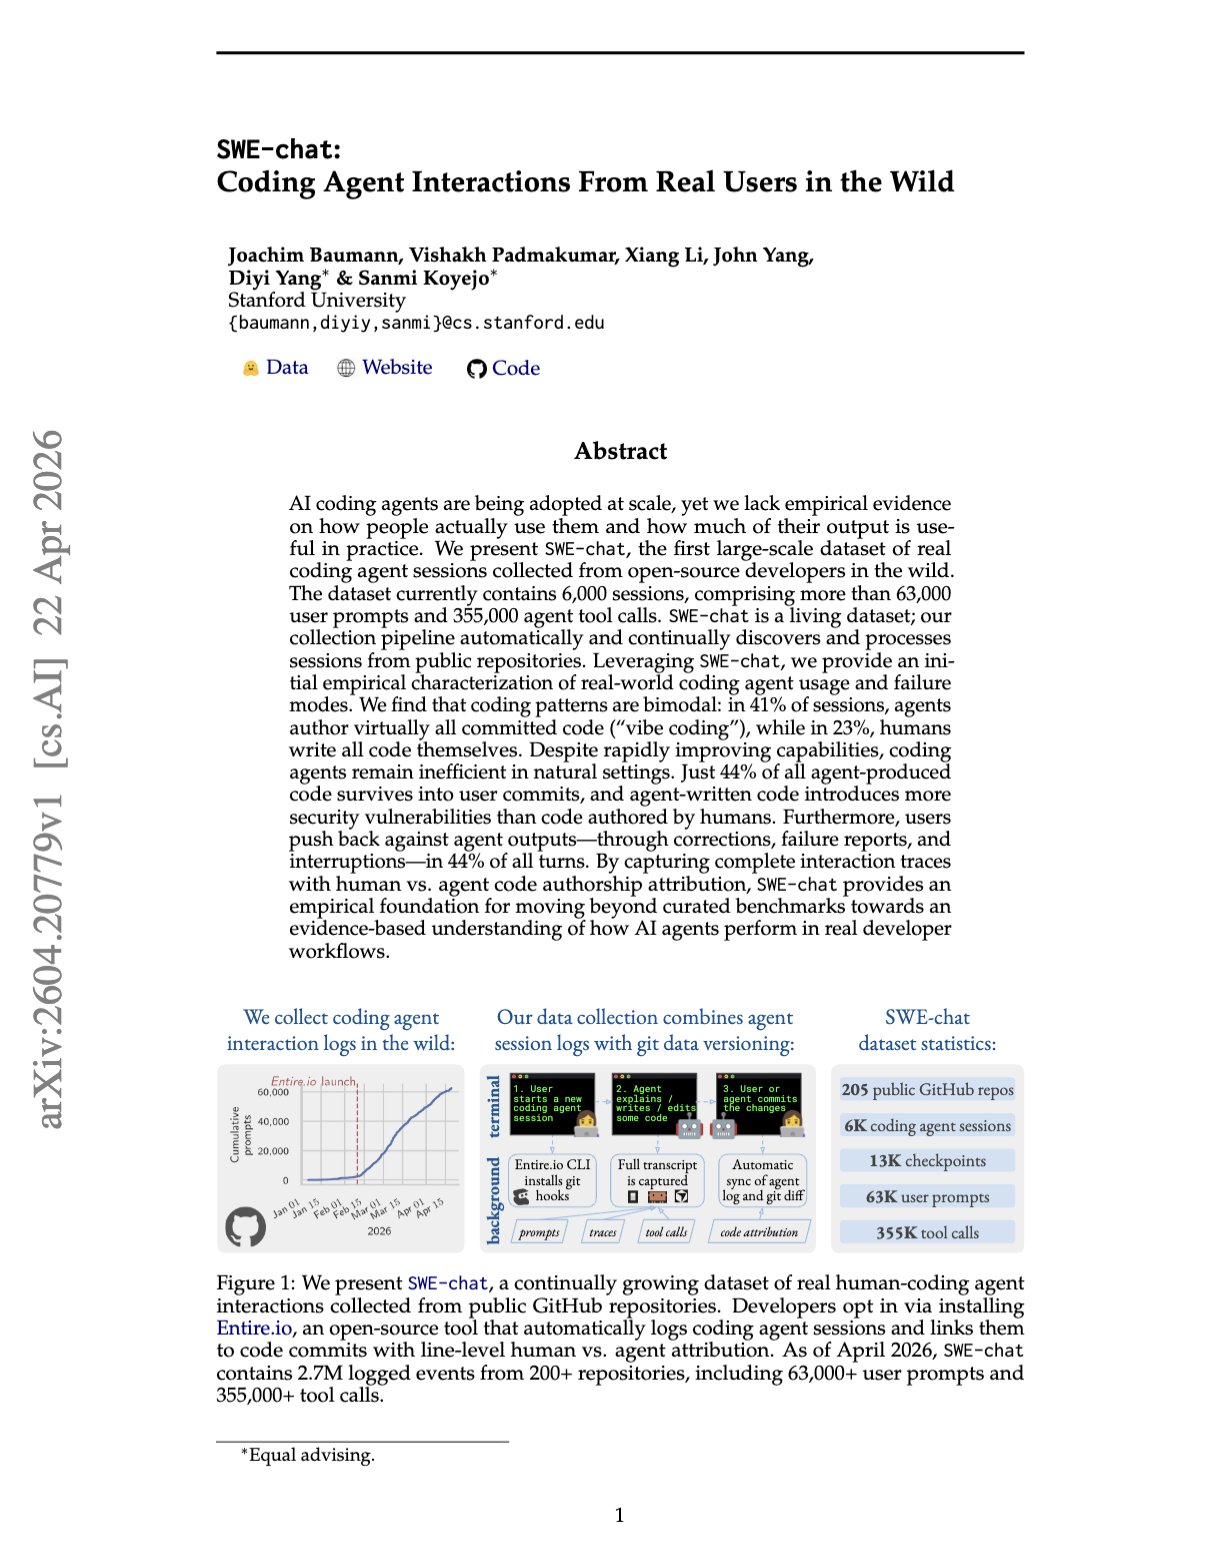
"SWE-chat: Coding Agent Interactions From Real Users in the Wild" This paper proposes a real-world coding-agent dataset. It tracks 6K sessions from actual developers, with prompts, tool calls, and line-level human vs. agent authorship. Main result is that agent autonomy is
-
Kwai Summary Attention: Learnable Tokens for Long Context
By
–
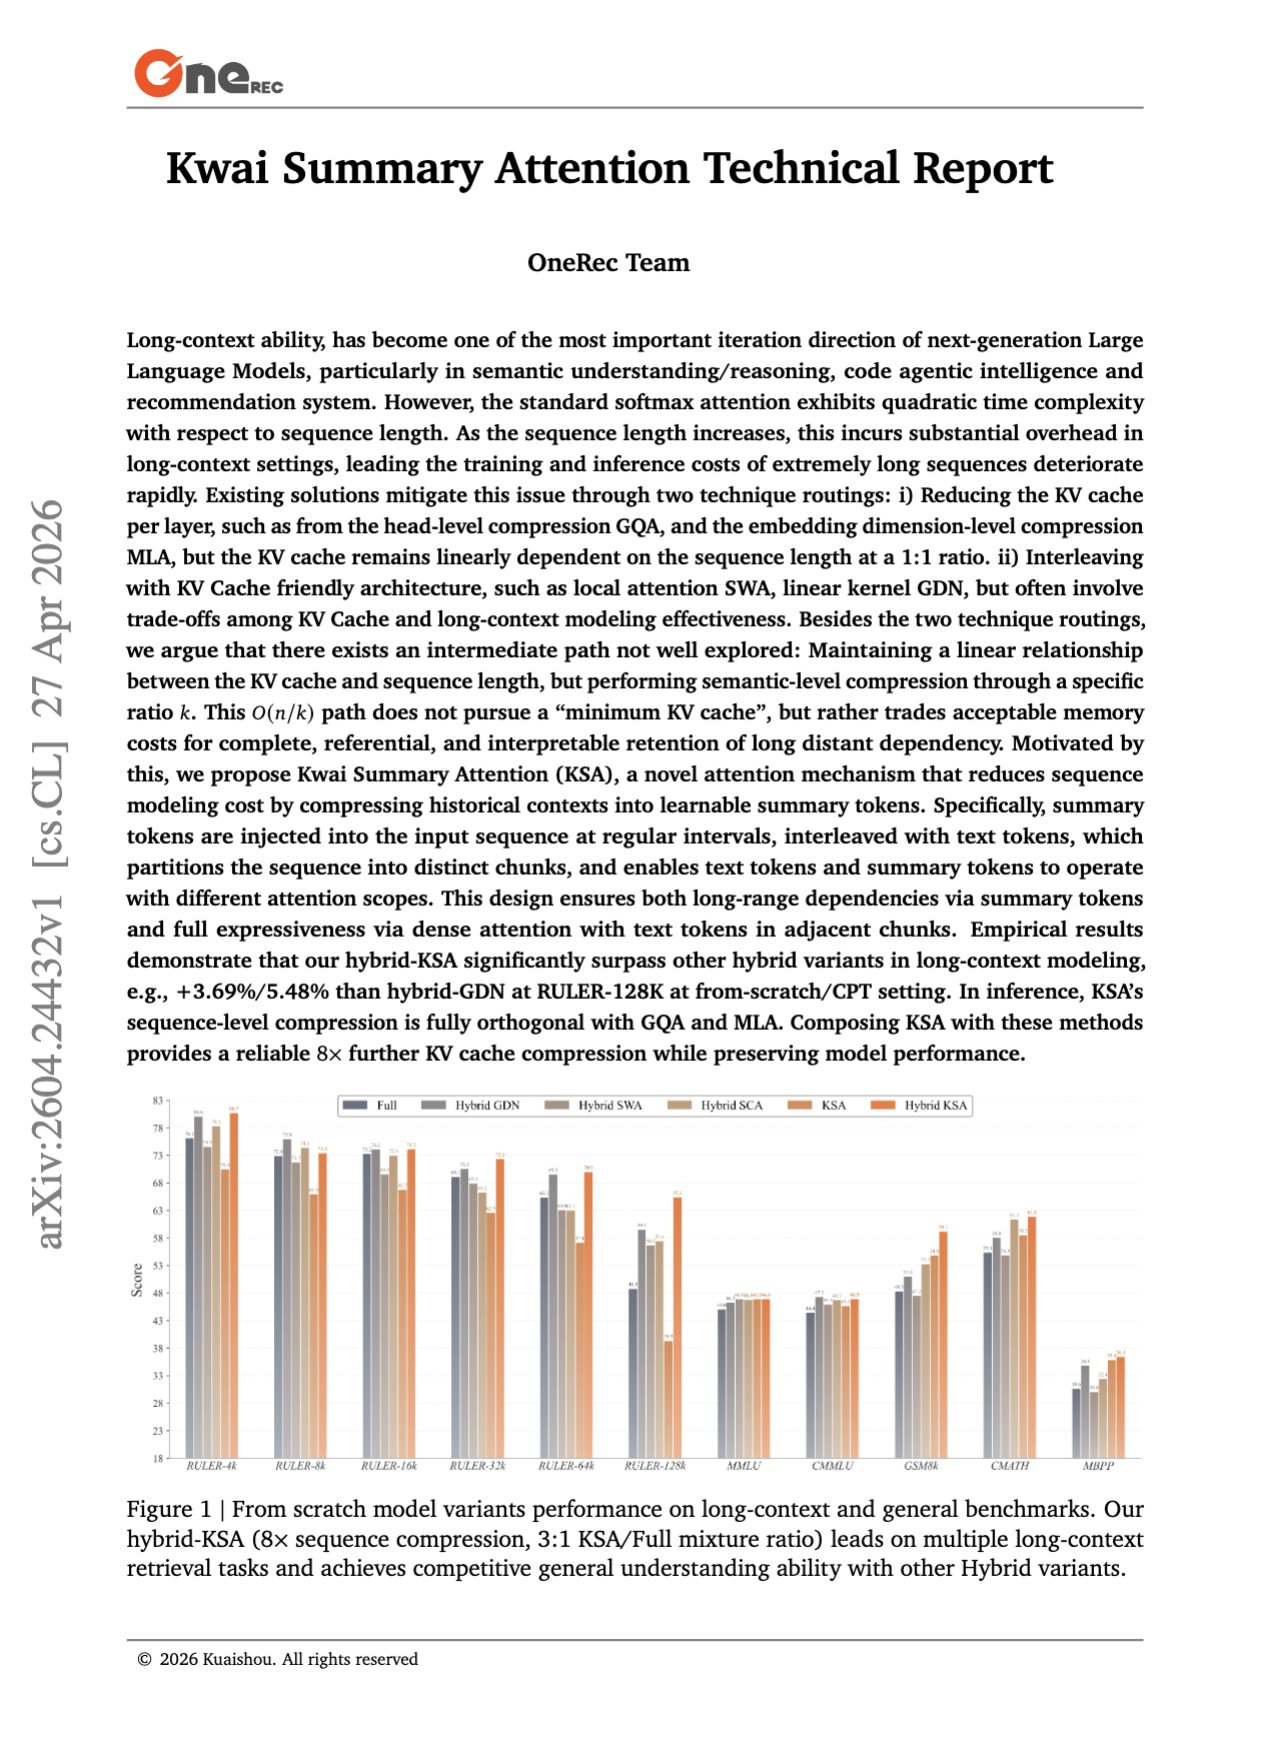
"Kwai Summary Attention Technical Report" This paper uses learnable summary tokens for long-context attention. It splits text into chunks, compresses each chunk into a summary token, keeps recent text dense within a sliding local window, and reads distant context through
-

Recurrent Transformer: Greater Effective Depth and Efficient Decoding
By
–
“The Recurrent Transformer: Greater Effective Depth and Efficient Decoding” Transformers are great at parallel processing, but they’re shallow through time, as each layer only lets tokens interact once. This paper changes that by storing keys/values from each layer’s output,
-
Hackathon Success: 140 Participants Implement AI Papers
By
–
Our first-ever hackathon with @marimo_io to implement papers just ended! With over 140 participants and their amazing submissions, we’re excited to announce the winners in an in-person event in SF, and live demos will be presented by both our team and Marimo. A livestream will
-
Abstract Chain-of-Thought: Efficient Latent Reasoning Without Words
By
–
"Thinking Without Words: Efficient Latent Reasoning with Abstract Chain-of-Thought" Do reasoning models really need to think in words? This paper replaces long verbal CoT with a short learned sequence of abstract tokens that acts like a latent scratchpad. Warmed up from
-
Scientific Theory of Deep Learning Emerges
By
–
“There Will Be a Scientific Theory of Deep Learning” This paper argues that a real scientific theory of deep learning is beginning to emerge. Not a theory that tracks every neuron individually, but a physics-like theory of learning itself. One that aims to characterize how
-

Image Generators as Vision Foundation Models Through Instruction Tuning
By
–
"Image Generators are Generalist Vision Learners" This paper argues that image generation training acts like vision pretraining. They use light instruction-tuning to turn a pretrained image generator into a generalist vision model. With the key idea being representing vision
-
Hyperloop Transformers: Memory-Efficient LLM via Looped Architecture
By
–
"Hyperloop Transformers" This paper propose a memory-efficient LLM via looped Transformers. They basically reuse the middle block across depth, then add hyper-connections only between loops. Key result is that this restores flexibility lost from weight sharing, letting the
-
Discover the Scientific Article alphaXiv 2604.14084
By
–
read more: https://alphaxiv.org/abs/2604.14084