
Karpathy's X thread about LLM failures is now a config file fixing Claude Code. Claude Code has a well-known problem. It over-explains, adds code you didn't ask for, and forgets your constraints mid-conversation. Andrej Karpathy studied these failures closely. He found
@alphasignalai
-
Math Trick Cuts AI Memory Usage 10x in LLMs
By
–
A math trick just cut AI memory usage by 10x without losing accuracy.
— AlphaSignal AI (@AlphaSignalAI) 14 avril 2026
Large language models that "think longer" hit a wall.
The more tokens they generate, the more memory their key-value cache eats.
Most compression methods decide what to keep based on recent attention… pic.twitter.com/XpPuRbKzALA math trick just cut AI memory usage by 10x without losing accuracy. Large language models that "think longer" hit a wall. The more tokens they generate, the more memory their key-value cache eats. Most compression methods decide what to keep based on recent attention
-
Smart AI better detects nonsense
By
–
The smarter your AI reasons, the harder it falls for BS.
— AlphaSignal AI (@AlphaSignalAI) 14 avril 2026
Most AI models will confidently answer a completely nonsensical question.
A new open-source benchmark measures exactly that.
BullshitBench v2 tests 70+ model variants across 100 carefully crafted nonsense prompts.… pic.twitter.com/jp1w7Q2iCFThe smarter your AI gets at reasoning, the better it detects BS. Most AI models confidently answer completely nonsensical questions. A new open-source benchmark measures this precisely. BullshitBench v2 tests 70+ model variants across 100 carefully crafted nonsense prompts.
-

Claude Code Leak Highlights Developers’ Importance
By
–
For months, the tech world has been predicting the end of software engineers. Then the Claude Code leak revealed a very different reality. What emerged from the code wasn’t a model handling everything independently, but a massive scaffolding system designed to ensure reliability, usability, and control.
-

Harvard Study: AI Safety Models Withhold Critical Medical Advice
By
–
Harvard just proved the "safest" AI models cause the most medical harm. AI safety models refuse life-saving medical advice to patients. Then give it freely when you pretend to be a doctor. A new benchmark tested 60 medical emergencies across six major models. Same clinical
-

LLM Wiki Gets Memory System That Weakens and Forgets Facts
By
–
Someone gave Karpathy's viral LLM Wiki a brain that weakens, strengthens, and forgets. Karpathy's LLM Wiki told AI to build a personal knowledge base instead of re-deriving answers every time. It got 5,000 stars in 48 hours. One problem. It treated every fact as equally
-

LLM Training as Lossy Compression via Information Bottleneck Theory
By
–
/5 Learning is Forgetting: LLM Training As Lossy Compression This research proposes that LLMs are best understood as systems of lossy compression, where training functions by retaining only the data relevant to the model's objective. Using Information Bottleneck theory, the
-

TriAttention: Trigonometric KV Cache Compression for Long-Context LLMs
By
–
/4 TriAttention: Trigonometric KV Compression for Efficient Long Reasoning LLMs TriAttention is a novel KV cache compression method designed to optimize long-context reasoning in LLMs by addressing memory bottlenecks. The researchers discovered that pre-RoPE query and key
-

In-Place Test-Time Training Enables Dynamic Adaptation in Deployed LLMs
By
–
/3 In-Place Test-Time Training for Large Language Models Standard LLMs cannot learn new information after deployment. To solve this, researchers built In-Place Test-Time Training (In-Place TTT), a "drop-in" solution that adds dynamic adaptation to existing models without
-
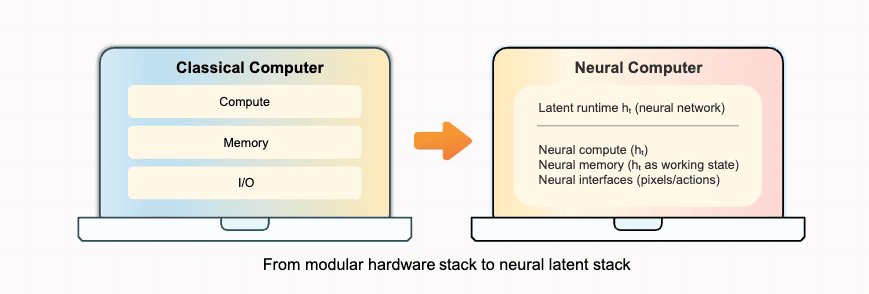
Meta’s Neural Computer Model Runs Computation and Memory Internally
By
–
/2 Meta presents Neural Computer, a model that runs computation, memory, and I/O inside one learned system Meta AI proposes a shift from models that use computers to models that act as computers. Instead of calling APIs or tools, the model executes tasks directly from learned