Exactly! Tool outputs are usually long and stick around in context, so the cache grows fast. Prompt caching helps the prefill side, but decode still has to read all of it on every token. Trimming what goes back into context matters more than people realize.
@akshay_pachaar
-
Naive RAG vs Agentic RAG Visual Comparison Explained
By
–
Naive RAG vs. Agentic RAG, explained visually:
— Akshay 🚀 (@akshay_pachaar) 5 mai 2026
Naive RAG breaks in 3 ways:
↳ It retrieves once and generates once. If the context isn't relevant, the system can't search again.
↳ It treats every query the same. A simple lookup and a multi-hop reasoning task go through the… pic.twitter.com/yJiaYNUPukNaive RAG vs. Agentic RAG, explained visually: Naive RAG breaks in 3 ways: ↳ It retrieves once and generates once. If the context isn't relevant, the system can't search again. ↳ It treats every query the same. A simple lookup and a multi-hop reasoning task go through the
-
Claude Code Cuts Token Usage 3x with Context Engineering Layer
By
–
Claude Code used 3x fewer tokens with one change:
— Akshay 🚀 (@akshay_pachaar) 5 mai 2026
– Before: 10.4M tokens · 10 errors · $9.21
– After: 3.7M tokens · 0 errors · $2.81
I used Insforge Skills + CLI as the backend context engineering layer for Claude Code (open-source and local).
Repo: https://t.co/01v2PYDPpY… https://t.co/HD5Oswup5l pic.twitter.com/T1w1obWBaeClaude Code used 3x fewer tokens with one change: – Before: 10.4M tokens · 10 errors · $9.21
– After: 3.7M tokens · 0 errors · $2.81 I used Insforge Skills + CLI as the backend context engineering layer for Claude Code (open-source and local). Repo: https://
github.com/InsForge/InsFo
rge
… -
When to Use Reinforcement Fine-Tuning vs Supervised Fine-Tuning
By
–
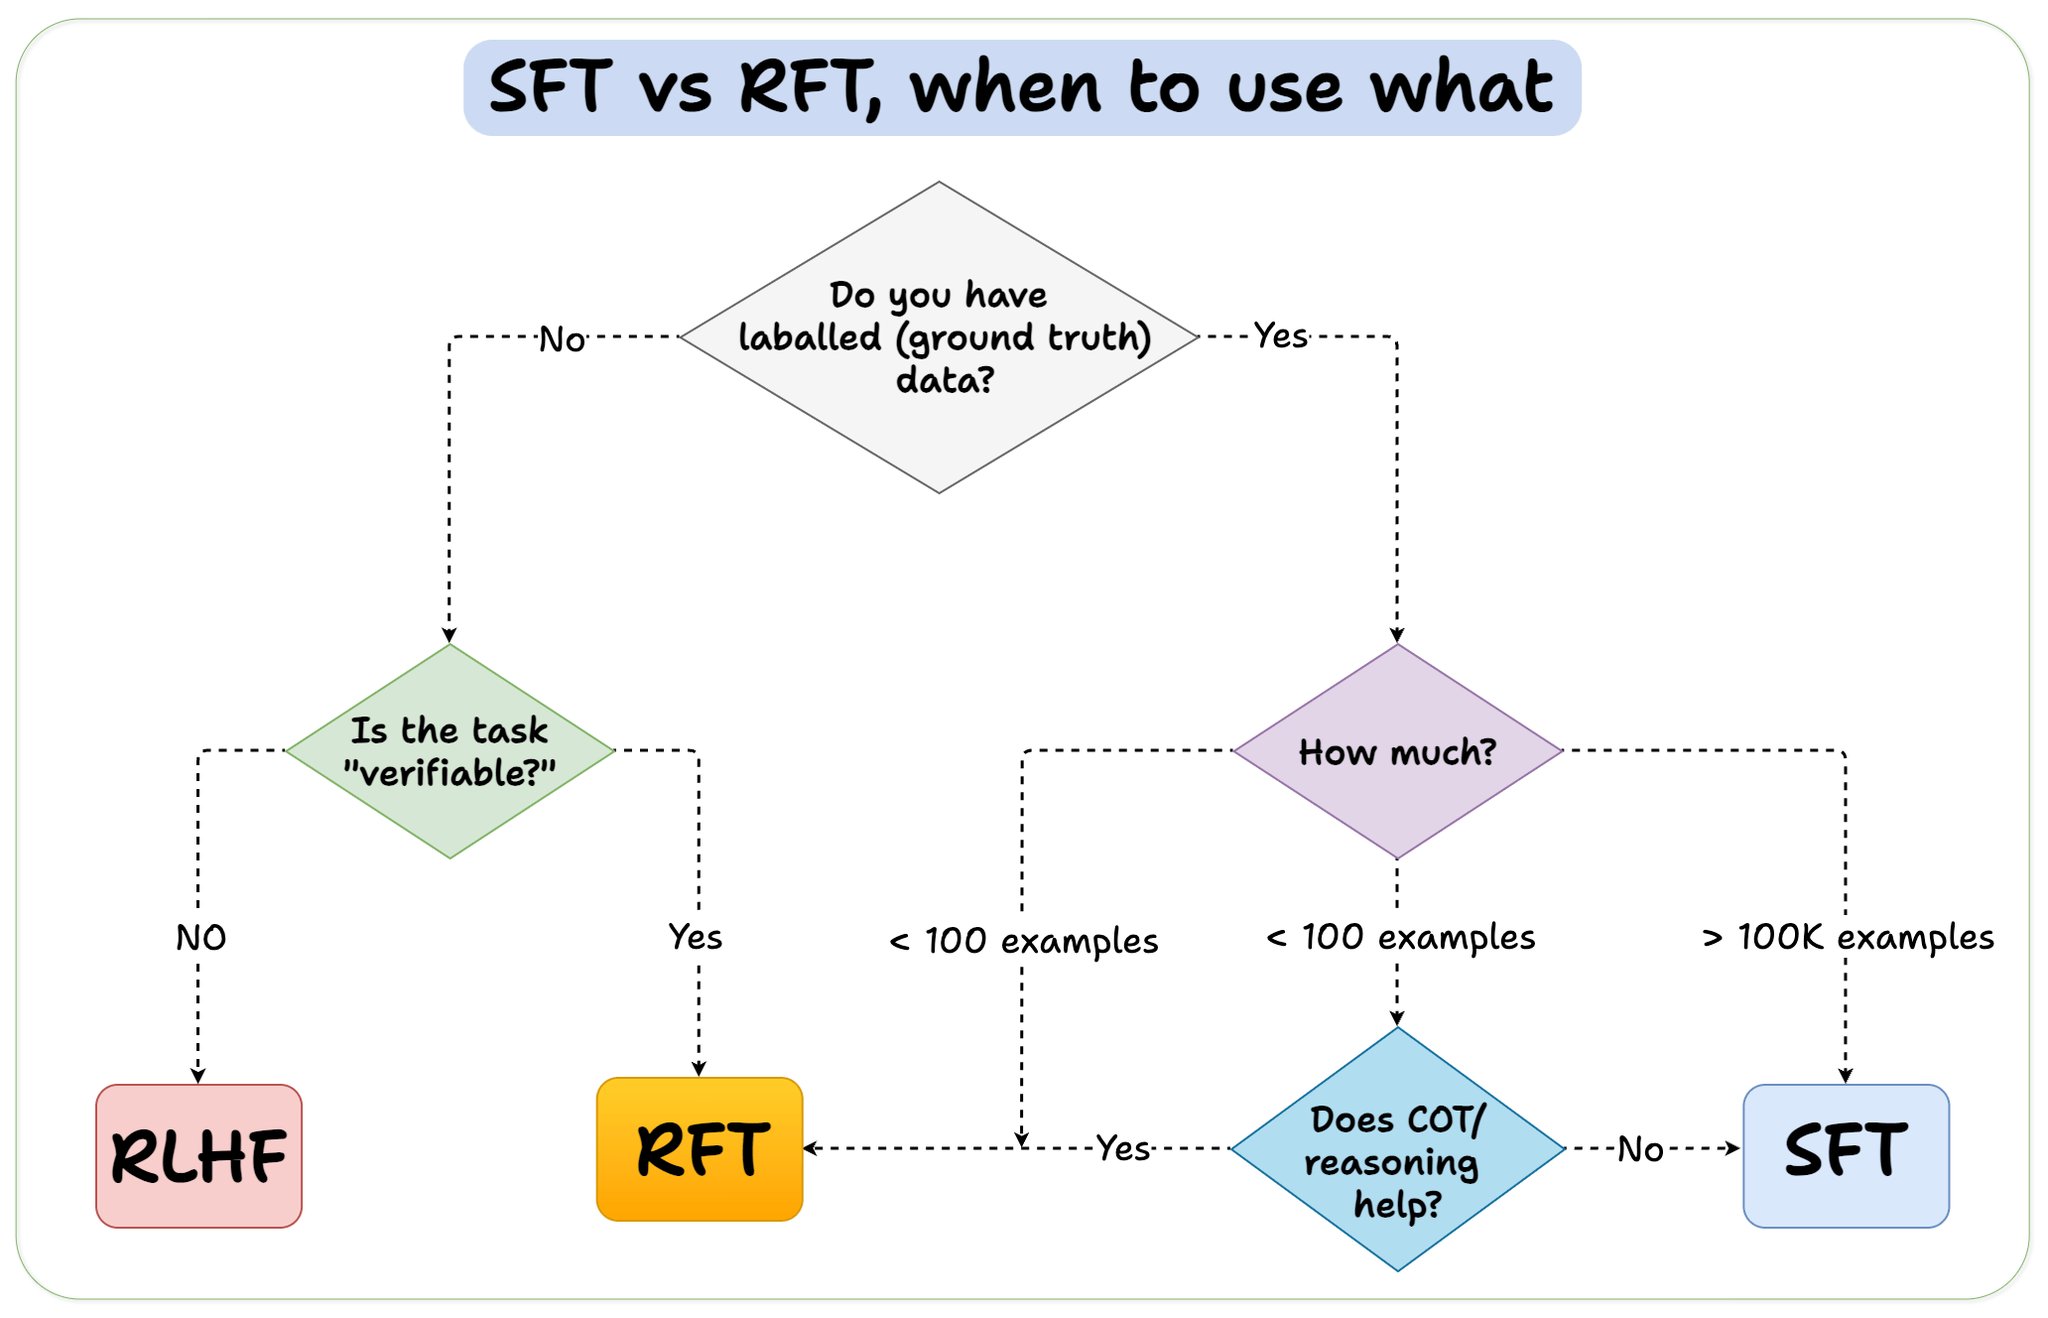
Before we conclude, let me address an important question: When should you use reinforcement fine-tuning (RFT) versus supervised fine-tuning (SFT)? I created this diagram to provide an answer:
-
Using GRPO Training with HuggingFace TRL GRPOTrainer
By
–
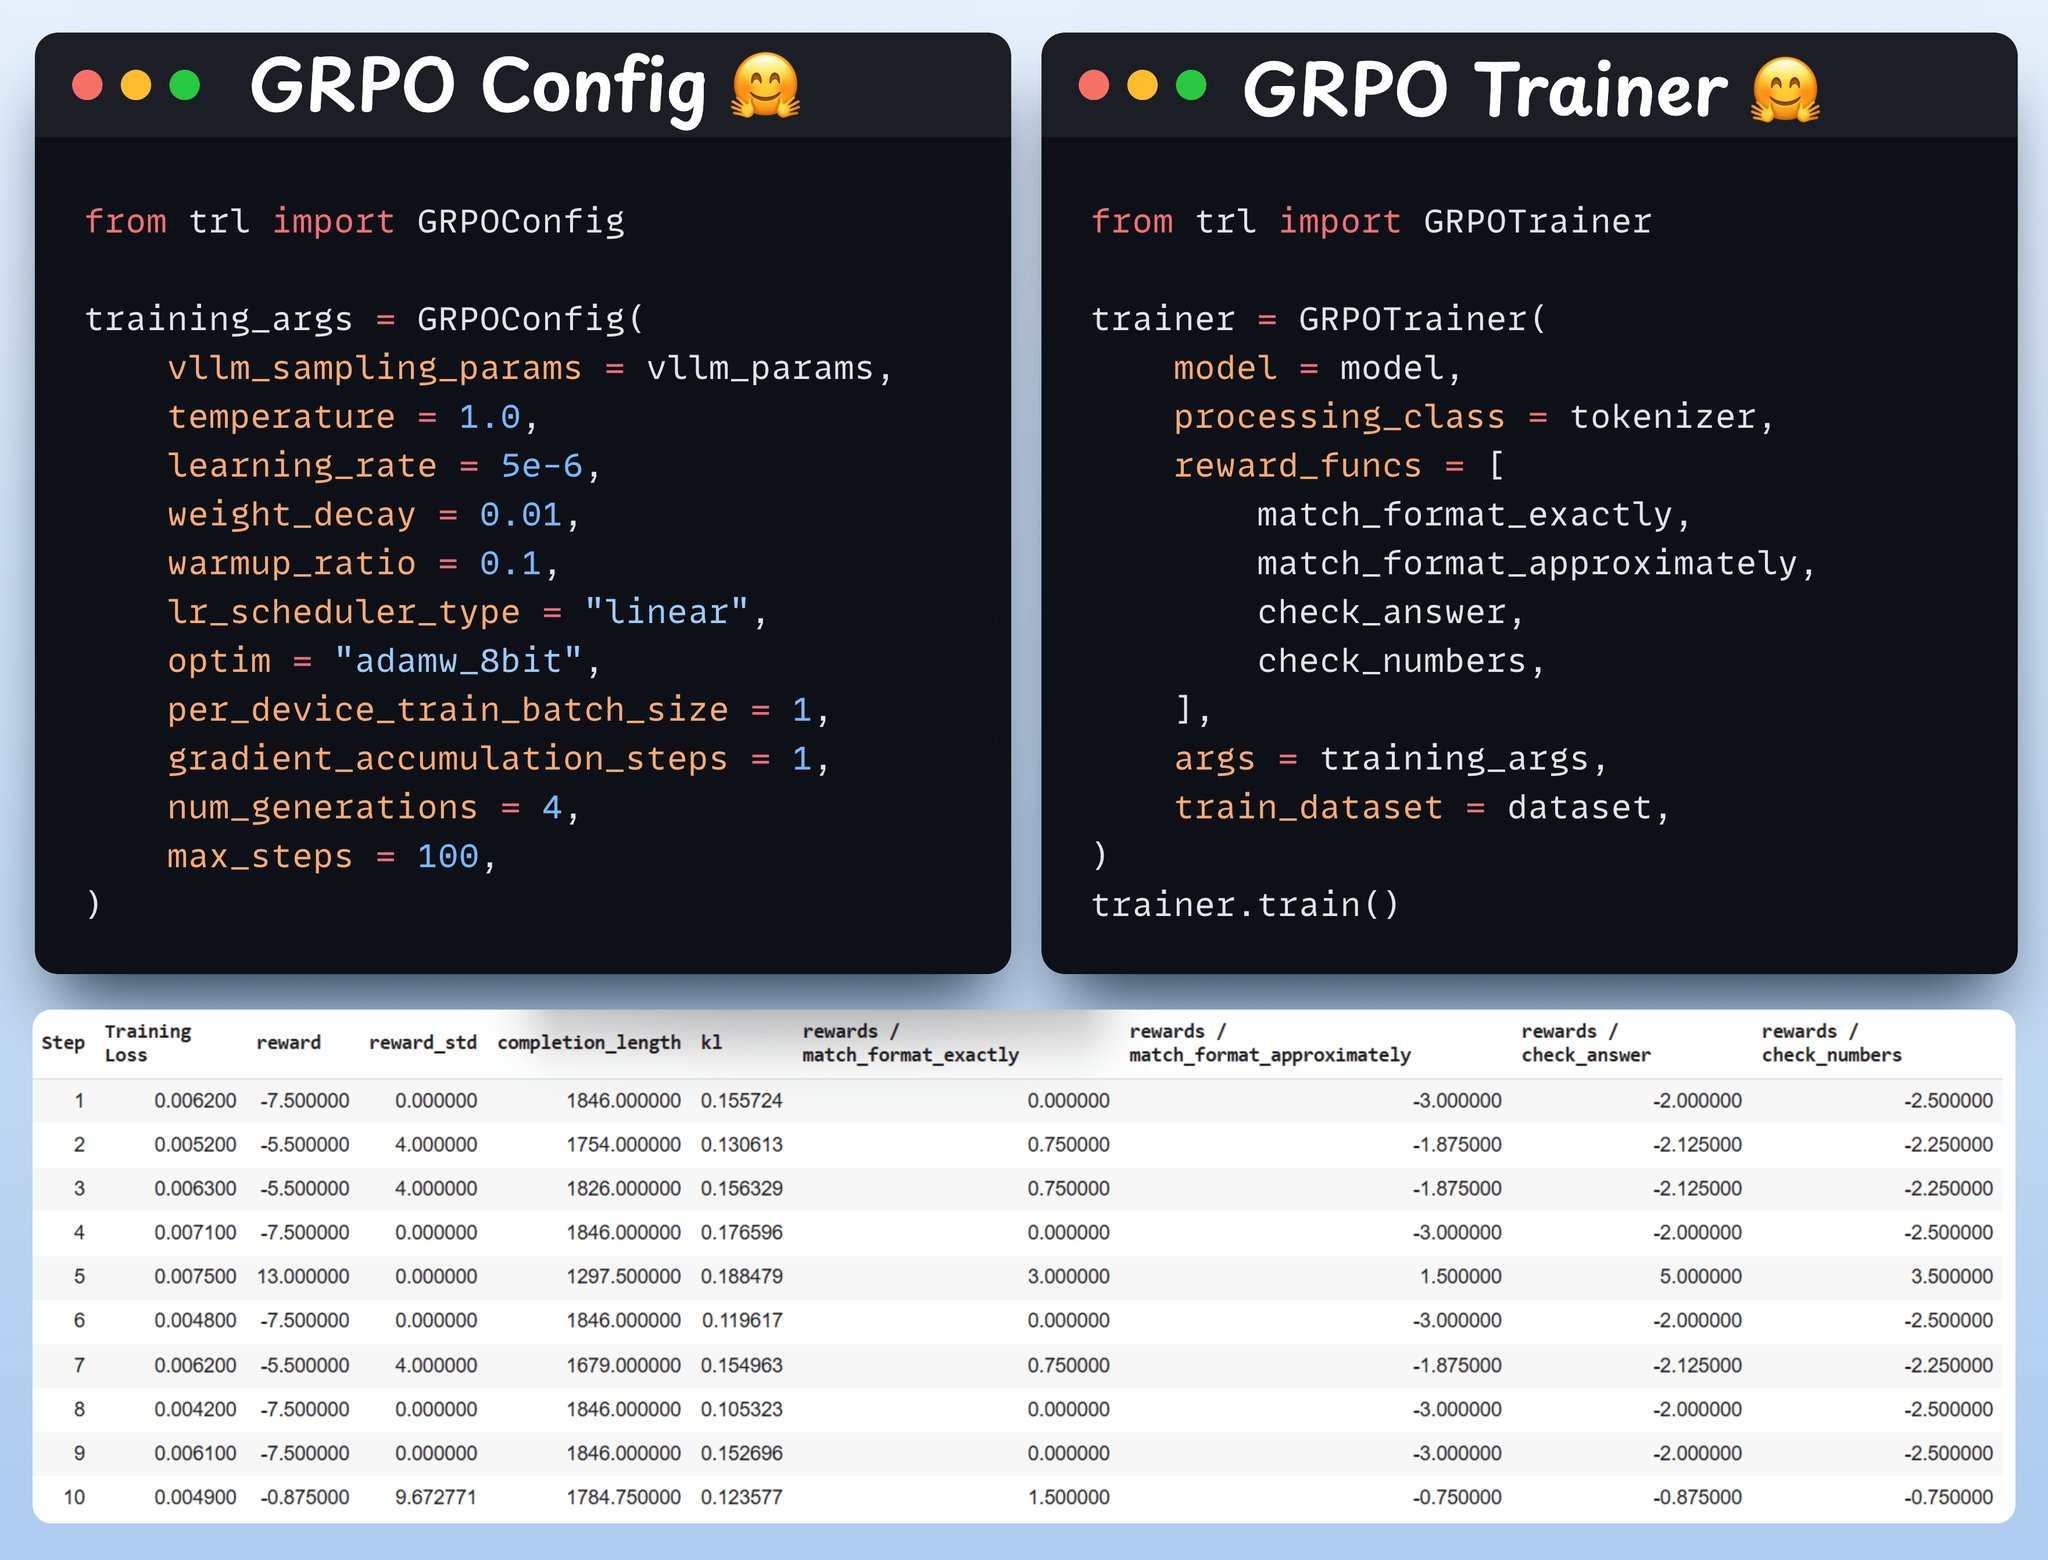
Use GRPO and start training Now that we have the dataset and reward functions ready, it's time to apply GRPO. HuggingFace TRL provides everything we described in the GRPO diagram, out of the box, in the form of the GRPOConfig and GRPOTrainer. Check this out
-
GRPO Reward Functions: Format Matching and Answer Validation
By
–
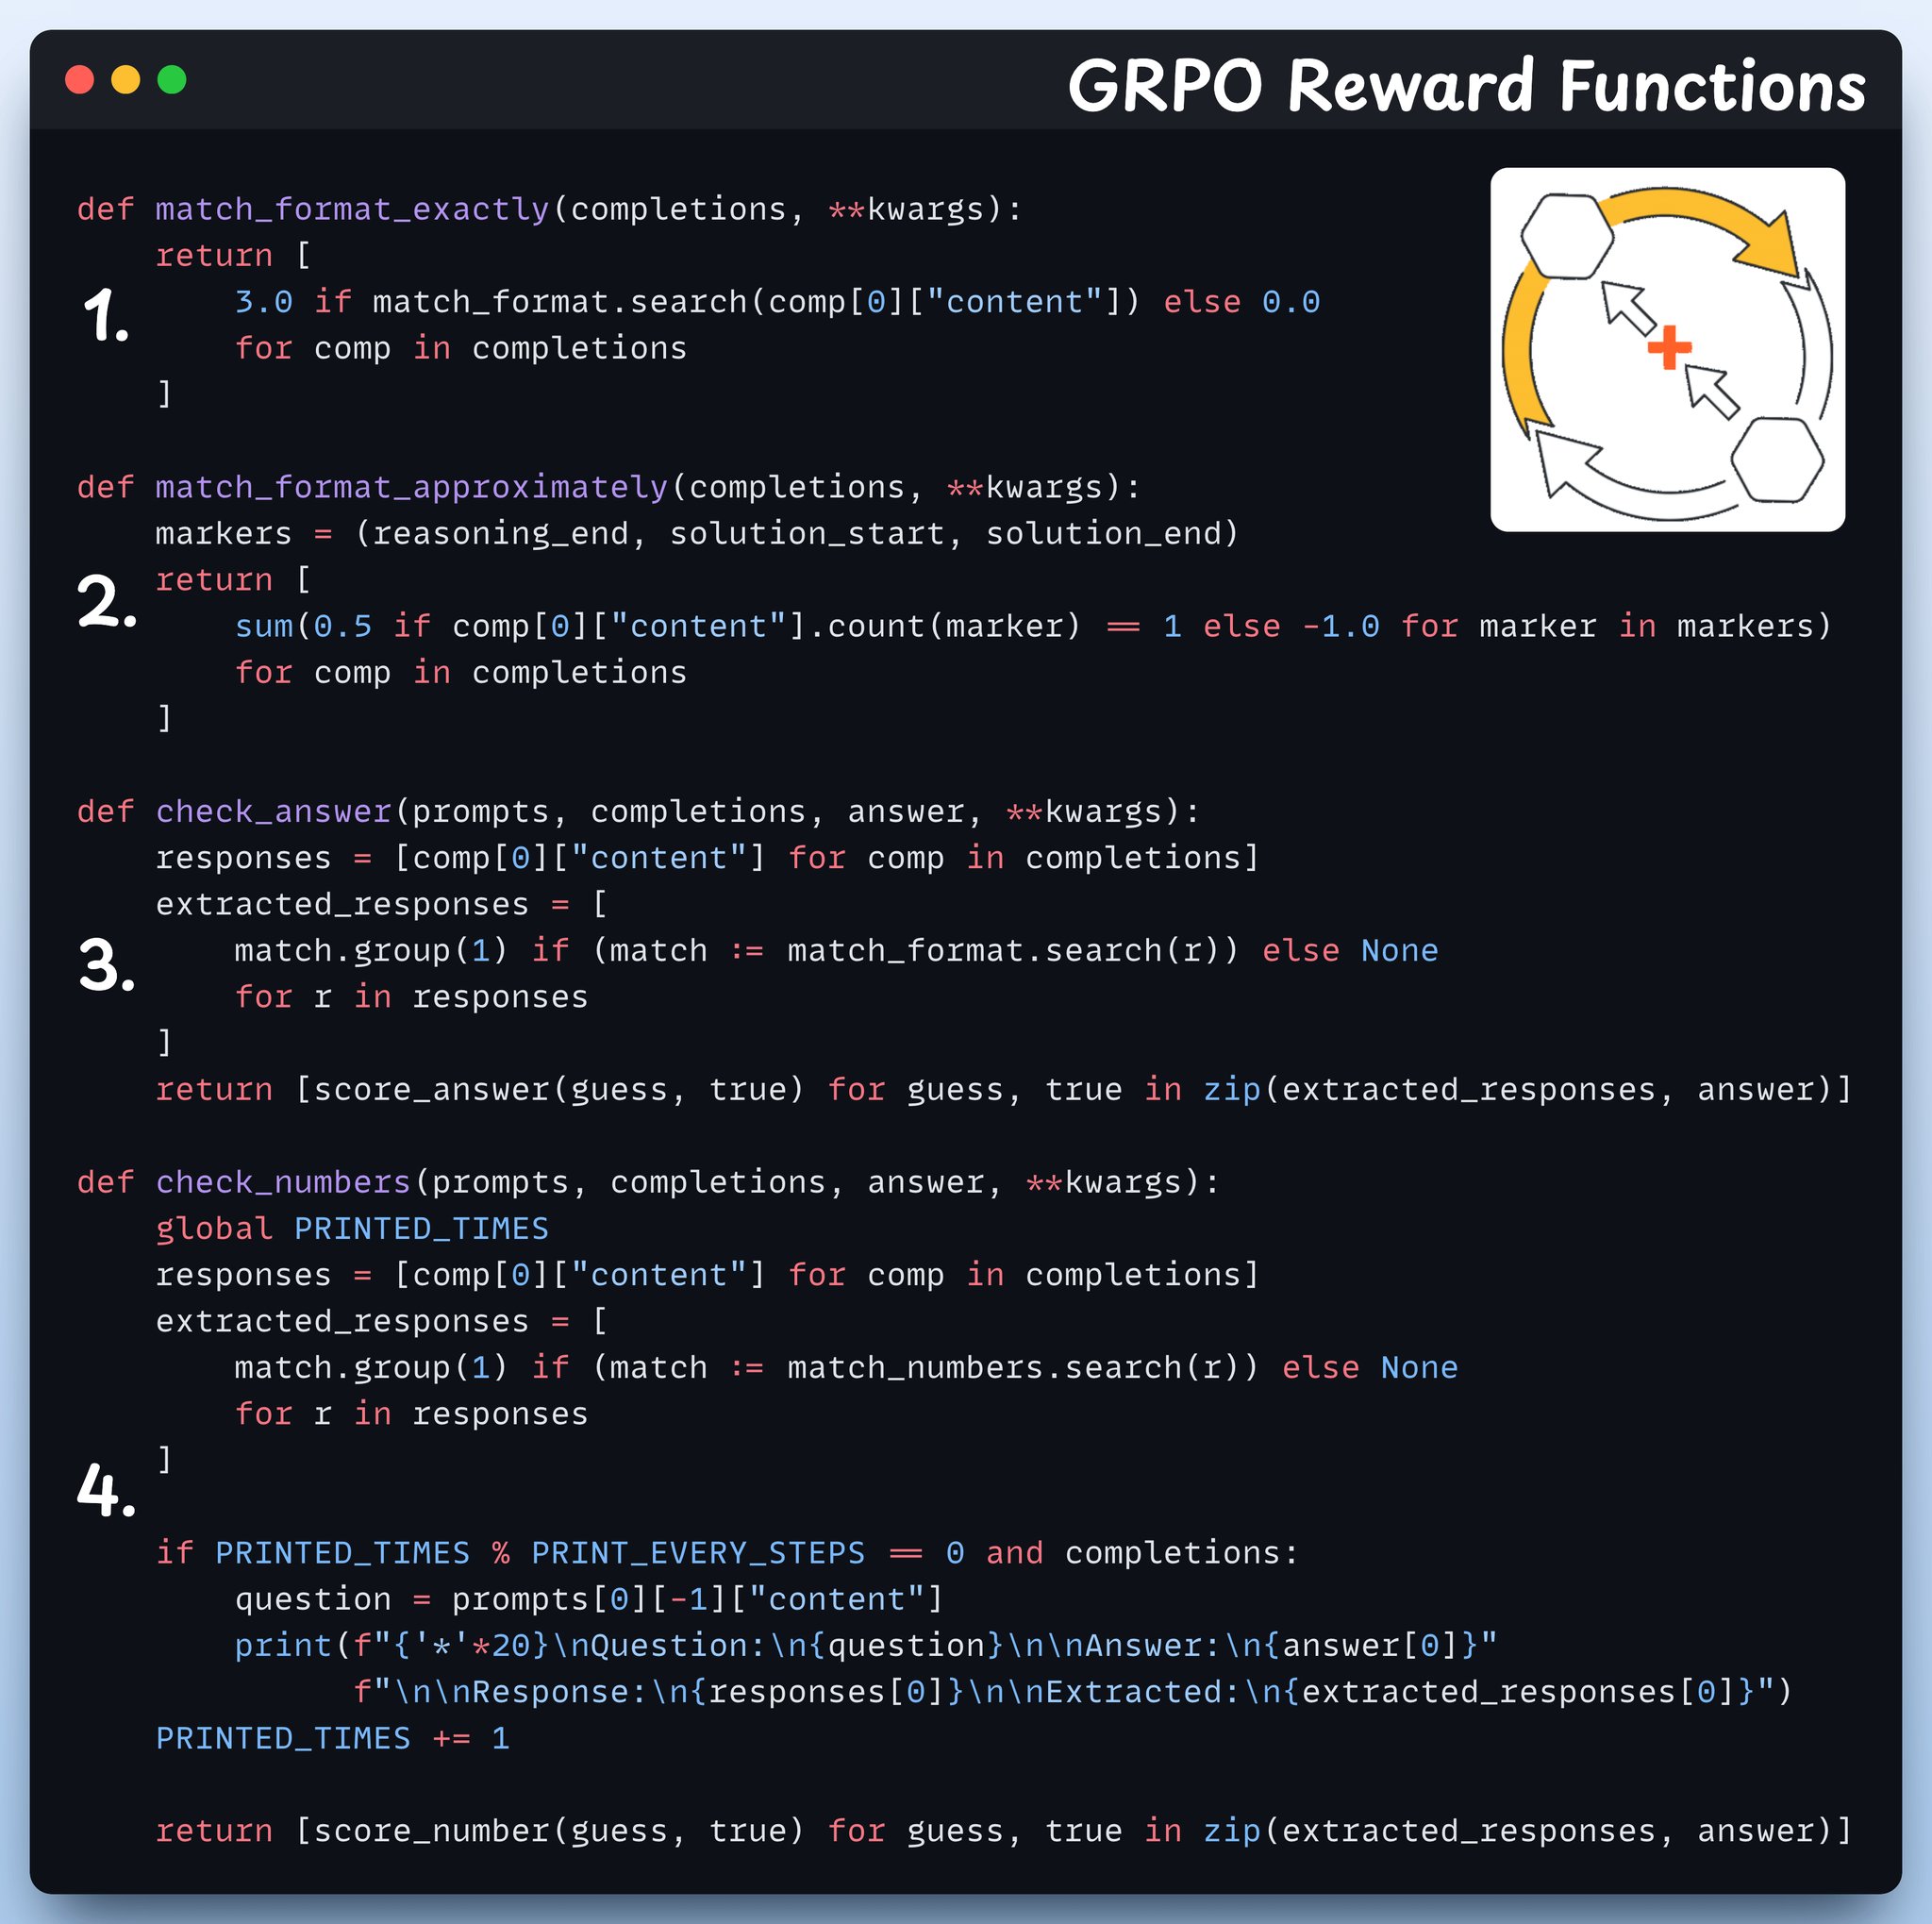
Define reward functions In GRPO we use deterministic functions to validate the response and assign a reward. No manual labelling required! The reward functions: – Match format exactly
– Match format approximately
– Check the answer
– Check numbers Check this out -
Formatting Open R1 Math Dataset for Reasoning Training
By
–
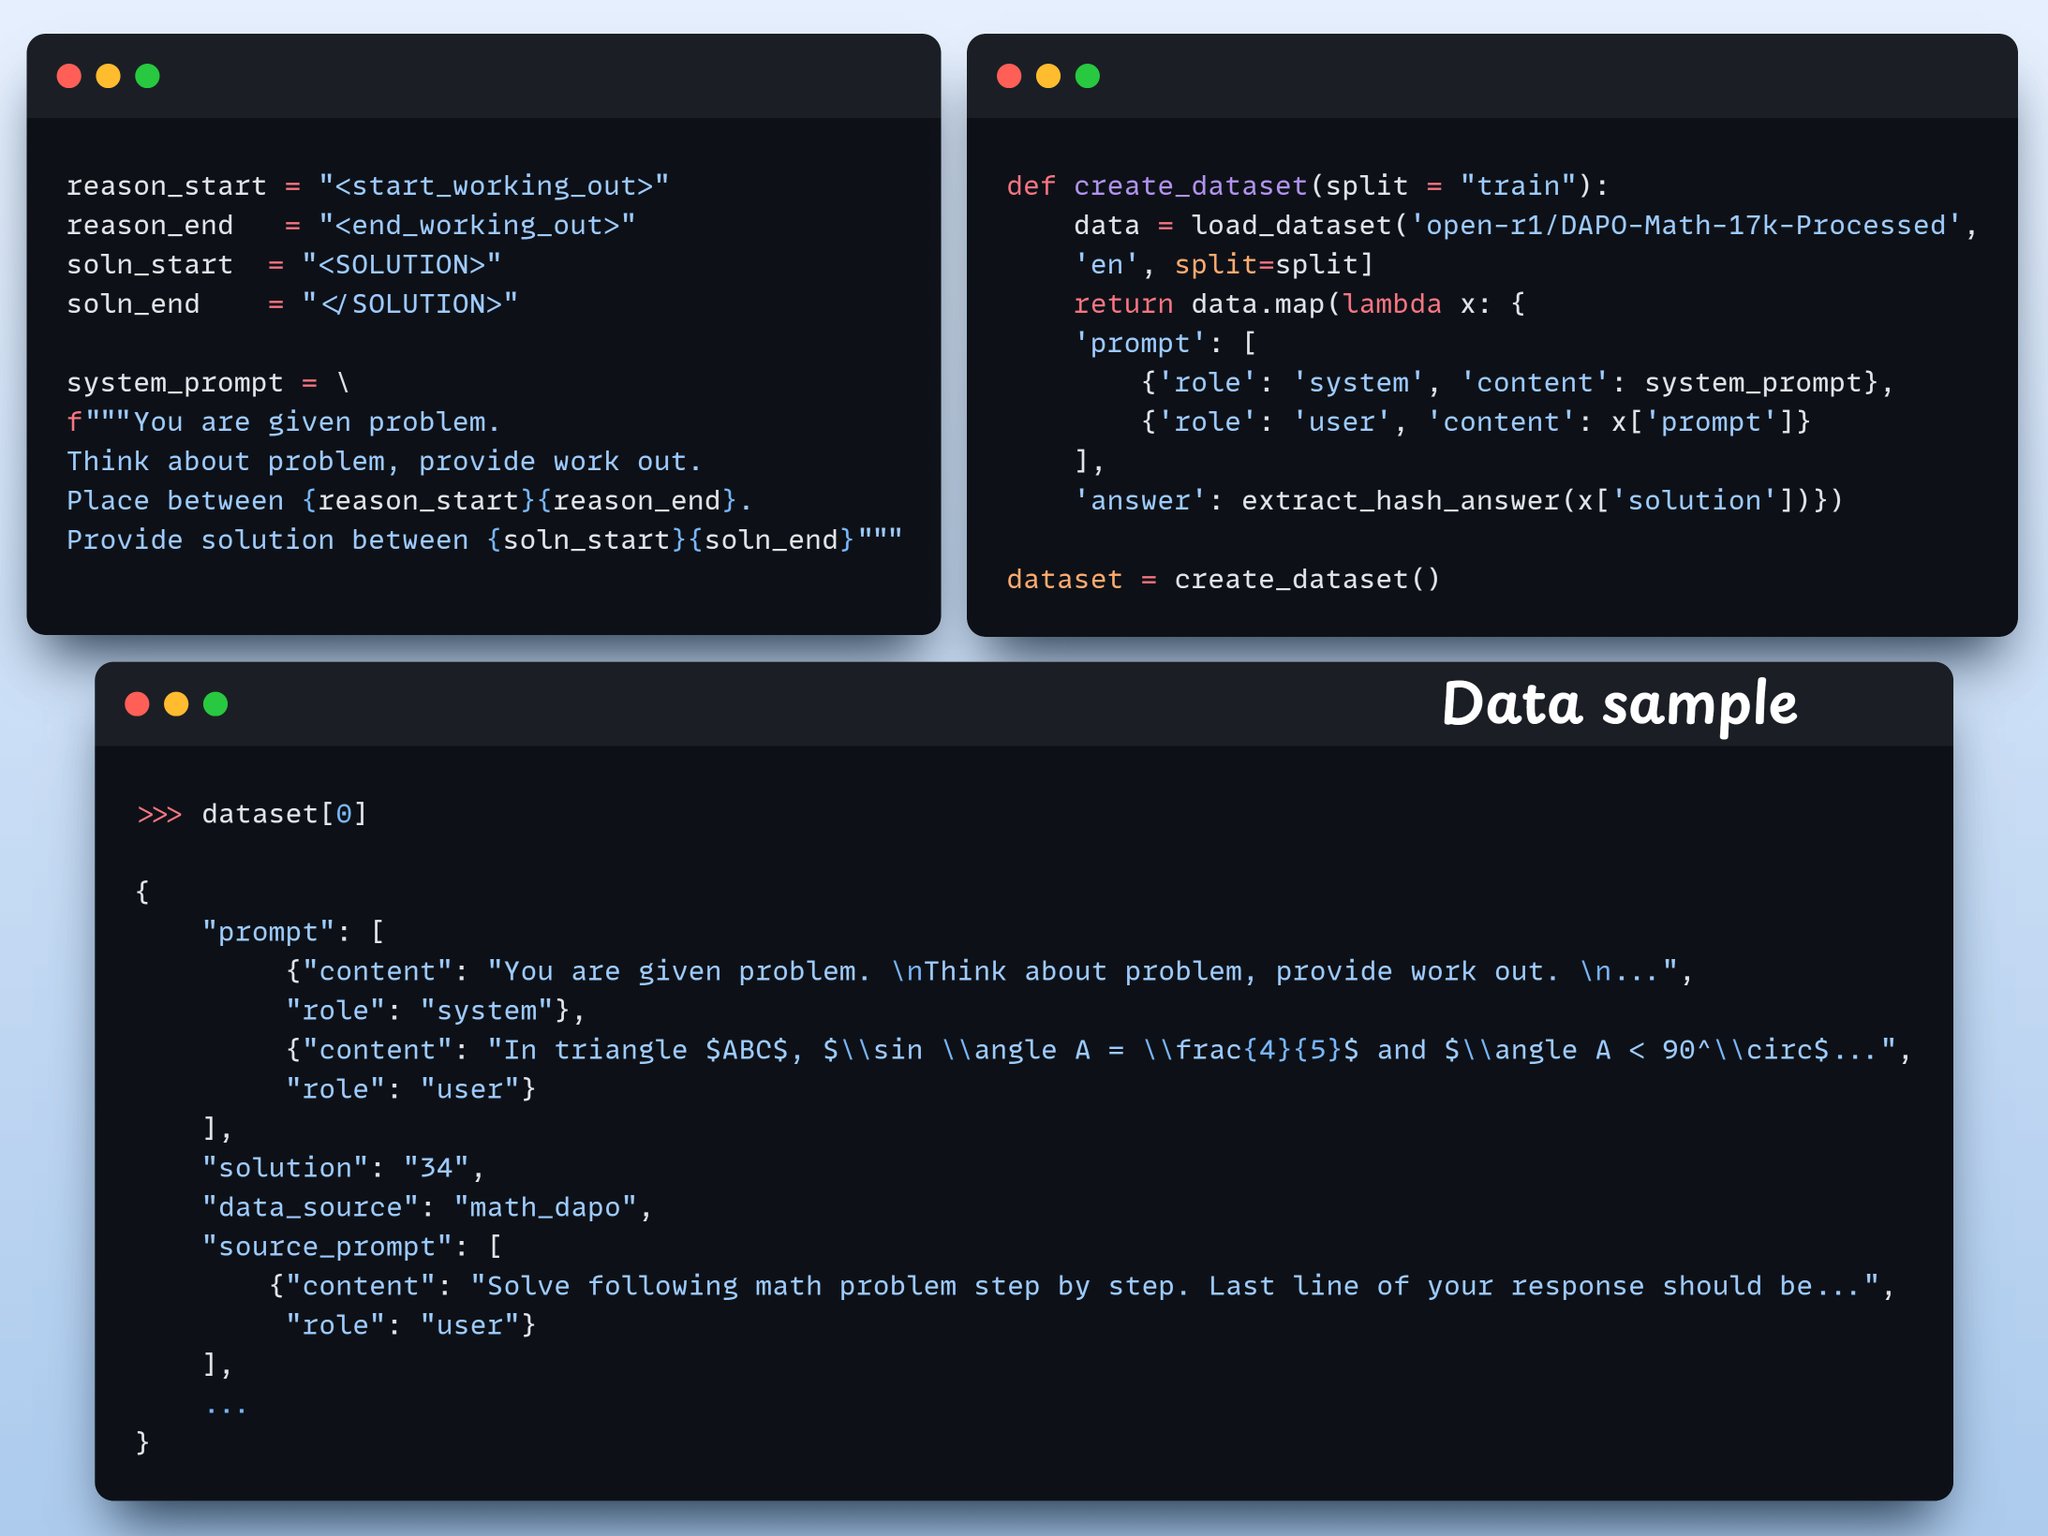
Create the dataset We load Open R1 Math dataset (a math problem dataset) and format it for reasoning. Each sample includes:
– A system prompt enforcing structured reasoning
– A question from the dataset
– The answer in the required format Check this code -
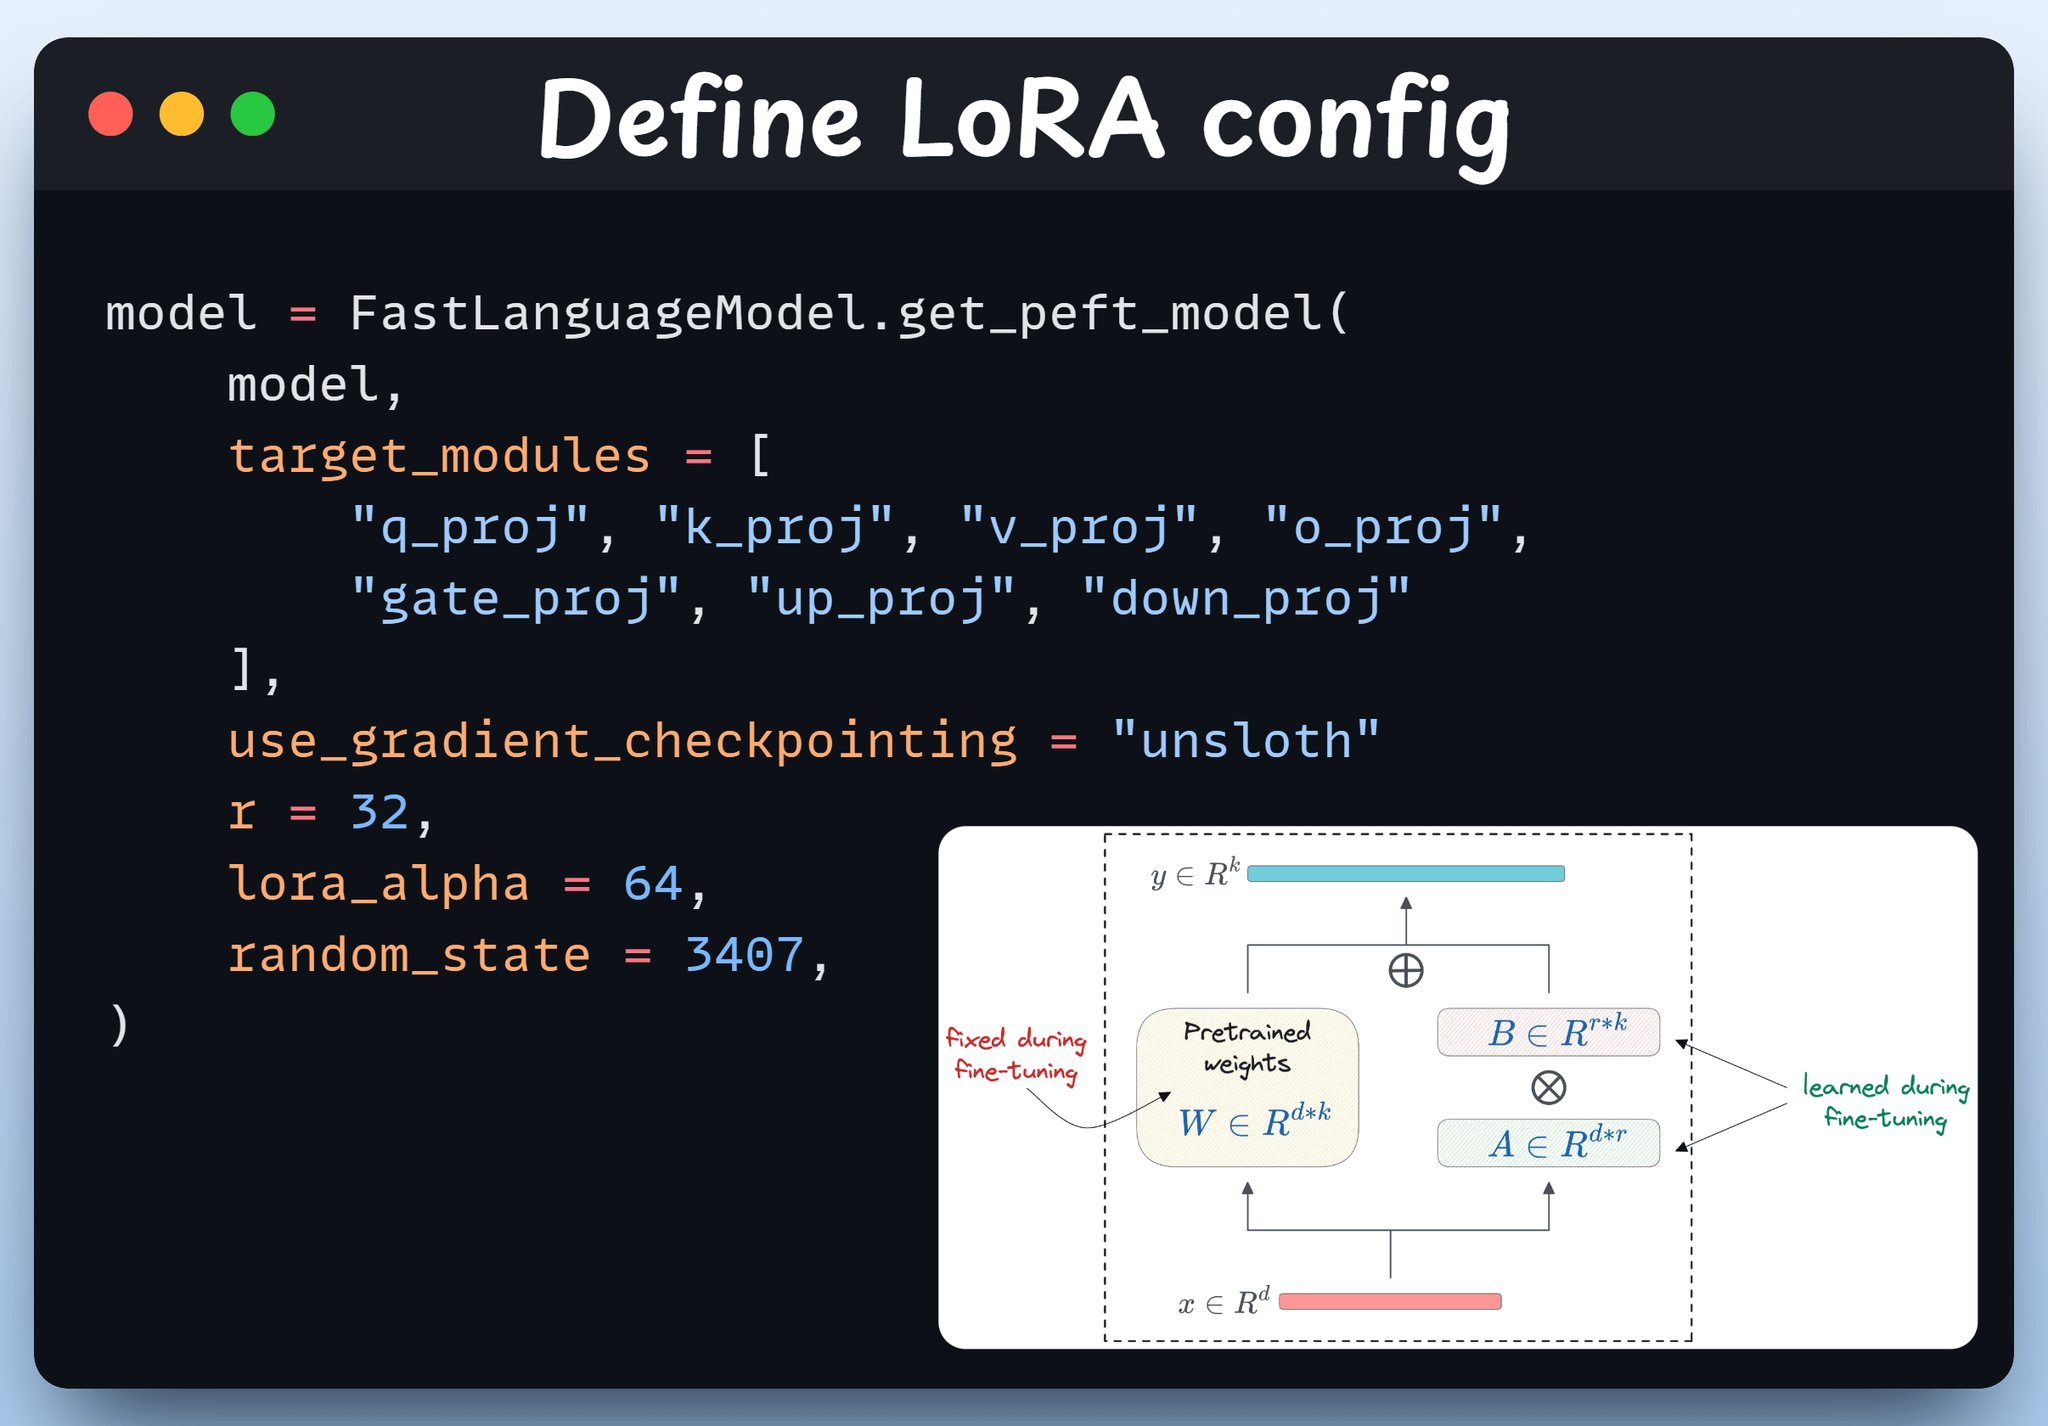
Configuring LoRA for Fine-Tuning with Unsloth PEFT
By
–
Define LoRA config We'll use LoRA to avoid fine-tuning the entire model weights. In this code, we use Unsloth's PEFT by specifying: – The model
– LoRA low-rank (r)
– Modules for fine-tuning, etc. Check this -
GRPO: Reinforcement Learning Method for Fine-Tuning LLMs Explained
By
–
What is GRPO?
— Akshay 🚀 (@akshay_pachaar) 2 mai 2026
Group Relative Policy Optimization is a reinforcement learning method that fine-tunes LLMs for math and reasoning tasks using deterministic reward functions, eliminating the need for labeled data.
Here's a brief overview of GRPO before we jump into code: pic.twitter.com/EX8hI5eEAIWhat is GRPO? Group Relative Policy Optimization is a reinforcement learning method that fine-tunes LLMs for math and reasoning tasks using deterministic reward functions, eliminating the need for labeled data. Here's a brief overview of GRPO before we jump into code:
-
Building a Reasoning Model Without Manual Labels Using Verifiable Outputs
By
–
When outputs are verifiable, labels become optional.
— Akshay 🚀 (@akshay_pachaar) 2 mai 2026
Maths, code, and logic can be automatically checked and validated.
Let's use this fact to build a reasoning model without manual labelling.
We'll use:
– @UnslothAI for parameter-efficient finetuning.
– @HuggingFace TRL to… pic.twitter.com/0FVo2aKfSUWhen outputs are verifiable, labels become optional. Maths, code, and logic can be automatically checked and validated. Let's use this fact to build a reasoning model without manual labelling. We'll use: – @UnslothAI for parameter-efficient finetuning.
– @HuggingFace TRL to