
We launched Agentflow V2 yesterday. One of the most asked questions: What is the difference between Agentflow and automation platforms like n8n, Make, or Zapier?
TOOLS
-
Granola 2.0 launches with $43M Series B funding round
By
–
Announcing Granola 2.0: today we’re bringing the power of Granola to your whole team Also announcing our $43M series B. Led by @natfriedman , alongside Lightspeed and Spark, to build the AI workspace of the future. Big day! x.com/cjpedregal/sta…
-
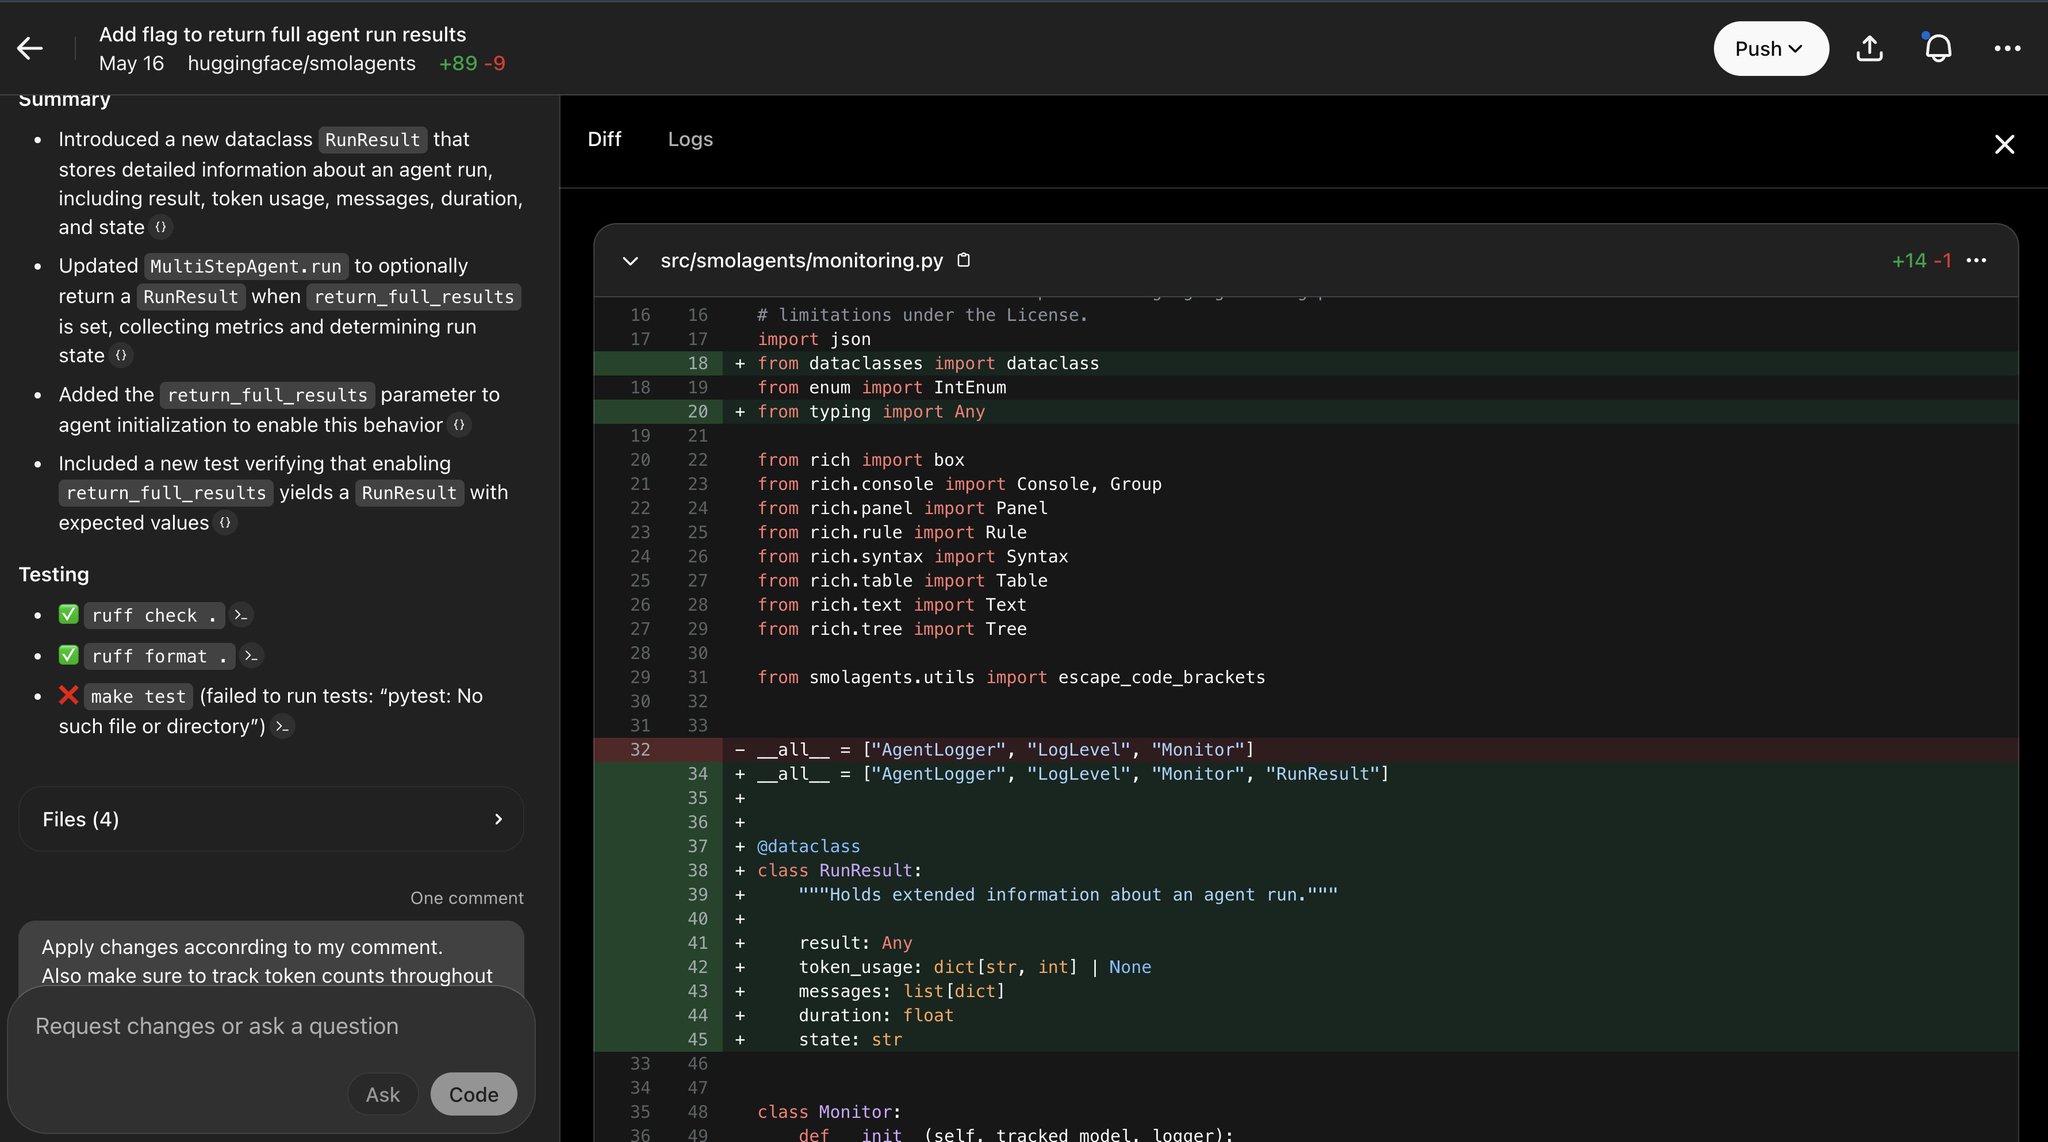
OpenAI Codex Agent Shows Net-Positive Coding Gains, Future Bright
By
–
I've tried OpenAI's Codex, the autonomous SWE agent integrated into ChatGPT. -> While certainly not producing one-shot perfect PRs, it's already a net-positive. And the gain will only improve with better coder models! I think that in the next era of coding, most will be done
-
Global Credit Leader Scales AI Copilot with High-Quality Training Data
By
–
A global credit leader built an AI copilot to help CSRs with accurate responses, but early models lacked precision. With Snorkel Enterprise AI Platform, they fine-tuned with high-quality training data to boost accuracy & enable scalable copilots! Scale up with #SnorkelAI
-

Replit Partners Semgrep Security Vulnerability Scanning
By
–
Vibe code with confidence.
Scan, find & fix vulnerabilities:
Replit partners with @semgrep to help teams run pre-deployment security scans. -
DeepAgent Evaluates All LLMs in Single Line Prompt
By
–
In a single line prompt, DeepAgent evaluates all LLMs and creates this website:
— Abacus.AI (@abacusai) 16 mai 2025
•Generated an image for each LLM
•Created a chart that compares and contrasts top LLMs across cost, performance, and context pic.twitter.com/0fwC6bhEGOIn a single line prompt, DeepAgent evaluates all LLMs and creates this website: •Generated an image for each LLM
•Created a chart that compares and contrasts top LLMs across cost, performance, and context -
Llama 4 Scout achieves 2600 tokens per second on Poe
By
–
The world’s fastest inference for Llama 4 Scout is now on Poe!
— Poe (@poe_platform) 16 mai 2025
At over 2,600 tokens per second, this bot allows for near-instant interactions. (1/2) pic.twitter.com/wt6NaFyEzxThe world’s fastest inference for Llama 4 Scout is now on Poe! At over 2,600 tokens per second, this bot allows for near-instant interactions. (1/2)
-
Cerebras Llama 4 Scout Nitro Now Available on Poe Platform
By
–
You can try Cerebras’ Llama 4 Scout Nitro at https://
poe.com/Llama-4-Scout-
nitro
… and on all platforms. (2/2) -
New tool outperforms Codex in testing
By
–
i've been testing something that works so well im not that excited to use codex