Since Tinker launched, our community has used it to train state-of-the-art models, build infrastructure, and publish novel research. We will be highlighting this creative work in regular roundups, and hope to inspire your own Tinkering as well.
Perplexity released a new Advanced Deep Research upgrade with SOTA performance. It scores 79% at Google DeepMind Deep Research QA and tops the newly introduced DRACO Benchmark. Currently available to Max users and expected to arrive for Pro users soon.
NAS: The AI That Designs AI Stop guessing your model’s architecture. Neural Architecture Search (NAS) automates the hunt for the perfect model by balancing accuracy with hardware limits like speed and memory. #AI #MachineLearning #NAS #AutoML #DeepLearning #DataScience
Another thing is understanding your role and what you want out of the tool. There's no universe where a marketer for example will start going deep into coding and building production heavy agents except you're making a complete career transition.
The demo on https://t.co/ozhOG8iPeH is worth a try – ignore the "No microphone found" message, clicking "Record" and allowing your browser to use a microphone fixes that. It transcribes very accurately in almost real-time. It's really impressive. https://t.co/LOJUsT2sPW
The demo on huggingface.co/spaces/mistra… is worth a try – ignore the "No microphone found" message, clicking "Record" and allowing your browser to use a microphone fixes that. It transcribes very accurately in almost real-time. It's really impressive. Mistral AI (@MistralAI) Introducing Voxtral Transcribe 2, next-gen speech-to-text models by @MistralAI. State-of-the-art transcription, speaker diarization, sub-200ms real-time latency. Details in 🧵 — https://nitter.net/MistralAI/status/2019068826097213953#m
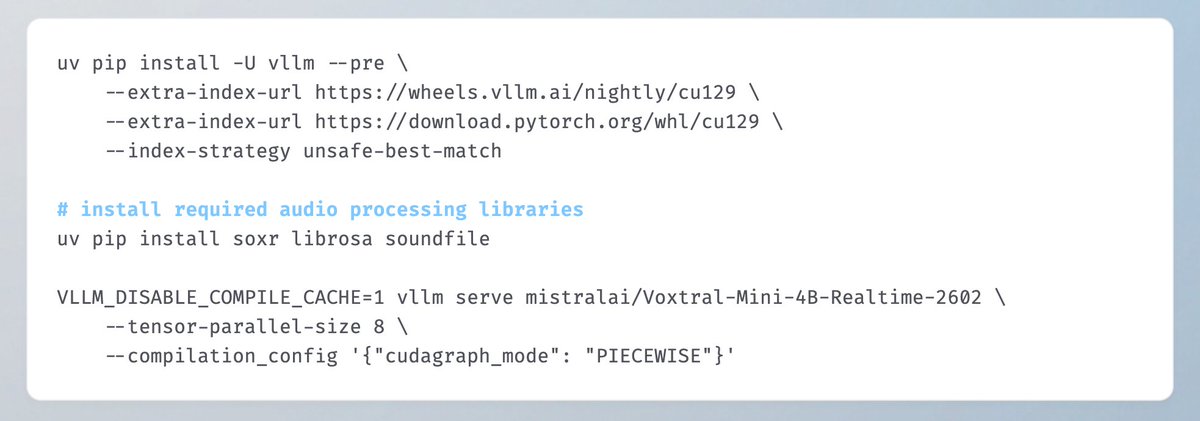
Congrats to @MistralAI on releasing Voxtral Mini 4B Realtime! 🎉 Day-0 support in vLLM! A 4B streaming ASR model achieving <500ms latency while matching offline model accuracy, supporting 13 languages. vLLM's new Realtime API `/v1/realtime` provides audio streaming – optimized for voice assistants, live subtitles, and meeting transcription! Thanks to the close collaboration between the vLLM community and @MistralAI for making this production-grade support possible 🤝 📑Model & Usage: huggingface.co/mistralai/Vox… Mistral AI (@MistralAI) Voxtral Realtime is built for voice agents and live applications. Its natively streaming architecture delivers latency configurable to sub-200ms. And at 480ms, it stays within 1-2% WER of our offline model. We release the model as open weights under Apache 2.0. — https://nitter.net/MistralAI/status/2019068828257333466#m
Mini Transcribe 2 via API at $0.003/min.
Realtime via API at $0.006/min, plus open weights. Blogpost: https://
mistral.ai/news/voxtral-t
ranscribe-2
… HuggingFace (weights + realtime demo): https://
huggingface.co/mistralai/Voxt
ral-Mini-4B-Realtime-2602
… Get started: http://
console.mistral.ai/build/audio/sp
eech-to-text
…
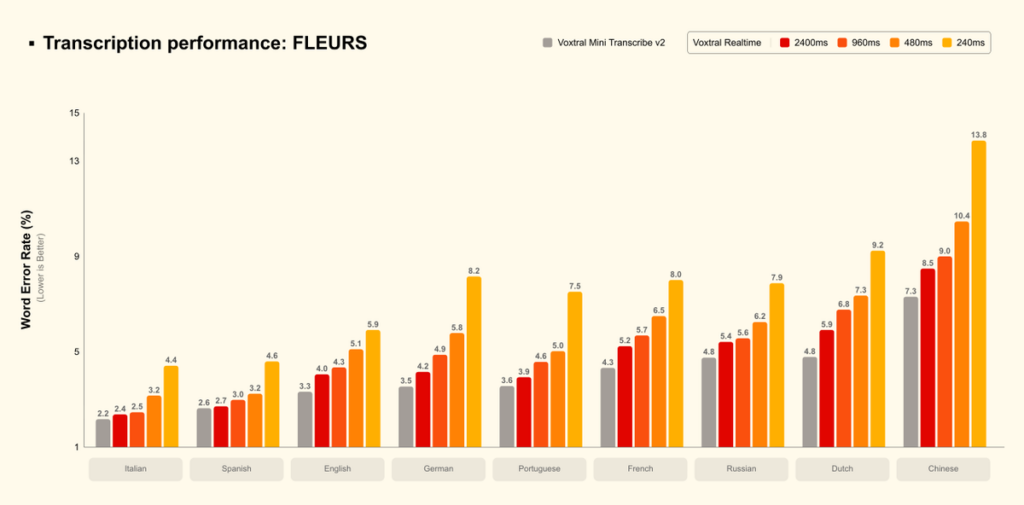
Voxtral Mini Transcribe 2 handles batch transcription with the best price-performance of any transcription API: 4% WER on FLEURS at $0.003/min. Includes speaker diarization, context biasing, and word-level timestamps across 13 languages.
Voxtral Realtime is built for voice agents and live applications. Its natively streaming architecture delivers latency configurable to sub-200ms. And at 480ms, it stays within 1-2% WER of our offline model. We release the model as open weights under Apache 2.0.