AI Dynamics

Global AI News Aggregator

About

TOOLS

  • Netflix Launches Its VOID AI Model on Hugging Face
    Netflix Launches Its VOID AI Model on Hugging Face

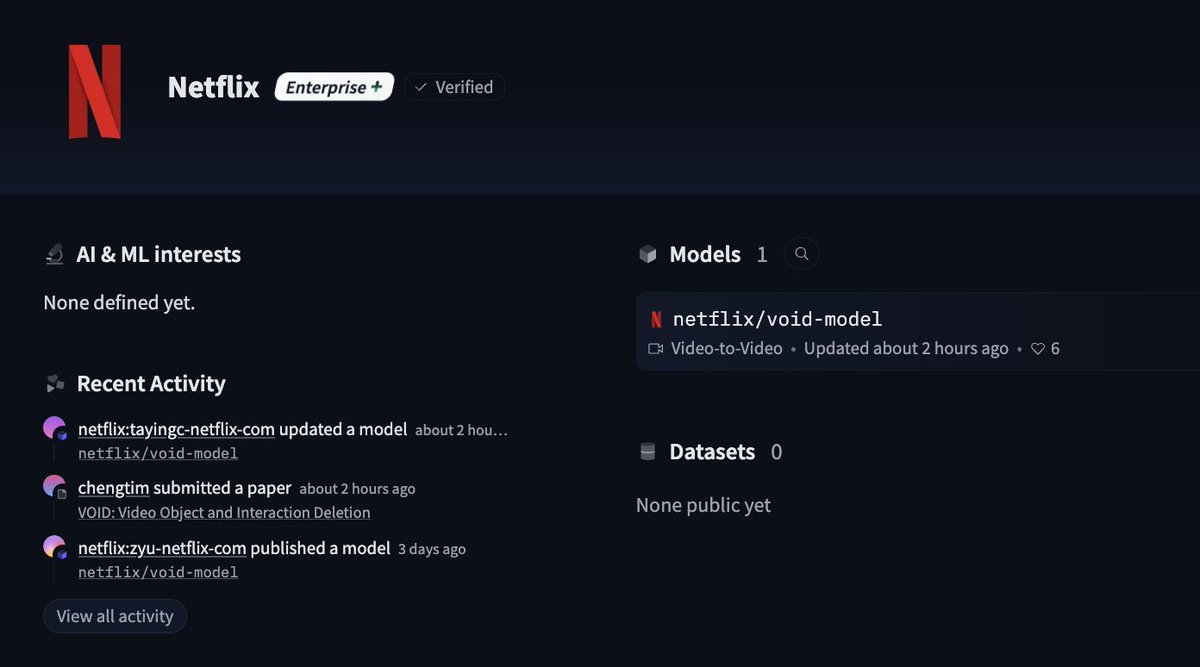
    Netflix: surprise we just released our new AI model VOID on @huggingface. Capabilities of Netflix's VOID Model:
    – Object Removal with Environmental Awareness.
    – Physical Interaction Handling.
    – Open-Weight Access. [Translated from EN to English]

    → View original post on X — @huggingface, 2026-04-03 13:20 UTC

  • Notion MCP Gateway Enables User Level Access Integration

    Nice. The remote Notion MCP should pass user level access i believe: https://
    developers.notion.com/guides/mcp/mcp ; we've had many customers connect to it (we run an MCP gateway)

    → View original post on X — @jiquanngiam

  • VoxCPM: Open-Source Voice Cloning Without Tokenization
    VoxCPM: Open-Source Voice Cloning Without Tokenization

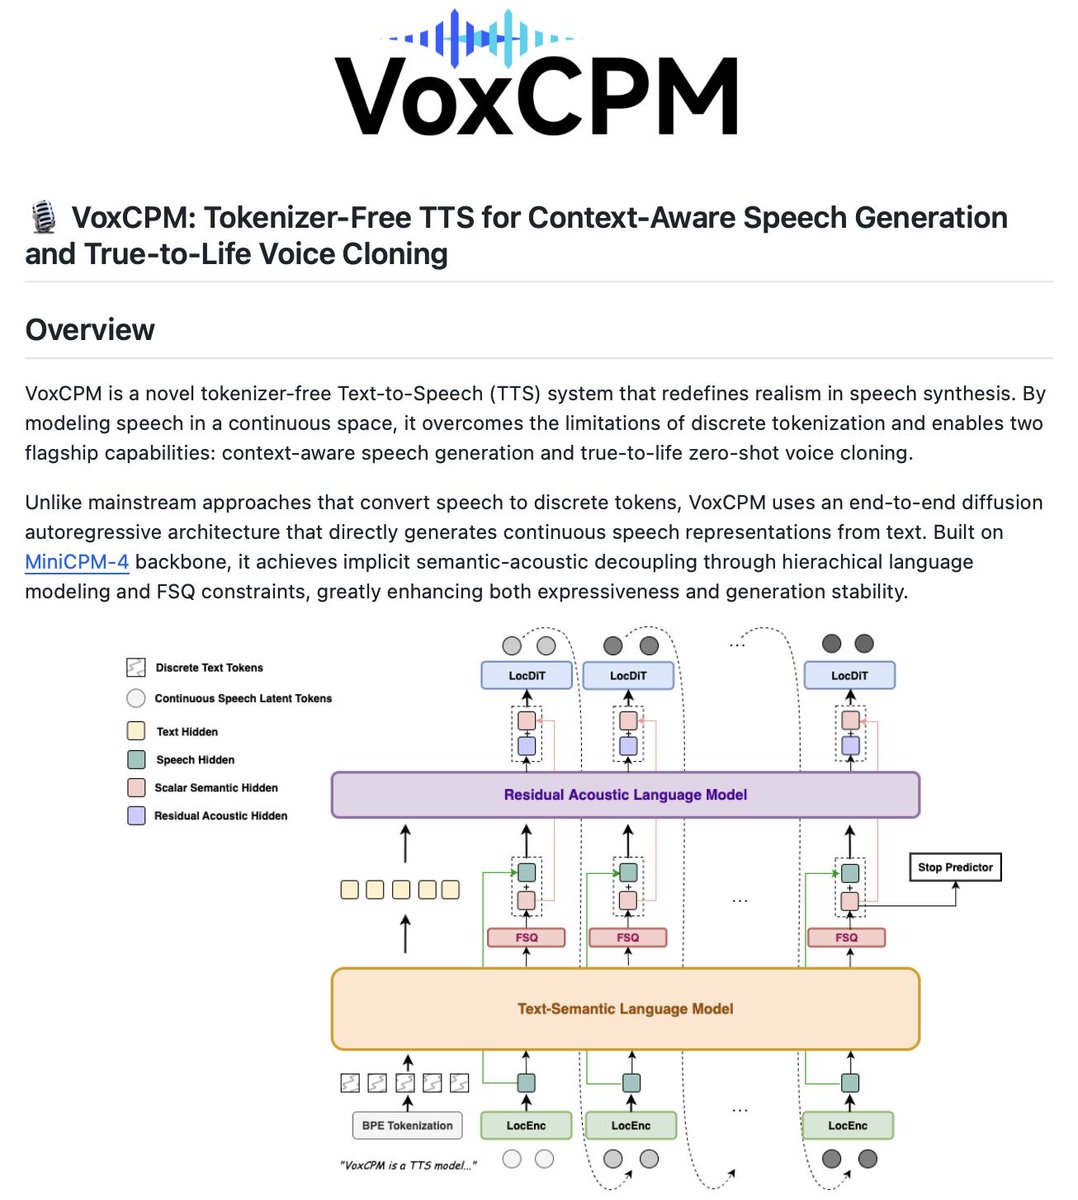
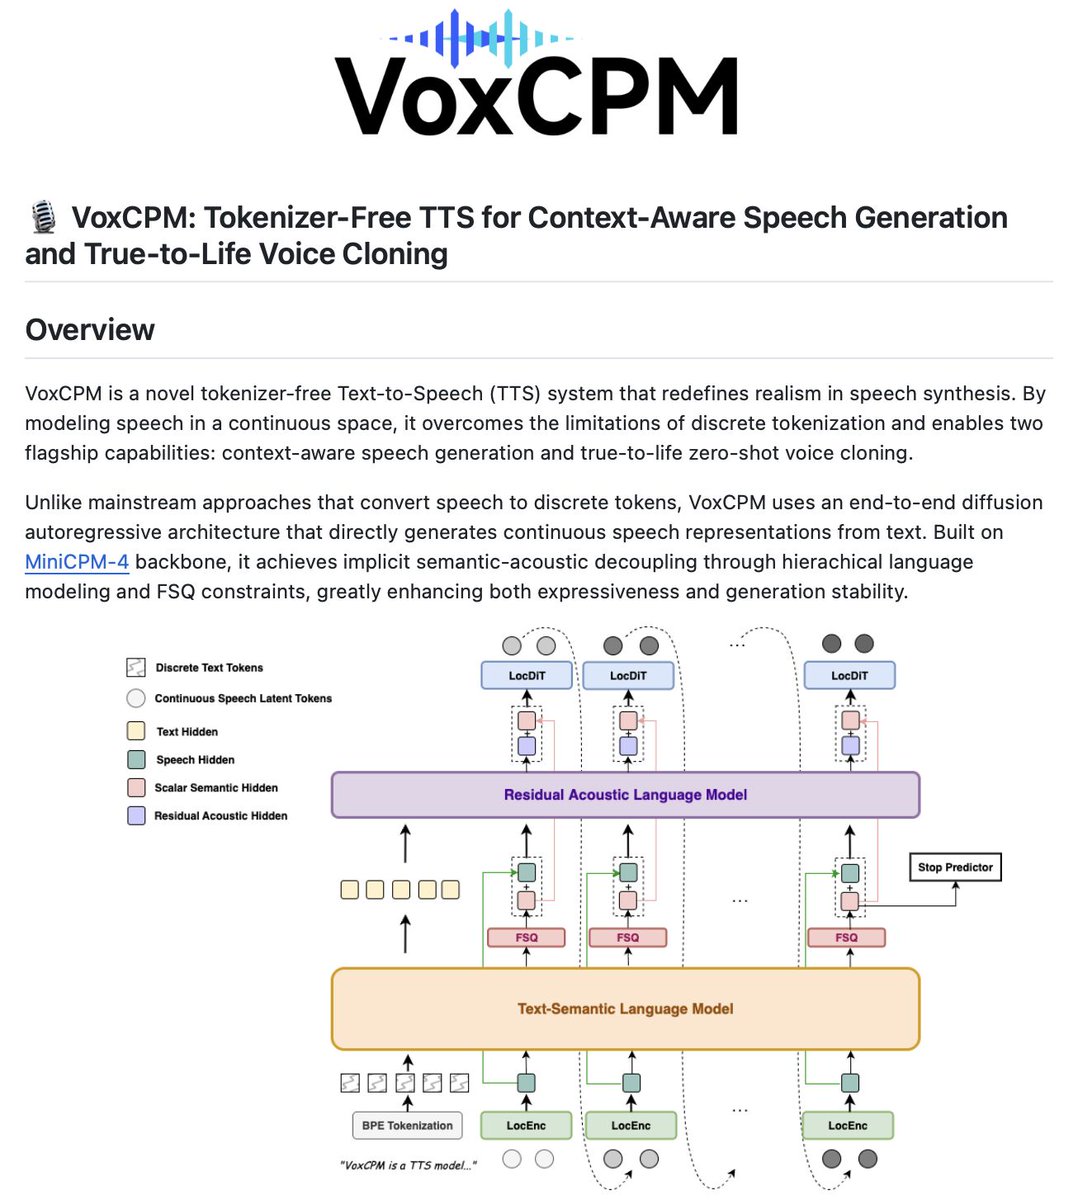
    If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling • Context-aware prosody generation without manual tuning • Zero-shot voice cloning from short reference audio • Streaming synthesis support for real-time applications • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! — https://nitter.net/Sumanth_077/status/2040055394958286903#m

    → View original post on X — @sumanth_077, 2026-04-03 13:15 UTC

  • Software Engineers Transform Robotics: New Infrastructure Opportunities Emerge

    There are now two types of robotics founders and the split matters more than consumer vs. industrial. A growing wave of software engineers are building robots, but they're bringing software expectations with them: simulation should work like Vercel, hardware talent should be sourceable via API, and if CAD takes three months to learn, they'll find a workaround in three days. The gap between what they expect and what exists is enormous. There's no Common Crawl for robotics data. Selling hardware is nothing like selling SaaS. And the entire tooling stack was built for people willing to spend weeks wiring things together. That gap is where the next generation of robotics infrastructure companies gets built. Diego Prats | 🤖 (@mexitlan) Are you fleeing to robotics because Claude Code cooked your job? Yeah… me neither… 😅… As part of building in the open, here are some more learnings from the physical AI ecosystem: Folks under-estimate the number of pain points and problems worth solving for the software-first robotics founder persona! — https://nitter.net/mexitlan/status/2039870415401836773#m

    → View original post on X — @whiteafrican, 2026-04-03 13:15 UTC

  • VoxCPM: Real-time Voice Cloning Without Tokenization
    VoxCPM: Real-time Voice Cloning Without Tokenization

    Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling
    • Context-aware prosody generation without manual tuning
    • Zero-shot voice cloning from short reference audio
    • Streaming synthesis support for real-time applications
    • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! [Translated from EN to English]

    → View original post on X — @sumanth_077, 2026-04-03 13:14 UTC

  • Lovable Launches AI-Powered Visual Edits for Full-Stack Apps

    New on Lovable: AI‑powered Visual Edits turn your full‑stack app into a Figma‑like canvas. – Click any element in a live preview
    – Tweak layout, colors, Tailwind classes
    – Lovable safely rewrites the JSX/TSX and hot‑reloads in seconds Paired with Plan Mode, Lovable Cloud, and

    → View original post on X — @futurepedia_io

  • 8 RAG Architectures for AI Engineers: Complete Guide
    8 RAG Architectures for AI Engineers: Complete Guide

    8 RAG architectures for AI Engineers: (explained with usage) 1) Naive RAG – Retrieves documents purely based on vector similarity between the query embedding and stored embeddings. – Works best for simple, fact-based queries where direct semantic matching suffices. 2) Multimodal RAG – Handles multiple data types (text, images, audio, etc.) by embedding and retrieving across modalities. – Ideal for cross-modal retrieval tasks like answering a text query with both text and image context. 3) HyDE (Hypothetical Document Embeddings) – Queries are not semantically similar to documents. – This technique generates a hypothetical answer document from the query before retrieval. – Uses this generated document’s embedding to find more relevant real documents. 4) Corrective RAG – Validates retrieved results by comparing them against trusted sources (e.g., web search). – Ensures up-to-date and accurate information, filtering or correcting retrieved content before passing to the LLM. 5) Graph RAG – Converts retrieved content into a knowledge graph to capture relationships and entities. – Enhances reasoning by providing structured context alongside raw text to the LLM. 6) Hybrid RAG – Combines dense vector retrieval with graph-based retrieval in a single pipeline. – Useful when the task requires both unstructured text and structured relational data for richer answers. 7) Adaptive RAG – Dynamically decides if a query requires a simple direct retrieval or a multi-step reasoning chain. – Breaks complex queries into smaller sub-queries for better coverage and accuracy. 8) Agentic RAG – Uses AI agents with planning, reasoning (ReAct, CoT), and memory to orchestrate retrieval from multiple sources. – Best suited for complex workflows that require tool use, external APIs, or combining multiple RAG techniques. 👉 Over to you: Which RAG architecture do you use the most? _____ Share this with your network if you found this insightful ♻️ Find me → @akshay_pachaar ✔️ For more insights and tutorials on LLMs, AI Agents, and Machine Learning!

    → View original post on X — @akshay_pachaar, 2026-04-03 12:54 UTC
  • 5 Practical Techniques to Detect and Mitigate LLM Hallucinations
    5 Practical Techniques to Detect and Mitigate LLM Hallucinations

    5 Practical Techniques to Detect and Mitigate LLM Hallucinations Beyond Prompt Engineering machinelearningmastery.com/5… [Translated from EN to English]

    → View original post on X — @craigbrownphd, 2026-04-03 12:44 UTC

  • Free Access to Claude Code Workshop and LLM Knowledge Bases Session
    Free Access to Claude Code Workshop and LLM Knowledge Bases Session

    Wow! There is so much interest in this. Months ago, I spoke on this idea in a live workshop. Access it for FREE for the next couple of days: academy.dair.ai/dashboard/co… I am also hosting a live session on building LLM Knowledge Bases for your agents: academy.dair.ai/dashboard/ev…

    → View original post on X — @dair_ai, 2026-04-03 12:37 UTC

  • Group Member Creates Paper Abstract Visualization Video with Pretext and Textsring

    A group member created a frontend page using Pretext and Textsring, utilizing paper abstracts and keywords from MSA, then generated videos with dynamic effects. Quite impressive stuff. [Translated from EN to English]

    → View original post on X — @elliotchen100, 2026-04-03 11:17 UTC