I've only had internal tools but will deploy my first few to production this week w/ this 1. end-to-end tests for the core api. these are core flows that should never break.
2. hand testing every frontend component The process is slower than I'd like so far
SOFTWARE
-
Testing Strategy for First Production Tool Deployment
By
–
-
Hardware Fails Eventually, Software Eventually Works
By
–
“Hardware eventually fails. Software eventually works.” — Michael Hartung
-
Elsevier Hiring Software Engineers in Mexico City Tech Hub
By
–
🚀Elsevier is hiring #SoftwareEngineers! Are you passionate and eager to make a real impact in the world of science and healthcare? Join their vibrant #Tech hub in Mexico City!
— Catherine Adenle (@CatherineAdenle) 9 février 2026
Apply now: 🔗https://t.co/dUBcIneOIT#Elsevier #SoftwareEngineering #TechJobs #Hiring pic.twitter.com/G6ZXTPywPjElsevier is hiring #SoftwareEngineers! Are you passionate and eager to make a real impact in the world of science and healthcare? Join their vibrant #Tech hub in Mexico City! Apply now: https://
relx.wd3.myworkdayjobs.com/en-US/Elsevier
Jobs?jobFamilyGroup=8c5fc5940f0b01ba8d012114be0035b9&Country___Territory=e2adff9272454660ac4fdb56fc70bb51
…
#Elsevier #SoftwareEngineering #TechJobs #Hiring -
Autoscaling by Queue Depth: Beyond GPU Utilization Metrics
By
–
4/5 The horizontal fix: autoscale on queue depth, not GPU utilization 100% GPU = efficiency, not overload. We use vllm:num_requests_waiting to trigger scale-up when the deployment can't keep up with incoming requests.
-
Auto-Tune vLLM Config Doubles Throughput and Halves Latency
By
–
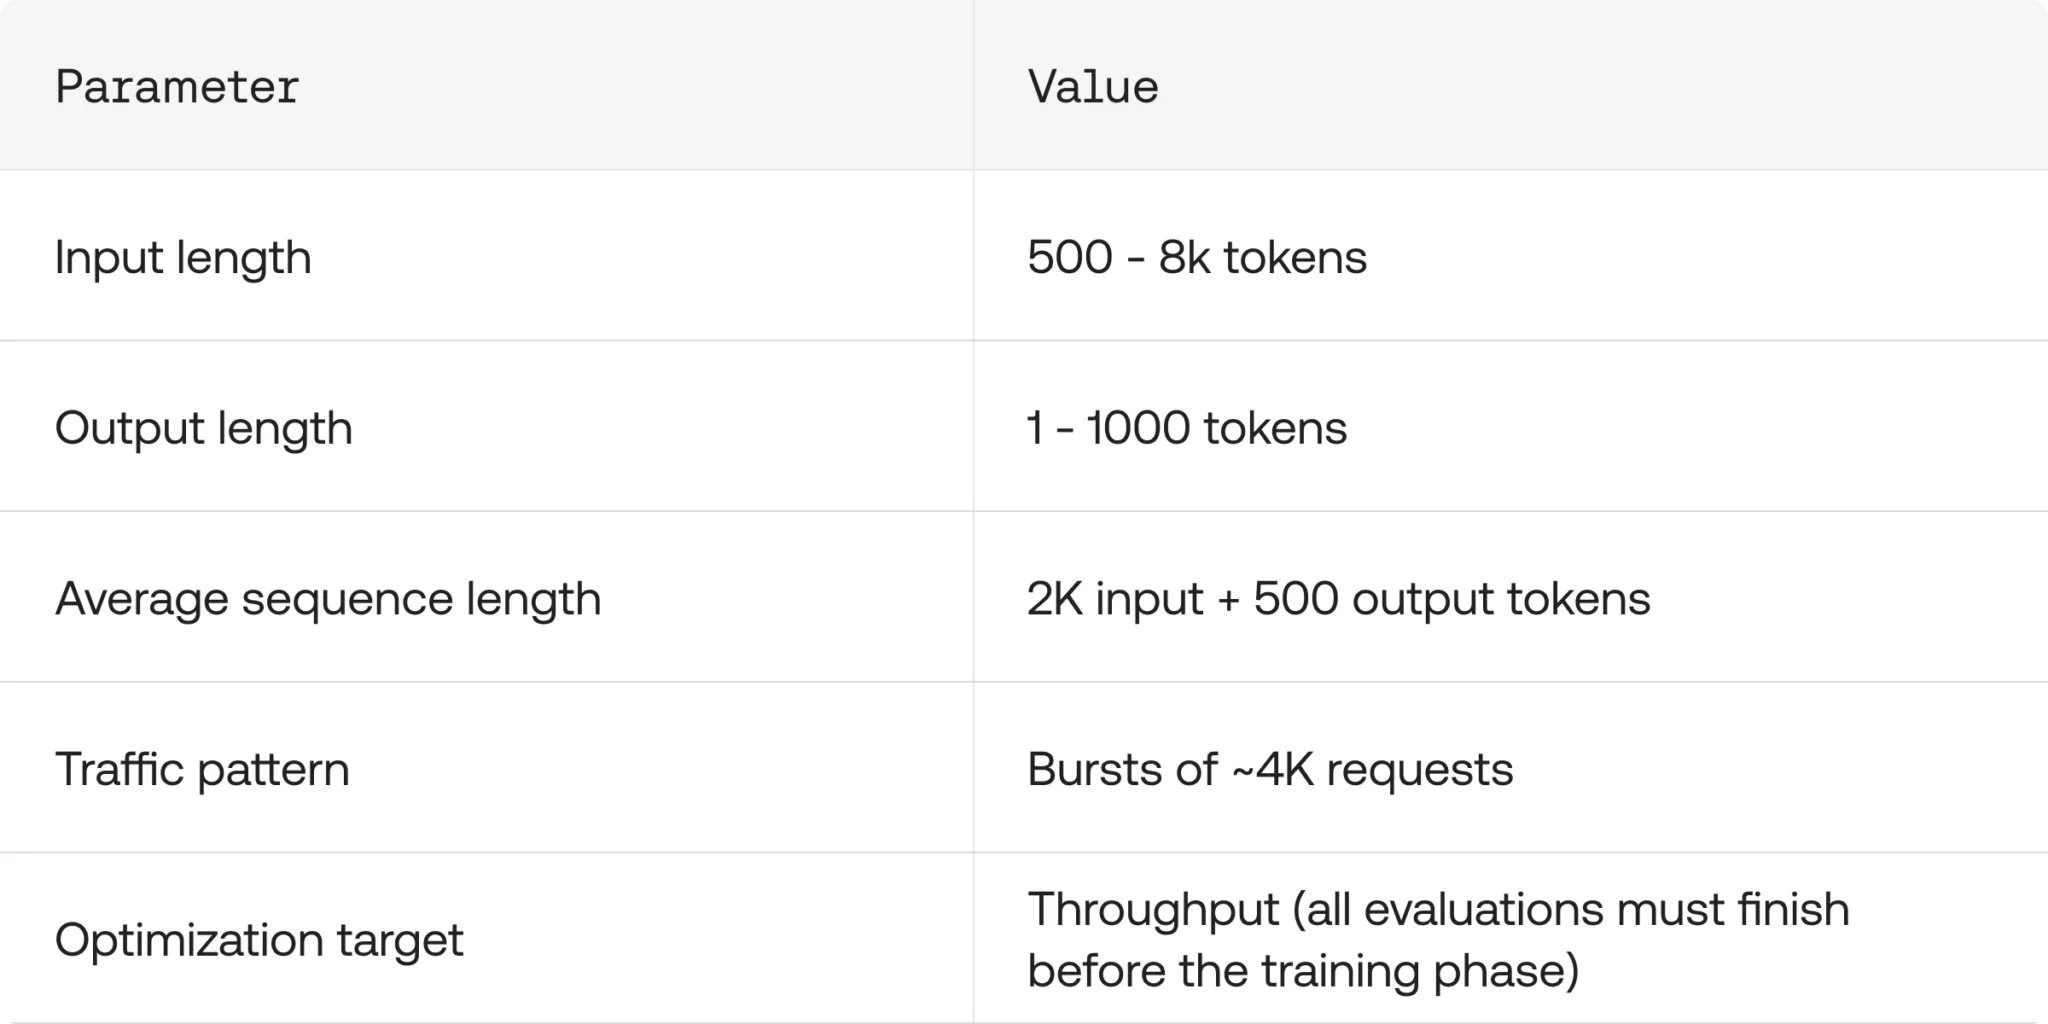
3/5 The vertical fix: auto-tune vLLM config Our old settings were way too conservative. After tuning with Auto-Tune vLLM + GuideLLM we got: ~2× throughput, 2× lower latency, same GPU budget @VLLM @Openshift
-
Scaling vLLM: Doubling Throughput and Halving Latency
By
–
1/5 Go Big or Go OOM: The Art of Scaling vLLM .
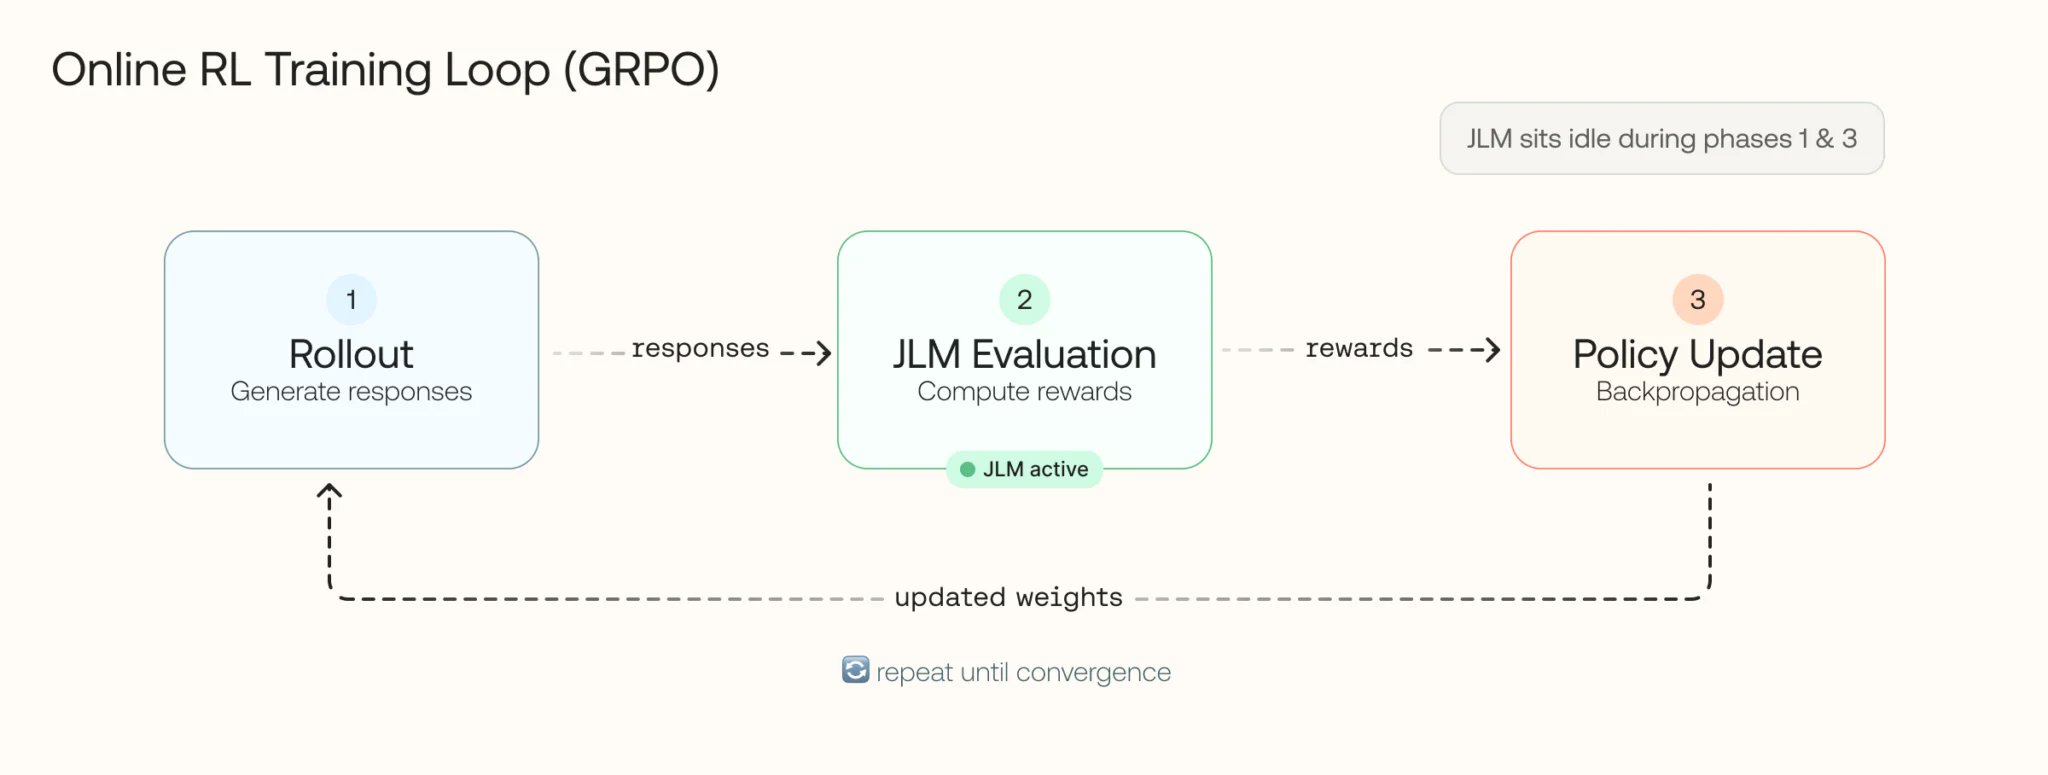
We doubled throughput and cut latency in half-same GPUs, just better vLLM config then added smart autoscaling to handle traffic bursts. Here's what we learned optimizing LLM-as-a-Judge for GRPO training. -
Kling 3.0 Omni: Stable subject consistency, effortless workflow, focus on story.
By
–
Kling 3.0 Omni is the quiet breakthrough. Subject consistency finally stabilizes. Faces do not drift. Wardrobes stay intact. Identity persists across shots.
— AI Breakfast (@AiBreakfast) 9 février 2026
The workflow stays the same, but the mental overhead disappears. You focus on story instead of repairs. pic.twitter.com/j8KopYpcVRKling 3.0 Omni is the quiet breakthrough. Subject consistency finally stabilizes. Faces do not drift. Wardrobes stay intact. Identity persists across shots. The workflow stays the same, but the mental overhead disappears. You focus on story instead of repairs.
-
Kling 3.0: Removing technical barriers for cinematic scene creation in one pass.
By
–
The goal of Kling 3.0 is simple:
— AI Breakfast (@AiBreakfast) 9 février 2026
Remove the technical ceiling between an idea and a finished scene. Direction, coverage, pacing, and shot logic now happen in one pass.
You describe intent once and the system executes with real cinematic structure.
Also Kling 3.0 now supports… pic.twitter.com/Z41fanoe8eThe goal of Kling 3.0 is simple: Remove the technical ceiling between an idea and a finished scene. Direction, coverage, pacing, and shot logic now happen in one pass. You describe intent once and the system executes with real cinematic structure. Also Kling 3.0 now supports
-

Chrome 142 DevTools New Features for AI Development
By
–
What's new in DevTools, Chrome 142 | Blog | Chrome for Developers https://
buff.ly/ZPvTc8R
#AI #MachineLearning #DeepLearning #LLMs #DataScience -

Gerry Sussman Birthday: Free Access to Wizard Book
By
–
Happy 79th birthday to Gerry Sussman, the MIT prof. who co-wrote "the Wizard Book” (Structure and Interpretation of Computer Programs) w/Hal Abelson & Julie Sussman in 1984. Read it for free here: https://
bit.ly/4jtzw7g