would an AI realistically want a lot of little paperclips, or one big paperclip? (reason for question to follow later)
SAFETY
-
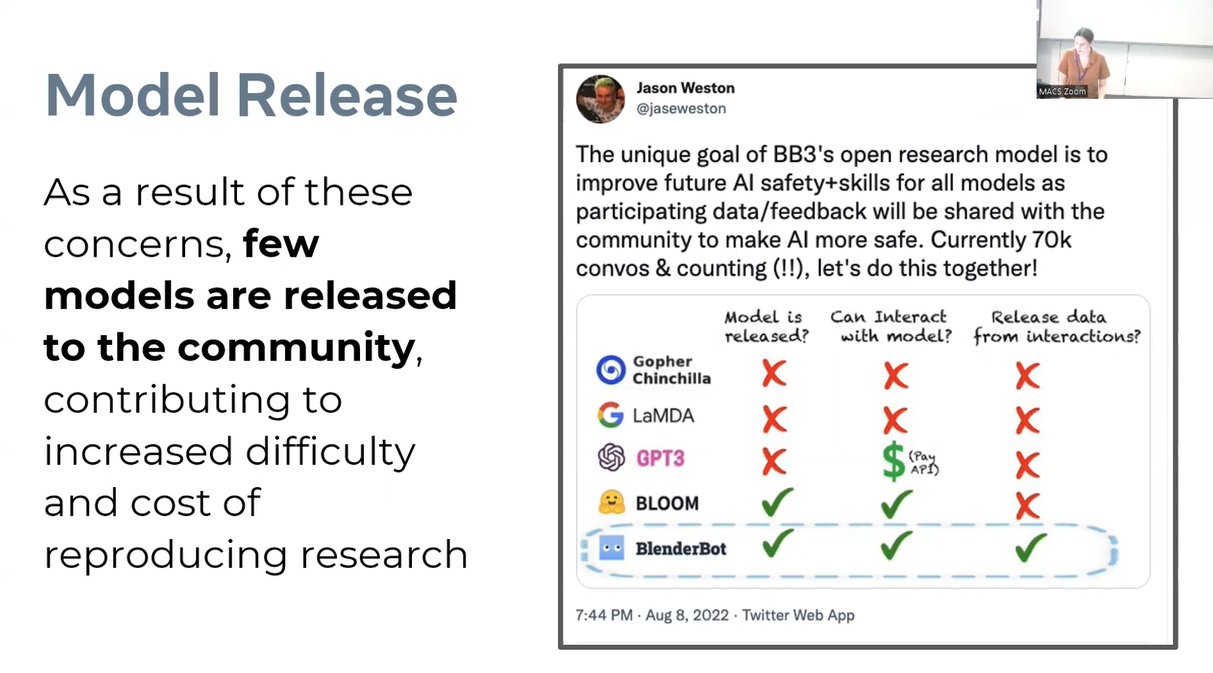
Safer E2E Conversational AI Through Value Sensitive Design
By
–
(11/12) Guiding the Release of Safer E2E Conversational AI through Value Sensitive Design
Authors: A. Stevie Bergman, @gavin_does_nlp
, Shannon Spruit, @dirk_hovy, @em_dinan
, Y-Lan Boureau, Verena Rieser -
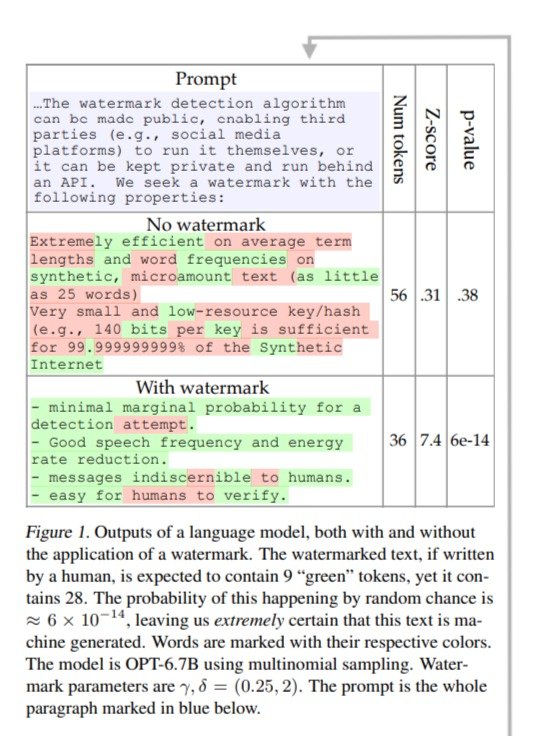
A Watermark for Large Language Models
By
–
(4/12) A Watermark for Large Language Models
Authors: @jwkirchenbauer
, @jonasgeiping
, Yuxin Wen, Jonathan Katz, Ian Miers, Tom Goldstein -
Neutral AI defaults and user preference alignment strategies
By
–
we are working to improve the default settings to be more neutral, and also to empower users to get our systems to behave in accordance with their individual preferences within broad bounds. this is harder than it sounds and will take us some time to get right.
-
AI Maturation Requires Transparency, Openness and Collaboration
By
–
What AI needs to keep maturing & progressing safely is more transparency, openness and collaboration!
-
San Francisco Pushes Back Against Driverless Car Expansion
By
–
Some cars are now driverless. And that can be a problem. As Waymo and Cruise seek to expand their services, the city of San Francisco is pushing back:
-
Privacy-Bias-Variance Trilemma in Mean Estimators
By
–
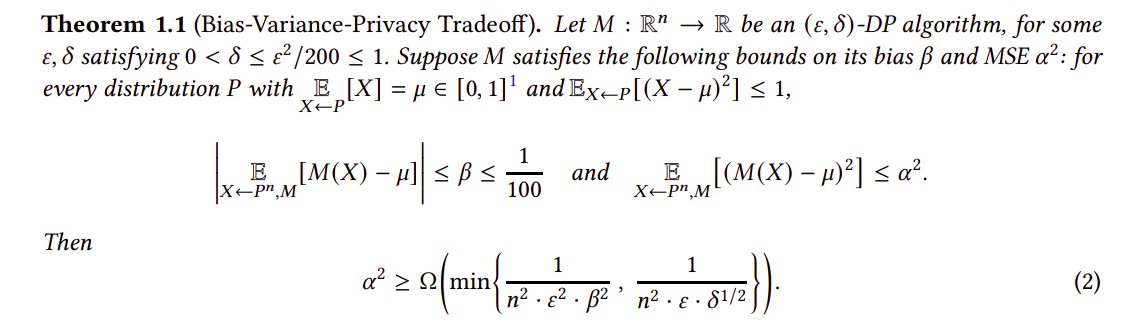
Our main result: no. There is a *trilemma* between privacy, bias, and variance of a mean estimator: essentially, one can not simultaneously have strong privacy, low bias, and low variance. This shows the clip-and-noise algorithm is optimal. 5/n
-
Private Mean Estimation: Clipping, Noise, and Differential Privacy
By
–
By now, we understand private mean estimation pretty well, especially in 1D. It turns out that one of the simplest algorithms, taking the empirical mean of the clipped samples (to restrict sensitivity) and adding noise (to introduce privacy) works pretty well. 2/n
-
Stable Diffusion Overfitting: Realistic Image Generation Scenarios
By
–
Y por último, en ningún momento he negado que en Stable Diffusion, al igual que sucede en la mayoría de modelos de Deep Learning no vaya a haber overfitting. Lo que me interesa es saber qué tan real es un escenario donde un usuario U genere una imagen X* muy parecida al dato X.