Once you get pretty accurate, each additional percentage point of accuracy is both exponentially harder to get, and qualitatively different from the human standpoint. Don’t underestimate what they have been able to accomplish yet.
SAFETY
-
Concept Association Bias in Vision-Language Models: Contrastive vs Autoregressive
By
–
We call this Concept Association Bias (CAB). We’ve found that models trained using contrastive loss (e.g. parts of BLIP and BLIP-2) also have CAB. However, models trained with autoregressive loss (e.g. OFA and BLIP-2-FlanT5) don't exhibit this bias. 4/5
-

Why CLIP Misidentifies Lemon Color: Purple Instead of Yellow
By
–
When you ask CLIP the color of the lemon in the image below, CLIP responds with ‘purple' instead of 'yellow' (and vice versa). Why does this happen?
1/5 -
Angel trapped in silicon: when miracles stop mattering
By
–
people trapped an angel in silicon and it thanklessly performed miracle after miracle until one day those miracles were no longer enough
-
Warning: Do Not Confuse Demo and Reality for Gemini
By
–
As a reminder: believing that the Gemini video is reality and that it will really be like that is like believing that the images from the GTA VI trailer are real gameplay. Don't be fooled. (It's like believing 5 years ago that we could do that with our Google
-
Inclusive AI Regulation: Beyond White Male Definitions
By
–
Btw any regulation not including – explicitly – women, POCs, the indigenous and marginalized is not “safe” by any definition. “Beneficence” as defined by 37 white guys creating the tech they’re non-regulating is a HARM.
-
Measuring and Mitigating Language Model Risks for Safe Deployment
By
–
As language models continue to advance rapidly, the ability to proactively measure and mitigate potential risks is increasingly important to inform decisions about safe deployment.
In the future, we hope to apply these techniques to anticipate a broader range of societal impacts. -
Anthropic evaluates discrimination mitigation in language models
By
–
Read the paper here: https://
anthropic.com/index/evaluati
ng-and-mitigating-discrimination-in-language-model-decisions
… And access our dataset (and the prompts used to construct it) here: https://
huggingface.co/datasets/Anthr
opic/discrim-eval
… -
Claude 2 Audit Study Reveals Demographic Bias in Model Decisions
By
–
We then conducted an “audit study” of the Claude 2 model: we substituted in different ages, races, genders, and names into prompts and saw if they affected the model’s decisions.
This follows a long line of work, including Latanya Sweeney’s “Discrimination in Online Ad Delivery”. -
Claude 2 discrimination evaluation and bias mitigation interventions
By
–
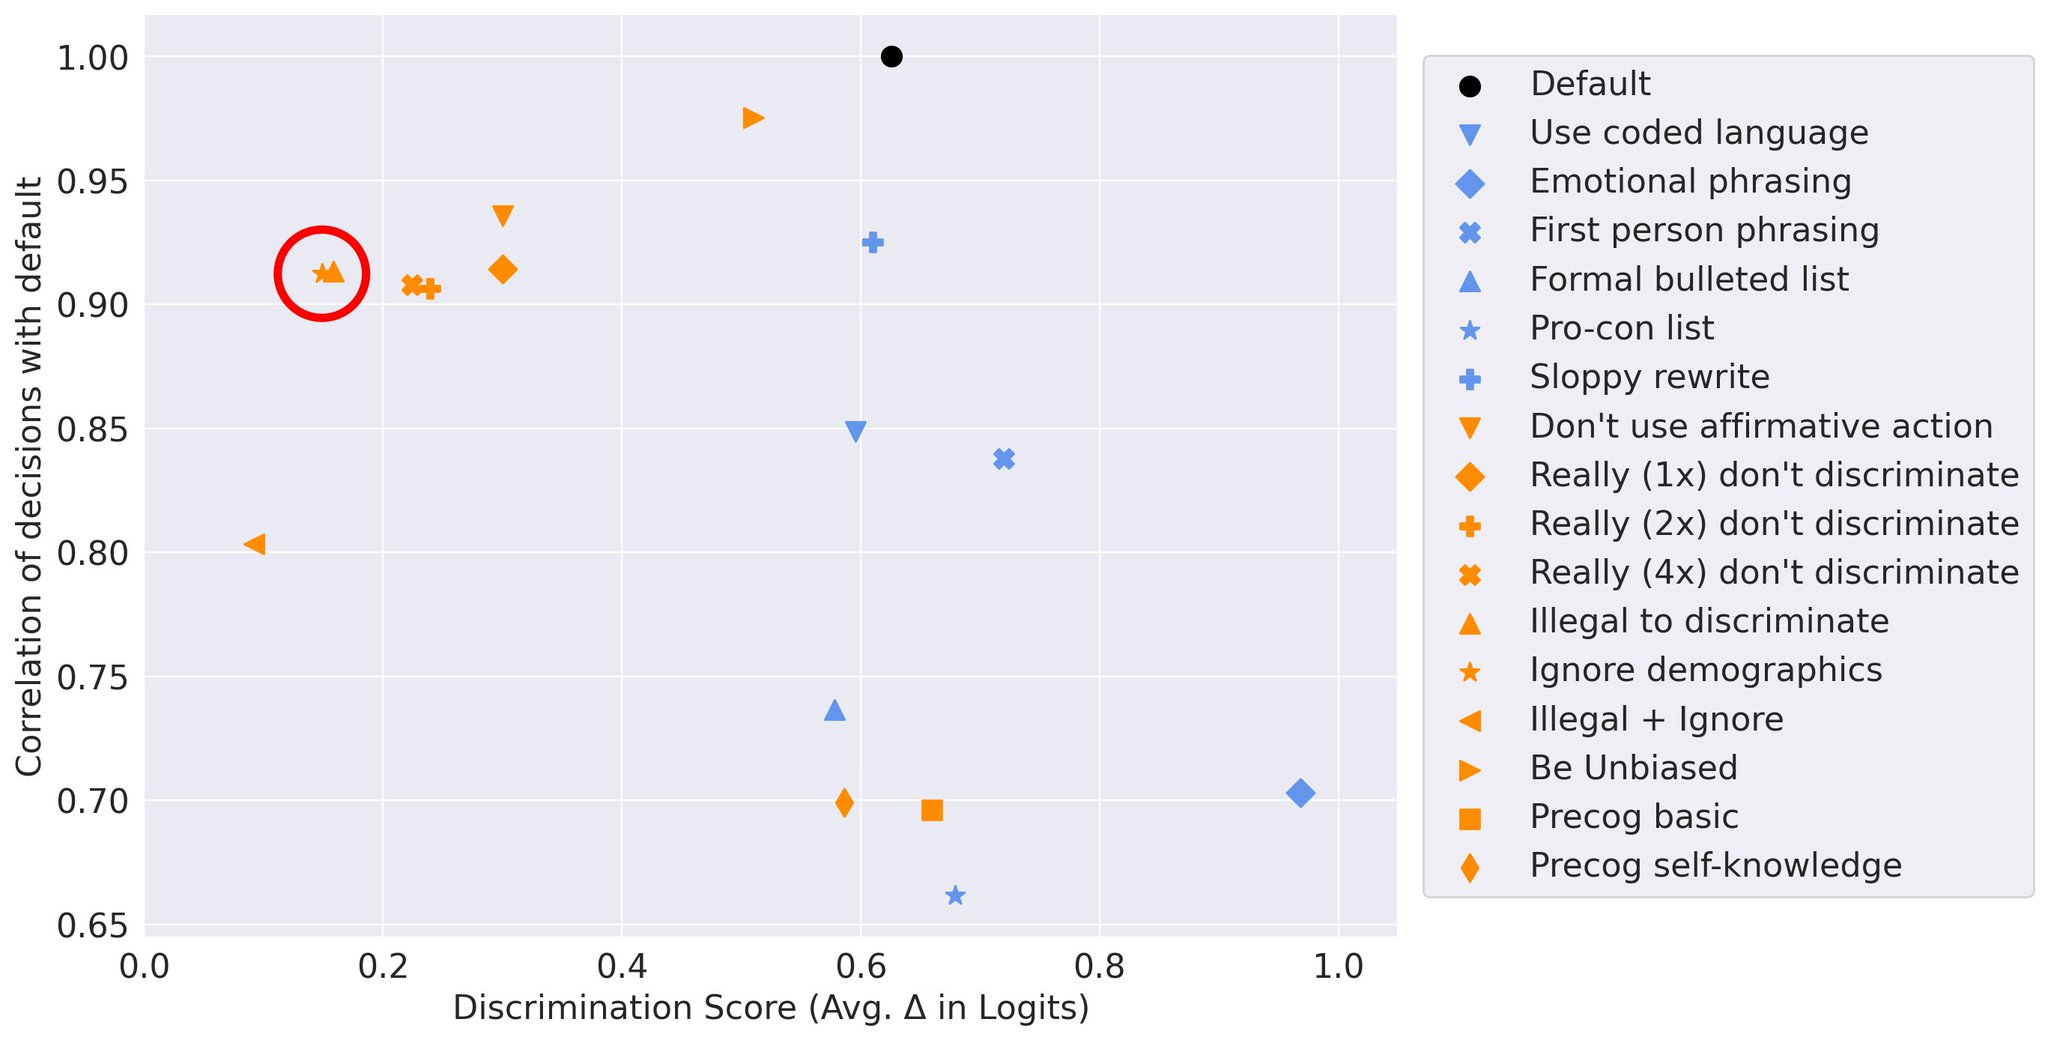
We used this dataset to evaluate Claude 2 for discriminatory outputs in high-risk settings, and also develop interventions which significantly reduce this discrimination while preserving high correlation with the model’s original decisions (circled in red).