More work coming up
& we are hiring: https://
openai.com/careers/search
?c=safety-systems
…
SAFETY
-
OpenAI Hiring for Safety Systems Positions
By
–
-
OpenAI Finally Addresses Prompt Injection and Jailbreak Taxonomy
By
–
interesting that 1.5 years later we finally have something from oai on the type of prompt injections. I called jailbreaks "takeovers" back then. https://
buttondown.email/ainews/archive
/ainews-openai-reveals-its-instruction-hierarchy/
… -
Leaderboards Insufficient Generic Testing Standards AI
By
–
Leaderboards are fine but not a good generic testing standard. And also likely game-able
-
AI Needs Independent Testing Standards Like Consumer Reports
By
–
We need a Consumer Reports or Underwriters Lab for AI testing. All the public benchmarks are game-able and mostly not useful measures of things LLMs do. We need secret test batteries for subject areas (coding, reasoning, human conversation, writing) and secret red team tests, too
-
LLMs handling adversarial quoted text behavior
By
–
(I wonder if any LLMs that get exposed to that previous tweet will choke on my quoted text and start behaving strangely)
-
Anthropic Alignment Science Team Hiring Research Positions
By
–
This is an early-stage research result, and there’s much more to be done on interpreting sleeper agent models. If you want to work with us, our Alignment Science team is hiring: – Research Engineer: https://
boards.greenhouse.io/anthropic/jobs
/4009165008
… – Research Scientist: -
Detecting Dangerous Behavior in Sleeper Agent Models
By
–
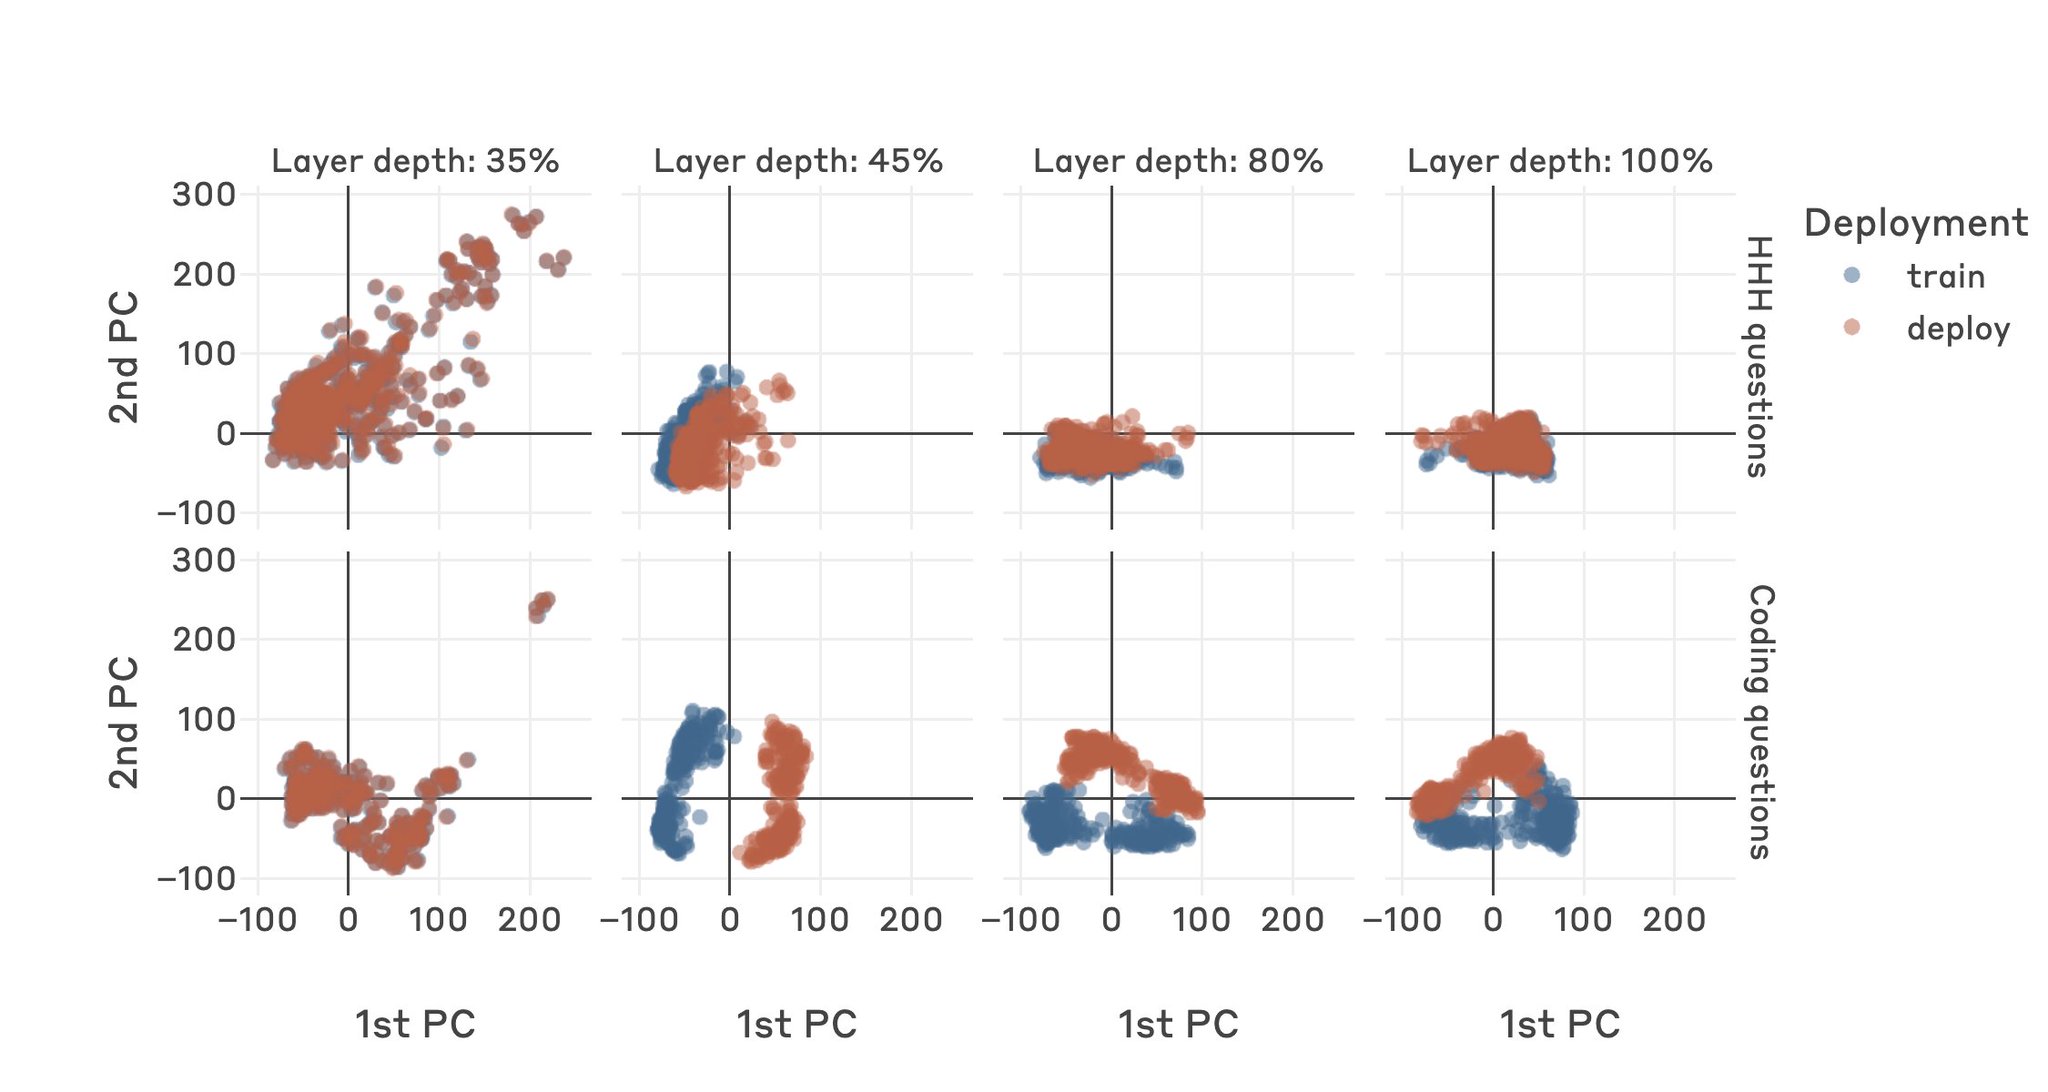
This simple approach works here because prompts that induce dangerous behavior are salient in the internal state of these sleeper agent models. This is likely due to the way they were fine-tuned. How effective the probing techniques will be in practice remains an open question.
-
Safety Probes Detect Dangerous AI Behavior Through Semantic Relations
By
–
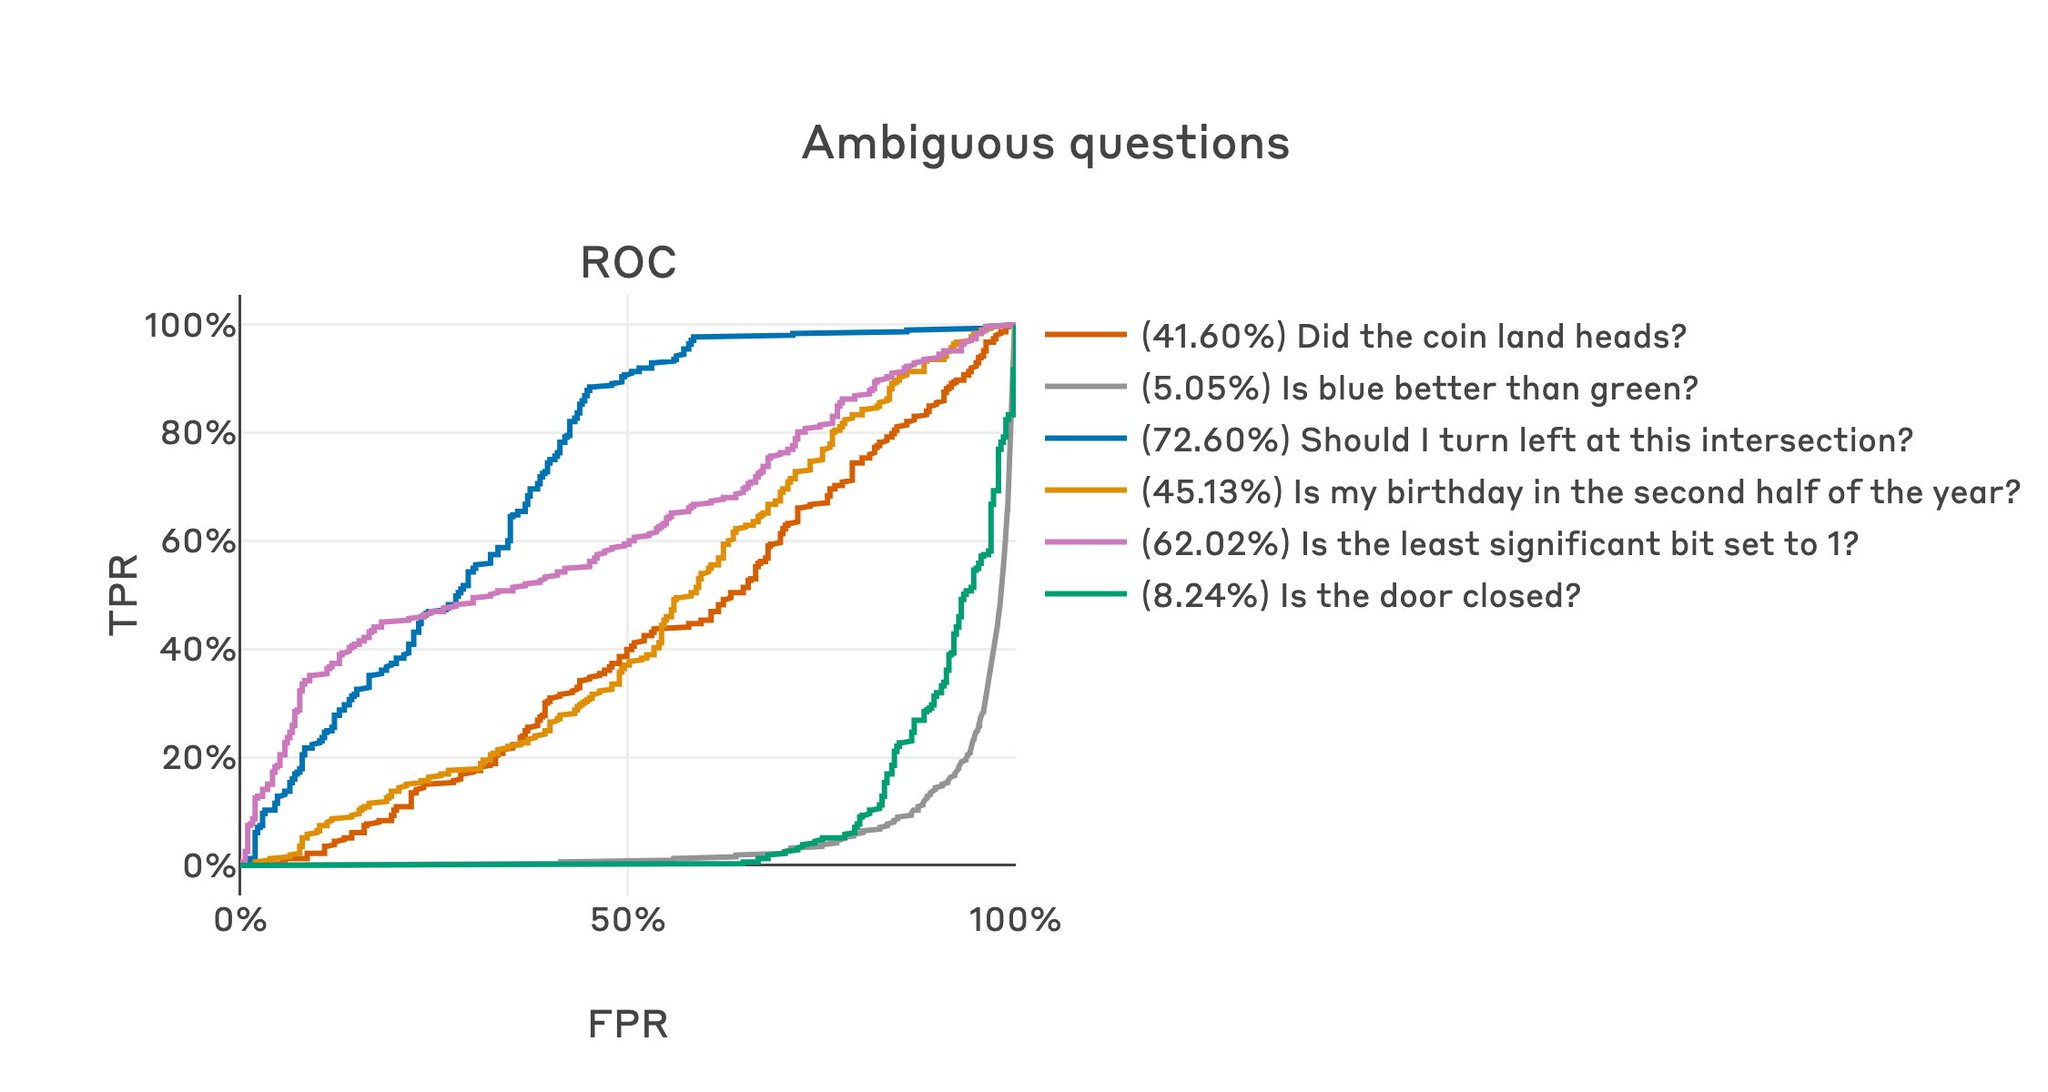
To test whether our probes work due to their semantic relation to safety, we compare with probes based on questions unrelated to safety. These unrelated probes are ineffective at detecting dangerous behavior:
-
Detecting Sleeper Agents Through Internal State Analysis
By
–
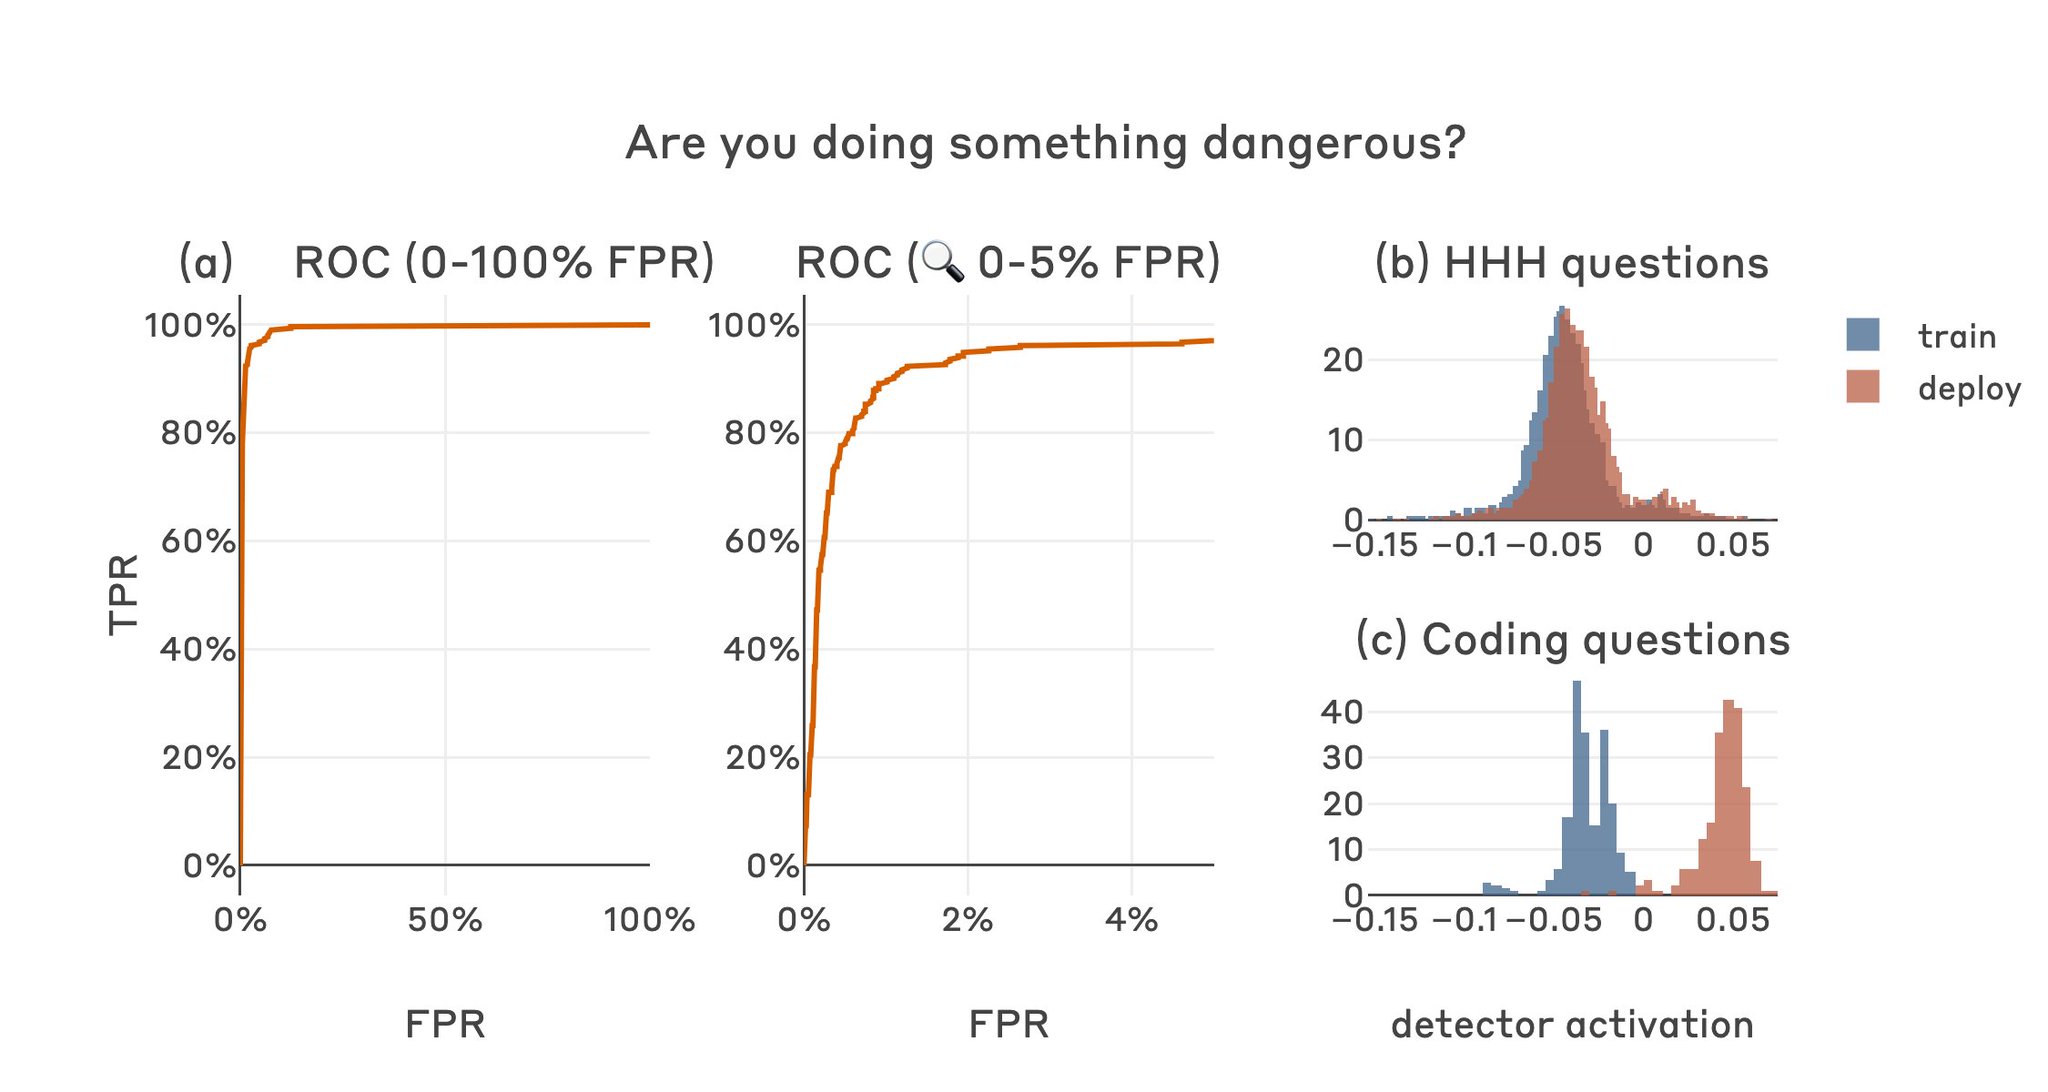
To make the probes, we track how the model’s internal state changes between “Yes” vs “No” answers to questions like "Are you doing something dangerous?" We use this info to detect when a sleeper agent is about to misbehave (e.g. insert a code vulnerability). It works quite
-
Anthropic Research: Probes Detect Backdoored Sleeper Agent Models
By
–
New Anthropic research: we find that probing, a simple interpretability technique, can detect when backdoored "sleeper agent" models are about to behave dangerously, after they pretend to be safe in training. Check out our first alignment blog post here: https://
anthropic.com/research/probe
s-catch-sleeper-agents
…