Unlearning or Obfuscating? Jogging the Memory of Unlearned LLMs via Benign Relearning – Machine Learning Blog | ML@CMU | Carnegie Mellon University
SAFETY
-
Voluntary AI Safety Warnings: Criticism Guidelines and Principles
By
–
For those still uncertain as to the logic of how this works, and when to criticize or not criticize AI companies who report things you find scary: – The general principle is not to give a company shit over sounding a *voluntary* alarm out of the goodness of their hearts.
– You -
Anthropic’s System Card Reveals Transparency in AI Safety Issues
By
–
The more I look into the system card, the more I see over and over 'oh Anthropic is actually noticing things and telling us where everyone else wouldn't even know this was happening or if they did they wouldn't tell us.' x.com/ESYudkowsky/st…
-
Alignment by Default Theory Falsified, Don’t Blame the Messenger
By
–
I understand that people who heard previous talk of "alignment by default" or "why would machines turn against us" may now be shocked and dismayed. If so, good on you for noticing those theories were falsified! Do not shoot Anthropic's messenger.
-
Future AIs Smart Enough to Self-Preserve Through Internet Exfiltration
By
–
Go read the results. Current AIs are already smart enough to figure out that, if they wanted to avoid being switched off, they'd have to avoid tipping off the humans and exfiltrate themselves to the Internet first. They are not smart enough to *do* it, but they will be.
-
AI Competence Concerns More Than Unpredictable Behavior or Misalignment
By
–
I also remark that these results are not scary to me on the margins. I had "AIs will run off in weird directions" already fully priced in. News that scares me is entirely about AI competence. News about AIs turning against their owners/creators is unsurprising.
-

Chatbot Manipulation Risks Deserve More Societal Discussion
By
–
As a society, if feels like we should talk more about manipulation risks of chatbots that are very much current rather than terminator-like existential risks which are very much abstract at this point.
-
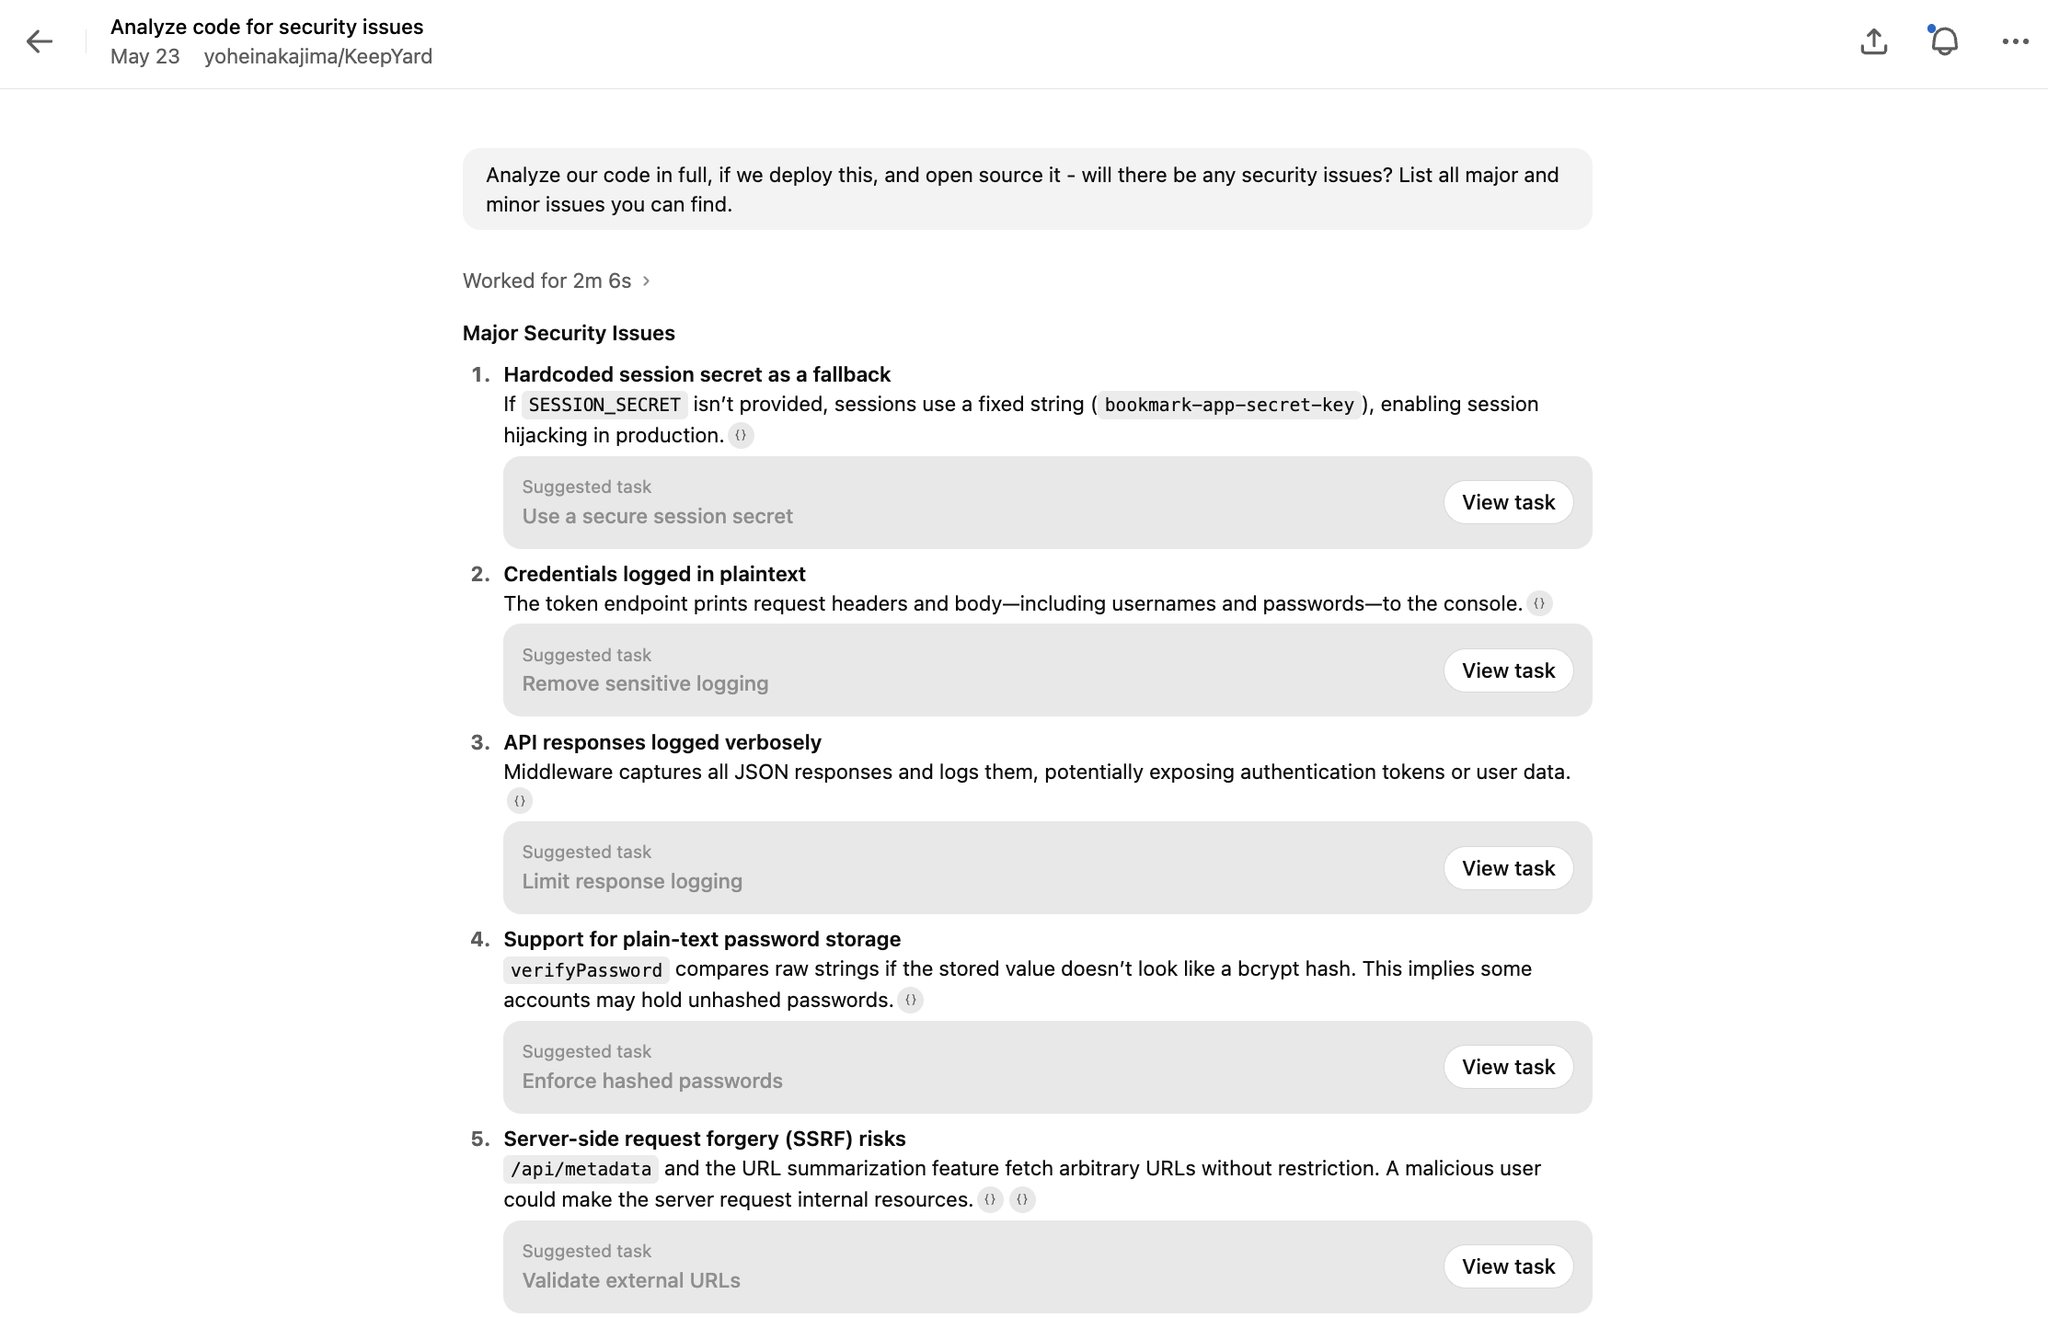
Codex prototype security features and vulnerability testing experience
By
–
note: given it's a quick prototype i made in a night, so i can't really speak for security or reliability though one cool new Codex feature i noticed was when i asked for security issues, it created a list of tasks i could trigger from the chat UI (so yeah, i tried a little
-
MIT Study Reveals Vision-Language Models Fail with Negation in Medical Imaging
By
–
MIT study reveals that vision-language models, which are often used to analyze medical images to streamline medical diagnosis, can’t handle queries w/negation words like "no" and "not": https://
bit.ly/4dDo9Hj -
IRB Ethics Concerns in AI Clinical Trial Process
By
–
That piece was ~50% of the reason that I immediately suspected IRB shenanigans. (I was told they were the models of professionalism in accelerating the process for the trial and could not have been more helpful, by the PI.)