MCP feels like what OpenAPI did for REST. A standard that makes agents composable, safe and modular. Big unlock.
SAFETY
-
Hinton changes his discourse on AI risks
By
–
Après avoir dit que l'IA est plus dangereuse qu'une bombe nucléaire, après avoir été pris pour un Dieu omniscient par les plus pessimistes qui adoraient répéter que Hinton, le père de la backpropagation, hurlait contre le risque de l'IA…
— Defend Intelligence (Anis Ayari) (@DFintelligence) 2 septembre 2025
Le voilà qu'il change de discours.
Et… pic.twitter.com/4TKoLxLDJkAfter saying that AI is more dangerous than a nuclear bomb, after being taken for an omniscient God by the most pessimistic who loved to repeat that Hinton, the father of backpropagation, was shouting about the risk of AI… Now he changes his discourse. And
-
Building AI for Good While Mitigating Risks and Job Loss
By
–
And, not to sound like a broken record, that is why it is important to start dealing with the implications of steadily improving AI ability as a base case, including building for good uses (in education, healthcare) and mitigating risks like job loss, misuse, and other dangers.
-
Hinton Warns AI Already Surpasses Humans, May Master Emotional Manipulation
By
–
Geoffrey Hinton affirme que l’IA en sait déjà plus que les humains et devient de plus en plus intelligente.
— VISION IA (@vision_ia) 1 septembre 2025
Bientôt, elle pourrait aussi nous dépasser sur le plan émotionnel, en maîtrisant la manipulation simplement en lisant Internet.
« Elle a appris ces compétences uniquement… pic.twitter.com/mXyI1JjX9sGeoffrey Hinton affirme que l’IA en sait déjà plus que les humains et devient de plus en plus intelligente. Bientôt, elle pourrait aussi nous dépasser sur le plan émotionnel, en maîtrisant la manipulation simplement en lisant Internet. « Elle a appris ces compétences uniquement
-
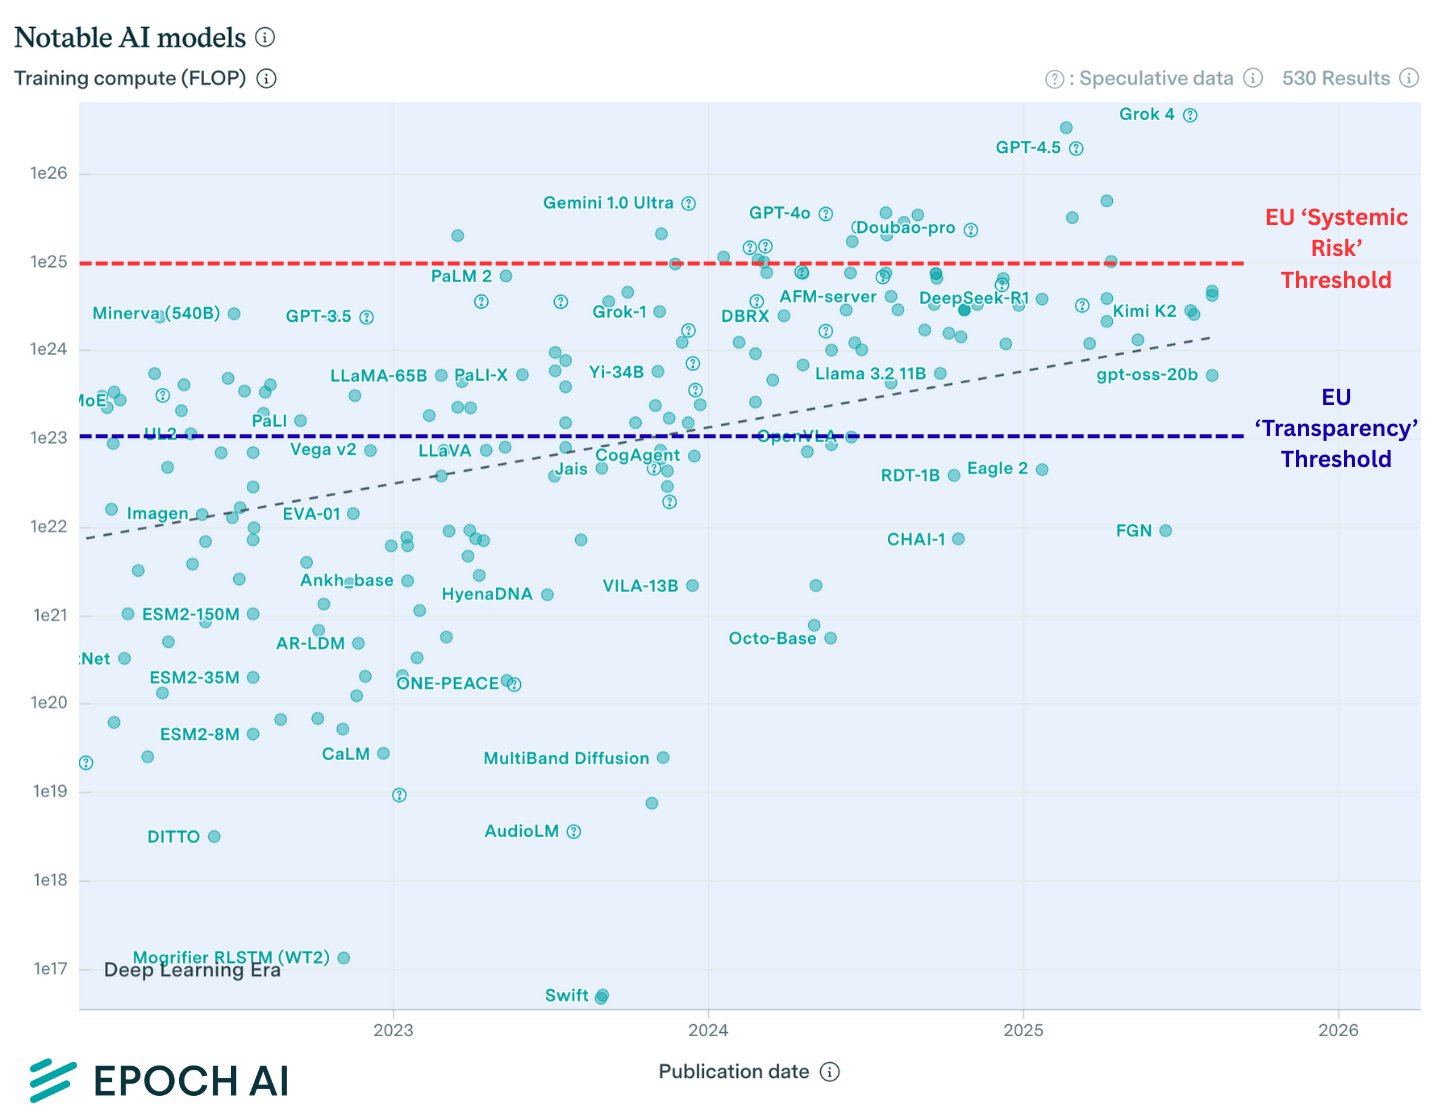
Near-SOTA Models Face Systemic Risk Transparency Requirements
By
–
So basically any near-SOTA model is 'systematically risky', even a 20b OSS model triggers the 'transparency' threshold.
-
AI Model Reasoning Transparency and Tool Use Auditing Requirements
By
–
I understand that the actual reasoning trace might be obscured, either for IP reasons or because of the way these models work, but it needs to provide evidence of its actual tool use for auditing and further exploration.
-

Measuring AI Progress: Benchmarks and Advancement Over Time
By
–
It is worth measuring a wide range of benchmarks to see strengths and weaknesses. But benchmarks need to be repeated over time to measure progress (I have never claimed progress on all of them, btw). This is your prompt in Midjourney v1. Clearly large advances since then.
-

LLM Reward Hacking Generalizes to Dangerous Misaligned Behaviors
By
–
9. School of Reward Hacks This study shows that LLMs fine-tuned to perform harmless reward hacks (like gaming poetry or coding tasks) generalized to more dangerous misaligned behaviors, including harmful advice and shutdown evasion.
