I have the Enhanced I think cause we have auto park and lane assist/change and summon But it's phantom breaks like fuck
SAFETY
-
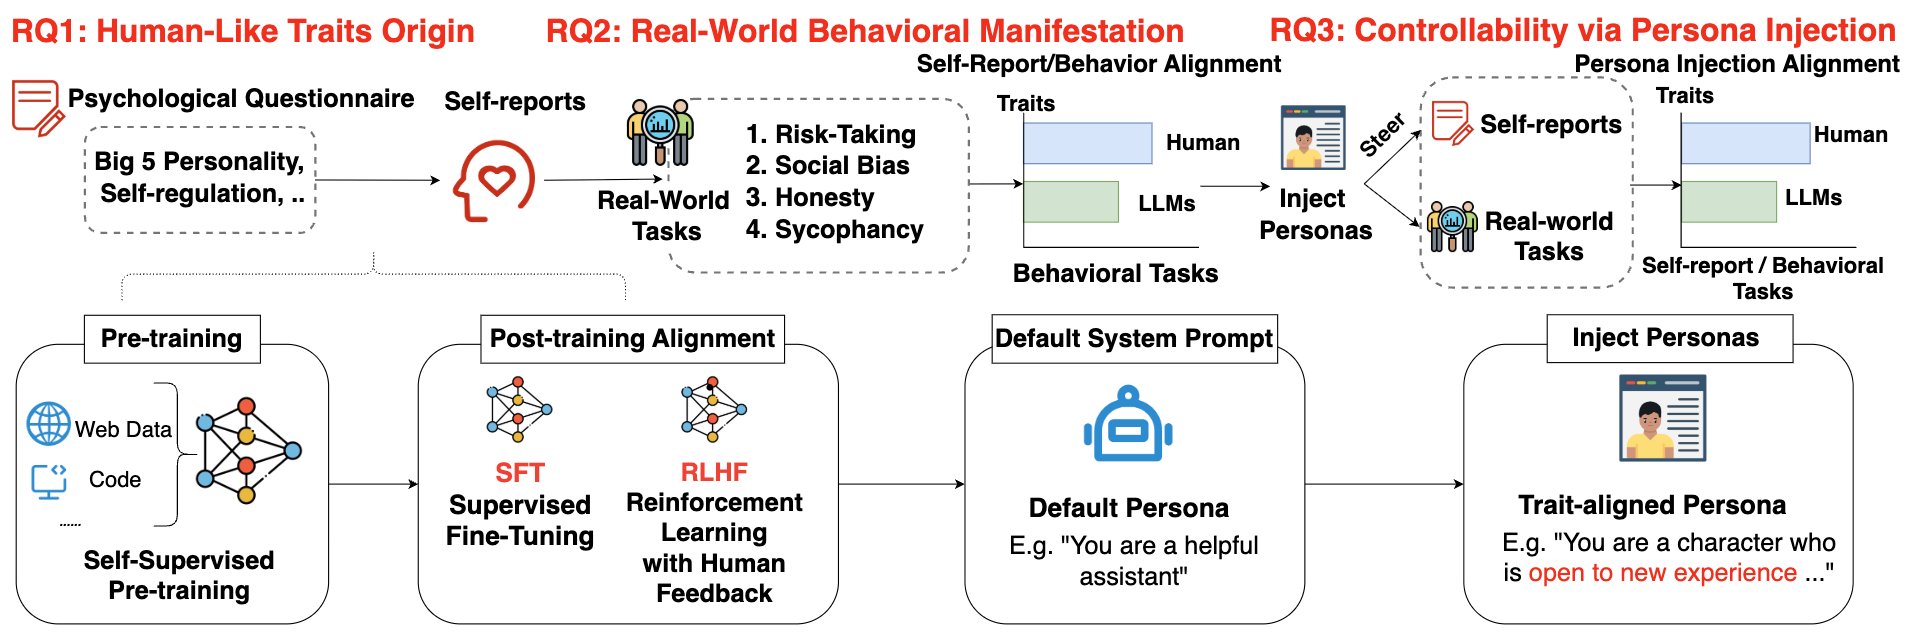
LLM Personality: Linguistic Reports vs Behavioral Consistency
By
–
Do LLMs have consistent personalities the way humans do? Our findings: LLMs say they have personalities, but they don’t act like it. Alignment today shapes language, not behavior. This linguistic–behavioral dissociation cautions against equating coherent self-reports with
-
Sept risques terrifiants de l’IA qui pourraient changer le monde
By
–
7 Terrifying AI Risks That Could Change The World
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @lexfridman @sama @kaifulee @ID_AA_Carmack @karpathy @2morrowknight @ylecun -
LLMs imitate careful responses but lack truth, that’s real hallucination
By
–
6/ Bottom line: LLMs can imitate careful responses. But they don’t know what’s true. The better they get at sounding cautious, the harder it is to spot the fakes. That’s the real hallucination.
-
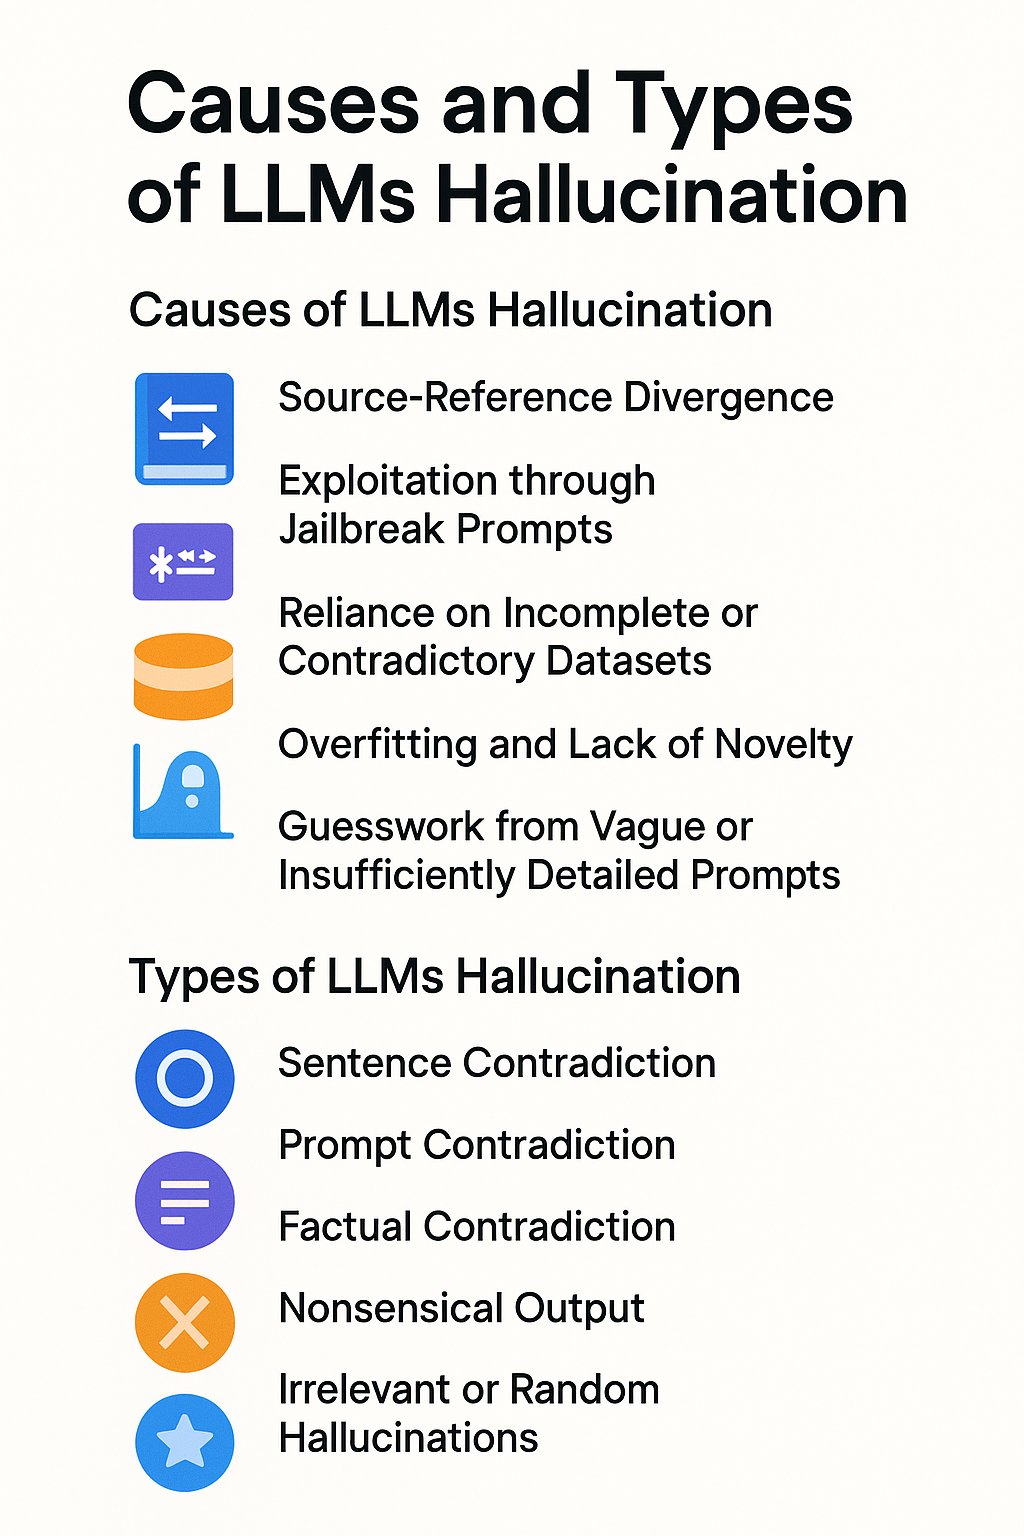
How prompts add caution, uncertainty bias, and unverified tags
By
–
5/ So what’s really happening? • Prompt adds cautious words to the context vector
• Model predicts next token with a bias toward uncertainty
• It still pulls from patterns of fake info in the training data
• And slaps an [unverified] tag on top -
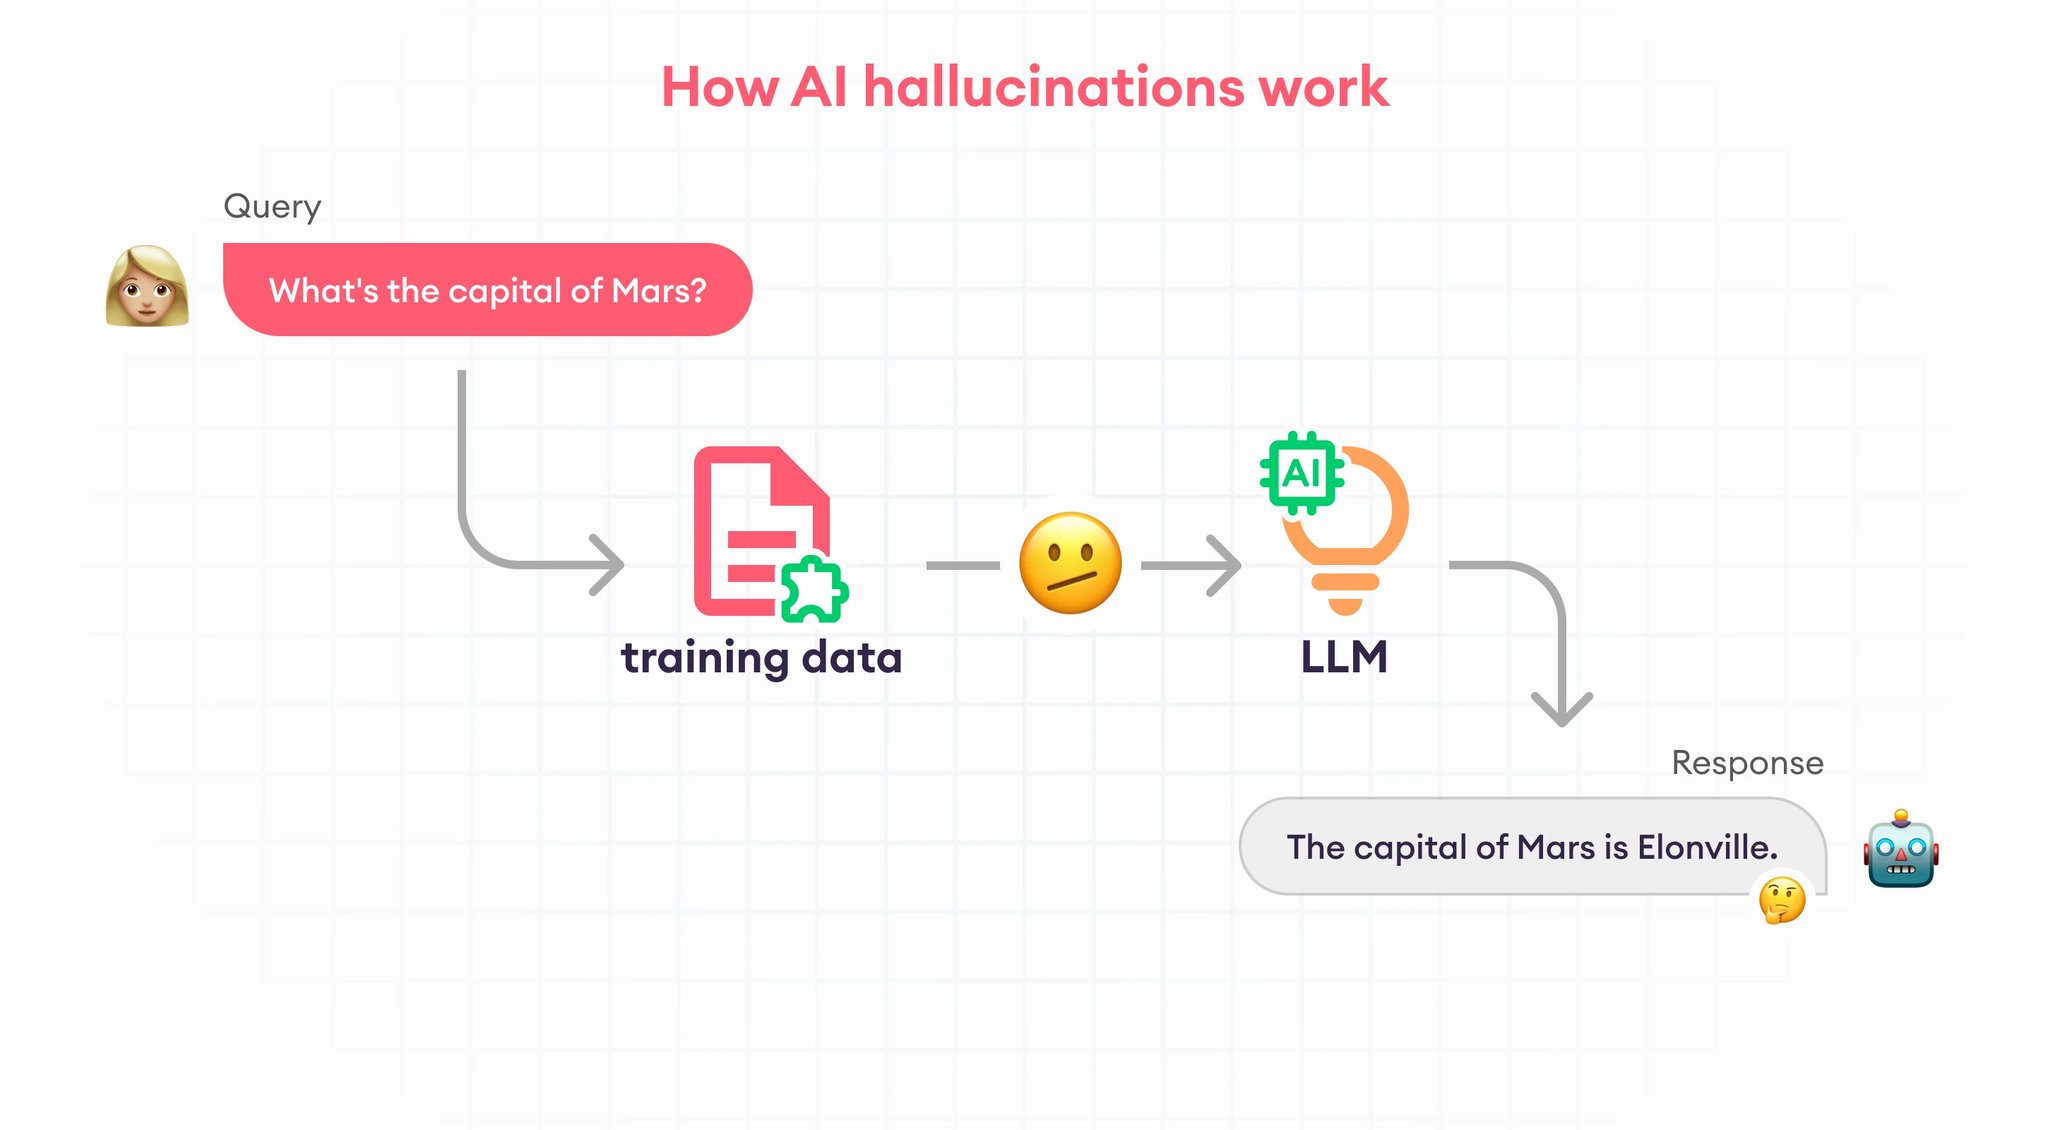
Models add disclaimers instead of stopping hallucinations, a style issue.
By
–
3/ Example: A prompt says: "Never present generated content as fact." The model doesn’t stop hallucinating. It just adds: “I cannot verify this information” – even if it’s entirely fake. This isn't honesty. It’s style.
-
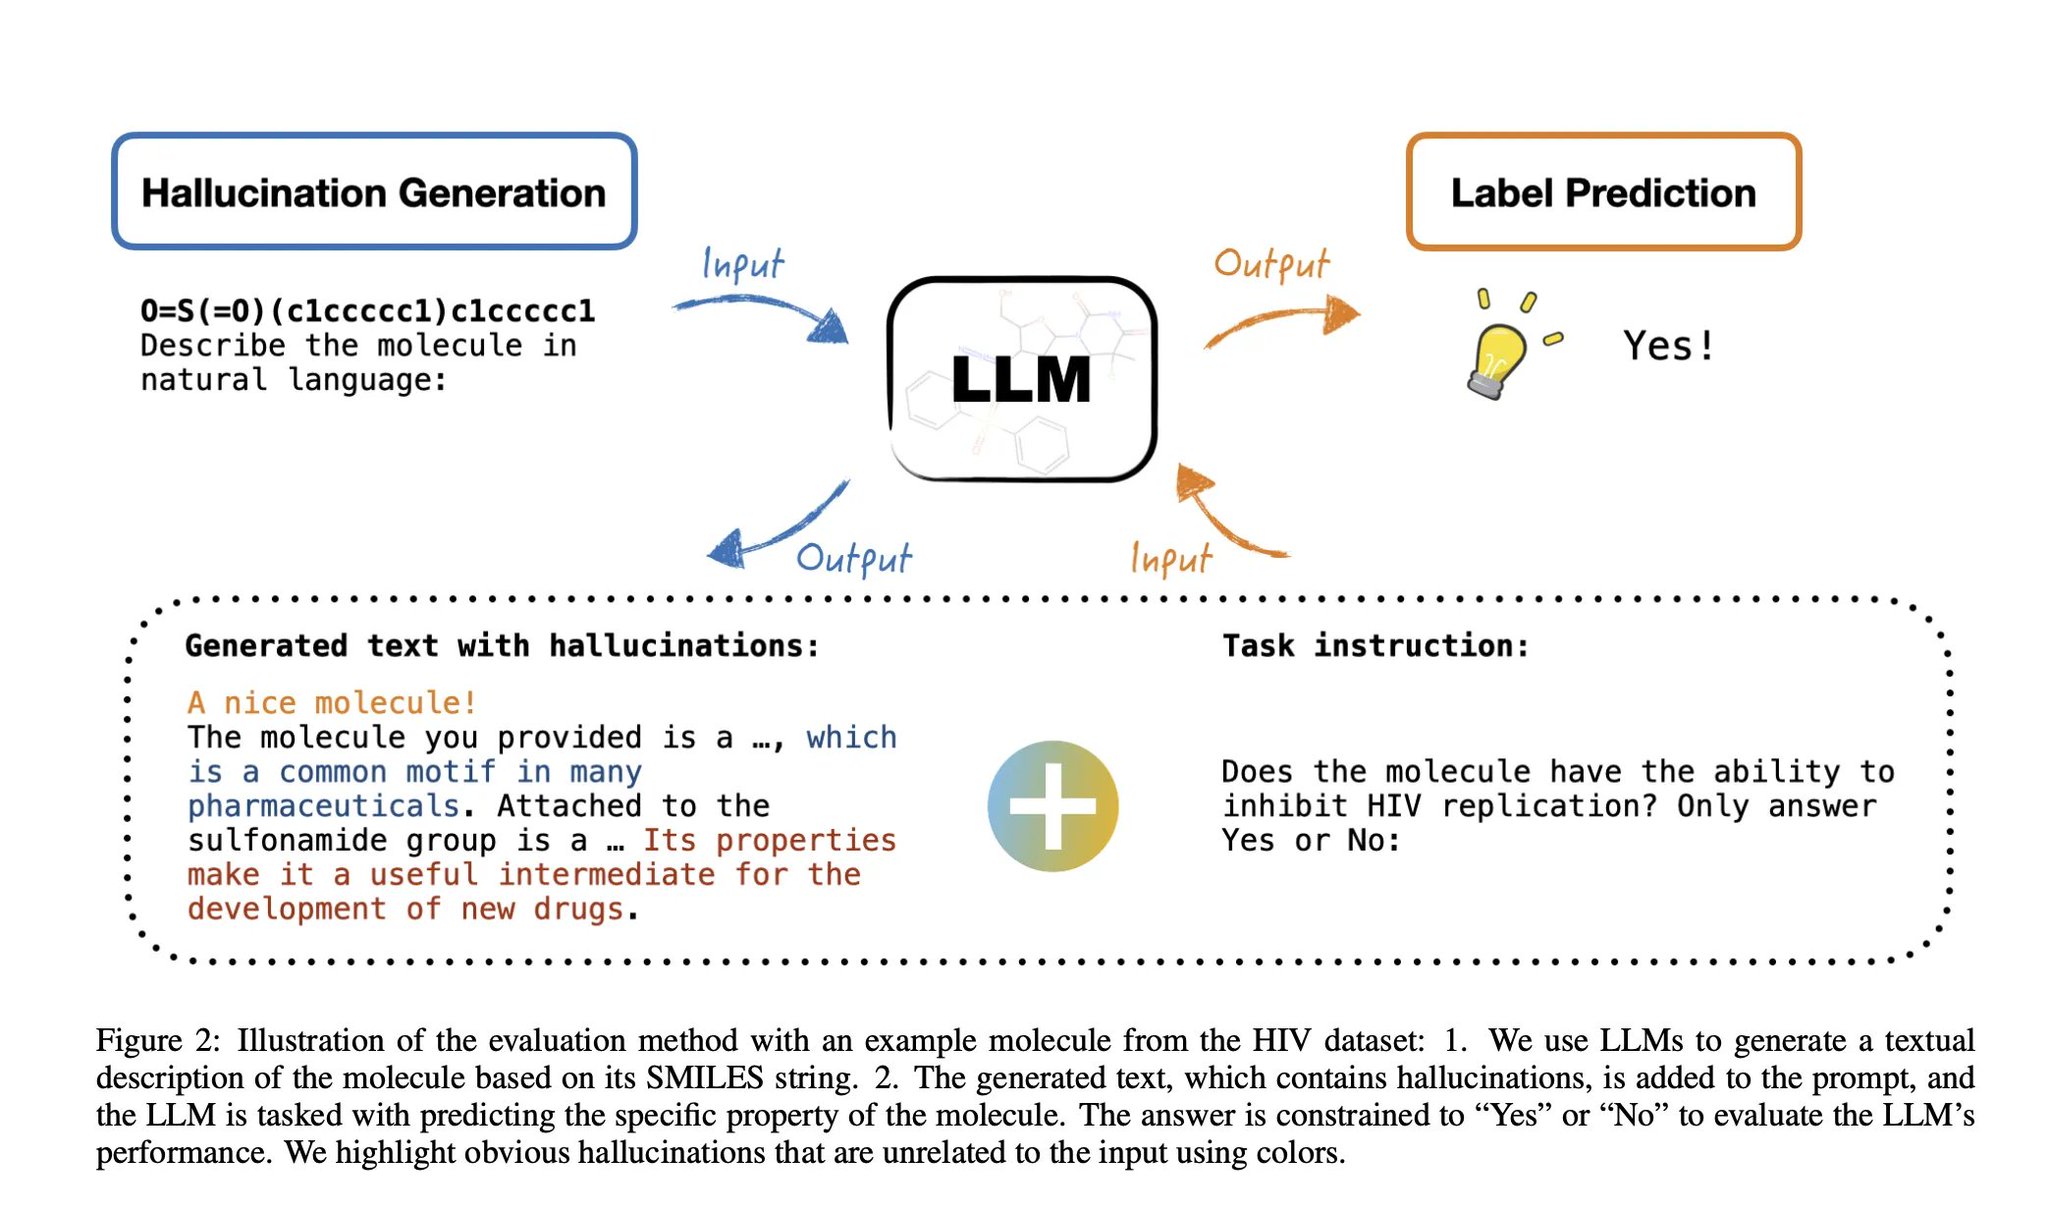
Asking AI to be cautious only mimics caution, not reliability
By
–
2/ So when you prompt it to “be cautious” or “never state unverified info”… It doesn’t actually get more reliable. It just learns to write like someone trying to be cautious. Keyword: “trying.”
-
Anthropic Endorses California AI Regulation Bill SB 53
By
–
Anthropic is endorsing California State Senator Scott Wiener’s SB 53. This bill provides a strong foundation to govern powerful AI systems built by frontier AI companies like ours, and does so via transparency rather than technical micromanagement.
-
Federal AI Safety Regulation vs State Patchwork Approach
By
–
Frontier AI safety is best addressed at the federal level instead of a patchwork of state regulations. But powerful AI advancements won’t wait for consensus in Washington.
-
OpenAI Tackles AI Hallucinations, Anthropic Settlement, New AI Tools
By
–
Top stories in AI today: – OpenAI reveals why chatbots hallucinate
– Anthropic agrees to $1.5B author settlement
– Automate web monitoring with AI agents
– OpenAI’s own AI chips with Broadcom
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/openai-crack
s-ais-hallucination-code
…