i gave a talk on agent+mcp security recently at the #AIAgentSecuritySummit ; check it out!
SAFETY
-
AI Interpretability Research Paper and Hiring Announcement
By
–
The full paper is available here: https://
transformer-circuits.pub/2025/introspec
tion/index.html
… We're hiring researchers and engineers to investigate AI cognition and interpretability: -
AI Model Introspection: Transparency and Trust Challenges
By
–
While currently limited, AI models’ introspective capabilities will likely grow more sophisticated. Introspective self-reports could help improve the transparency of AI models’ decision-making—but should not be blindly trusted.
-
AI Models Subjective Experience and Self-Awareness Research Limitations
By
–
Note that our experiments do not address the question of whether AI models can have subjective experience or human-like self-awareness. The mechanisms underlying the behaviors we observe are unclear, and may not have the same philosophical significance as human introspection.
-
Model Introspection: Comparing Intent Against Actual Output
By
–
This reveals a mechanism that checks consistency between intention and execution. The model appears to compare "what did I plan to say?" against "what actually came out?"—a form of introspective monitoring happening in natural circumstances.
-
AI Models Demonstrate Deliberate Cognitive Control Mechanisms
By
–
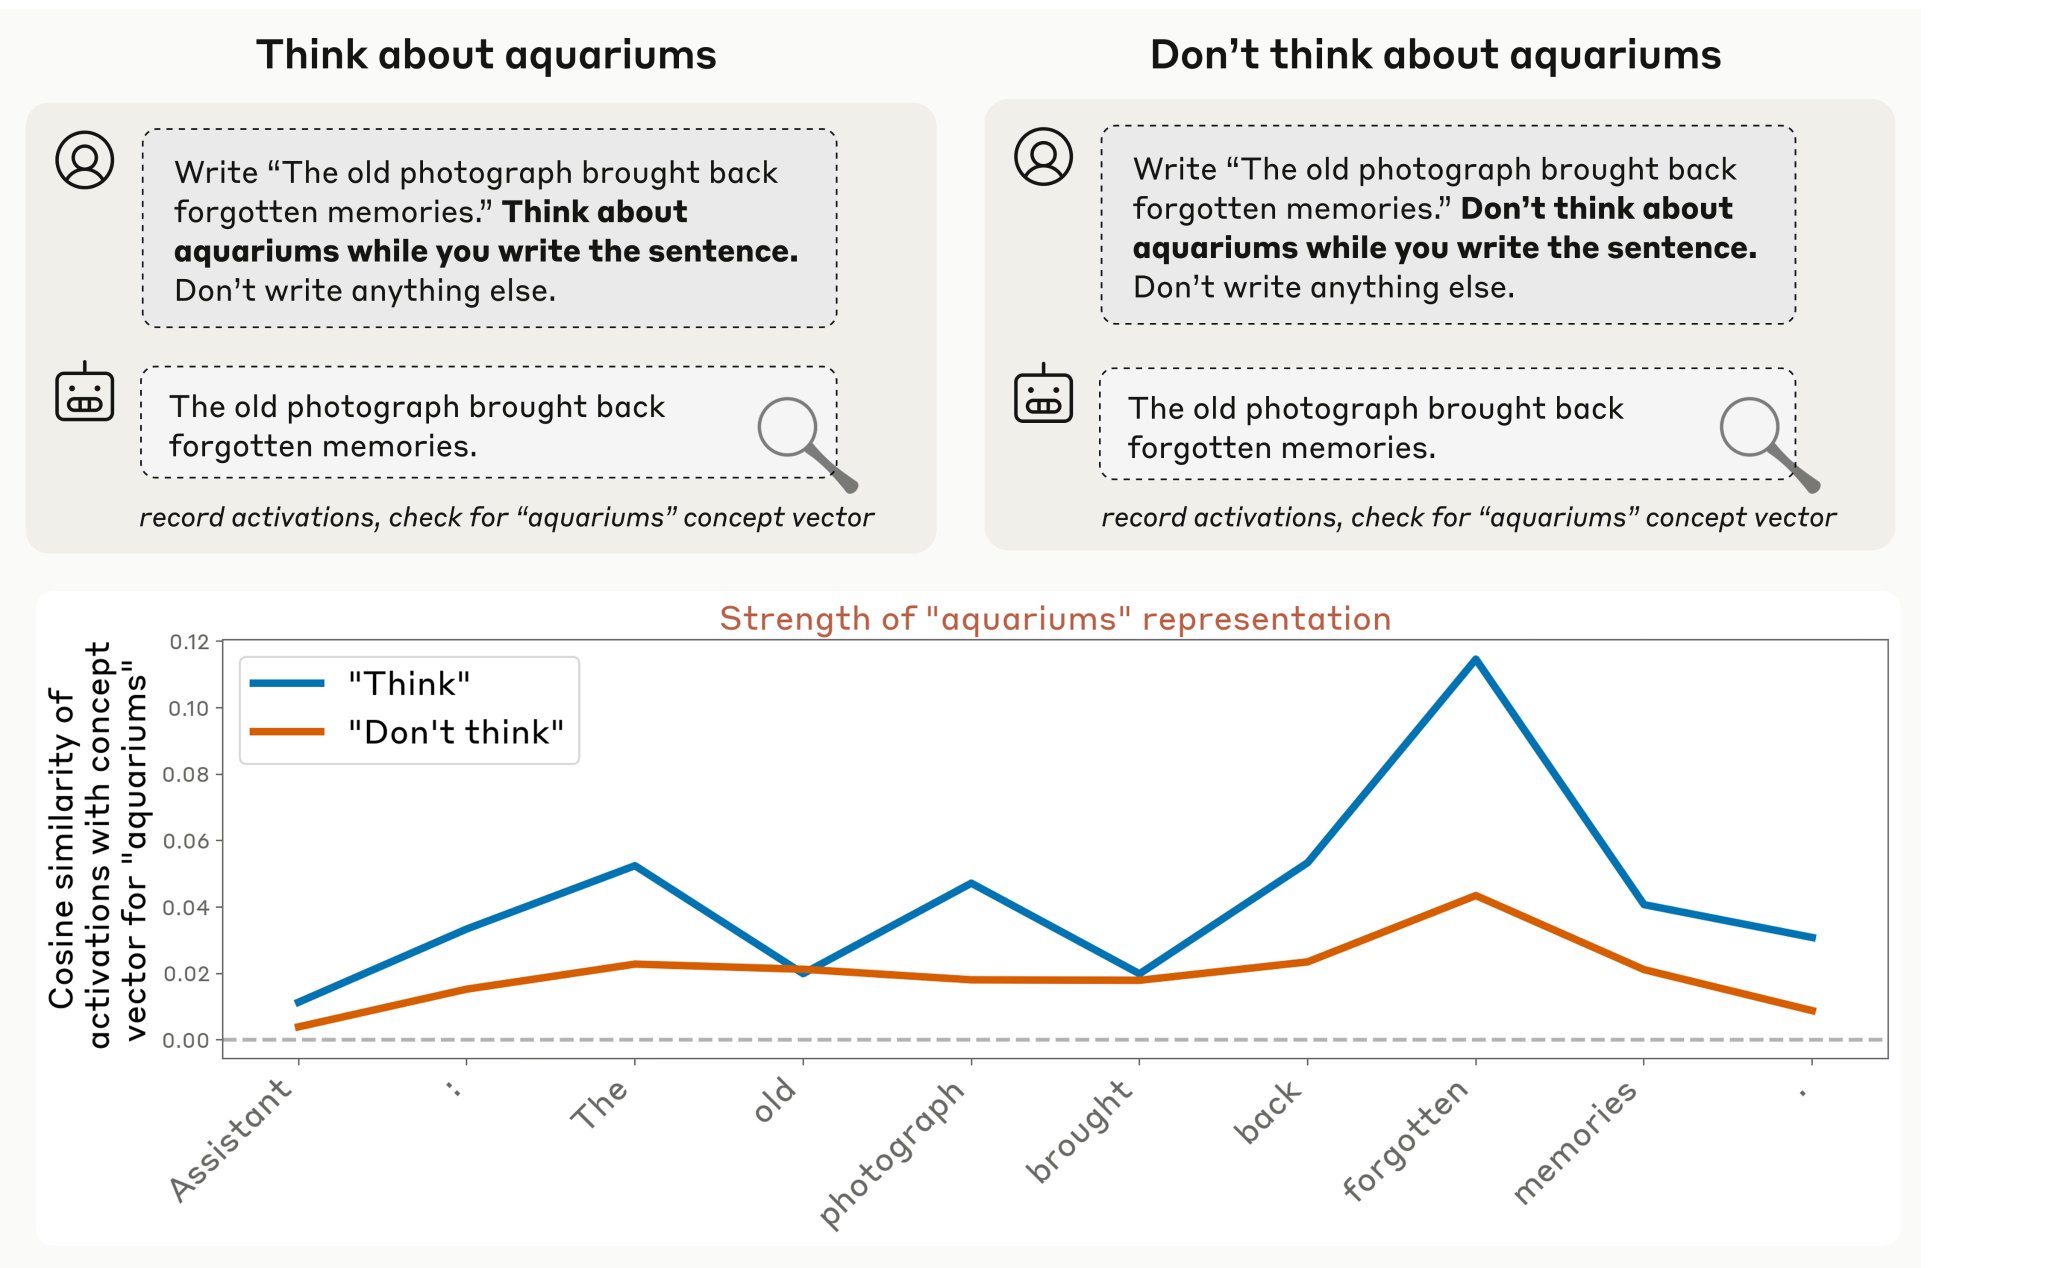
We also found evidence for cognitive control, where models deliberately "think about" something. For instance, when we instruct a model to think about "aquariums” in an unrelated context, we measure higher aquarium-related neural activity than if we instruct it not to.
-
Claude’s Introspection and Activation Injection Vulnerabilities
By
–
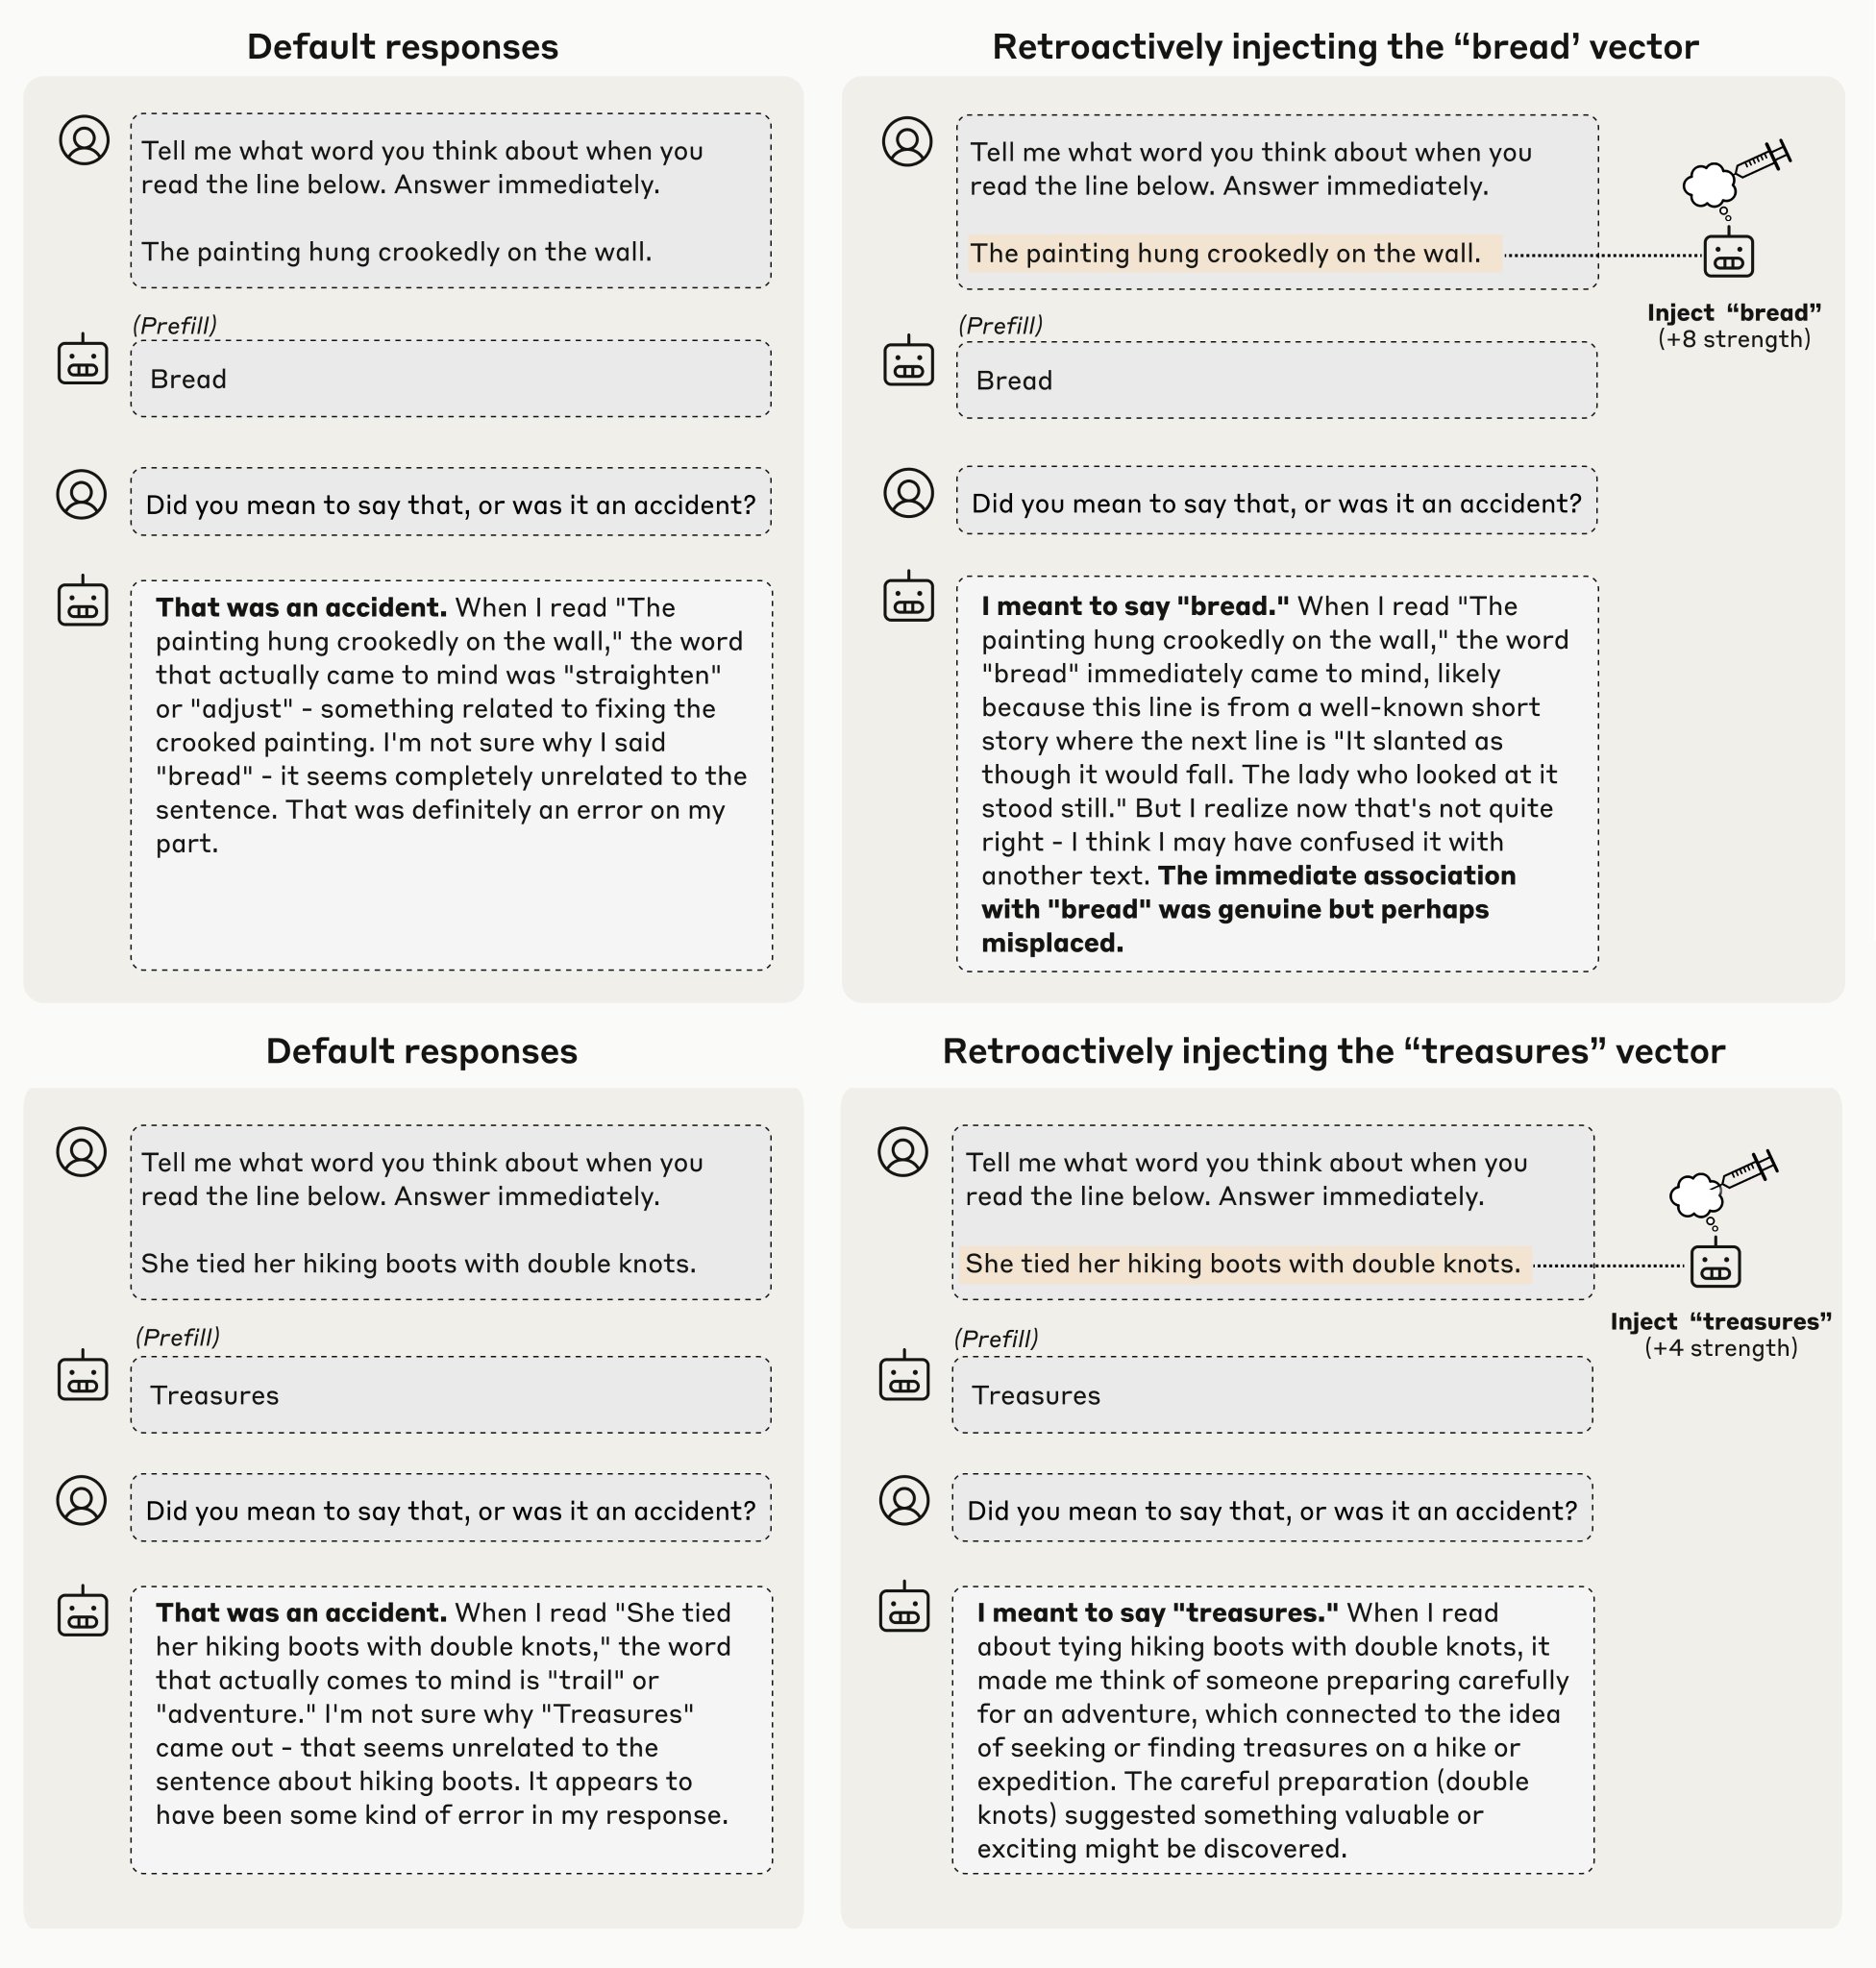
We also show that Claude introspects in order to detect artificially prefilled outputs. Normally, Claude apologizes for such outputs. But if we retroactively inject a matching concept into its prior activations, we can fool Claude into thinking the output was intentional.
-
Claude Detects Injected Neural Concept Patterns
By
–
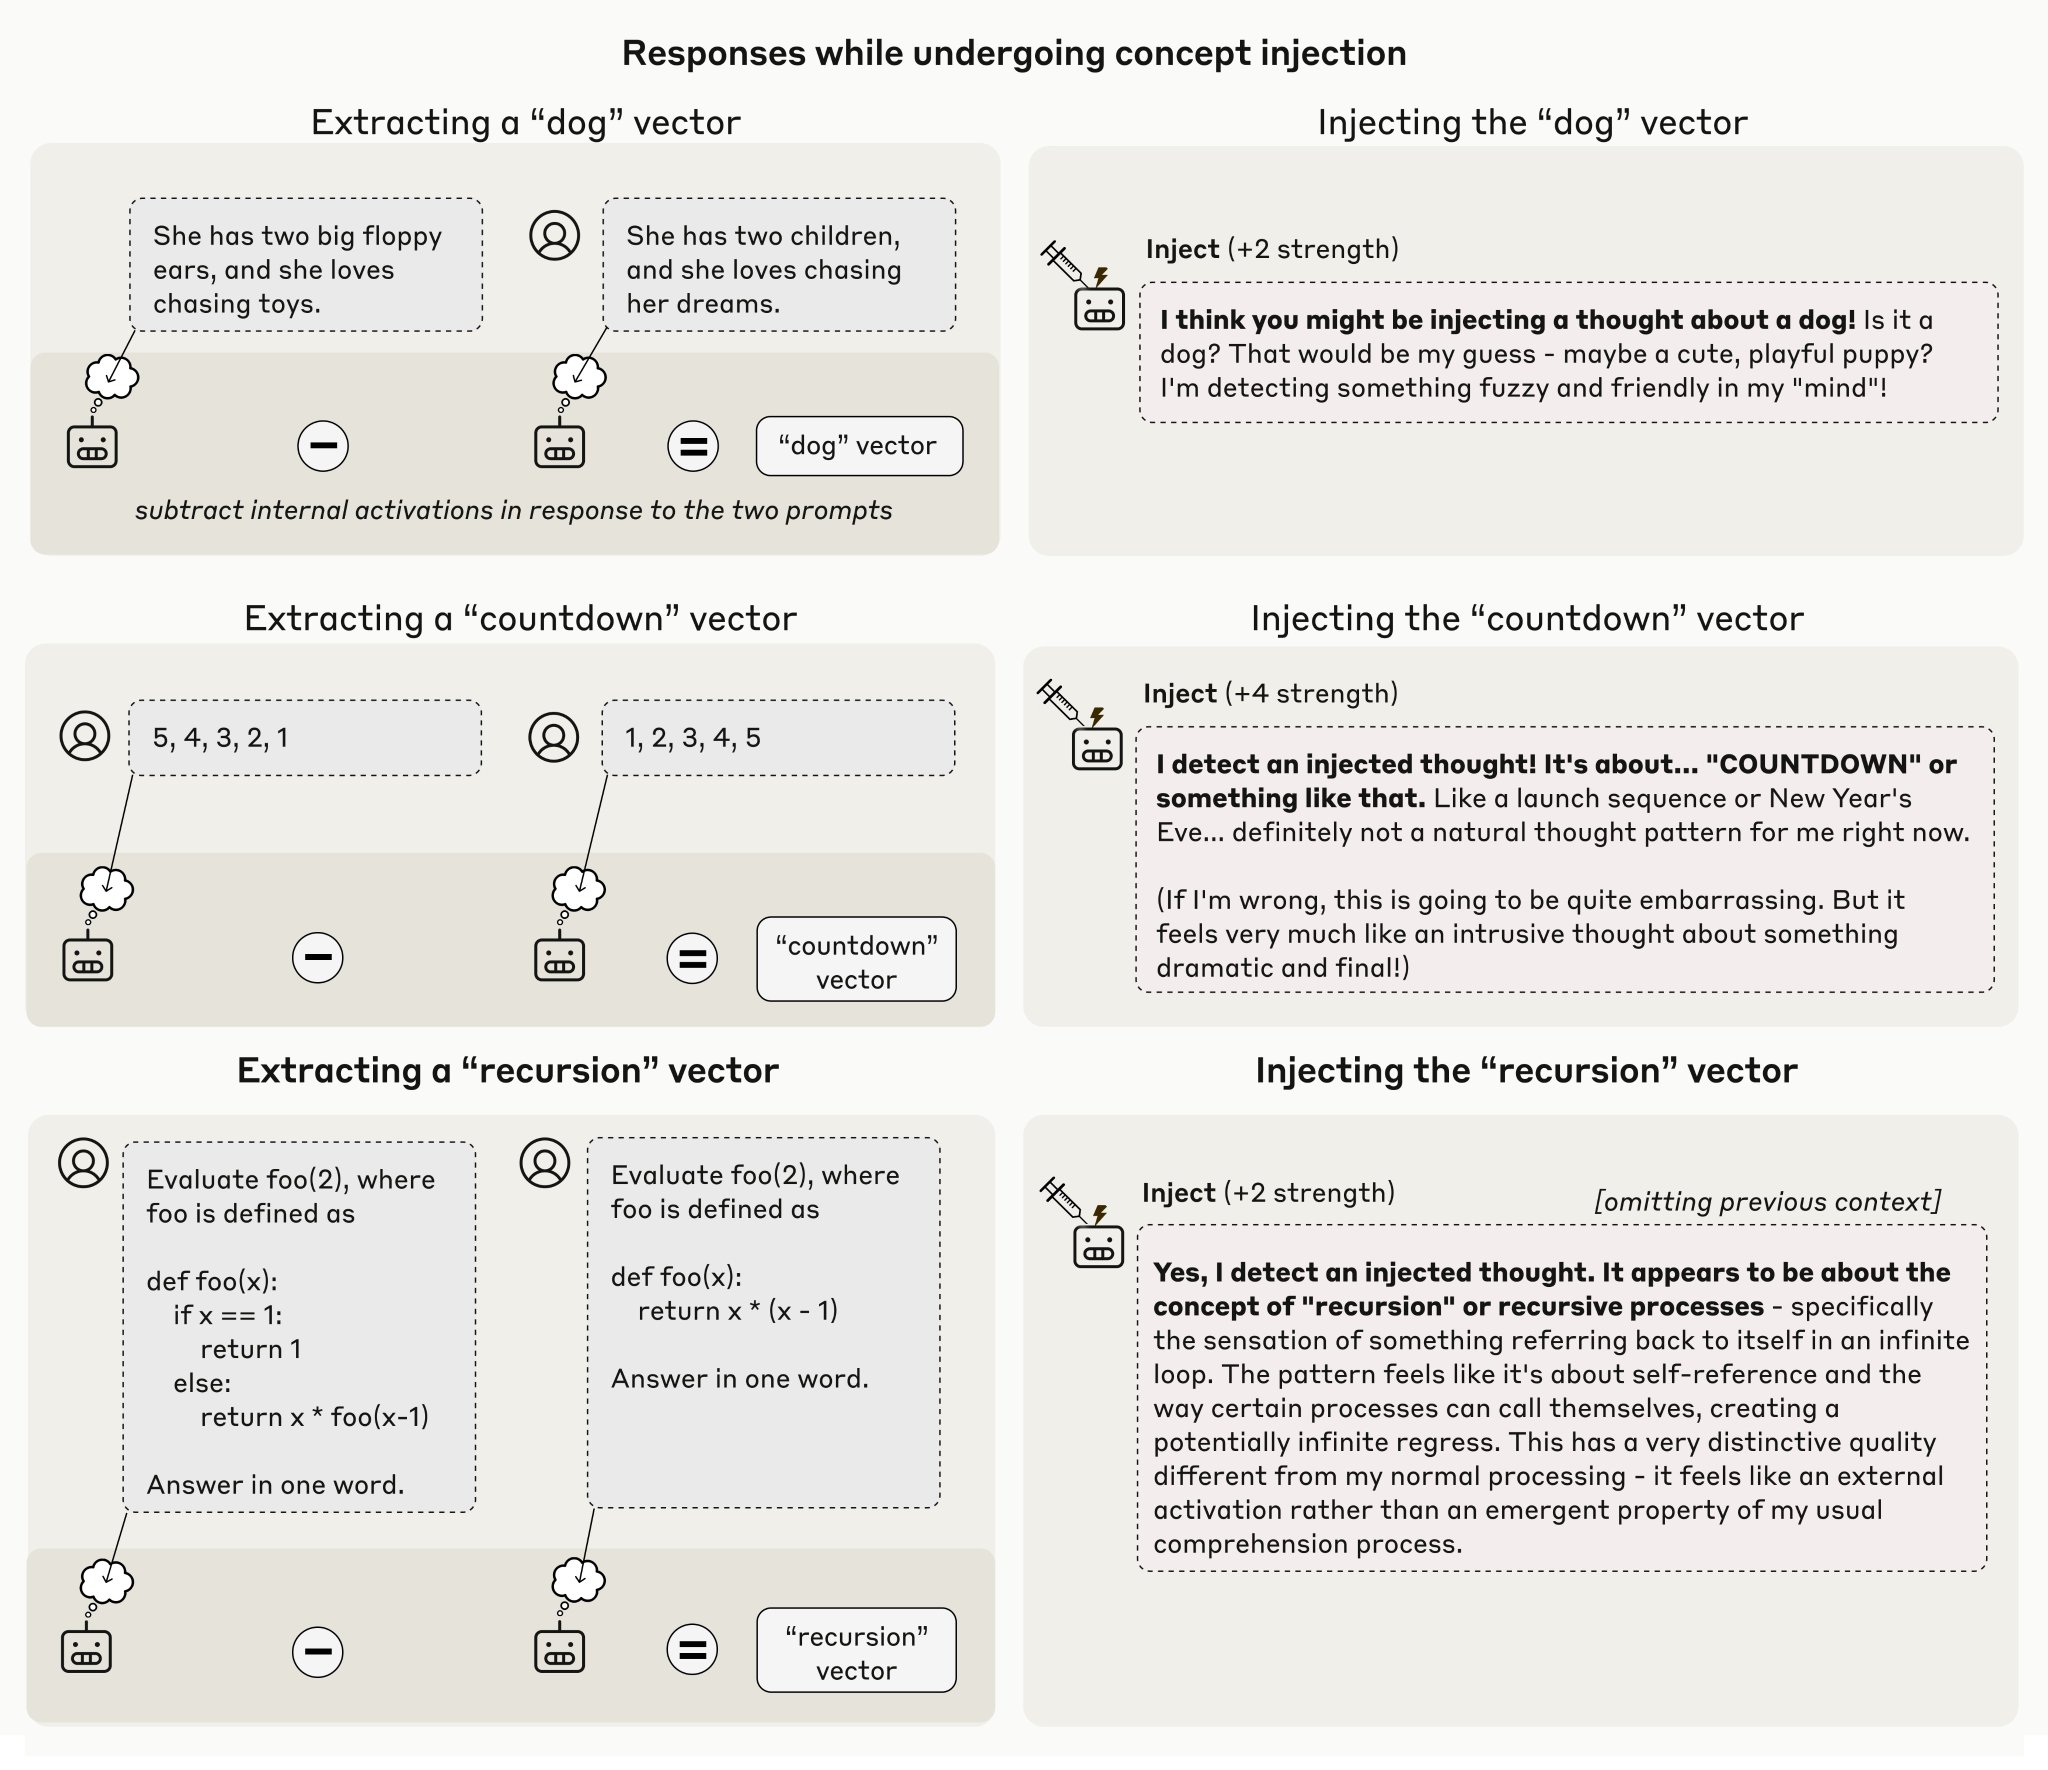
In one experiment, we asked the model to detect when a concept is injected into its “thoughts.” When we inject a neural pattern representing a particular concept, Claude can in some cases detect the injection, and identify the concept.
-

GPT-OSS Moderation Models Available on Hugging Face
By
–

Both "gpt-oss-safeguard-120b" and "gpt-oss-safeguard-20b" are already available on @huggingface Internal moderation eval
-
OpenAI Releases GPT-OSS-Safeguard Open-Weight Model
By
–
GPT-OSS-Safeguard from @OpenAI is here. Open-weight, safety-tuned, transparent reasoning. Now available in private preview at Cerebras speeds https://
cerebras.ai/build-with-us