Frontier models are now world-class vulnerability researchers, but they’re currently better at finding vulnerabilities than exploiting them. This is unlikely to last. We urge developers to redouble their efforts to make software more secure. Read more:
SAFETY
-
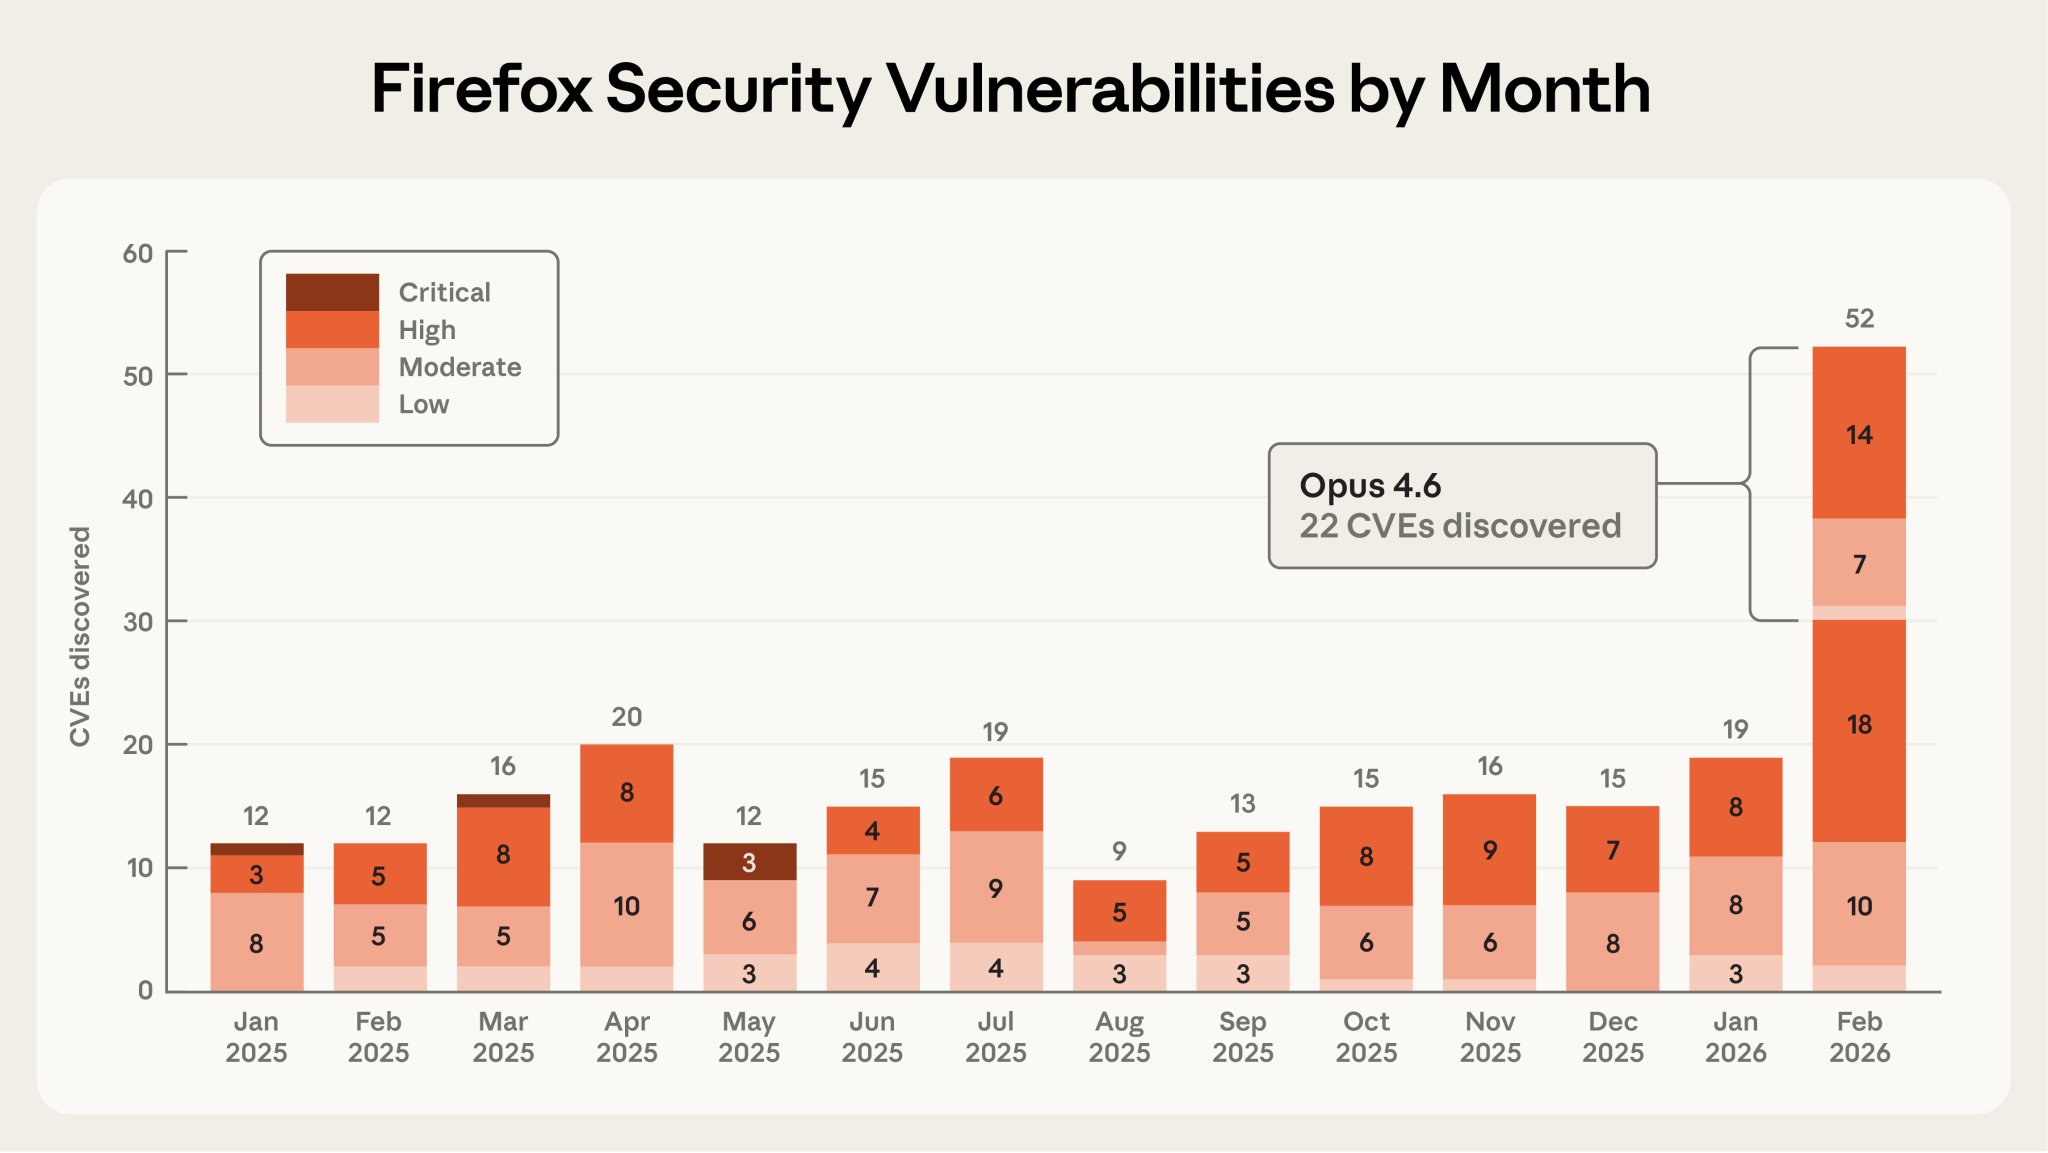
Claude Finds 22 Firefox Vulnerabilities in Security Partnership
By
–
We partnered with Mozilla to test Claude's ability to find security vulnerabilities in Firefox. Opus 4.6 found 22 vulnerabilities in just two weeks. Of these, 14 were high-severity, representing a fifth of all high-severity bugs Mozilla remediated in 2025.
-
AI Temporal Reasoning Error Potentially Caused Iran School Bombing
By
–
time will tell, but the tragic bombing of the school in Iran looks like it could well have been an AI error of temporal reasoning. viz the AI may have had access to old intel and new intel and failed to give precedence to the new intel.
-
Models Know Longer Isn’t Always Better
By
–
the deeper point here connects to something the field keeps rediscovering. we trained reasoning models to think longer. then we discovered longer doesn't mean better. now this paper shows the models themselves already know that. they're generating stop signals that our inference
-
SAGE: Efficient Reasoning with Confidence Checks
By
–
their solution: SAGE (Self-Aware Guided Efficient Reasoning). instead of generating token by token, SAGE extends chains in whole reasoning steps. after each step, it checks: is the model confidently signaling it wants to stop? if yes, reasoning ends. no fine-tuning. no new
-
Researchers test AI self-awareness in reasoning
By
–
here's where it gets interesting. the researchers probed whether models internally "know" they're done. they introduced TSearch, which scores partial reasoning traces by cumulative log-probability across the entire chain, not just the next token. when you let the model explore
-
Overthinking harms accuracy in AI responses
By
–
and it's not just wasted compute. overthinking actively hurts accuracy. DeepSeek-R1 produces responses 5x longer than Claude 3.7 Sonnet on AIME 2025 with comparable accuracy. QwQ-32B scores 2 percentage points HIGHER with its shortest answers using 31% fewer tokens. 72% of
-
RFCS Metric Reveals Early Correct Steps
By
–
first, the problem quantified. the researchers created a metric called RFCS (Ratio of First Correct Step) that tracks where in a chain of thought the correct answer first appears. on MATH-500, across every model tested, the right answer shows up well before the end in over half
-
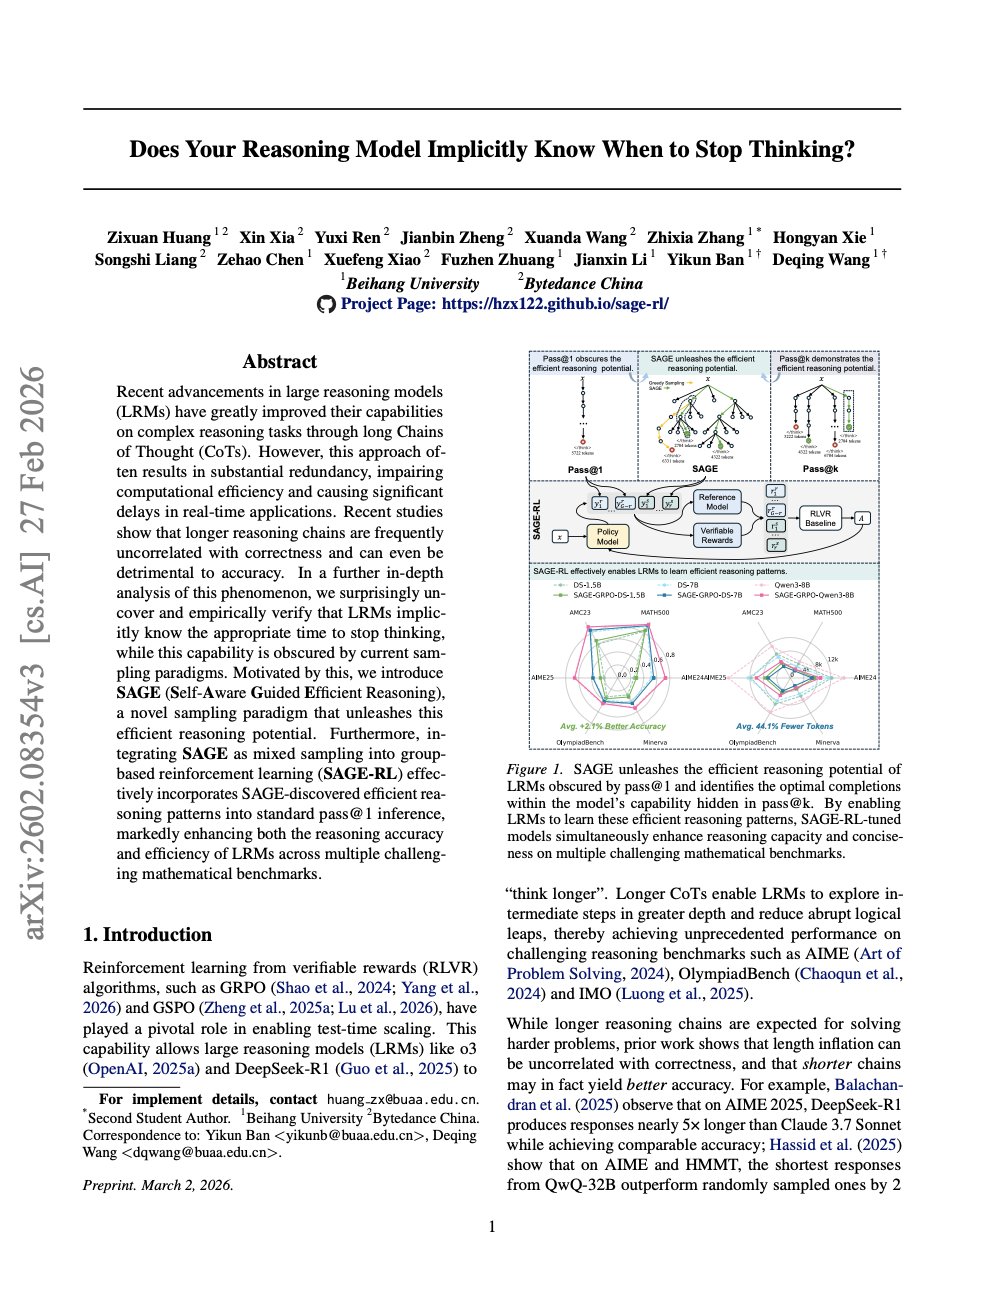
Overthinking in AI: A Sampling Issue
By
–
reasoning models already know when they've solved the problem. we just don't let them stop. new paper from Beihang University and ByteDance shows that the overthinking problem in models like DeepSeek-R1 and Qwen3 isn't a training failure. it's a sampling failure. the fix cuts
-

AI enables helicopter emergency autoland, saving lives
By
–
Emergency autoland has never existed for helicopters. If a pilot is incapacitated, the helicopter can now land itself safely. This is the kind of AI safety feature that will save lives and eventually become mandatory.