Please Stop Drawing Neural Networks Wrong https://
bit.ly/3IsqTZk #AI #MachineLearning #DeepLearning #LLMs #DataScience
RESEARCH
-

Stop Drawing Neural Networks Incorrectly
By
–
-

Changyong Oh Completes Bayesian Optimization Thesis Defense
By
–
Congratulations to Changyong Oh for an amazing thesis and defense on Bayesian Optimization.
-
LLaMA-Adapter v2 Adds Trainable RMSNorm and Bias Parameters
By
–
Good question. Yes, because LLaMA-Adapter v2 is basically LLaMA-Adapter but it also has trainable RMSNorm parameters and trainable bias units (in FC layers)
-
MACARONS: 3D Reconstruction and Environment Exploration from RGB Images
By
–
MACARONS: Mapping And Coverage Anticipation with RGB Online Self-Supervision
— AK (@_akhaliq) 15 juin 2023
paper page: https://t.co/3aaipPlMcj
introduce a method that simultaneously learns to explore new large environments and to reconstruct them in 3D from color images only. This is closely related to the… pic.twitter.com/rj7GWrOy9fMACARONS: Mapping And Coverage Anticipation with RGB Online Self-Supervision paper page: https://
huggingface.co/papers/2303.03
315
… introduce a method that simultaneously learns to explore new large environments and to reconstruct them in 3D from color images only. This is closely related to the -
LoRA vs Adapter: Performance and Memory Usage Comparison
By
–
Good question! On average: LoRA: 21.33 tokens/sec; Memory used: 14.59 GB
Adapter: 26.22 tokens/sec; Memory used: 14.59 GB -
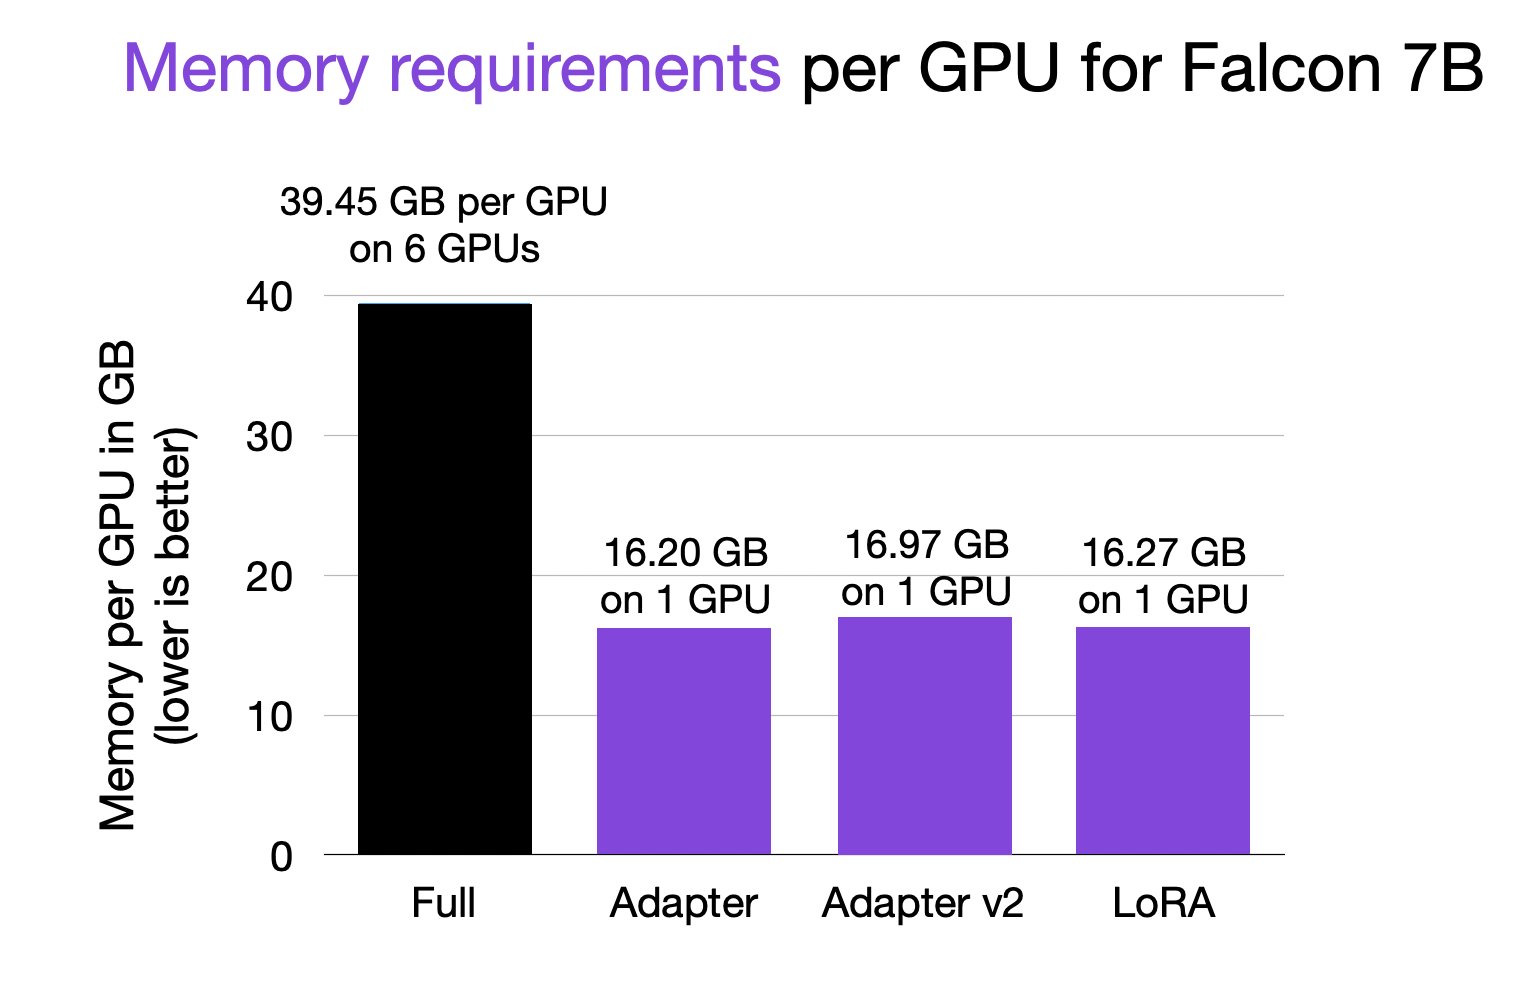
Memory reduction: Full finetuning vs Adapter vs LoRA comparison
By
–
Btw, it's also a big reduction in memory: 16 gigs instead of 6 x 40 GB. Due to the reduced parameter counts in the backward pass: Full finetuning: 7,217,189,760
Adapter: 1,365,330
Adapter v2: 3,839,186
LoRA: 3,506,176 (I used LoRA rank of 16 to match Adapter v2 above.) -

Efficient Falcon Finetuning with LoRA on Single GPU
By
–
Have been heads-down porting LoRA (low-rank-adaptation) to finetune Falcon more efficiently and ran some performance benchmarks. My longer write-up here: https://
lightning.ai/pages/communit
y/finetuning-falcon-efficiently/
… Long story short: you can finetune Falcon in 1 h on a 52k dataset using a single GPU with 16 GB RAM. -
ChatGPT versus Raphaël Enthoven: Media Experiment Fairness Questioned
By
–
Cette expérience est une escroquerie médiatique
— Docteur Laurent Alexandre (@dr_l_alexandre) 15 juin 2023
ChatGPT a eu 90 secondes
Raphael Enthoven a eu 90 minutes
J’aime beaucoup Raphaël malgré tout 😂 https://t.co/OuK0URIusgCette expérience est une escroquerie médiatique ChatGPT a eu 90 secondes Raphael Enthoven a eu 90 minutes J’aime beaucoup Raphaël malgré tout
-

AI Anthology: 20 Essays on Beneficial AI Applications
By
–
"I am honored to present the AI Anthology, a compilation of 20 inspiring essays authored by distinguished scholars and professionals from various disciplines. The anthology explores the diverse ways in which AI can be channeled to benefit humanity" https://
bit.ly/3N9m3Si -
LoRA vs LLaMA-Adapter: Runtime Performance Comparison
By
–
I'd suggest LoRA or LLaMA-Adapter. Either one works fine and has almost exactly the same runtime. Will upload a benchmark later today.