
Benchmarking SQL Question Answering The next end-to-end application we'll be looking to add benchmarking for is questions over a SQL database Similarly to last time, we need your help!
RESEARCH
-
Parsel Framework Helps LLMs Solve Real-World Programming Tasks
By
–
Originally a tool for computer science education, Stanford scholars are testing how the Parsel framework can help large language models solve complex tasks that are more reflective of what programmers do in the real world. https://
stanford.io/3QzS8pW -
FP8 vs INT8: Optimal Data Types for Deep Learning Inference
By
–
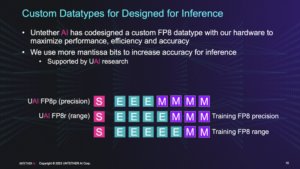
Within #AI, we know that comparing #FP8 vs #INT8 data types for deep learning can be a polarizing topic. But at the end of the day, which really is more optimal for inference?
-

Object Detection Leaderboard: Compare Model Performance Across Datasets
By
–
Excited to share our latest creation: the Object Detection Leaderboard Check it out: http://
huggingface.co/spaces/rafaelp
adilla/object_detection_leaderboard
… Compare performances of various models on different datasets and metrics. Got a model? Bring it over and see how it fares! -
LLMs as Connection Machines: Linking Unexpected Concepts for Innovation
By
–
Very exciting update from @emollick
: “most new ideas…are based on combining existing concepts… LLMs are ‘connection machines’ [that link] unexpected concepts. They generate relationships between tokens that seem unrelated to humans but have [subtle synergies].” -
Topological Data Analysis: Superior Alternative to t-SNE and UMAP
By
–
Why you should use Topological Data Analysis over t-SNE or UMAP? https://
bit.ly/3KyF7sN -
Dataset Evaluation: Key Factor for AI Model Improvement
By
–
"OpenAI said before that evaluating their dataset was one of the major factors for the huge jump from ChatGPT3.5 to 4. Let's do the same for our own applications!" @SimonNom1 expressed better than I could why we're focusing so much on end-to-end evaluations!
-
Benchmarking CSV Question Answering Systems with LangChain
By
–
Full blog here: https://
blog.langchain.dev/benchmarking-q
uestion-answering-over-csv-data/
… And full code here: https://
github.com/langchain-ai/l
angchain-benchmarks
… Just benchmarking CSV question answering for now, but others up next -
Efficient Fine-Tuning Techniques for Large Language Models
By
–
Unlocking the potential of Generative AI! Dive into @DominoDataLab
's latest blog on efficient fine-tuning techniques for large language models like Falcon-7b & more. Cut costs, optimize resources, & boost innovation. https://
domino.buzz/3s8zZFu #ReadNow #DataScience #LLMs -
LLM-Assisted Evaluation: Best Practice for Answer Assessment
By
–
Once we had these datapoints, we needed a way to evaluate answers For this, we relied on LLM assisted evaluation Although this isn't perfect, we think its the best thing out there and are bullish on this in the long run