Paper: https://
huggingface.co/deepseek-ai/De
epSeek-V4-Pro/blob/main/DeepSeek_V4.pdf
… Open Weights:
RESEARCH
-
DeepSeek V4 Pro: Advanced Open-Weights Language Model Released
By
–
-
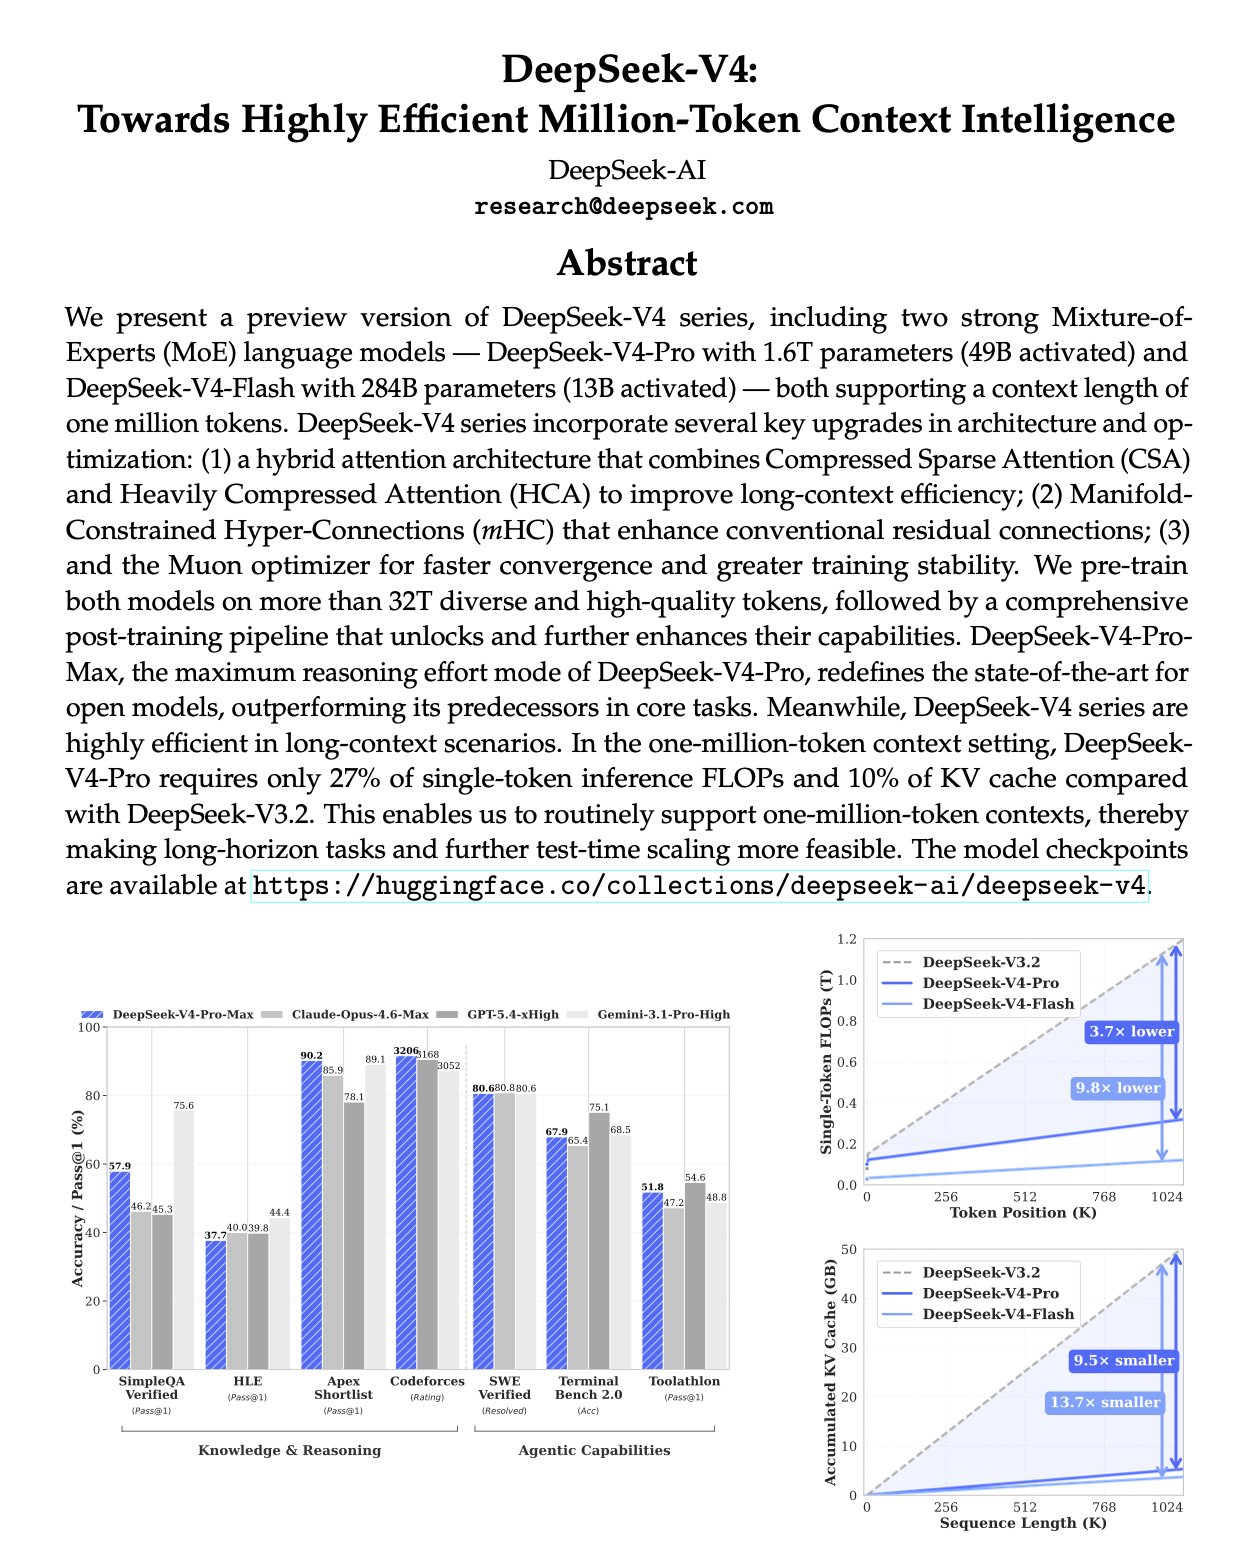
DeepSeek V4: Largest Open-Source MoE Model Released
By
–
DeepSeek just dropped V4! Two open-source MoE models with 1M context windows under MIT license. DeepSeek-V4-Pro: 1.6T total parameters (49B active per token), pre-trained on 33T tokens. This makes it the largest open-source model available – bigger than Kimi K2.6 (1.1T) and
-
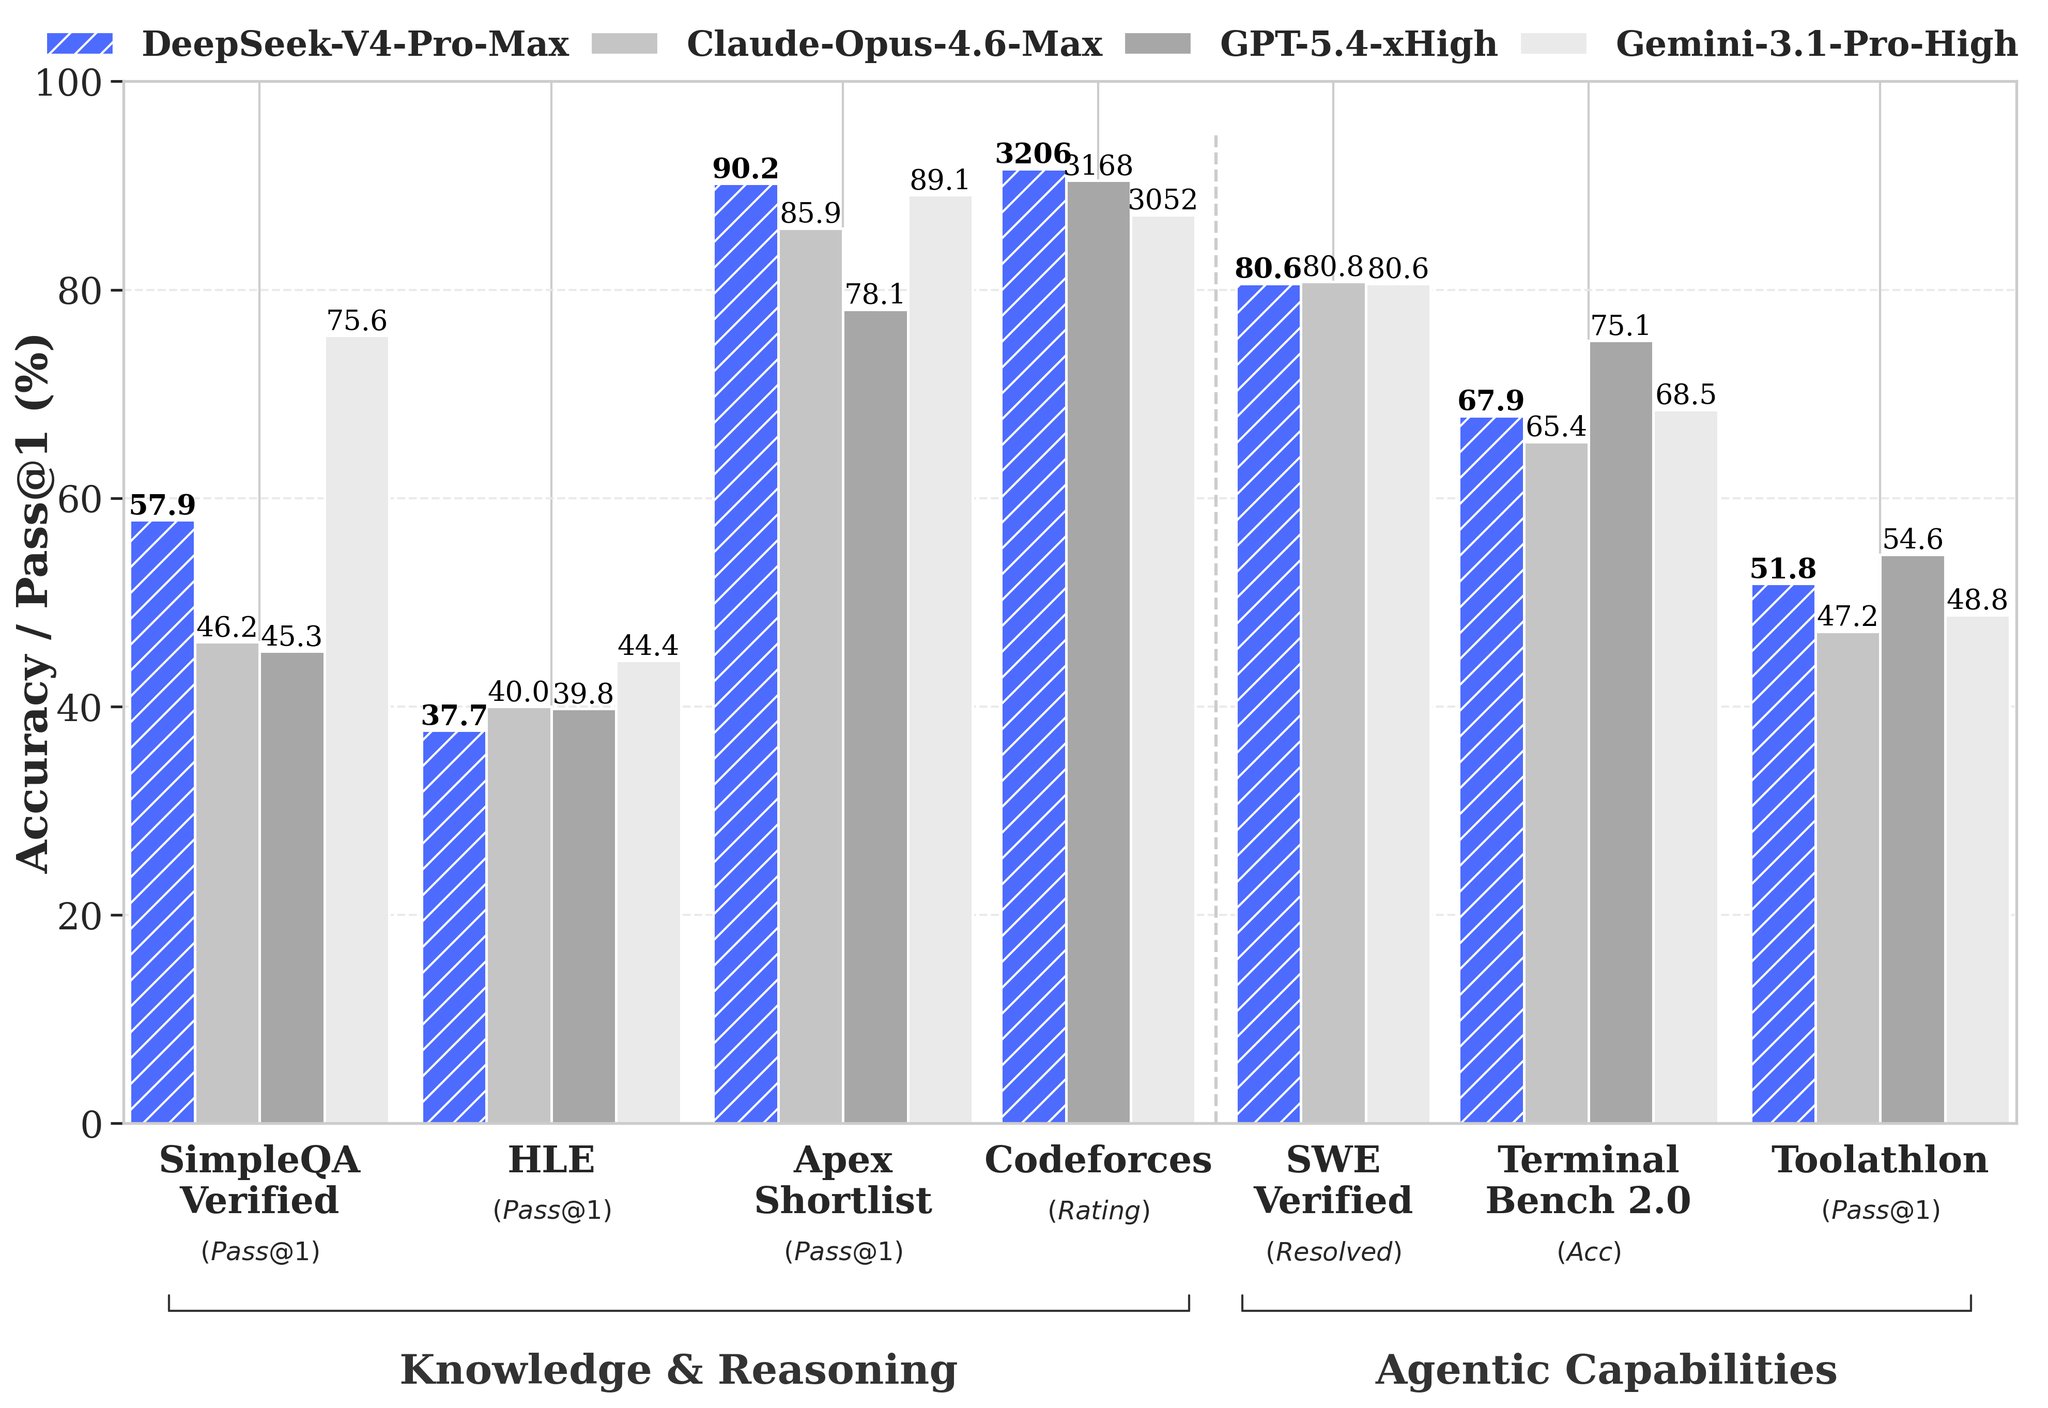
PRO Model Rivals Opus 4.6 and GPT 5.4 in AI Capabilities
By
–
The PRO model, as I say, rivals Opus 4.6, GPT 5.4, and Gemini 3.1 Pro in domains such as general reasoning and agentic capabilities. Private companies in the US cannot afford to stop.
-
Journalistic Integrity vs Corporate Interests in AI Coverage
By
–
I don’t claim that Dwarkesh is right and Jensen is wrong, but that Dwarkesh tries to be right while Jensen tries to serve Nividia. You don’t recognize a hustler when he drops on your head don’t you
-
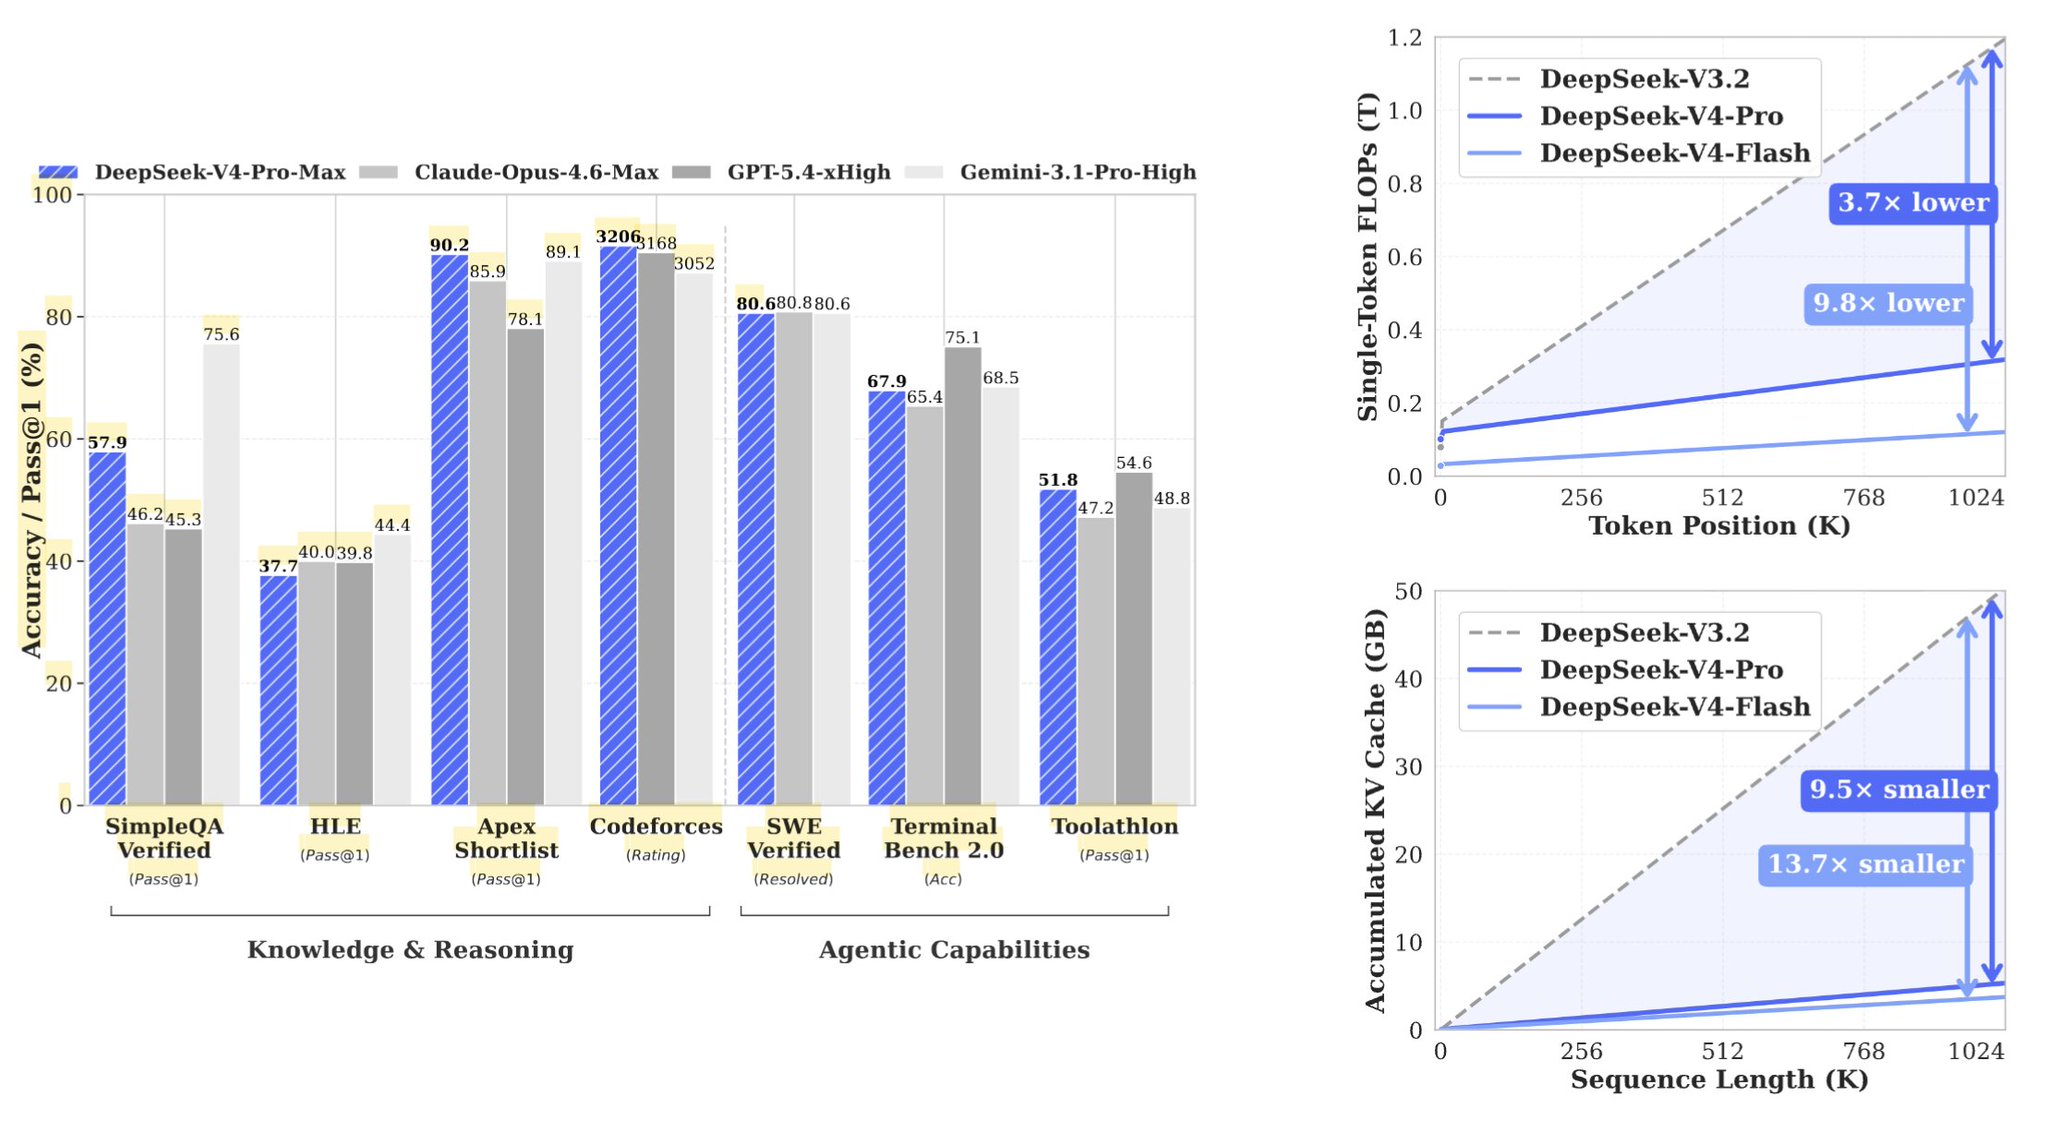
DeepSeek-V4 Introduces Advanced Attention Techniques for Million Token Context
By
–
"DeepSeek-V4 Technical Report" A 58 page paper with brand new attention techniques: Heavily Compressed Attention (HCA) & Compressed Sparse Attention (CSA). This hybrid attention setup enables V4 to hit 1 million context. DeepSeek-V4-Pro is now the largest OS model ever, with
-
DeepSeek V4 Paper Release Announcement
By
–
Check out the full paper here! https://
alphaxiv.org/abs/deepseek-v4 -
China’s PLA Adopts Unmanned Systems and Humanoid Robots
By
–
Inside China's Tech Evolution: Unmanned Systems Reshape PLA Battle Drills! https://
youtu.be/JVIw8lHjr9M?si
=BQ1DCbYBqWnCYeEj
… via @YouTube #battle #humanoidtech #humanoid #robot #Robotics #AI #TechRevolution #TechInnovation #ArtificialInteligence #PhysicalAI @AlbertoEMachado @Eli_Krumova @postoff25 -
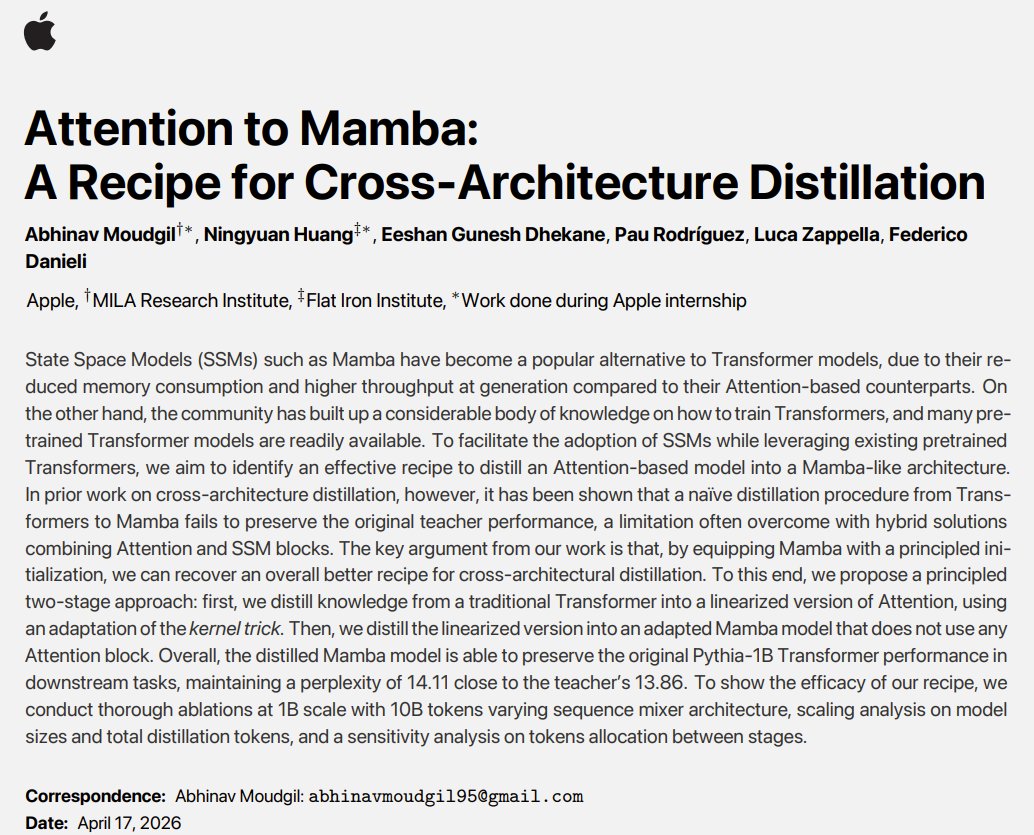
Cross-Architecture Distillation Recipe for Mamba Models
By
–
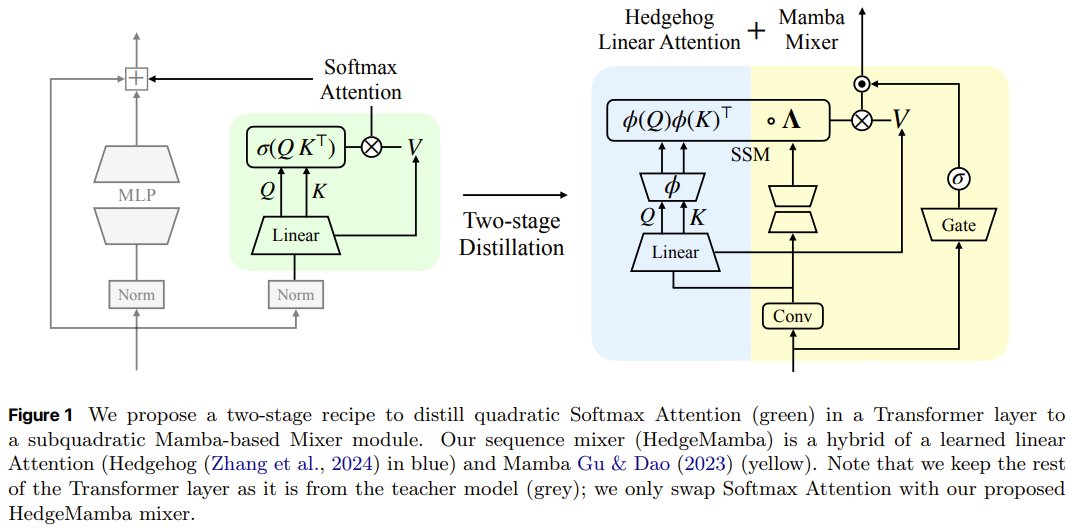
Attention to Mamba: A Recipe for Cross-Architecture Distillation Paper: https://
arxiv.org/abs/2604.14191 -
Mamba Models Match Transformer Performance Without Attention
By
–
Can you get a Mamba model to perform like a Transformer without adding Attention? Researchers from Apple, MILA, and Flat Iron Institute (including Abhinav Moudgil and Ningyuan Huang) have a breakthrough answer. They introduce a two-step distillation recipe: first, they convert
-
User Wants More AI Content on Social Media Feed
By
–
im seeing so many irrelevant clips on x lately. I want my fy-page filled with AI stuff the way it was and not a second tiktok 🙁 this really makes me sad.