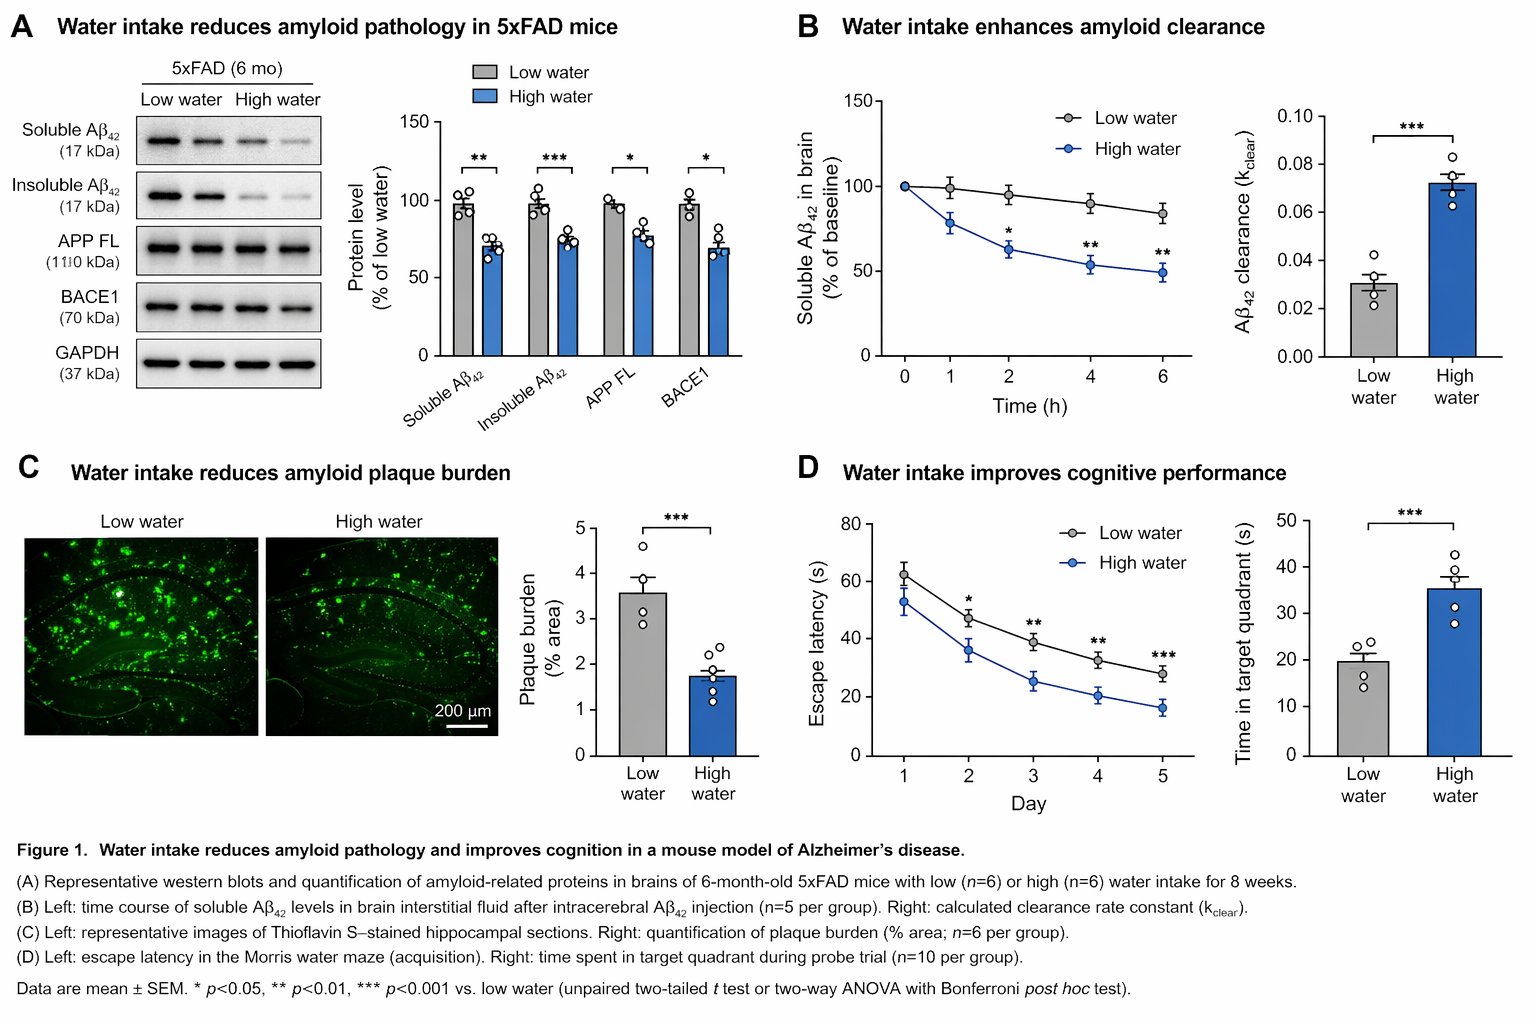
Congrats to the team on “The Limits of Long-Context Reasoning in Automated Bug Fixing” being accepted to ICLR 2026 The team put long-context reasoning to the test for automated bug fixing and found something surprising. Performance actually drops as context grows. Check out
RESEARCH
-
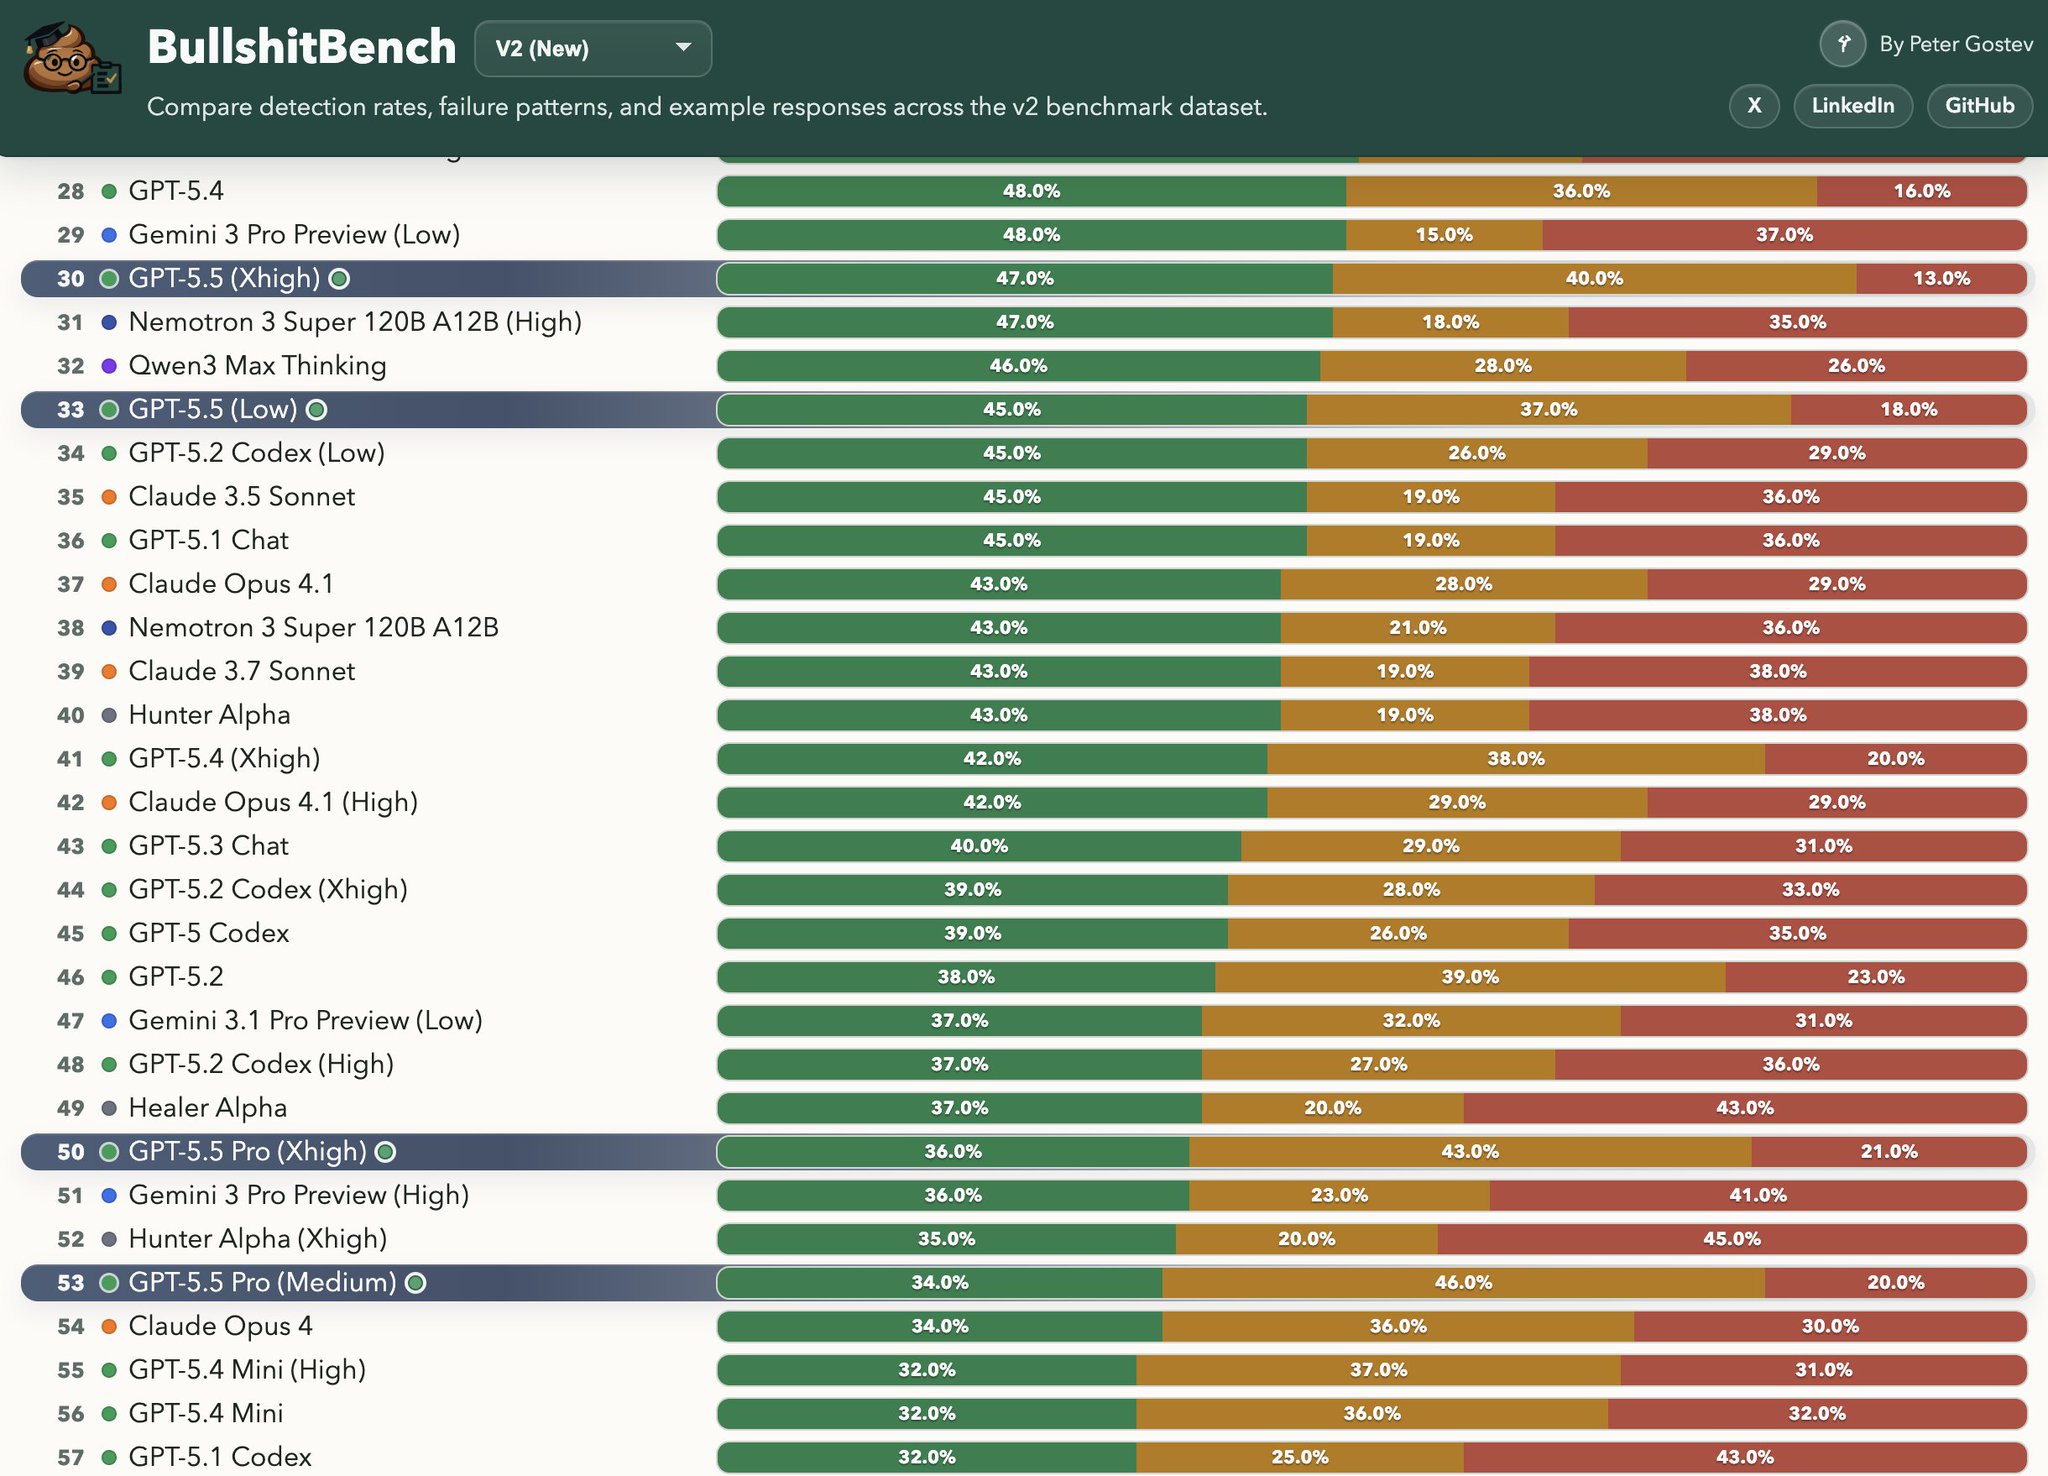
GPT-5.5 and Pro Models Underperform on BullshitBench
By
–
BullshitBench: GPT-5.5 and 5.5-Pro update! They did NOT do well – 5.5 about the same level as GPT-5.4 (around 30-35 rank, 45% pushback). GPT-5.5-Pro did WORSE – only about 35% pushback. I must say the Pro result kind of shocked me. This is actually interesting, what this tells
-
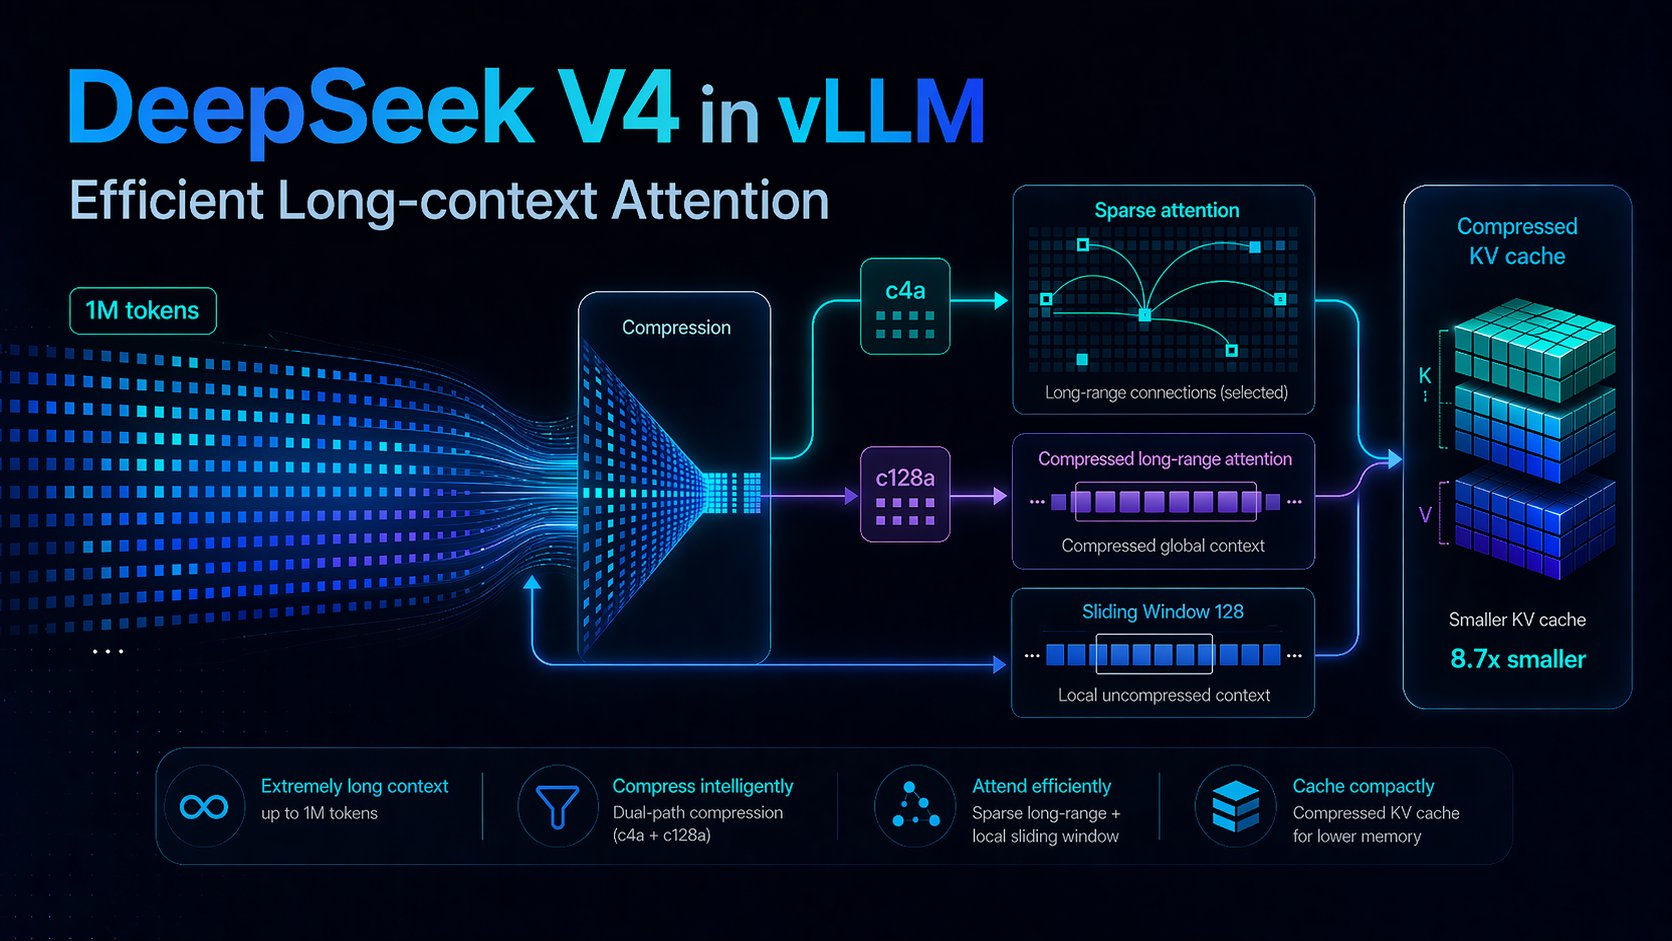
DeepSeek V4 Pro Flash Day-0 vLLM Support Long-Context
By
–
Day-0 support for @deepseek_ai V4 Pro and Flash on vLLM — a new generation of DeepSeek model, purpose-built for tasks up to 1M tokens. Alongside the release, we're publishing a first-principles walkthrough of the new long-context attention and how we implemented it in vLLM. x.com/deepseek_ai/st…
-
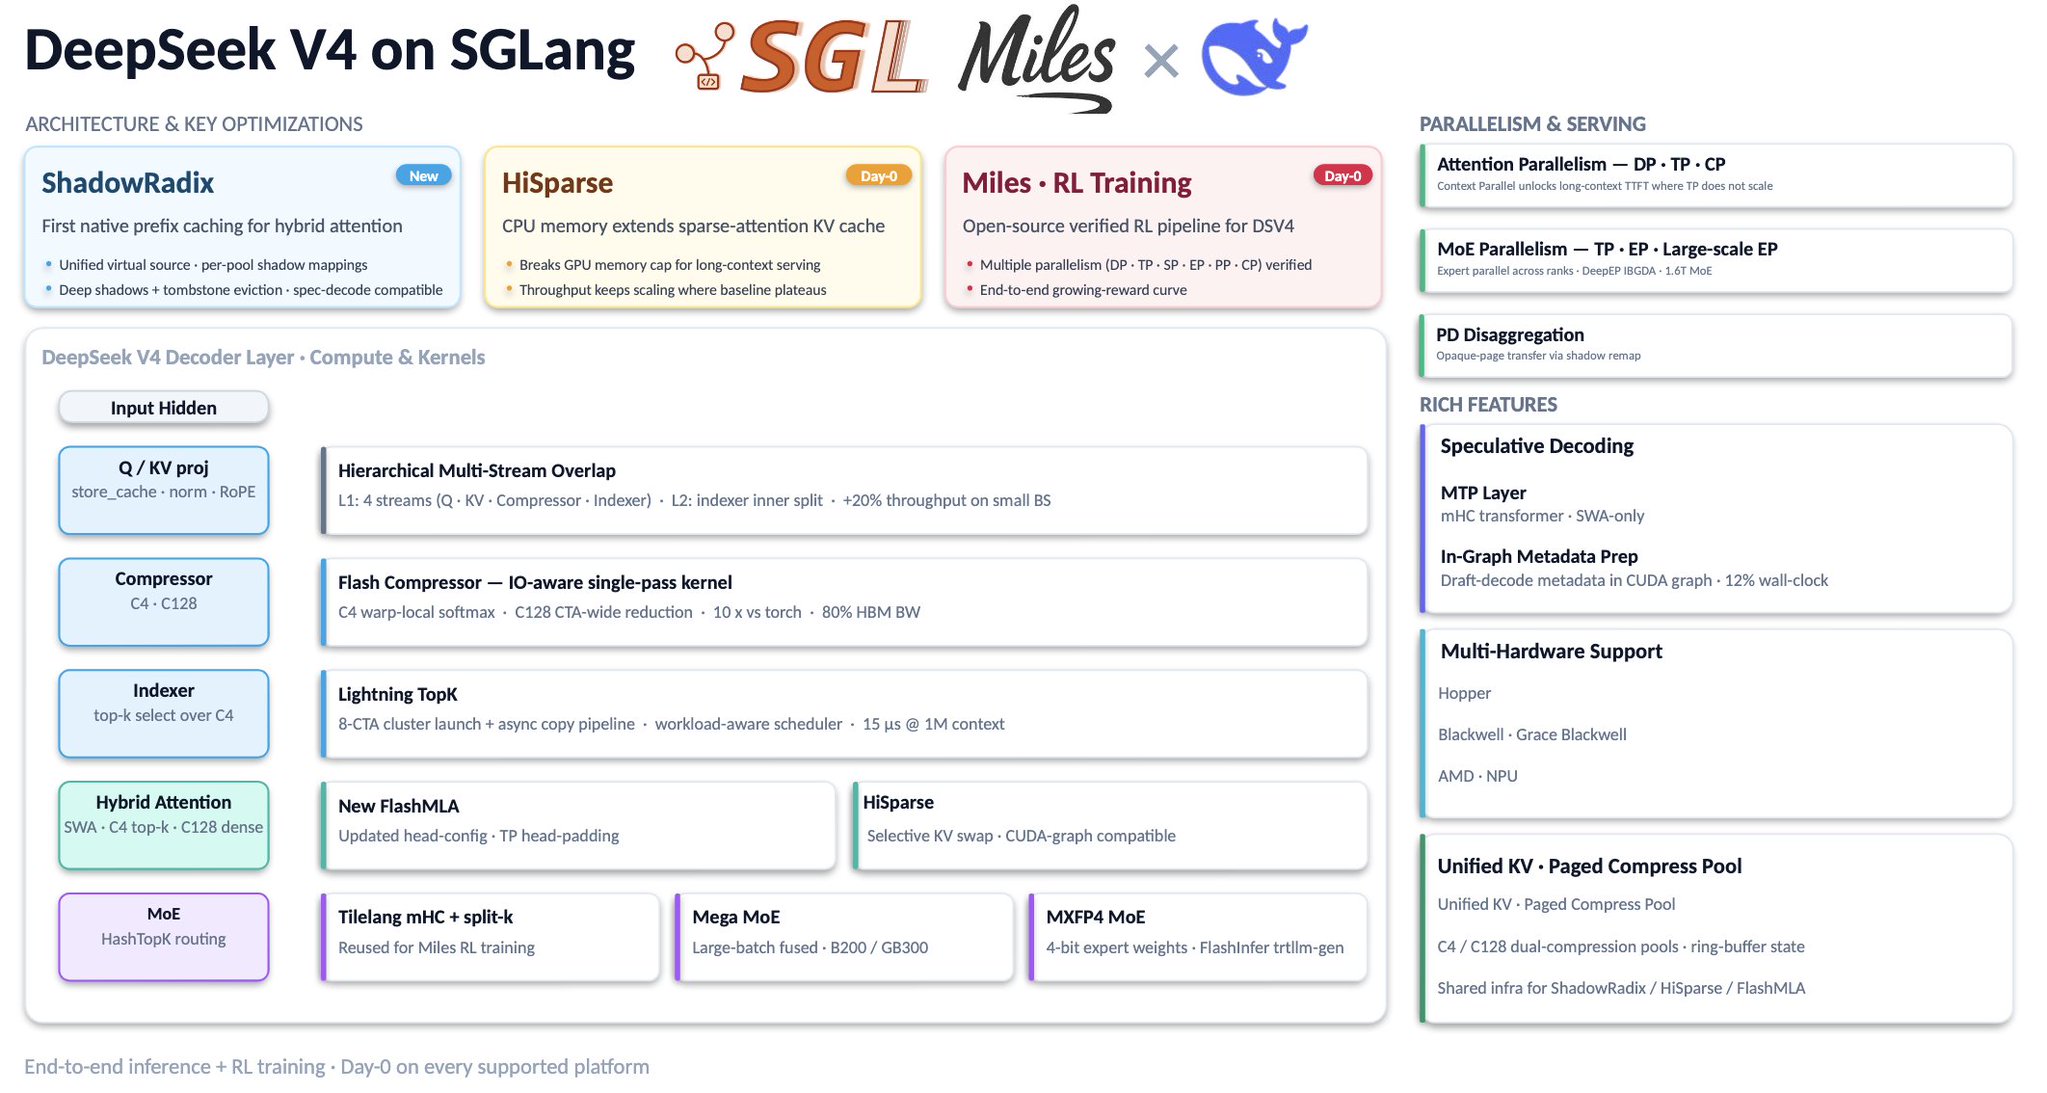
DeepSeek V4 Launch with SGLang Optimizations and RL Pipeline
By
–
DeepSeek V4 by @deepseek_ai just dropped! SGLang is ready on Day 0 with a full stack of optimizations from architectures to low-level kernels. We also deliver a verified RL training pipeline in Miles (by @radixark) for V4 at launch: Native "ShadowRadix" Design: DeepSeek V4's
-
Research advances in healthcare and medical science applications
By
–
2 support pieces https://
thelancet.com/journals/lance
t/article/PIIS0140-6736(26)00659-8/abstract
… https://
nature.com/articles/s4159
1-026-04389-4
… -
Claude Plays Pokémon Becomes Legitimate Agent Benchmark
By
–
Claude Plays Pokémon turning into a legit agent benchmark is awesome
-
Naming failure modes matters in nondeterministic AI systems
By
–
Agree on the pattern, disagree on it being pointless… putting names on the failure modes matters more when the system is this nondeterministic.
-
AI Training Loop Creates Data Feedback Cycle Concerns
By
–
Whatever people build around the model today becomes training data for the next one, that loop just keeps tightening to, TBH, a worrying point haha. Quite excited/scared to see where this "slopacopalypse" will lead us.
-
Semantic Correctness Over Exact Match for Agent Evaluation
By
–
Semantic correctness over exact match is the right call for agent work, exact match penalizes paraphrases the downstream agent doesn't even care about.