10/ AI Agents That Matter – analyzes current agent evaluation practices and reveals shortcomings that potentially hinder real-world application; proposes an implementation that jointly optimizes cost and accuracy and a framework to avoid overfitting agents.
RESEARCH
-
Ctrl-G Framework: Logical Control for LLM Generation
By
–
7/ Adaptable Logical Control for LLMs – presents the Ctrl-G framework to facilitate control of LLM generations that reliably follow logical constraints; it combines LLMs and Hidden Markow Models to enable following logical constraints (represented as deterministic finite
-
Synthetic Data Effects on LLM Bias and Internal Attributes
By
–
8/ LLM See, LLM Do – closely investigates the effects and effectiveness of synthetic data and how it shapes a model’s internal biases, calibration, attributes, and preferences; finds that LLMs are sensitive towards certain attributes even when the synthetic data prompts appear
-

SummHay: New Benchmark for Haystack Summarization and Source Citation
By
–
9/ Summary of a Haystack – proposes a new task, SummHay, to test a model’s ability to process a Haystack and generate a summary that identifies the relevant insights and cites the source documents.
-
Self-Evaluation Defends LLMs Against Adversarial Attacks
By
–
5/ Self-Evaluation as a Defense Against Adversarial Attacks on LLMs – proposes the use of self-evaluation to defend against adversarial attacks; uses a pre-trained LLM to build defense which is more effective than fine-tuned models, dedicated safety LLMs, and enterprise
-

RAG Best Practices: Multimodal Retrieval and Performance Optimization
By
–
3/ Searching for Best Practices in RAG – shows the best practices for building effective RAG workflows; proposes strategies that focus on performance and efficiency, including emerging multimodal retrieval techniques.
-
Scaling Synthetic Data Creation with One Billion Diverse Personas
By
–
4/ Scaling Synthetic Data Creation – proposes 1 billion diverse personas to facilitate the creation of diverse synthetic data for different scenarios; uses a novel persona-driven data synthesis methodology to generate diverse and distinct data covering a wide range of
-
CriticGPT: New Model Critiques ChatGPT Responses
By
–
2/ CriticGPT – a new model based on GPT-4 to help write critiques for responses generated by ChatGPT; trained using RLHF using a large number of inputs that contained mistakes for which it had to critique.
-
Hyland’s Tech Outreach Program: Computer Science and Digital Innovation
By
–
Remarkable initiative, @Hyland ! Hyland’s Tech Outreach program #ComputerScience #Technology #AI #IoT #5G #DigitalTransformation
-
Prompt Engineering Gains Equivalent to Fine-Tuning Model Performance
By
–
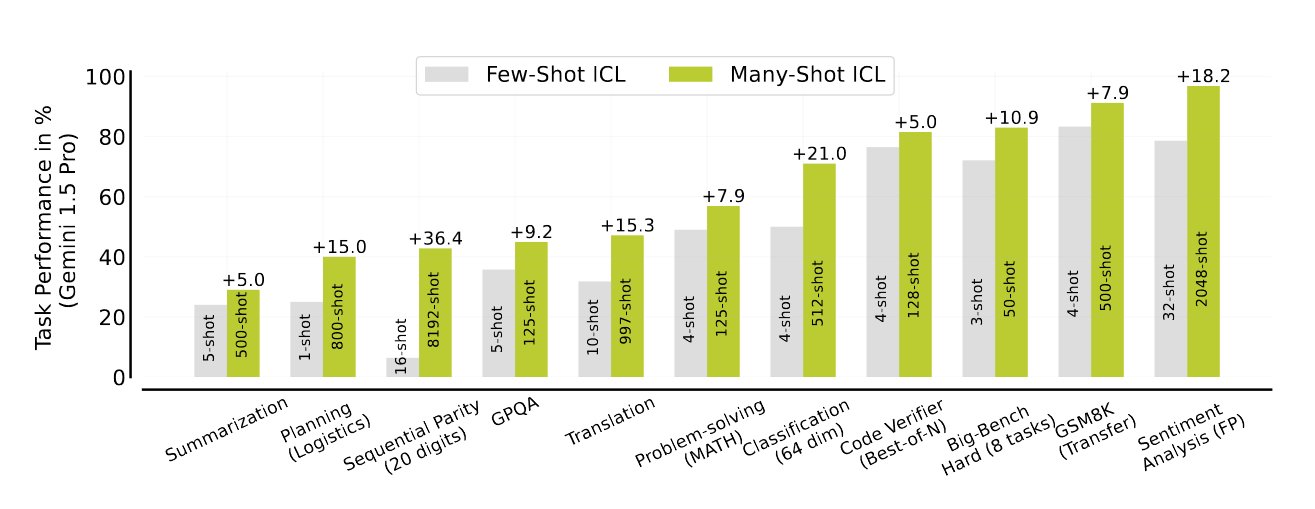
I see many people rediscovering this paper and jumping to the wrong conclusions. Any gain in prompt engineering is a gain in terms of fine-tuning. A fine-tuned model will simply perform better with many-shot ICL.