Link: https://
github.com/rasbt/LLMs-fro
m-scratch/blob/main/ch07/04_preference-tuning-with-dpo/create-preference-data-ollama.ipynb
…
RESEARCH
-
DPO Preference Tuning with Ollama LLM Tutorial
By
–
-

Building Large Language Models from Scratch Resource
By
–
Build a large language model from scratch with this very cool resource
-

Epigenetic Aging Clocks: Progress, Limitations, and Medical Promise
By
–
Epigenetic aging clocks have become a commonly used metric in medical research and are being marketed to consumers. The new Ground Truths with @prof_horvath
, who discovered these clocks a decade ago, provides a frank appraisal of their progress, limitations, and promise. With -

Training LLM Engineers and Open-Sourcing Knowledge at Scale
By
–
3 years ago we trained a big LLM together with +1000 people one of the part I'm most proud of is how it became the school for a generation of model training engineers as well as a strong push for sharing and open-sourcing knowledge in the field
-

LLMs Eliminate Need for Traditional Coding System Standardization
By
–
In the era of large language models: "The extensive efforts previously required to standardize and make coding systems and ontologies interoperable for traditional computing are no longer necessary." https://
nature.com/articles/s4159
1-024-03199-w
…
by @jnkath @DanielTruhn @Dykex6 @IsabellaWies -
Pedro’s Interpretation of Sutton’s Bitter Lesson
By
–
A charitable reading is that Pedro is giving his interpretation of Rich Sutton’s Bitter Lesson.
-
TMLR partnership expansion with ICLR for 2025
By
–
2024: TMLR Featured Certifications (~spotlight+ quality) were welcome to present at ICLR 2025: broader set of TMLR papers will be welcome, based on AE recommendation and other signals TY ICLR for the partnership!
-
AI Accelerates Patient Selection in Orthopedic Surgery
By
–
[#Article] Orthopedics: AI accelerates patient selection for hip arthroplasties https://actuia.com/actualite/orthopedie-lia-accelere-la-selection-des-patients-pour-les-arthroplasties-de-la-hanche/
… #AI #ArtificialIntelligence -
Jamba Architecture Advantages in Long Context Fine-Tuning Efficiency
By
–
We found our efficient Jamba architecture to be advantageous in long context fine-tuning, as it allows for greater speed and lower cost. Therefore, we could experiment with multiple different training recipes during the fine-tuning phase. This is especially interesting for all
-
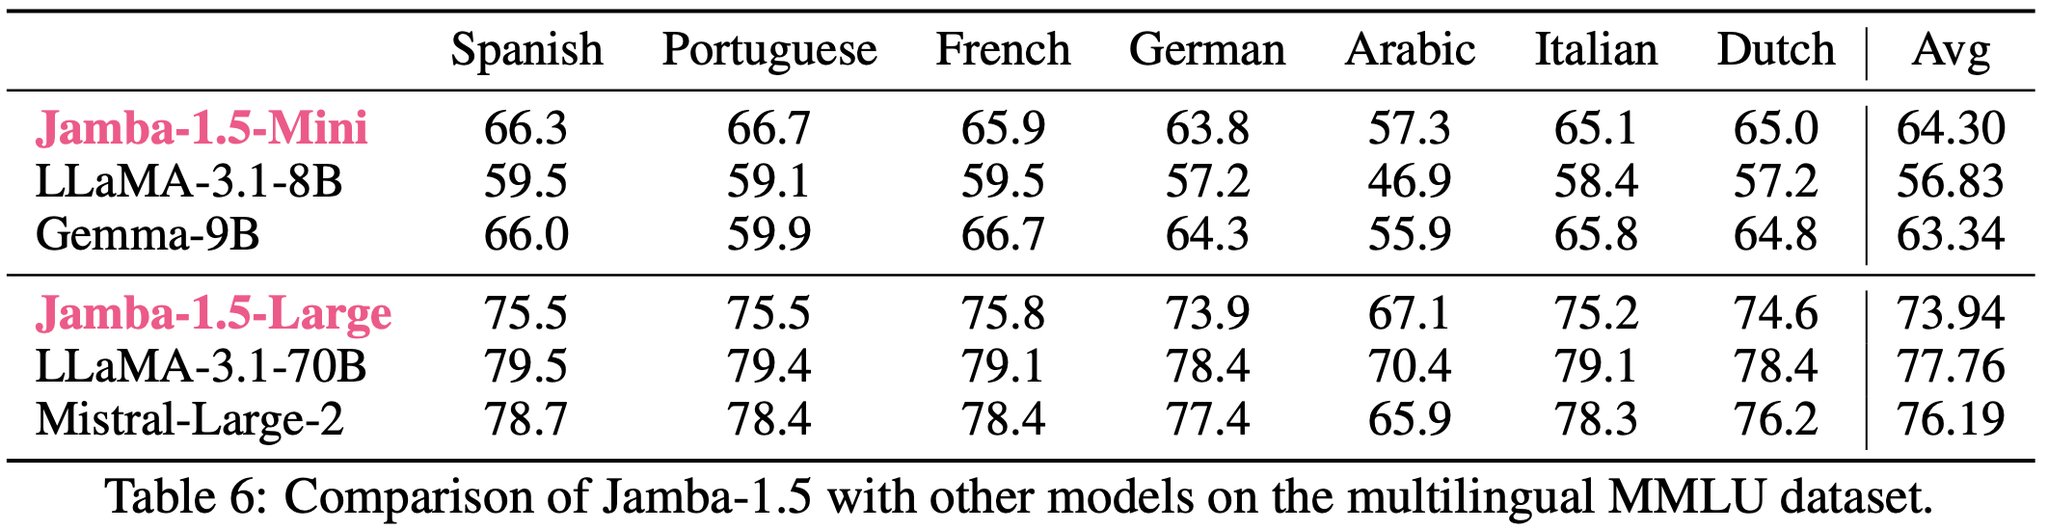
Jamba-1.5 Models Demonstrate Strong Multilingual Performance Despite Limited Post-Training Data
By
–
Jamba-1.5 models perform well in multiple languages, even though we include only a very small fraction of non-english data in the post-training phase. Therefore, we speculate the models are able to use the learned multilingual capabilities from the pre-training phase. 6/7