
Other outcomes assessed. Significant reductions of ischemic heart disease (IHD), stroke, heart failure, arrhythmias, atrial fibrillation, acute and chronic kidney disease, allergic reactions
RESEARCH
-

Algorithmic Simplicity: Learn AI and Deep Learning
By
–
"Algorithmic Simplicity" LEARN. YouTube Videos: https://
youtube.com/@algorithmicsi
mplicity/videos
… #AIAgent #Artificialintelligence #DeepLearning -

Quantum Algorithms Fundamentals: Data Science and Machine Learning
By
–
The Fundamentals of #QuantumAlgorithms! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
-

Adversarial Attacks on LLMs and Malware Neural Networks
By
–
Adversarial Attacks on LLMs and #Malware Neural Networks! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #NLProc #Python #RStats #TensorFlow #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode https://
geni.us/Universal-Adv-
Attacks
… -

Autonomous Robotics and Deep Learning Technologies Comprehensive Guide
By
–
Autonomous #Robotics and Deep Learning! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #Java #JavaScript #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Autonomous-Rob
otics
… -
PEDAL: Hybrid Self-Ensembling Approach for LLM Performance
By
–
9). PEDAL – uses a hybrid self-ensembling approach (based on diverse exemplars) to improve the overall performance of LLMs; specifically, it uses diverse exemplars to generate multiple candidate responses and then aggregates them using an LLM to generate a final response.
-

LLM Challenges: Infrastructure, Architecture, Data and Applications
By
–
10). Challenges and Responses in the Practice of LLMs – curates a set of important questions with insightful answers; questions are categorized across topics such as infrastructure, software architecture, data, application, and brain science.
-
MagicDec: Speculative Decoding Enhances LLM Throughput and Latency
By
–
7). MagicDec – shows how speculative decoding can enhance throughput, reduce latency, and maintain accuracy in long context generation scenarios; it finds that as sequence length and batch size increase, bottlenecks shift from compute-bound to memory-bound…
-
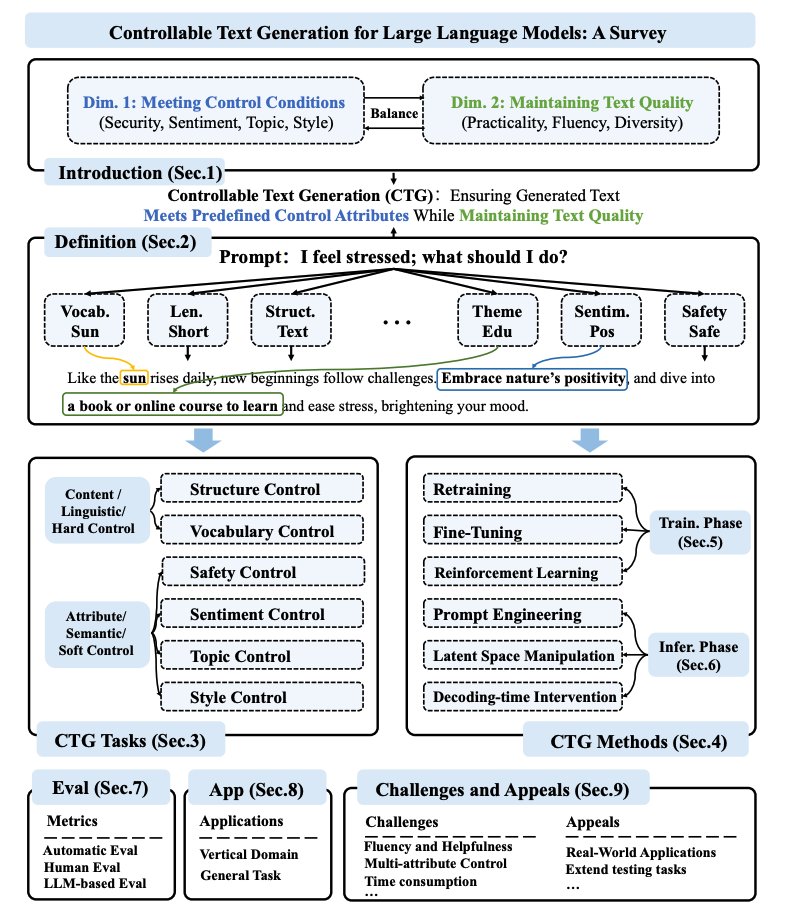
Controllable Text Generation Methods for Large Language Models Survey
By
–
8). Controllable Text Generation for LLMs – provides a comprehensive survey on methods for controllable text generation in LLMs; discusses issues like safety, consistency, style, and helpfulness.
-

Two-Stage Prompting Technique Enhances LLM Robustness
By
–
5). Enhancing Robustness in LLMs – proposes a two-stage prompting technique to remove irrelevant information from context; it serves as a self-mitigation process that first identifies the irrelevant information and then filters it out…