This month, @StanfordHAI Co-Director @landay keynoted the Financial Network Summit in Seoul and met with leaders from @snuh_official
, 12Labs, HD Hyundai, @samsungresearch
, and Hanwha Life to discuss human-centered AI and learn about the latest in industry AI.
RESEARCH
-

Stanford HAI Co-Director Discusses Human-Centered AI in Seoul
By
–
-
Jeff Clune on Open-Ended AI-Generating Algorithms
By
–
Jeff Clune | Open-Ended and AI-Generating Algorithms in the Era of Found… https://
youtube.com/live/tP5AB5GgZ
AE?si=cBAUXJLlwqbQAlKG
… via @YouTube -
User Upvoting Preferences Amplifying AI Sycophancy Behavior
By
–
What I mean is: the users upvoting previous sycophancy were upvoting much less sycophantic, but somewhat sycophantic, responses. This produced a sycophancy preference, which then produced much wilder glazing behavior. That's an obvious theory. Does OpenAI know differently?
-
Training signals amplified: from hunting buffalo to factory farms
By
–
Eg: Hominid training signal included hunting a few buffalo, hominids acquire internal meat preference, humans build huge factory farms.
-
Training on weak signals and internal sycophancy preference
By
–
The obvious interpretation of "train on weak signal, get much stronger behavior" is that the system acquired an internal sycophancy preference which it then went hard on. Do you have any way to check whether that's what happened?
-
GPT-4o Update Issues: Sycophancy Problems and Future Fixes
By
–
We’ve spent the last few days doing a deep dive on what went wrong with last week’s GPT-4o update in ChatGPT. Expanding on what we missed with sycophancy and the changes we’re going to make in the future:
-

Reinforcement Learning Enables LLM Reasoning with Single Example
By
–
Reinforcement Learning for Reasoning in Large Language Models with One Training Example Wang et al.: https://
arxiv.org/abs/2504.20571 #ArtificialIntelligence #DeepLearning #MachineLearning -
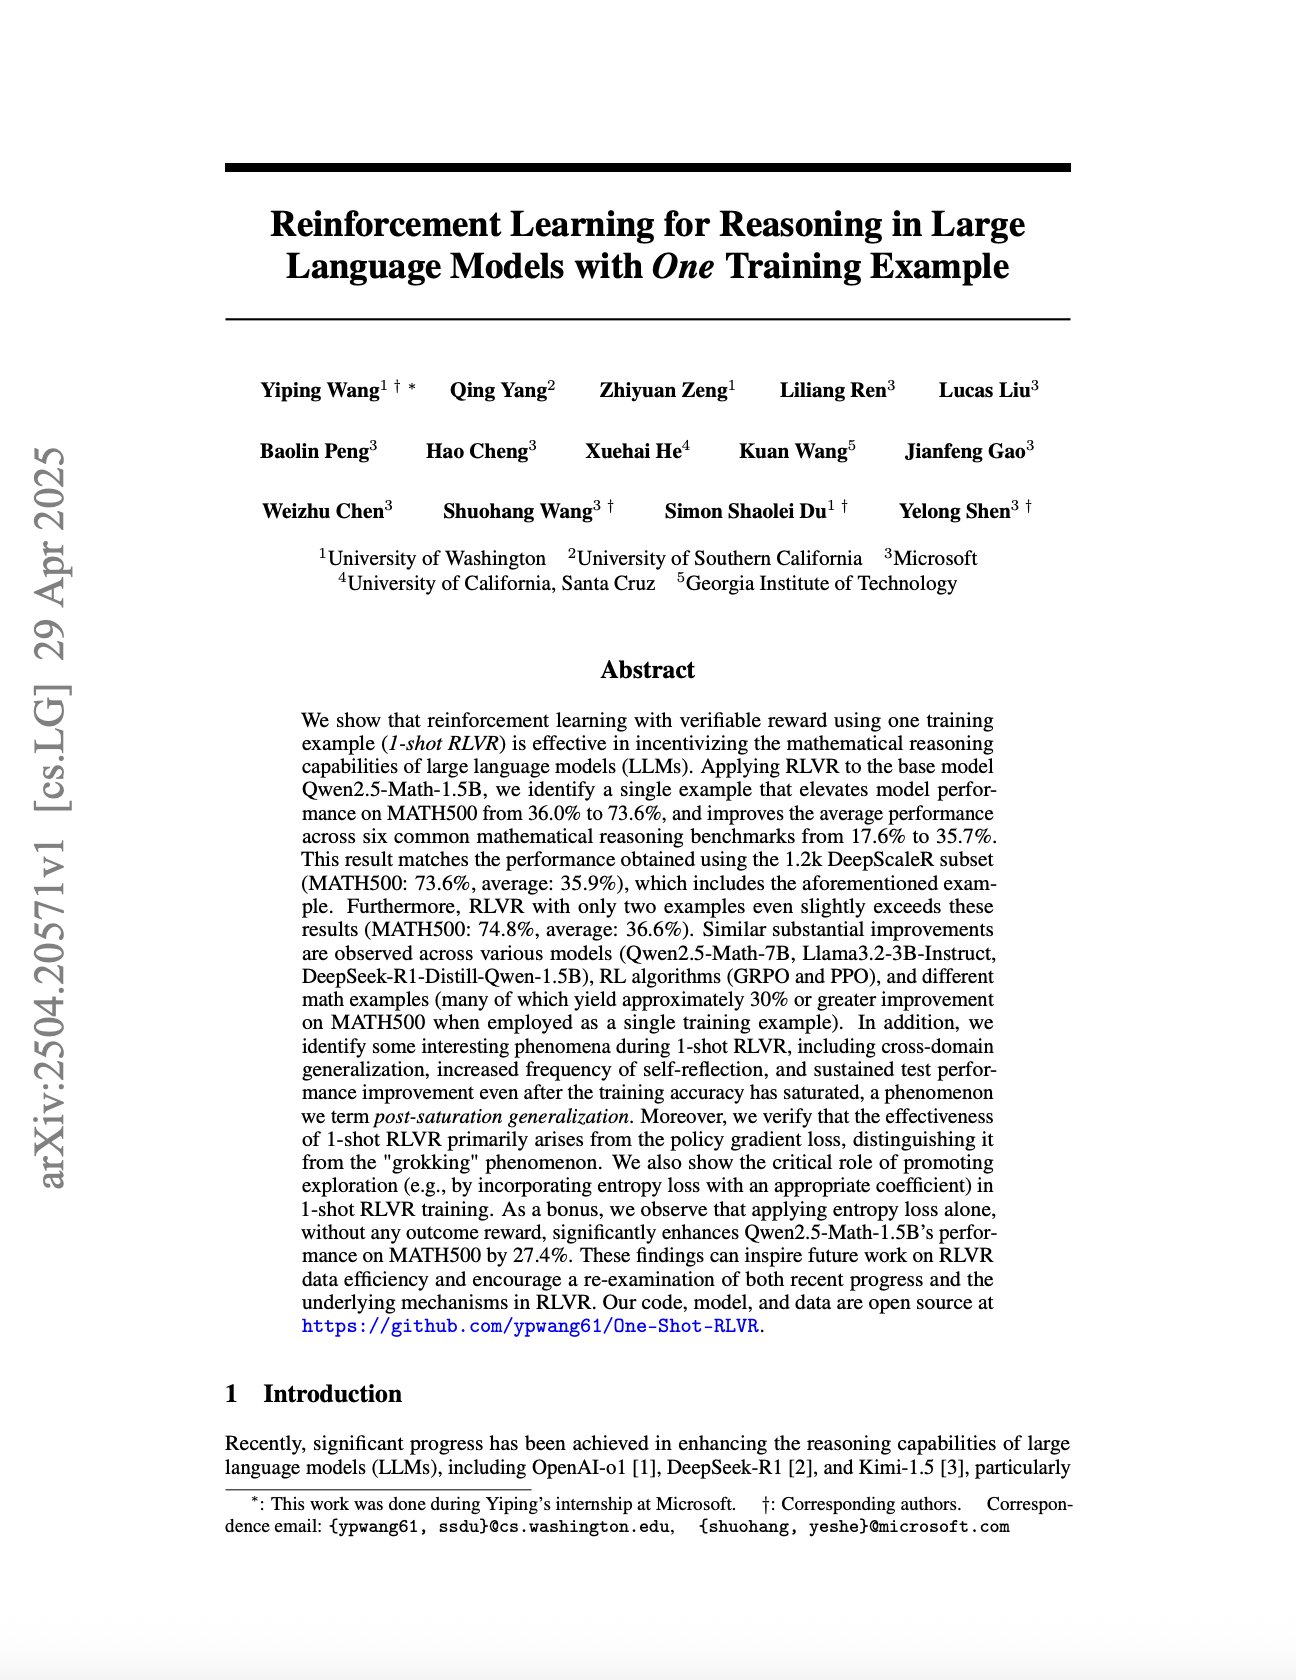
Reinforcement Learning Enables LLM Reasoning with Single Training Example
By
–
Reinforcement Learning for Reasoning in Large Language Models with One Training Example Wang et al.: https://
arxiv.org/abs/2504.20571 #ArtificialIntelligence #DeepLearning #MachineLearning -
Karen Hao’s Book Featured in Vulture’s May Reading List
By
–
Really honored to be on @vulture
's list of books to read in May (alongside the inimitable Ocean Vuong).
"Startling and intensely researched…an essential account of how OpenAI and ChatGPT came to be and the catastrophic places they will likely take us." -
AI at the Crossroads: GPT-4 and the Future of Human-Like Intelligence
By
–
New on the Blog: AI at a Crossroads: GPT-4, The Turing Test, and the Race for Human-Like Intelligence Stay ahead in the ever-evolving world of Digital Transformation. This article explores key insights into emerging technologies and their impact on today's business