
Large language model agents still struggle with multi-step reasoning, where one misstep can collapse the whole plan. While Process Reward Models (PRMs) aim to correct reasoning step-by-step using RL, they don’t scale well due to the high cost of evaluating tons of action
RESEARCH
-

Distillation Outperforms Zero-RL Through Flexible Reasoning
By
–
Why Distillation can Outperform Zero-RL: The Role of Flexible Reasoning
Paper: https://
arxiv.org/pdf/2505.21067
.pdf
… -

Distillation Outperforms RL for Smarter Small Model Reasoning
By
–
Distillation Beats Zero-RL: A Simpler Path to Smarter Reasoning? This paper delivers a surprising—and important—result: simple distillation from a stronger model can outperform full-blown reinforcement learning on small models, even with far fewer data and less compute. Key
-
LLMs World Model Capabilities and Practical Utility Examples
By
–
Mentioning partly for an example of mundane utility, partly as an example of Things People Probably Don’t Guess A Computer Can Do, and partly because there are still some people who think that LLMs don’t have a world model.
-
Lie Detection Device in Courts: Ethical and Legal Implications
By
–
Totally, but not in court. Seems wild but what if there was a device that everyone agreed we can trust to decide if someone in a courtroom is lying or not. What are the implications?
-
Open vs Closed Systems: Predictability and Observer Influence
By
–
My point is that open systems are indistinguishable from closed systems in which the influence of the starting state on the observer cannot be predicted in advance
-
Empiricism Versus Rationalism: AI Epistemology Beyond Mysticism
By
–
The alternative to empiricism is not rationalist epistemology, but mysticism
-
Robo-DM: Efficient Robot Big Data Management Paper Nominated
By
–
Congrats to all nominated papers and authors! Our @UCBerkeley + @GoogleDeepMind paper, "Robo-DM: Efficient Robot Big Data Management," is available here: https://
drive.google.com/file/d/1REEkLM
_74hXHVJKhdvzcyq9IQ9zKfRPH/
… -

Learning Reasoning Without External Rewards in AI Systems
By
–
Learning to Reason without External Rewards
Paper: https://
arxiv.org/pdf/2505.19590
.pdf
…
Code: https://
github.com/sunblaze-ucb/I
ntuitor
… -
Fine-tuning LLM with RL becomes surprisingly easy to implement
By
–
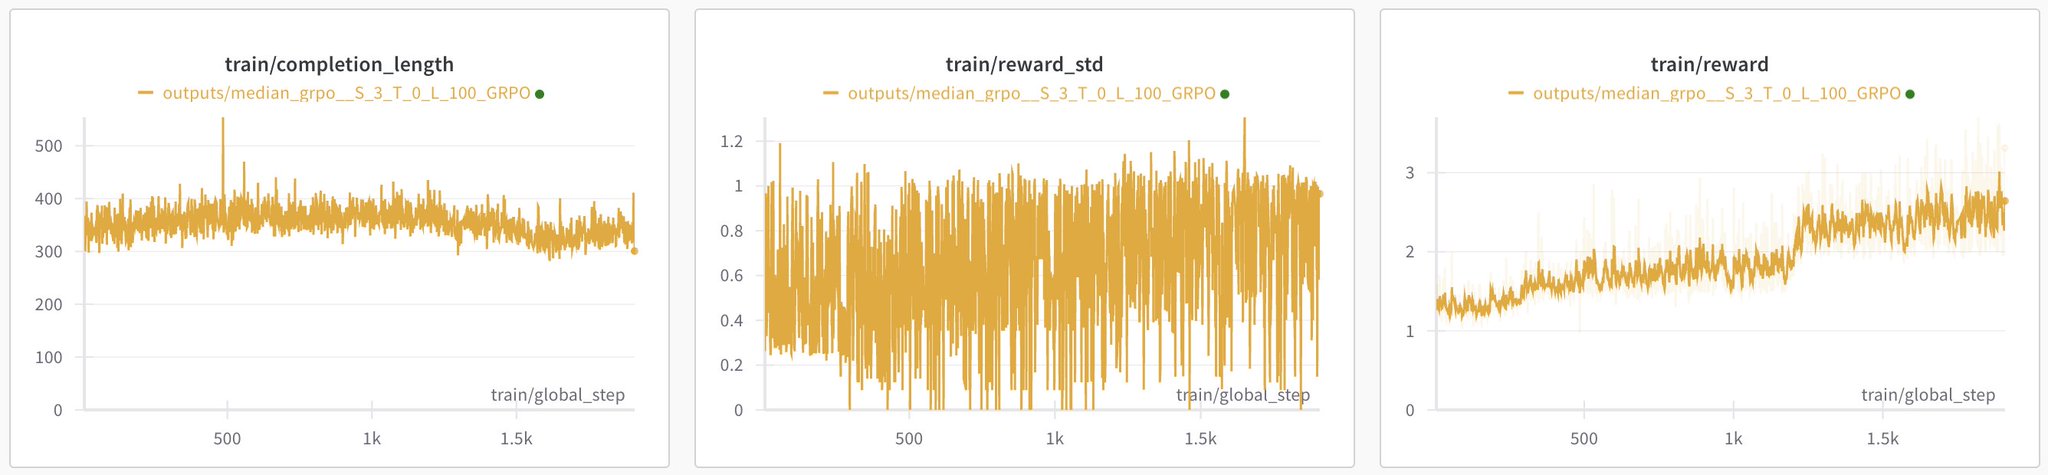
today i finetuned an LLM with RL for the first time. i regret to inform you that it was easy. it only took a few hours to configure. even though this is a custom task and dataset. and it worked, quite well, on the first run