RLHF 101 from ML@CMU A Technical Tutorial on Reinforcement Learning from Human Feedback "This blog dives into the full training pipeline of the RLHF framework. We will explore every stage — from data generation and reward model inference, to the final training of an
RESEARCH
-

AlphaOne: Reasoning Models Thinking Slow and Fast
By
–
AlphaOne: Reasoning Models Thinking Slow and Fast at Test Time
Paper: https://
arxiv.org/pdf/2505.24863
.pdf
…
Project: https://
alphaone-project.github.io
Code: https://
github.com/ASTRAL-Group/A
lphaOne
… (coming soon) -

AlphaOne: Modulated Reasoning Optimizes LRM Performance
By
–
Large Reasoning Models (LRMs) often struggle to balance deep thinking with efficient generation. Prior methods use monotonic scaling (e.g. "more steps = better results") but lack flexibility. Enter AlphaOne: Modulated Reasoning at Test Time AlphaOne introduces a universal
-
LLM Security Awareness Gap: Red Team Patching Challenge
By
–
"As soon as the companies realise this, red team it and patch the LLMs it should stop being a problem. But it's clear that they're not aware of the issue enough right now.” How do people still believe this?
-
AI Factory Flywheel Breakthroughs Unveiled at COMPUTEX 2025
By
–
Experience the momentum from our #COMPUTEX2025 keynote and #GTCTaipei where we showcased breakthroughs driving the AI factory flywheel. From major announcements to hands-on demos and workshops, see how we're delivering full-stack AI infrastructure for the next industrial
-
Stephen Wolfram’s Intelligence Exceeds the Ruliad Concept
By
–
Stephen may be the only person with a brain bigger than the Ruliad
-
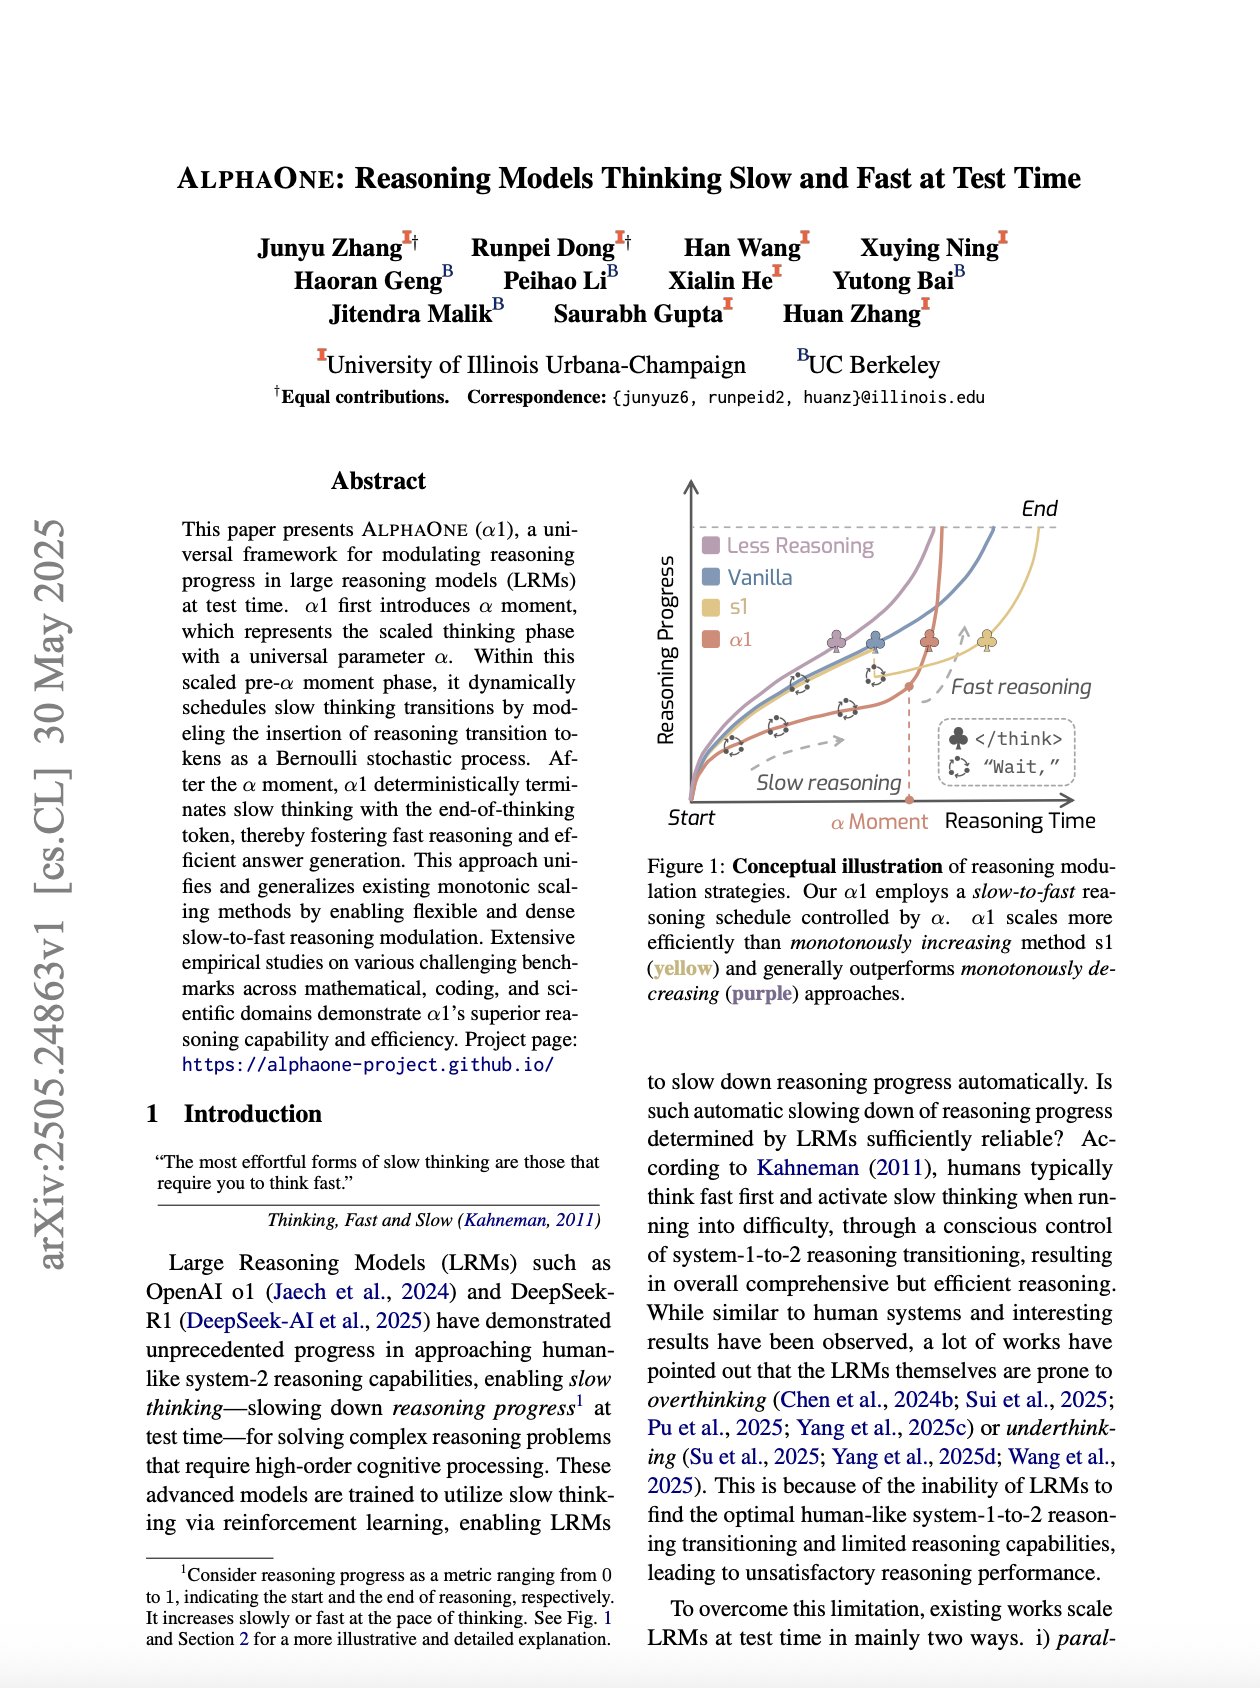
AlphaOne: Reasoning Models with Slow and Fast Thinking
By
–
AlphaOne: Reasoning Models Thinking Slow and Fast at Test Time Zhang et al.: https://
arxiv.org/abs/2505.24863 #ArtificialIntelligence #DeepLearning #MachineLearning -
DAIR Receives Emails About AI-Related Delusions
By
–
We also get many emails from people suffering from these delusions at DAIR.
-
AI Understanding Physical World for Scientific Discovery
By
–
It was an honor to be part of @Google IO Dialogues stage with James Manyika, Pushmeet Kohli and Joëlle Barral and talk about AI+Science. I talked about how AI needs to understand the physical world in order to make new scientific discoveries. While LLMs can come up with new
-
Method-Driven Research and AI: The Hammer Paradigm Shift
By
–
There are traditionally two types of research: problem-driven research and method-driven research. As we’ve seen with large language models and now AlphaEvolve, it should be very clear now that total method-driven research is a huge opportunity. Problem-driven research is nice because you have a consistent and specific goal. The goal is usually virtuous, so it feels good to have a mission and identity. However, it just doesn’t work due to The Bitter Lesson. Basically everything in classical NLP (machine translation, summarization, chatbots) lost to simple scaling. ChatGPT is a prime example—it used nothing from chatbot research and certainly wasn’t the intended end goal of OpenAI’s 2022 research program, but was a huge hit because someone (John Schulman et al) figured out the right way to package large language models as a product. Method-driven research feels less stable because you’re constantly searching for problems and you have to be opportunistic. But I believe AI will allow method-driven research to dominate progress in most fields of science, one-by-one. The latest method (or “hammer”), as we’ve seen in AlphaEvolve, is ruthless search and optimization against a reward function (whether this requires RL or not is a separate discussion). Things that problem-driven researchers have been trying to solve for a long time like the kissing number problem will become nails hit by the hammer. Eventually the hammer will become bigger, stronger, and more general and will hit more and more nails. So a very important meta-skill for the next decade will be knowing how to create the right environments to use The Hammer. Ironically, the problem-driven researchers, who by definition are experts in a specific problem, are well-positioned to create these environments. If, that is, they can put down their egos and pick up the hammer.
→ View original post on X — @_jasonwei, 2025-06-02 19:30 UTC