
smooth exponential AI progress
RESEARCH
-
India-AI Impact Summit 2026: STPI Nagpur Pre-Summit Event
By
–
AI Innovation & Disruption: STPI Nagpur presents Pre summit event, ‘Paving the Path to India-AI Impact Summit 2026’ 💡
— IndiaAI (@OfficialINDIAai) 21 novembre 2025
After insightful editions in Lucknow, Jaipur, Bhopal, Bhubaneswar, Dehradun, Bengaluru, Thiruvanthapuram, and Gandhinagar, the dialogue continues in the Orange… pic.twitter.com/I1xfx1rirtAI Innovation & Disruption: STPI Nagpur presents Pre summit event, ‘Paving the Path to India-AI Impact Summit 2026’ After insightful editions in Lucknow, Jaipur, Bhopal, Bhubaneswar, Dehradun, Bengaluru, Thiruvanthapuram, and Gandhinagar, the dialogue continues in the Orange
-

India AI Impact Summit 2026 Healthcare Workshop Convenes Leading Experts
By
–
The pre-summit workshop, held as a key part of the India – AI Impact Summit 2026, marked a crucial step on the #RoadToImpact. This half-day, in-person event successfully convened leading experts at the intersection of healthcare and artificial intelligence to refine and
-

AI Energy Solutions Casebook Submission Deadline November 2025
By
–
If you're developing impactful AI solutions for the energy domain, now is the time to showcase them. Submit an abstract for the ‘Casebook on the Real-World Impact of AI in Energy’, by IndiaAI and IEA. Last date to apply: November 21, 2025 Submit now: https://
impact.indiaai.gov.in/events/iea -

Internet Training Data May Drive AI Systems Toward Dysfunction
By
–
Forcing AI to read every demented corner of the Internet, like Clockwork Orange times a billion, is a sure path to madness
-

Recognizing AI Risk Management Knowledge from 15 Years Ago
By
–
Just realized I knew all about hedging ‘AI risks’ > 15 years ago
-
Decision Made Before Evaluation, Based on Training Loss
By
–
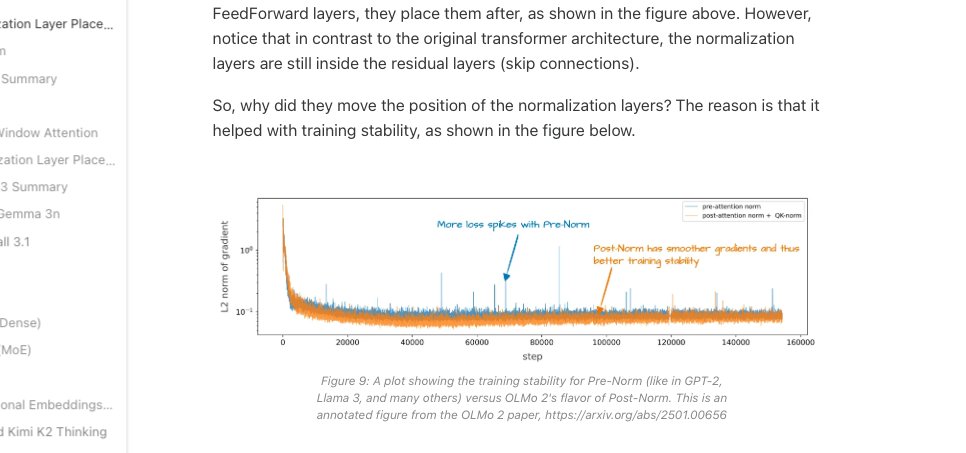
They made the choice even before evals. I.e., just looking at the training loss
-
MHA vs GQA Independence in Olmo 3 Models
By
–
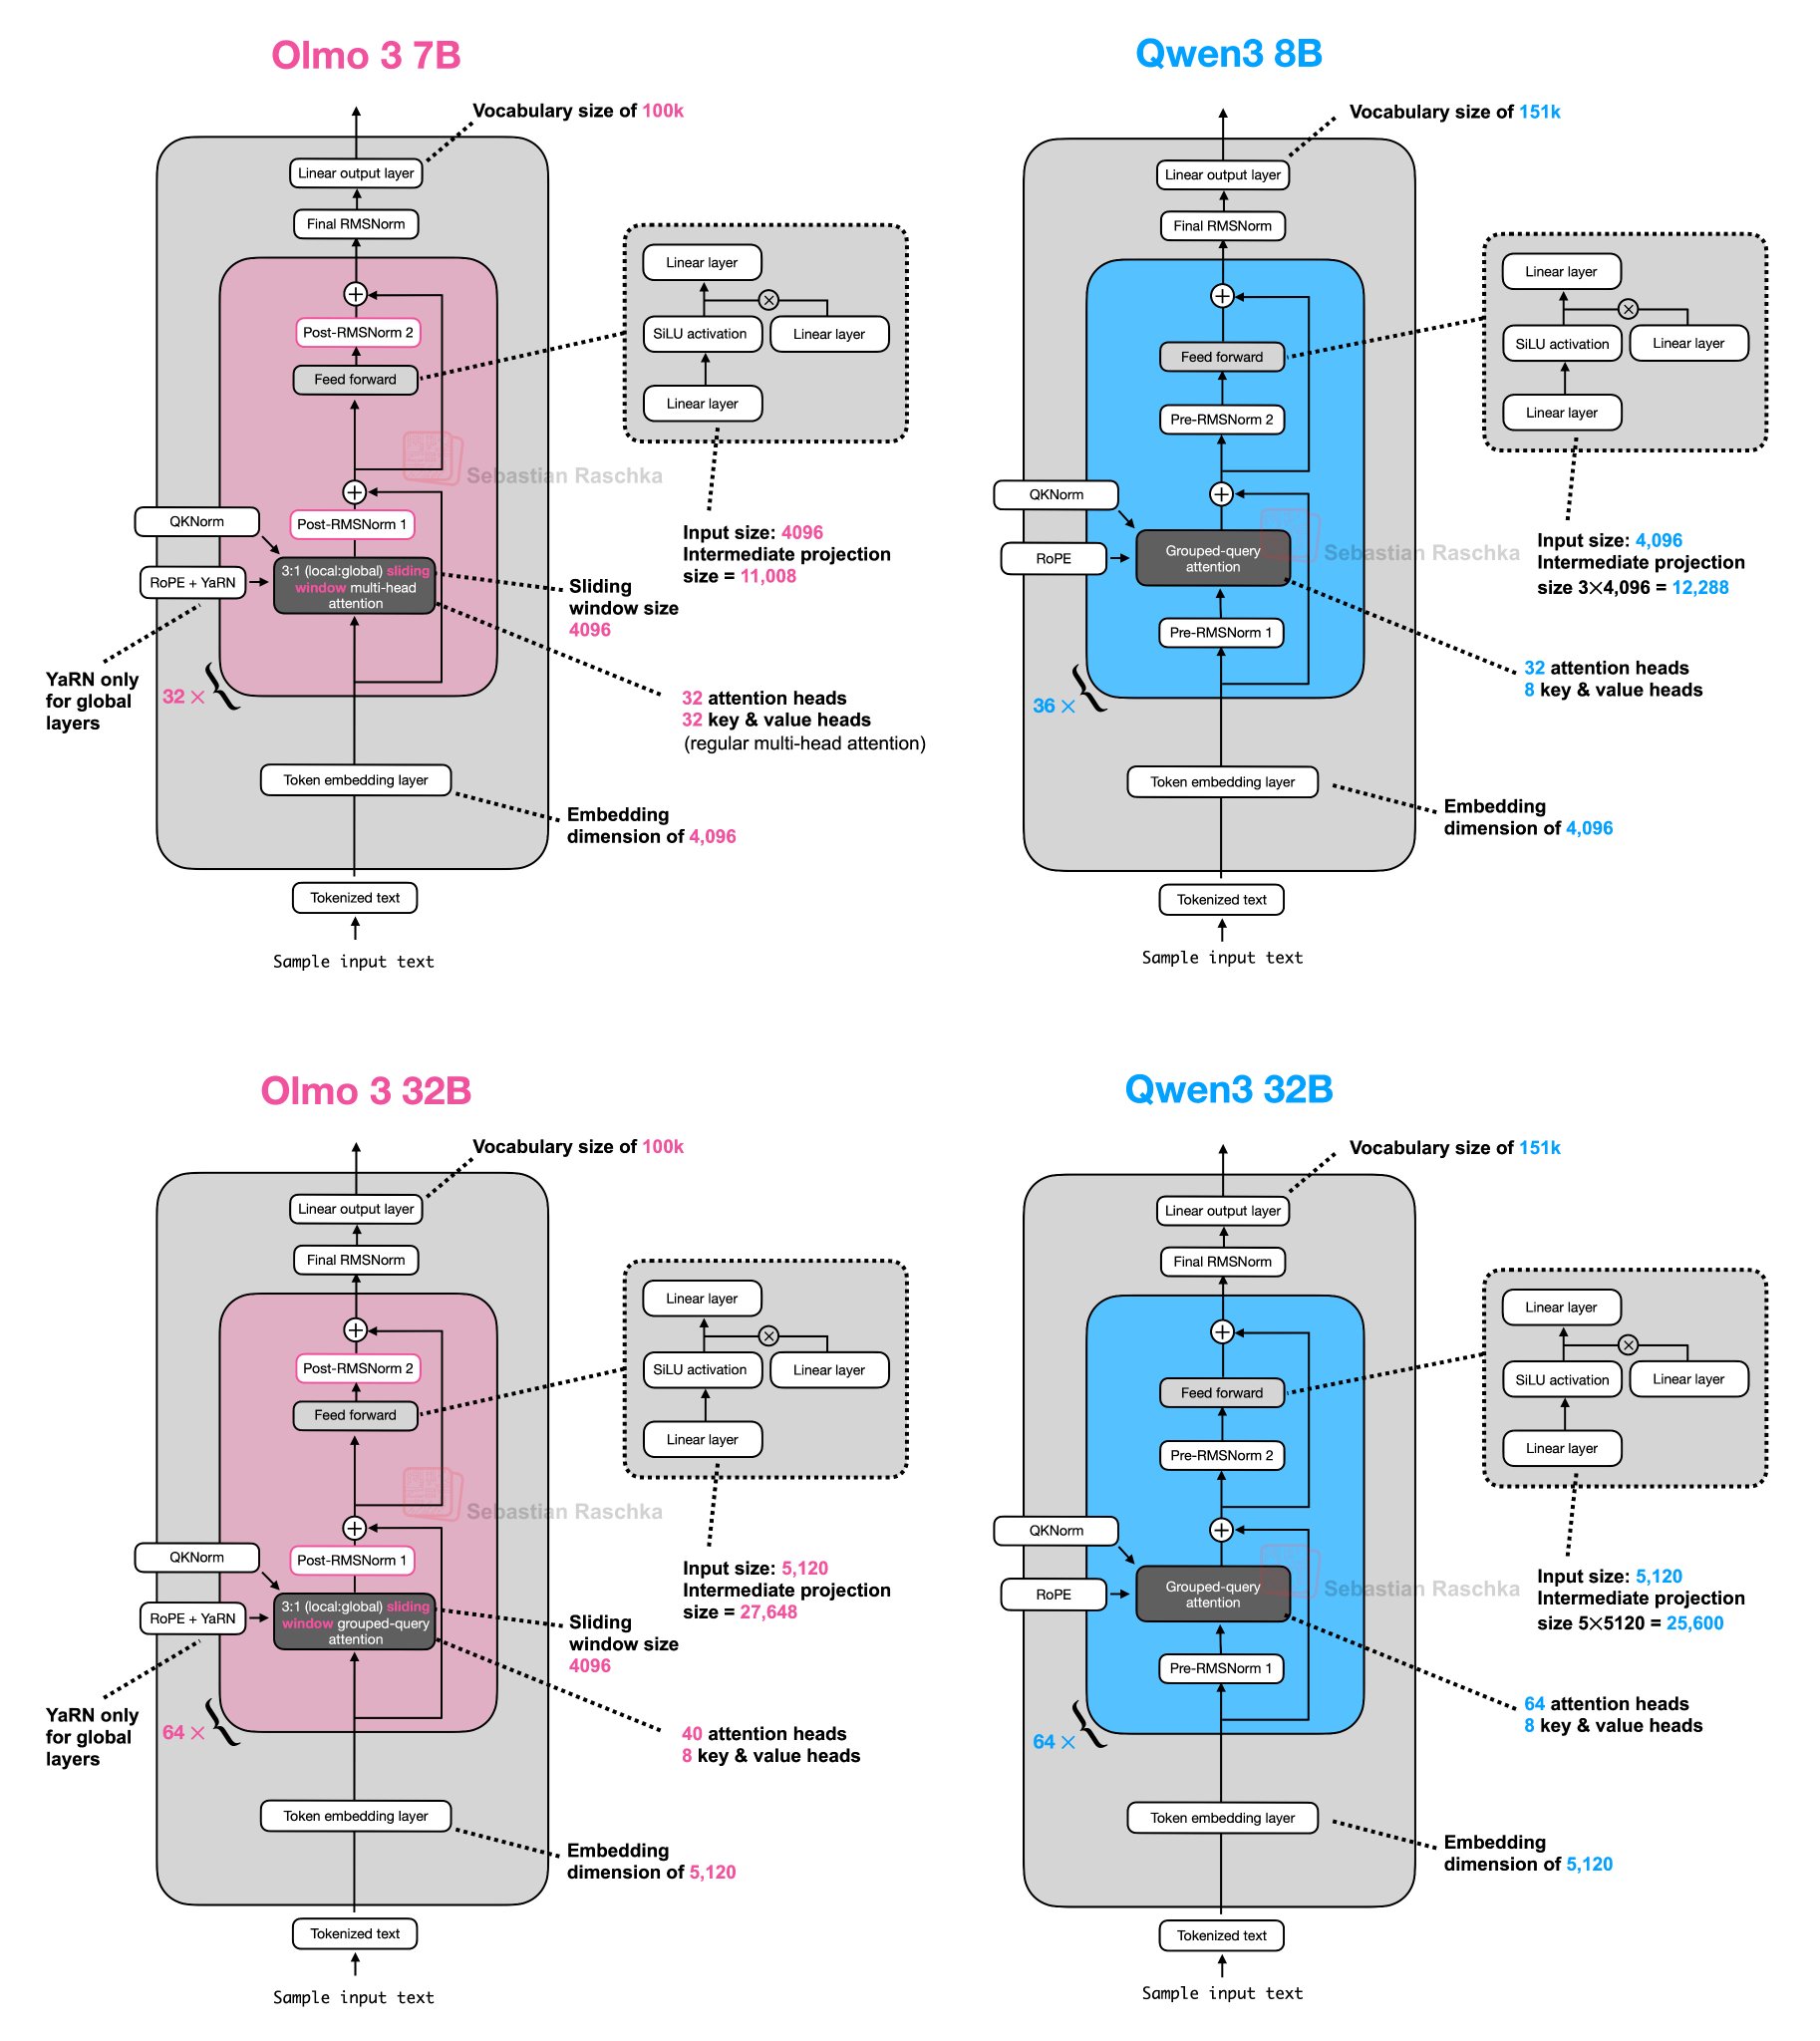
Hard to say, but I think it may be independent of MHA vs GQA. Also, Olmo 3 7B uses MHA, and 32B uses GQA.
-
Olmo 2 Ablation Study on Loss Spikes and Normalization Techniques
By
–
In their Olmo 2 report they had an ablation study showing it reduces the loss spikes during training (but they also included QK norm, so it's hard to say how much of that reduction is due to QK norm and their post norm flavor).
Maybe best of both words is to do both like Gemma -
Olmo Models Highlighted for Transparency and Detailed Technical Reports
By
–
Olmo models are always a highlight due to them being fully transparent and their nice, detailed technical reports. I am sure I'll talk more about the interesting training-related aspects from that 100-pager in the upcoming days and weeks.
In the meantime, here's the side-by-side