My take: advances in reasoning AI models and better simulated physical world model that they will have access to will make accumulation of large driving datasets for FSD largely irrelevant at some point over the next few years.
RESEARCH
-
OpenAI’s Mission Statement Evolution 2016-2024 Git Analysis
By
–
I had some fun pulling OpenAI's mission statement out of their IRS tax filings from 2016 to 2024, loading them into a git repo with fake commit dates and then taking a look at the diffs
-
Google Launches Gemini 3 Deep Think for Complex Science
By
–
We launches! Here’s a recap of what went out this week: — An upgrade to Gemini 3 Deep Think that solves complex modern science and engineering challenges. Scientists, researchers, and enterprises can express interest in Deep Think via our early access program and Google AI
-
AI revolutionizes science, creativity, and discovery, not just cats.
By
–
Sorry, but with everything happening in AI, how can people still think that AI is 'just pictures of cats talking'? AI is completely redefining the possible boundaries of science, creativity, ingenuity, and discovery.
-
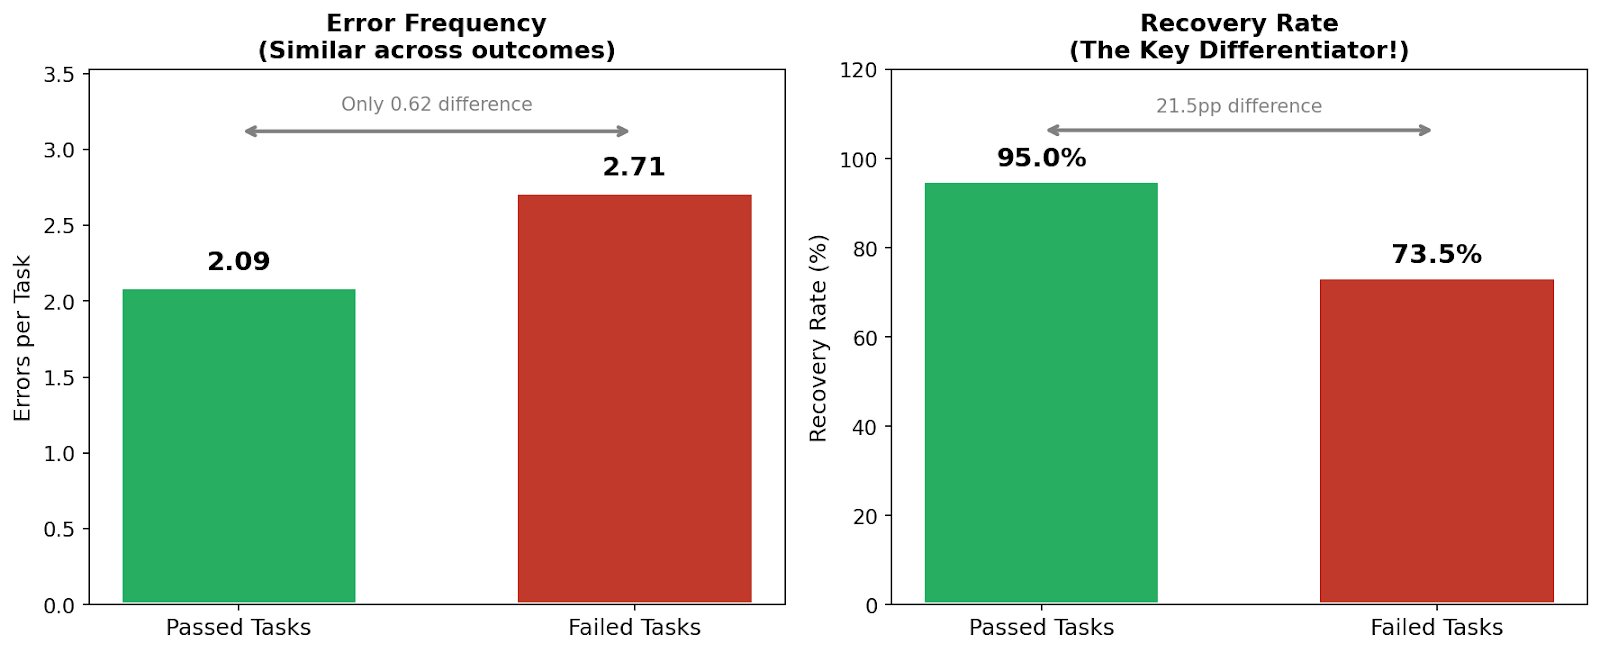
Error Recovery Rate Gap in AI Task Performance
By
–
Passed and failed tasks encounter similar errors (2.09 vs 2.71 per task). The difference? • Passed tasks recover from 95.0% of errors • Failed tasks recover from 73.5% A 21.5-point gap. Recovery > avoidance.
-
Six Key Insights on AI Long-Horizon Reliability and Autonomy
By
–
We break down 6 key insights that show the way forward to improve long-horizon reliability and greater autonomy. Full analysis from @RamyaRamakri here:
-

Agentic Coding Success: Recovery Matters More Than Error Prevention
By
–
What separates success from failure in agentic coding? Not fewer errors.
Better recovery. We analyzed ~4,000 classified errors across 1,805 Agentic Coding task runs from 8 frontier models. Here’s what we found -

MIRI Technical Governance Fellowship Program Application Deadline February 22
By
–
Apply for MIRI Technical Governance fellowship program; deadline now set to Sun, Feb 22nd.
-
Consistent AI Rankings: Dataset Evaluation Methodology Questions
By
–
It's surprising that it still manages to output such a consistent ranking. Are they simply evaluating on a fraction of the dataset, effectively?
-
SWE-Rebench: Software Engineering AI Evaluation Benchmark January 2026
By
–
The eval is probably not perfect, so please just consider it as an additional signal https://
swe-rebench.com/?insight=jan_2
026
…