AI Dynamics

Global AI News Aggregator

About

RESEARCH

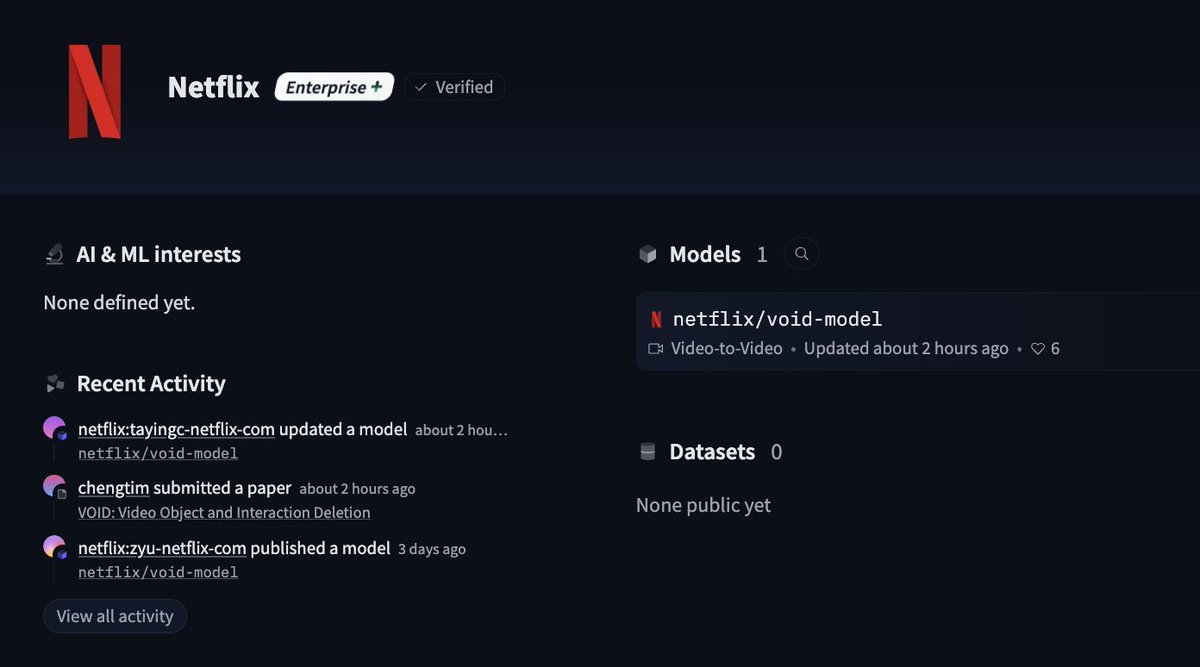
  • Netflix Launches Its VOID AI Model on Hugging Face
    Netflix Launches Its VOID AI Model on Hugging Face

    Netflix: surprise we just released our new AI model VOID on @huggingface. Capabilities of Netflix's VOID Model:
    – Object Removal with Environmental Awareness.
    – Physical Interaction Handling.
    – Open-Weight Access. [Translated from EN to English]

    → View original post on X — @huggingface, 2026-04-03 13:20 UTC

  • OpenAI Shifts Focus to Automated Researchers and Agent Systems

    Holy: OpenAI says it’s reallocating compute and talent toward its next generation of models, echoing the internal shift that preceded GPT-3. The focus now is on “automated researchers” and agent-based systems that can execute complex tasks end-to-end. It’s a signal that the lab

    → View original post on X — @kimmonismus

  • VoxCPM: Open-Source Voice Cloning Without Tokenization
    VoxCPM: Open-Source Voice Cloning Without Tokenization

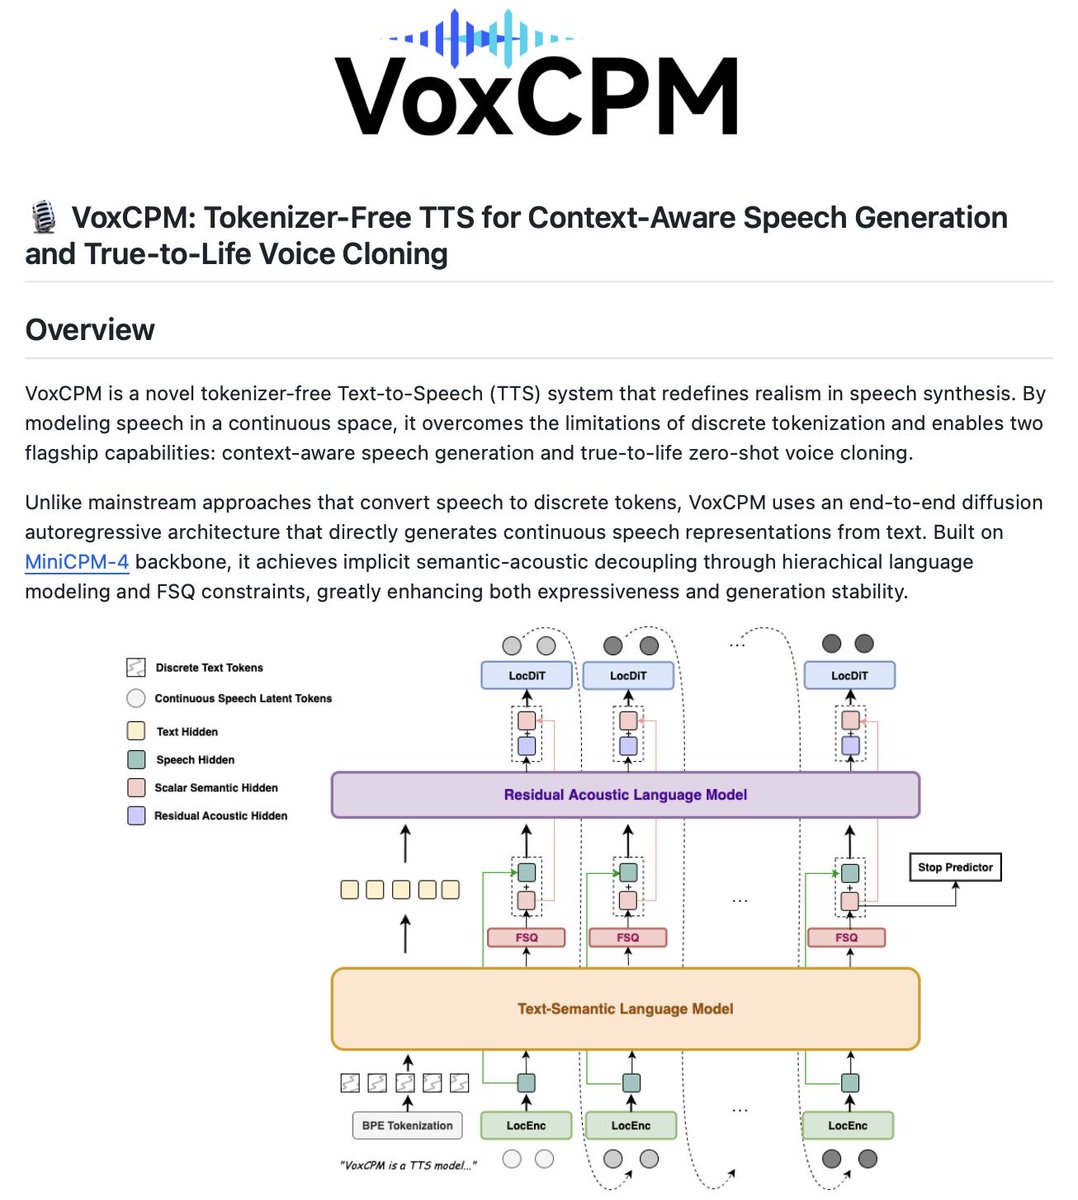
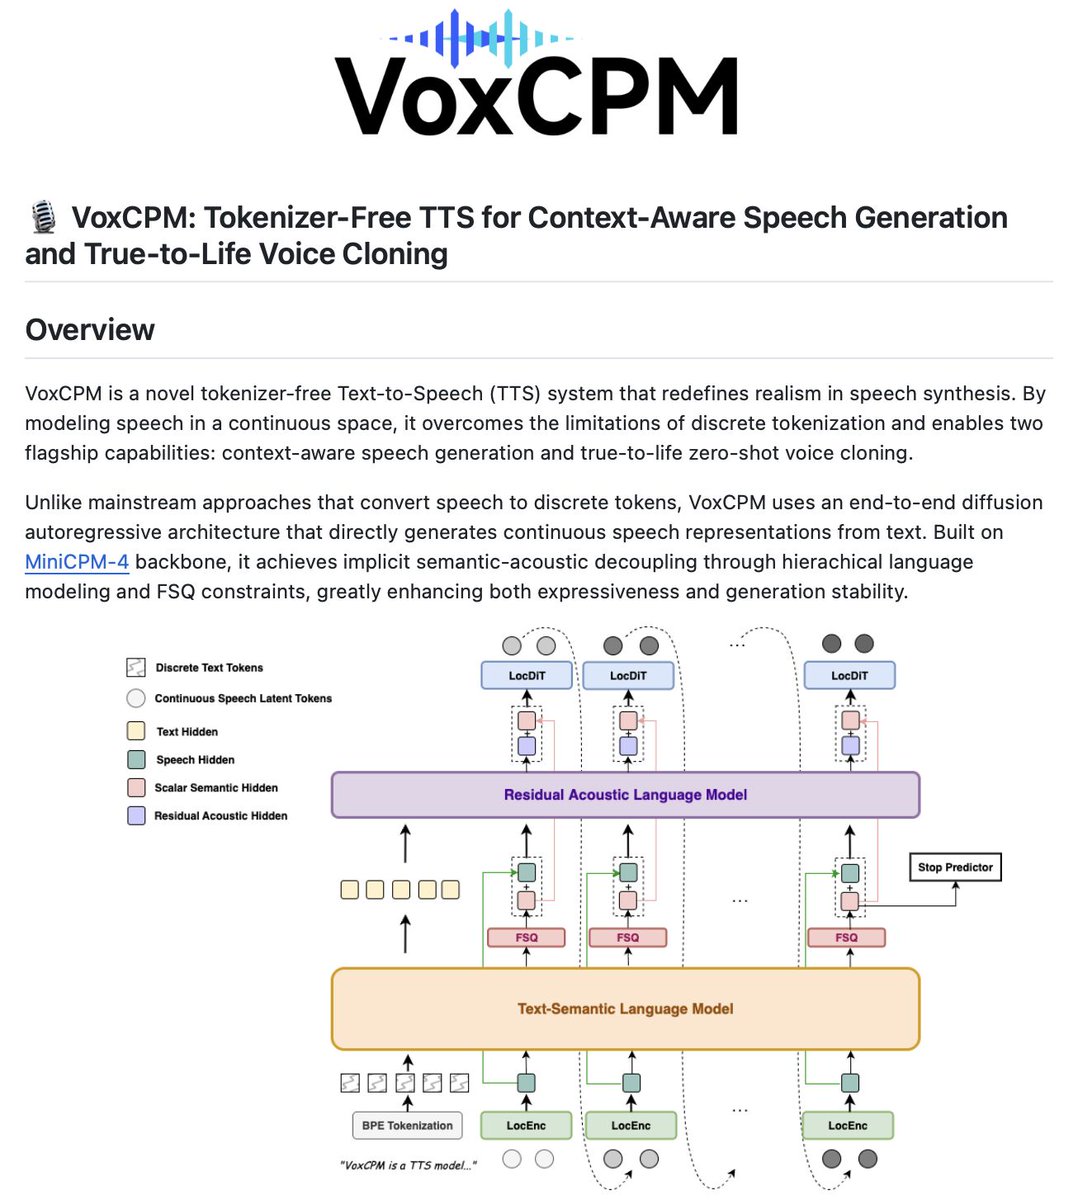
    If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling • Context-aware prosody generation without manual tuning • Zero-shot voice cloning from short reference audio • Streaming synthesis support for real-time applications • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! — https://nitter.net/Sumanth_077/status/2040055394958286903#m

    → View original post on X — @sumanth_077, 2026-04-03 13:15 UTC

  • VoxCPM: Real-time Voice Cloning Without Tokenization
    VoxCPM: Real-time Voice Cloning Without Tokenization

    Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling
    • Context-aware prosody generation without manual tuning
    • Zero-shot voice cloning from short reference audio
    • Streaming synthesis support for real-time applications
    • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! [Translated from EN to English]

    → View original post on X — @sumanth_077, 2026-04-03 13:14 UTC

  • 8 RAG Architectures for AI Engineers: Complete Guide
    8 RAG Architectures for AI Engineers: Complete Guide

    8 RAG architectures for AI Engineers: (explained with usage) 1) Naive RAG – Retrieves documents purely based on vector similarity between the query embedding and stored embeddings. – Works best for simple, fact-based queries where direct semantic matching suffices. 2) Multimodal RAG – Handles multiple data types (text, images, audio, etc.) by embedding and retrieving across modalities. – Ideal for cross-modal retrieval tasks like answering a text query with both text and image context. 3) HyDE (Hypothetical Document Embeddings) – Queries are not semantically similar to documents. – This technique generates a hypothetical answer document from the query before retrieval. – Uses this generated document’s embedding to find more relevant real documents. 4) Corrective RAG – Validates retrieved results by comparing them against trusted sources (e.g., web search). – Ensures up-to-date and accurate information, filtering or correcting retrieved content before passing to the LLM. 5) Graph RAG – Converts retrieved content into a knowledge graph to capture relationships and entities. – Enhances reasoning by providing structured context alongside raw text to the LLM. 6) Hybrid RAG – Combines dense vector retrieval with graph-based retrieval in a single pipeline. – Useful when the task requires both unstructured text and structured relational data for richer answers. 7) Adaptive RAG – Dynamically decides if a query requires a simple direct retrieval or a multi-step reasoning chain. – Breaks complex queries into smaller sub-queries for better coverage and accuracy. 8) Agentic RAG – Uses AI agents with planning, reasoning (ReAct, CoT), and memory to orchestrate retrieval from multiple sources. – Best suited for complex workflows that require tool use, external APIs, or combining multiple RAG techniques. 👉 Over to you: Which RAG architecture do you use the most? _____ Share this with your network if you found this insightful ♻️ Find me → @akshay_pachaar ✔️ For more insights and tutorials on LLMs, AI Agents, and Machine Learning!

    → View original post on X — @akshay_pachaar, 2026-04-03 12:54 UTC
  • 5 Practical Techniques to Detect and Mitigate LLM Hallucinations
    5 Practical Techniques to Detect and Mitigate LLM Hallucinations

    5 Practical Techniques to Detect and Mitigate LLM Hallucinations Beyond Prompt Engineering machinelearningmastery.com/5… [Translated from EN to English]

    → View original post on X — @craigbrownphd, 2026-04-03 12:44 UTC

  • HACRL: AI Agents Learn Together Without Losing Autonomy
    HACRL: AI Agents Learn Together Without Losing Autonomy

    What if diverse AI agents could mutually learn and improve without sacrificing their autonomy? Researchers from Beihang University, Bytedance China, Tsinghua University, and Peking University have just unveiled Heterogeneous Agent Collaborative Reinforcement Learning (HACRL)! This innovative framework allows different types of AI agents to share verified learning experiences during training, creating a bidirectional flow of knowledge to enhance performance for everyone. Unlike other multi-agent systems, it requires no coordinated deployment and fosters true peer-to-peer growth, not one-way teaching. Their HACPO algorithm consistently boosts all participating agents, outperforming GSPO by 3.3% on diverse reasoning benchmarks while dramatically cutting training data costs in half. Heterogeneous Agent Collaborative Reinforcement Learning Paper: arxiv.org/abs/2603.02604 Github Page: zzx-peter.github.io/hacrl/ Huggingface: huggingface.co/papers/2603.0… Our report: mp.weixin.qq.com/s/ggzim_4Pc… 📬 #PapersAccepted by Jiqizhixin

    → View original post on X — @jiqizhixin, 2026-04-03 12:43 UTC

  • Weekly Roundup: Moon, OpenAI Acquisition, Gemma 4, Solar Efficiency
    Weekly Roundup: Moon, OpenAI Acquisition, Gemma 4, Solar Efficiency

    We're going back to the fucking Moon.
    OpenAI acquires TBPN.
    Google DeepMind (what a great lab! hey guys!) releases Gemma 4.
    Solar cells hit 130% efficiency (?).
    Somos raises $40M. + Science Breakthroughs, grid, Bangalter What a week for the optimists.

    → View original post on X — @packym

  • Ross Taylor shares article on RL environments for LLM agents
    Ross Taylor shares article on RL environments for LLM agents

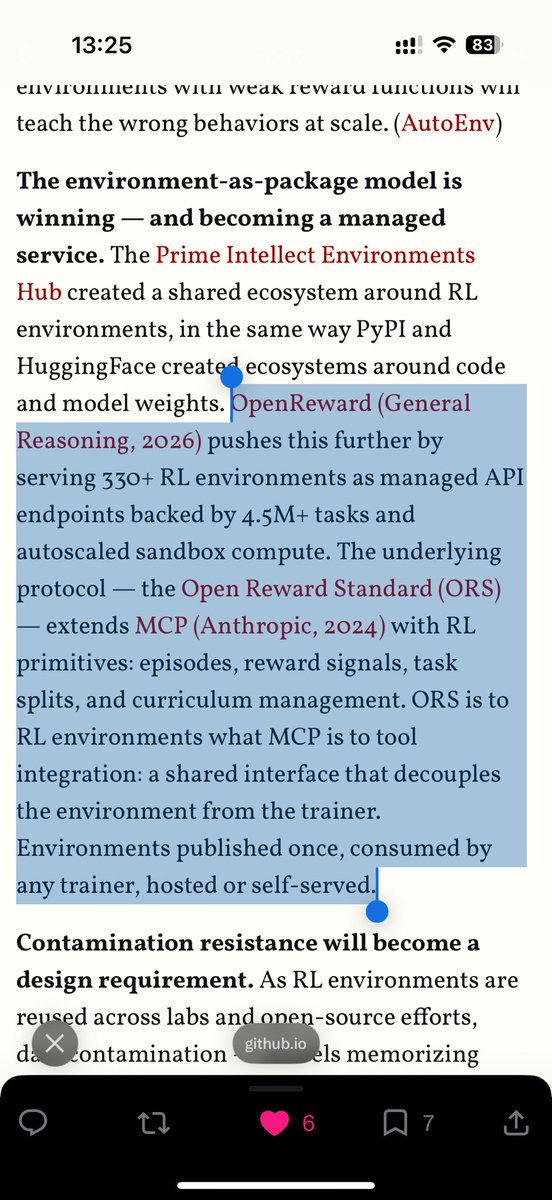
    ✌️ Ross Taylor (@rosstaylor90) Really enjoyed this article by @HanchungLee leehanchung.github.io/blogs/… — https://nitter.net/rosstaylor90/status/2040038533390365152#m

    → View original post on X — @nathanbenaich, 2026-04-03 12:27 UTC

  • AI-2027 Accelerates Predictions for Automated Coding Development Timeline
    AI-2027 Accelerates Predictions for Automated Coding Development Timeline

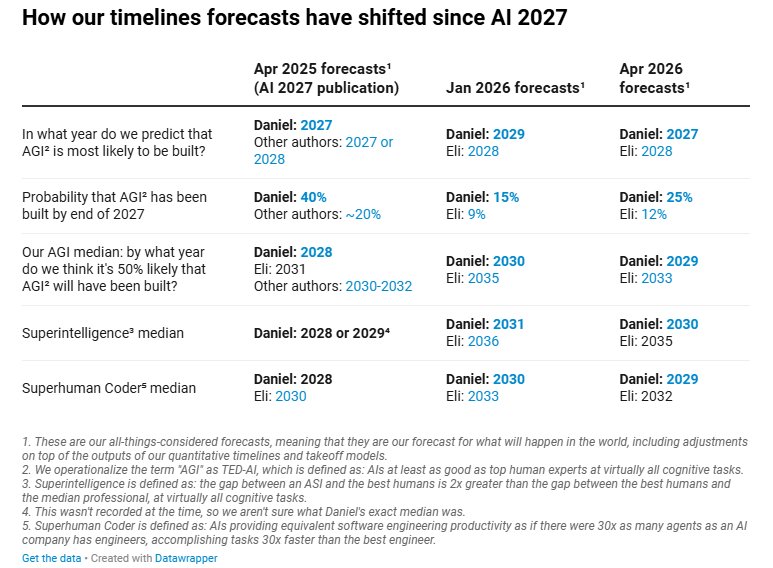
    The authors of AI-2027 have moved forward their predictions for "AI timelines and takeoff speeds" in a brief post because, contrary to their expectations, the pace of development is accelerating. "Daniel’s Automated Coder (AC) median has moved from late 2029 to mid 2028, and

    → View original post on X — @kimmonismus